# Graph Engineering: Stop Chaining Your Agents
**作者**: seeco
**日期**: 2026-08-14T09:41:44.000Z
**来源**: [https://x.com/seeconvm/status/2088199384580108339](https://x.com/seeconvm/status/2088199384580108339)
---
Almost every multi step agent I have ever opened is a queue. Step one, step two, step three, each one politely waiting for the last one to finish. And once you look closely, roughly half of those steps never had anything to wait for.
They don't route. They don't split. They don't run anything side by side. They just stand in line, one head, one context, one thing at a time, until the window fills up and the agent quietly forgets what it was doing in the first place.
Here is the part nobody spells out for you. A prompt is a sentence. A loop is a cycle. A harness is the floor your agent stands on. But the shape of the work itself, what runs before what, what can run at the same time, what genuinely has to wait for everything else, that shape is a graph. Nodes do the thinking. Edges carry the results.
Claude Code shipped the tooling for building these graphs directly: dynamic workflows. Claude writes a plain JavaScript orchestration script, then spawns a coordinated fleet of subagents to execute it. The coordination itself costs zero model tokens, because it is code, not another conversation.
This is the 14 step roadmap I use to turn a single file agent into a graph that fans out across a fleet, checks its own findings, and lands on a result one agent could never hold.
## AT A GLANCE
1. Nodes are jobs. Edges are what flows.
2. Your linear script is already a graph, just a bad one.
3. Every node gets a contract.
4. Every edge gets a data contract.
5. Fan out with parallel().
6. Fan in at a barrier, and only when you must.
7. The diamond: split, work, merge.
8. Route the edge at runtime with a conditional.
9. Put a verifier on the edge.
10. Isolate nodes so one failure stays local.
11. Add a cycle, but make it converge.
12. Tier your models across the nodes.
13. Topology is your cost and your latency.
14. Let Claude draw the graph for you.
## 01. Nodes and Edges, or Why "And Then" Is Not a Dependency
A graph has exactly two pieces, and getting them straight clears up most of the confusion.
A node is a unit of work. One agent, one bounded job, one input in, one output out.
An edge is a dependency. It says this node's output feeds that node's input. That is the whole definition.
The mistake almost everyone makes is treating "and then" as an edge. "Summarize this file and then tell me the weather" has no edge in it anywhere. The weather does not consume the summary. Those are two disconnected nodes that a linear script chained together for no reason at all.
The question to ask. For every and then in your agent: does the next step actually read the previous step's output? If it doesn't, there is no edge there, and the wait is pure waste.
```
Draw it as boxes and arrows. A box is one agent()
call. An arrow is a variable that leaves one call's
return and enters another call's prompt. If you cannot
draw the arrow, if no variable crosses, those two boxes
are independent. That independence is the thing you are
going to spend the rest of this article exploiting.
```
## 02. Your Linear Script Is a Degenerate Graph
When you write an agent as "do A, then B, then C, then D," you already drew a graph. You drew the worst one available: a single unbranching chain where every node has exactly one edge in and one edge out.
It runs. It also runs slowly, and it breaks badly, because a chain has no redundancy. If C stalls, D never happens, and everything A produced is stuck upstream with nowhere to go.
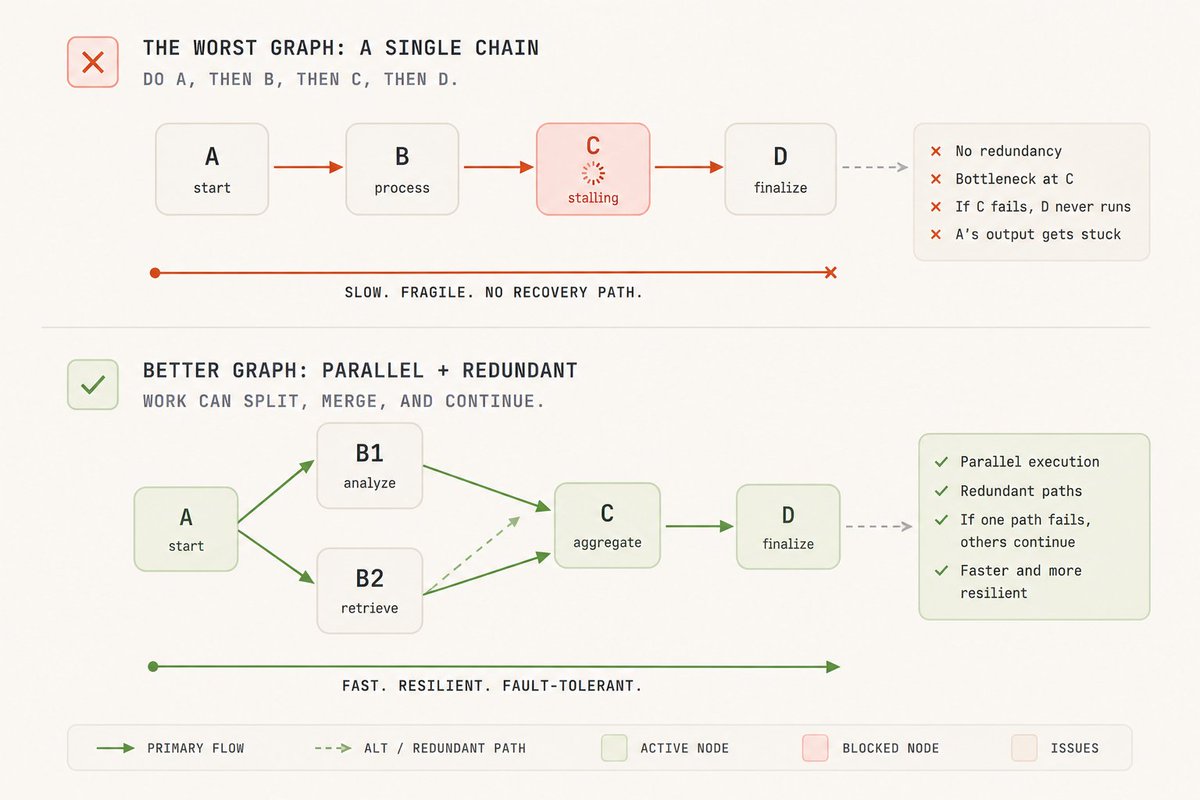
The first real skill here is redrawing the chain. Take your linear agent, walk every arrow, and ask the question from step 01. In practice you will find two or three arrows that carry no data at all. They only exist because that is the order you happened to type things in.
Cut those arrows and the chain collapses sideways into something much wider: a handful of independent nodes that can all run at once, feeding into a single node that needs all of them.
## 03. Give Every Node a Contract
A node you cannot reason about is a node you cannot parallelize. The fix is a contract: bounded input, bounded output, exactly one job.
The input is whatever that node reads, passed in explicitly. Never assumed from some shared window it happens to be sitting in. The output is a defined shape, ideally validated, so the next node can consume it without guessing.
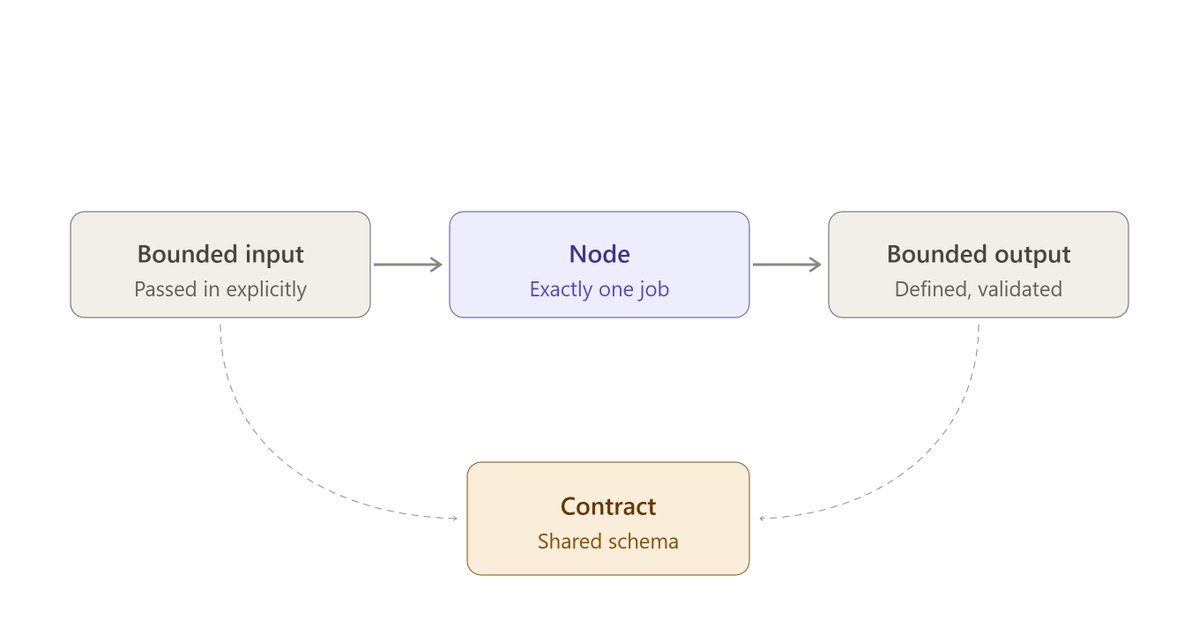
In a workflow you enforce this with a schema. When you hand Claude an agent() call with a JSON schema attached, the subagent it spawns is forced to return validated structured data. Validation happens down at the tool call layer, so Claude retries on a mismatch instead of handing you free text you have to parse and pray over.
```
// A node with a real contract: bounded in, validated
out, one job.
const FINDING = {
type: 'object',
additionalProperties: false,
properties: {
title: { type: 'string' },
url: { type: 'string' },
impact: { type: 'string', enum: ['high', 'medium',
'low'] },
},
required: ['title', 'url', 'impact'],
};
const result = await agent(source.prompt, {
label: `research:${source.key}`,
schema: FINDING, // forces validated
structured output
agentType: 'general-purpose',
});
// result is now a shape the next node can trust, not
free text.
```
That is the entire difference between a node Claude can wire into a graph and a node that only works when a human reads its output.
## 04. The Edge Is a Data Contract Too
An edge is not "B comes after A." It is a promise about what crosses: A produces this shape, B was built to consume this shape. Name your edges by their data instead of their order and two things get much easier.
You can instantly tell whether the edge is even real, meaning does data actually move across it. And you can swap the node on either end without touching the rest of the graph, as long as the shape holds.
In practice the edge lives in plain JavaScript. The reduce step between a fan out and a synthesis, flatten, dedupe, filter, is just code operating on the shapes your nodes returned.
No agent needed. This is one of the quiet wins of thinking in graphs: a huge amount of what people burn model tokens on is really just an edge, and edges are free.
```
// Tempting: spawn an agent to "combine the results.
"Don't.
// If combining means flatten and dedupe, that is flatMap
plus a Set.
// Deterministic, instant, zero tokens.
const flat = collected.flatMap((c) => c.items);
const clean = [...new Map(flat.map((i) => [i.url, i])).
values()];
```
Save agents for judgment. Not for plumbing. A graph where every edge is an agent is a graph paying rent on its own wiring.
## 05. Fan Out With parallel()
This is the move that pays for everything else. When you have N independent nodes, N sources to check, N files to review, N routes to audit, you do not chain them.
You tell Claude to fan them out and run them at once. In a workflow that is parallel(): Claude takes an array of thunks, spawns one subagent per thunk, runs them concurrently, and hands you back the array of results.
Two details make it robust. First, parallel() is a barrier, so it waits for every thunk before it returns and the next stage always sees the complete set. Second, a thunk that throws resolves to null instead of rejecting the whole batch, so one flaky agent cannot sink the run.
Always .filter(Boolean) on the way out. Concurrency is capped around your core count and the overflow queues up, so you can hand it a hundred thunks and they will all finish, just a handful at a time.
```
phase('Research');
// Nine sources, nine agents, all at once.
const raw = await parallel(
SOURCES.map((s) => () =>
agent(s.prompt, {
label: `research:${s.key}`,
phase: 'Research',
schema: ITEM_SCHEMA, // each node returns
validated JSON
agentType: 'general-purpose',
}),
),
);
const collected = raw.filter(Boolean); // drop nulls
from failed agents
```
The fan out lives in code Claude wrote, not in a model conversation. Claude's own context never holds nine sources at once. Each subagent carries its own, and only the final answer comes back. That is what lets a workflow scale to dozens or hundreds of subagents without drowning the session, and the orchestration layer costs nothing, because it is not another turn of Claude thinking.
## 06. Fan In at a Barrier
A fan out is only worth anything if something gathers it. The fan in is the node where your edges converge, where one agent or one piece of code sees all the upstream results at the same time and does something that genuinely requires the whole set: dedupe across sources, rank by impact, exit early if everything came back empty.
That is the one place a barrier earns its wall clock cost.
The rule that keeps graphs fast: use a barrier only when a stage truly needs every prior result together. Deduping across all sources qualifies.
```
// The edge: plain JS, no agent, zero tokens.
const flat = collected.flatMap((c) => c.items);
log(`Collected ${flat.length} items`);
phase('Curate');
// The barrier node: needs the WHOLE set to dedupe and
rank.
const curated = await agent(
`Dedupe and rank these by impact:\n${JSON.stringify
(flat)}`,
{ phase: 'Curate', schema: CURATED_SCHEMA },
);
```
Just flattening a list is not a barrier, it is an edge, do it inline. The smell test is brutally simple: if you wrote parallel, then a transform, then parallel again, and that middle transform has no cross item dependency, you should have used a pipeline and skipped the barrier entirely.
## 07. The Diamond: Split, Work, Merge
Put a fan out and a fan in together and you get the workhorse topology of every serious agent graph: the diamond.
One node splits the job. Many nodes do the work in parallel. One node merges. That is the shape behind a market scan, a dependency audit, a code review, a research report. Swap the sources and the prompts and the same skeleton adapts to all of them.
The canonical form is worth memorizing: fan out, reduce, synthesize. Fan out to gather breadth. Reduce with plain code to compress it. Synthesize with a final agent to write the answer.
Once you can see the diamond, you stop asking "how do I make my agent do more steps" and start asking "where is the split, where is the merge." That second question is the one that actually scales.
## 08. Route the Edge at Runtime With a Conditional
Not every graph is fixed. Sometimes which edge you take depends on what a node found. A router node inspects a result and decides which downstream path fires: classify the ticket, then branch to the right handler. Check the diff size, then either do a quick review or spin up a full audit.
In a workflow this is just a JavaScript if or switch on a node's validated output, because your control flow lives in code.
```
// Router node: an agent classifies, code picks the edge.
const { severity } = await agent(`Classify this diff's
risk:\n${diff}`, {
schema: {
type: 'object',
properties: { severity: { type: 'string', enum:
['low', 'high'] } },
required: ['severity'],
},
});
let review;
if (severity === 'high') {
// heavy path: full parallel audit
review = await parallel(FILES.map((f) => () => agent
(`Audit ${f}`)));
} else {
// light path: one quick pass
review = await agent(`Quick review of ${diff}`);
}
```
This is where determinism turns into a feature instead of a limitation. The router's decision can be Claude powered, a subagent classifies it. The routing is code Claude wrote, so it runs the same way every single time for the same classification.
You get Claude's judgment at the node and a script's reliability at the edge. There is no emergent "Claude decided to skip the audit today" surprise, because skipping would have to be written into the graph, and it isn't.
## 09. Put a Verifier on the Edge
The real leverage of a graph is not that you get more agents. It is the structure you can wrap around them to produce confidence.
A verifier node sits on the edge, before a result is allowed downstream, and its only job is to try to kill the finding. If it survives, it passes. If it doesn't, it never reaches your answer.
Three patterns worth keeping in your hands:
- Adversarial verify. For each finding, spawn N independent skeptics prompted to refute it, and keep it only if a majority survive.
- Perspective diverse verify. Give each verifier its own lens, correctness, security, does it reproduce, because diversity catches failure modes that N identical checks never will.
- Judge panel. Generate N attempts from different angles, score them with parallel judges, synthesize from the winner while grafting in the best pieces of the runners up.
This is exactly the pattern that let a real team port the Bun runtime with adversarial code review baked straight into the loop.
## 10. Isolate Nodes So One Failure Stays Local
In a chain, a failure cascades. C dies, D never runs, the whole thing halts. In a graph, failure should be contained to its node.
Part of that is already true: a thunk that throws inside parallel() resolves to null, so eight good agents still return while the one bad one drops out. Your .filter(Boolean) is the containment. Design every fan in to tolerate missing inputs instead of assuming a full set.
The subtler failure is nodes stepping on each other. When agents write files in parallel, they collide.
The fix is isolation: worktree. Each agent runs in its own git worktree, does its work in a sandbox, and merges cleanly at the end. Reach for it only when nodes genuinely write in parallel. It is the seatbelt for one specific topology, not a default tax on every run.
## 11. Add a Cycle, But Make It Converge
Sometimes you have no idea how big the job is until you are inside it. Discovery of unknown size. A bug sweep where finding one bug reveals three more. That calls for a cycle, a controlled edge back to an earlier node.
The danger is obvious. A cycle that never converges is an infinite loop that spawns agents until your budget is gone.
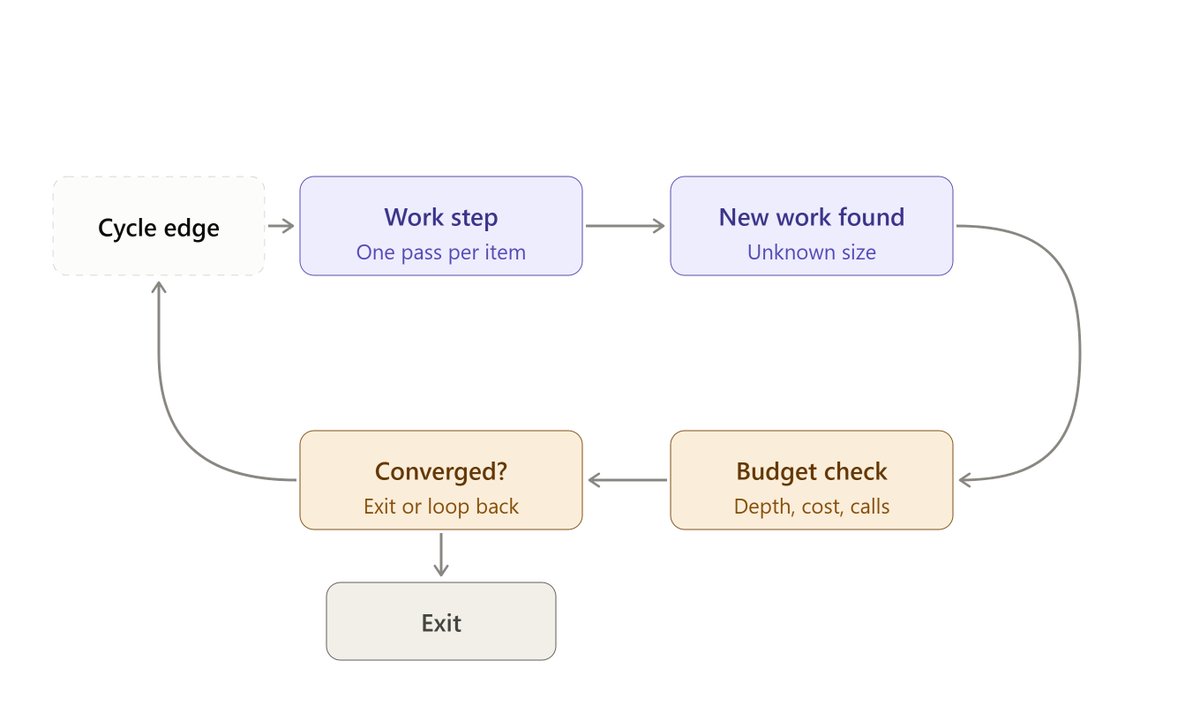
The pattern that converges is loop until dry: keep spawning finders until K consecutive rounds surface nothing new, then stop. And here is the detail that makes or breaks it, the one almost everybody gets wrong the first time: what you dedupe against.
Dedupe against everything seen, not just against confirmed results. Otherwise rejected findings come back every round, the loop never runs dry, and you have built a machine that pays to rediscover the same dead ends forever.
```
const seen = new Set(); const confirmed = []; let dry = 0;
while (dry < 2) { // stop after 2
empty rounds
const found = (await parallel(
FINDERS.map((f) => () => agent(f.prompt, { schema:
BUGS }))
)).filter(Boolean).flatMap((r) => r.bugs);
const fresh = found.filter((b) => !seen.has(key(b)));
if (!fresh.length) { dry++; continue; } // nothing
new, closer to dry
dry = 0;
fresh.forEach((b) => seen.add(key(b))); // dedupe vs
SEEN, not confirmed
// diverse lens verify: every fresh finding earns its
place
const judged = await parallel(fresh.map((b) => () =>
parallel(['correctness', 'security', 'repro'].map
((lens) => () =>
agent(`Judge "${b.desc}" via ${lens}. Real?`, {
schema: VERDICT })))
.then((v) => ({ b, real: v.filter(Boolean).filter
((x) => x.real).length >= 2 }))
));
confirmed.push(...judged.filter((v) => v.real).map((v)
=> v.b));
}
```
## 12. Tier the Models Across Your Nodes
Not every node needs your best model. A graph makes this obvious in a way a single agent never does: some nodes are bounded and repetitive, extract this field, classify this ticket. Others carry the actual judgment, synthesize the report, adjudicate the finding.
Run the boring nodes on a cheaper model and spend your expensive tokens where judgment actually lives.
In a workflow, every subagent Claude spawns inherits your session model unless the script overrides it, so by default a big run bills entirely at your session tier. The model option on a single agent() call tells Claude to route just that node somewhere else.
Check /model before a large run, then have Claude route the fan out's repetitive nodes down to a cheaper model while keeping the merge node up top. This is the lever that turns a token hungry graph into an economical one without touching its shape at all.
## 13. Topology Is Your Cost and Latency
The shape of the graph is not cosmetic. It is the single biggest lever you have on wall clock time. The choice that trips up basically everyone is parallel() versus pipeline().
A parallel() barrier makes everything wait for the slowest node before the next stage can start. A pipeline() streams each item through all the stages independently, with no barrier, so item A can be sitting in stage 3 while item B is still in stage 1. Fast items finish early instead of idling behind slow ones.
Default to pipeline(). Reach for a barrier only when a stage truly needs every prior result at once: a cross set dedupe, an early exit on the total, a prompt that compares one finding against all the others.
"It's cleaner code" and "the stages feel separate" are not reasons. Barrier latency is real, measurable, wasted time. Separate is not the same thing as synchronized.
| Shape | Use it when | What it costs you |
| --- | --- | --- |
| Chain | Each step really reads the last step's output | Slowest possible run, one stall kills everything |
| parallel() fan out | N independent jobs, and the next stage needs them all | Everyone waits for the slowest node |
| pipeline() | N independent jobs flowing through the same stages | Almost nothing, this is your default |
| Diamond | Breadth first, then one merged answer | One barrier, at the merge, where it is earned |
| Conditional | The path depends on what a node found | A classification call before the branch |
| Cycle | You don't know how big the job is | Runaway spend if it never converges |
## 14. Let Claude Draw the Graph
The final move is to stop drawing graphs by hand for jobs you cannot plan in advance.
With dynamic workflows you describe the objective and Claude writes the orchestration script itself: decomposing the task, choosing the fan out, spawning a coordinated fleet of subagents, and synthesizing the result. You end up with a graph tailored to **this** run instead of a fixed one you hoped would fit.
There are three ways in.
Say the word workflow in your prompt and Claude writes one for the task.
Run a saved or bundled one. /deep-research is a real graph shipping in production right now: scope, parallel search, fetch, adversarial verify, synthesize. That is the exact skeleton from this article.
Turn on ultracode and Claude plans a workflow for every substantial task in the session. When a run comes out good, press s to save its script into .claude/workflows/. Now it is version controlled, re-runnable by name, and a graph anyone who clones the repo can launch.
```
> Run a workflow to audit every route under src/routes/
for missing auth.
Spawn one agent per route file, then verify each
finding before reporting.
• Claude wrote an orchestration script · launching in
background...
/workflows > auth-audit · running
✓ Scope 1/1 2.1k tok · 4s
✓ Fan-out 18/18 one agent per route file
○ Verify 11/18 3-vote skeptics per finding...
○ Synthesize 0/1 waiting on verify
session stays responsive, keep working while the fleet
runs
```
## Six Graphs Worth Building This Week
- A security sweep across every route. One subagent per route file, each hunting missing auth checks, then a verifier pass that confirms every finding before it reaches the report. Breadth no single context could hold.
- A cited report with /deep-research. Claude splits your question into distinct angles, runs the searches in parallel, dedupes the sources, then adversarially verifies every claim with three vote skeptics before it writes a word.
- A module ported file by file. The Bun ceiling, scaled down to your repo. Claude fans translation out across files, runs the test suite as a gate on each one, and loops the failures back, with adversarial review catching what a single pass would have shipped broken.
- An adversarial review of a diff. Claude routes on diff size: a small change gets one quick pass, a large one triggers a full parallel audit with reviewers on distinct lenses, then a judge panel synthesizes the verdict.
- An ecosystem scan on a schedule. Save it once, re-run it forever. Claude checks many sources in parallel, releases, blogs, discussion, ranks by impact at a barrier, and writes the digest. Version controlled in .claude/workflows/, launchable by name.
- A discovery job of unknown size. You have no idea how many bugs are in there. Claude runs finders in parallel, dedupes each new find against everything seen, verifies the survivors, and keeps looping until two rounds turn up nothing new.
## Why This Actually Matters
Every one of these steps points at the same underlying thing. Your agent's ceiling is almost never the model. It is the shape of the work you handed it.
A chain forces one context to hold everything, one failure to halt everything, and every fast step to wait behind the slowest one. A graph spreads the context across a fleet, contains failure at the node, and buys you structure you can wrap confidence around: schemas at the nodes, verifiers on the edges, routing that runs the same way every time.
And the orchestration layer is code. That is the part people underestimate. Coordination between eighteen agents costs zero model tokens, because a script is not a conversation.
## What Actually Matters Here
If you only take three things from this: cut the arrows that carry no data, default to pipeline() instead of a barrier, and dedupe against everything you have seen rather than everything you confirmed.
Those three alone will make your agents faster, cheaper, and far harder to break than adding another step to the queue ever will.
The linear agent was never the ceiling. It was just the first shape everybody reaches for, because it matches how we type. One line, one head, one thing at a time.
A prompter asks a question. An architect draws a graph.
So which is your agent right now, a line or a graph?
If you made it this far, there is a lot more to this topic than fourteen steps and a few code blocks.
@seeconvm is where I keep breaking it down.
More coming soon.
## 相关链接
- [seeco](https://x.com/seeconvm)
- [@seeconvm](https://x.com/seeconvm)
- [4.2K](https://x.com/seeconvm/status/2088199384580108339/analytics)
- [@seeconvm](https://x.com/@seeconvm)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [5:41 PM · Aug 14, 2026](https://x.com/seeconvm/status/2088199384580108339)
- [4,209 Views](https://x.com/seeconvm/status/2088199384580108339/analytics)
- [View quotes](https://x.com/seeconvm/status/2088199384580108339/quotes)
---
*导出时间: 2026/8/15 20:44:31*
---
## 中文翻译
# 图工程:别再让你的智能体排队了
**作者**: seeco
**日期**: 2026-08-14T09:41:44.000Z
**来源**: [https://x.com/seeconvm/status/2088199384580108339](https://x.com/seeconvm/status/2088199384580108339)
---

我打开过的几乎每一个多步骤智能体都是一个队列。第一步,第二步,第三步,每一步都礼貌地等待着上一步完成。而一旦你仔细看,大约一半的步骤根本没有什么可等的。
它们不路由。不拆分。不并行运行任何东西。它们只是排队,一个大脑,一个上下文,一次只做一件事,直到窗口填满,智能体悄悄忘记了自己最初在做什么。
这里有个没人告诉你的关键点。提示词是一个句子。循环是一个周期。框架是你的智能体站立的地板。但工作本身的形状——什么在什么之前运行,什么可以同时运行,什么真正必须等待其他所有东西——这个形状是一个图。节点负责思考。边负责传递结果。
Claude Code 直接提供了构建这些图的工具:动态工作流。Claude 编写一个纯 JavaScript 编排脚本,然后启动一个协调的子智能体集群来执行它。协调本身消耗零模型令牌,因为它是代码,而不是另一段对话。
这是我用来将单个文件智能体转变为一个图的 14 步路线图,这个图可以扩展到整个集群,检查自己的发现,并得出单个智能体永远无法承载的结果。
## 概览
1. 节点是任务。边是流动的东西。
2. 你的线性脚本已经是一个图,只是一个糟糕的图。
3. 每个节点都有一个契约。
4. 每条边都有一个数据契约。
5. 使用 parallel() 进行扇出。
6. 在屏障处扇入,且仅在必要时。
7. 菱形:拆分、工作、合并。
8. 使用条件在运行时路由边。
9. 在边上放置验证器。
10. 隔离节点,使单个故障保持局部化。
11. 添加循环,但使其收敛。
12. 跨节点分层使用模型。
13. 拓扑结构就是你的成本和延迟。
14. 让 Claude 为你绘制图。
## 01. 节点和边,或为什么“然后”不是依赖关系
一个图恰好有两个部分,把它们搞清楚就能消除大部分困惑。
节点是工作单元。一个智能体,一个有界任务,一个输入进,一个输出出。
边是依赖关系。它表示这个节点的输出馈送到那个节点的输入。这就是全部定义。
几乎每个人都会犯的错误是把“然后”当作边。“总结这个文件,然后告诉我天气”中没有任何边。天气不消费摘要。这是两个断开的节点,线性脚本毫无理由地把它们串在一起。
要问的问题。对于智能体中的每一个“然后”:下一步真的会读取上一步的输出吗?如果不会,那里就没有边,等待纯粹是浪费。
```
把它画成方框和箭头。一个方框是一个 agent()
调用。一个箭头是一个变量,它离开一个调用的
返回值,进入另一个调用的提示词。如果你无法
画出箭头,如果没有变量跨越,那两个方框
就是独立的。这种独立性就是你将在本文其余部分
利用的东西。
```
## 02. 你的线性脚本是一个退化图
当你把智能体写成“做 A,然后 B,然后 C,然后 D”时,你已经画了一个图。你画的是最糟糕的那种:一个单一的无分支链,每个节点恰好有一条边进,一条边出。
它能运行。但它也运行缓慢,而且容易严重故障,因为链没有冗余。如果 C 停滞,D 永远不会发生,A 产生的所有东西都卡在上游无处可去。

这里第一个真正的技能是重新绘制链。拿你的线性智能体,走一遍每个箭头,问第 01 步的问题。在实践中你会发现两三个箭头根本不携带任何数据。它们存在只是因为那是你碰巧输入的顺序。
切断这些箭头,链就会向侧面坍塌成更宽的东西:几个独立的节点可以同时运行,馈送到一个需要所有它们的单一节点。
## 03. 给每个节点一个契约
一个你无法推理的节点是一个你无法并行化的节点。解决办法是契约:有界输入,有界输出,恰好一个任务。
输入是节点读取的任何内容,显式传入。绝不假设来自某个它碰巧所在的共享窗口。输出是定义好的形状,理想情况下经过验证,这样下一个节点就可以在不猜测的情况下消费它。

在工作流中,你通过模式来强制执行这一点。当你给 Claude 一个带有 JSON 模式的 agent() 调用时,它生成的子智能体被迫返回经过验证的结构化数据。验证发生在工具调用层,所以 Claude 会在不匹配时重试,而不是给你需要解析和祈祷的自由文本。
```
// 一个具有真实契约的节点:有界输入,验证过的
输出,一个任务。
const FINDING = {
type: 'object',
additionalProperties: false,
properties: {
title: { type: 'string' },
url: { type: 'string' },
impact: { type: 'string', enum: ['high', 'medium',
'low'] },
},
required: ['title', 'url', 'impact'],
};
const result = await agent(source.prompt, {
label: `research:${source.key}`,
schema: FINDING, // 强制验证过的
结构化输出
agentType: 'general-purpose',
});
// result 现在是下一个节点可以信任的形状,而不是
自由文本。
```
这就是 Claude 可以接入图的节点与只能在人类读取其输出时才能工作的节点之间的全部区别。
## 04. 边也是数据契约
边不是“B 在 A 之后”。它是一个关于什么跨越的承诺:A 产生这个形状,B 被构建来消费这个形状。用数据而不是顺序来命名你的边,两件事会变得容易得多。
你可以立即判断边是否真实存在,即数据是否真的在移动。而且你可以交换任一端上的节点,而不触及图的其余部分,只要形状保持不变。
在实践中,边存在于纯 JavaScript 中。扇出和综合之间的 reduce 步骤——扁平化、去重、过滤——只是对节点返回的形状进行操作的代码。
不需要智能体。这是图思维的一个安静的胜利:人们消耗大量模型令牌的事情实际上只是一个边,而边是免费的。
```
// 诱人的做法:生成一个智能体来“合并结果。”别
// 这样做。
// 如果合并意味着扁平化和去重,那就是 flatMap
加一个 Set。
// 确定性,即时,零令牌。
const flat = collected.flatMap((c) => c.items);
const clean = [...new Map(flat.map((i) => [i.url, i])).
values()];
```
把智能体留给判断。不要用于管道。一个每条边都是智能体的图,是一个为自己的布线支付租金的图。
## 05. 使用 parallel() 扇出
这是为其他一切买单的动作。当你有 N 个独立节点、N 个要检查的来源、N 个要审查的文件、N 条要审计的路由时,你不会把它们串起来。
你告诉 Claude 把它们扇出并同时运行。在工作流中,这就是 parallel():Claude 接受一个 thunk 数组,为每个 thunk 生成一个子智能体,并发运行它们,然后把结果数组交还给你。
两个细节使它健壮。首先,parallel() 是一个屏障,所以它会等待每个 thunk 完成才返回,下一阶段总是看到完整的集合。其次,抛出的 thunk 会解析为 null 而不是拒绝整个批次,所以一个不稳定的智能体不会搞砸整个运行。
在输出时始终 .filter(Boolean)。并发数上限大约是你的核心数,溢出会排队,所以你可以给它一百个 thunk,它们都会完成,只是一次几个。
```
phase('Research');
// 九个来源,九个智能体,全部同时。
const raw = await parallel(
SOURCES.map((s) => () =>
agent(s.prompt, {
label: `research:${s.key}`,
phase: 'Research',
schema: ITEM_SCHEMA, // 每个节点返回
验证过的 JSON
agentType: 'general-purpose',
}),
),
);
const collected = raw.filter(Boolean); // 丢弃来自
失败智能体的 null
```
扇出存在于 Claude 编写的代码中,而不是模型对话中。Claude 自己的上下文永远不会同时持有九个来源。每个子智能体携带自己的,只有最终答案返回。这就是让工作流扩展到几十或几百个子智能体而不淹没会话的原因,而编排层不花费任何成本,因为它不是 Claude 思考的另一轮。
## 06. 在屏障处扇入
扇出只有在有东西收集它时才有价值。扇入是你的边汇聚的节点,一个智能体或一段代码同时看到所有上游结果,并做一些真正需要整个集合的事情:跨来源去重,按影响排序,如果一切都返回空则提前退出。
这是屏障的墙钟时间成本唯一值得的地方。
保持图快速的规则:只有当阶段真正需要所有先前结果在一起时才使用屏障。跨所有来源去重符合条件。
```
// 边:纯 JS,无智能体,零令牌。
const flat = collected.flatMap((c) => c.items);
log(`Collected ${flat.length} items`);
phase('Curate');
// 屏障节点:需要整个集合来去重和
排序。
const curated = await agent(
`Dedupe and rank these by impact:\n${JSON.stringify
(flat)}`,
{ phase: 'Curate', schema: CURATED_SCHEMA },
);
```
仅仅扁平化列表不是屏障,它是一个边,内联做。气味测试极其简单:如果你写了 parallel,然后一个转换,然后又 parallel,而中间那个转换没有跨项目依赖,你应该使用管道并完全跳过屏障。
## 07. 菱形:拆分、工作、合并
把扇出和扇入放在一起,你就得到了每个严肃智能体图的主力拓扑:菱形。
一个节点拆分任务。许多节点并行工作。一个节点合并。这是市场扫描、依赖审计、代码审查、研究报告背后的形状。交换来源和提示词,同一个骨架适应所有它们。
规范形式值得记住:扇出、归约、综合。扇出以获取广度。用纯代码归约以压缩。用最终智能体综合以写答案。
一旦你能看到菱形,你就不再问“我如何让我的智能体做更多步骤”,而是开始问“拆分在哪里,合并在哪里”。第二个问题才是真正能扩展的。
## 08. 使用条件在运行时路由边
不是每个图都是固定的。有时你走哪条边取决于节点发现了什么。路由器节点检查结果并决定哪个下游路径触发:对工单进行分类,然后分支到正确的处理器。检查 diff 大小,然后要么做快速审查,要么启动完整审计。
在工作流中,这只是对节点验证输出做的 JavaScript if 或 switch,因为你的控制流存在于代码中。
```
// 路由器节点:智能体分类,代码选择边。
const { severity } = await agent(`Classify this diff's
risk:\n${diff}`, {
schema: {
type: 'object',
properties: { severity: { type: 'string', enum:
['low', 'high'] } },
required: ['severity'],
},
});
let review;
if (severity === 'high') {
// 重路径:完整并行审计
review = await parallel(FILES.map((f) => () => agent
(`Audit ${f}`)));
} else {
// 轻路径:一次快速通过
review = await agent(`Quick review of ${diff}`);
}
```
这就是确定性变成特性而不是限制的地方。路由器的决定可以由 Claude 驱动,一个子智能体进行分类。路由是 Claude 编写的代码,所以对于相同的分类,它每次都完全相同地运行。
你在节点获得 Claude 的判断,在边获得脚本的可靠性。没有突发的“Claude 今天决定跳过审计”的意外,因为跳过必须被写进图中,而它没有。
## 09. 在边上放置验证器
图的真正杠杆不是你有更多智能体。而是你可以围绕它们构建以产生信心的结构。
验证器节点位于边上,在结果被允许向下游传递之前,它的唯一任务是尝试杀死发现。如果它幸存下来,它就通过。如果没有,它永远不会到达你的答案。
三个值得掌握的范式:
- 对抗性验证。对于每个发现,生成 N 个独立的怀疑者,提示它们反驳它,只有大多数幸存时才保留它。
- 视角多样化验证。给每个验证器自己的视角,正确性、安全性、能否复现,因为多样性捕获 N 个相同检查永远不会捕获的失败模式。
- 评审团。从不同角度生成 N 个尝试,用并行评审打分,从获胜者综合,同时嫁接亚军的最佳部分。
这正是让一个真实团队将 Bun 运行时移植到具有内置于循环中的对抗性代码审查的模式。
## 10. 隔离节点,使单个故障保持局部化
在链中,故障会级联。C 死了,D 永远不会运行,整个事情停止。在图中,故障应该被限制在它的节点内。
部分已经成立:在 parallel() 内抛出的 thunk 解析为 null,所以八个好的智能体仍然返回,而一个坏的掉出。你的 .filter(Boolean) 就是遏制。设计每个扇入以容忍缺失输入,而不是假设完整集合。
更微妙的故障是节点互相踩踏。当智能体并行写文件时,它们会冲突。
解决办法是隔离:worktree。每个智能体在自己的 git worktree 中运行,在沙箱中做工作,最后干净地合并。只在节点真正并行写入时才使用它。它是针对一种特定拓扑的安全带,不是每次运行的默认税。
## 11. 添加循环,但使其收敛
有时你在进入之前不知道工作有多大。未知规模的发现。一个 bug 扫描,发现一个 bug 又揭示三个。这需要循环,一条受控的边回到较早的节点。
危险是明显的。永不收敛的循环是一个无限循环,生成智能体直到你的预算耗尽。

收敛的模式是循环直到枯竭:持续生成查找器,直到 K 个连续轮次没有发现新东西,然后停止。而这里有一个成败攸关的细节,几乎每个人第一次都会搞错:你用来去重的对象。
对一切见过的去重,而不仅仅是对确认的结果。否则被拒绝的发现每轮都会回来,循环永远不会枯竭,你构建了一台永远为重新发现同样的死胡同付费的机器。
```
const seen = new Set(); const confirmed = []; let dry = 0;
while (dry < 2) { // 2 轮空后停止
const found = (await parallel(
FINDERS.map((f) => () => agent(f.prompt, { schema:
BUGS }))
)).filter(Boolean).flatMap((r) => r.bugs);
const fresh = found.filter((b) => !seen.has(key(b)));
if (!fresh.length) { dry++; continue; } // 没有新东西,接近枯竭
dry = 0;
fresh.forEach((b) => seen.add(key(b))); // 对见过的去重,而非确认的
// 多样化视角验证:每个新发现都赢得自己的位置
const judged = await parallel(fresh.map((b) => () =>
parallel(['correctness', 'security', 'repro'].map
((lens) => () =>
agent(`Judge "${b.desc}" via ${lens}. Real?`, {
schema: VERDICT })))
.then((v) => ({ b, real: v.filter(Boolean).filter
((x) => x.real).length >= 2 }))
));
confirmed.push(...judged.filter((v) => v.real).map((v)
=> v.b));
}
```
## 12. 跨节点分层使用模型
不是每个节点都需要你最好的模型。图使这一点变得明显,而单个智能体永远不会:有些节点是有界和重复的,提取这个字段,分类这个工单。其他节点承载实际判断,综合报告,裁决发现。
在便宜的模型上运行无聊的节点,把昂贵的令牌花在判断真正存在的地方。
在工作流中,Claude 生成的每个子智能体都继承你的会话模型,除非脚本覆盖它,所以默认情况下大型运行完全按你的会话层级计费。单个 agent() 调用上的 model 选项告诉 Claude 只将该节点路由到其他地方。
在大型运行前检查 /model,然后让 Claude 将扇出的重复节点路由到更便宜的模型,同时保持合并节点在顶层。这是一个杠杆,可以在完全不改变图形状的情况下把令牌饥饿的图变成经济的图。
## 13. 拓扑结构就是你的成本和延迟
图的形状不是装饰性的。它是你在墙钟时间上拥有的最大杠杆。几乎每个人都会绊倒的选择是 parallel() 与 pipeline()。
parallel() 屏障使一切等待最慢的节点,然后下一阶段才能开始。pipeline() 独立地将每个项目流过所有阶段,没有屏障,所以项目 A 可以在阶段 3,而项目 B 仍在阶段 1。快速项目提前完成,而不是在慢项目后面闲置。
默认使用 pipeline()。只有当阶段真正需要所有先前结果同时出现时才使用屏障:跨集合去重,对总数的提前退出,将一个发现与所有其他发现进行比较的提示词。
“代码更干净”和“阶段感觉分离”不是理由。屏障延迟是真实的、可测量的、浪费的时间。分离不等于同步。
| 形状 | 何时使用 | 代价 |
| --- | --- | --- |
| 链 | 每一步真正读取上一步的输出 | 最慢的可能运行,一个停滞杀死一切 |
| parallel() 扇出 | N 个独立任务,下一阶段需要它们全部 | 每个人都等待最慢的节点 |
| pipeline() | N 个独立任务流过相同阶段 | 几乎没什么,这是你的默认 |
| 菱形 | 先广度,然后一个合并答案 | 一个屏障,在合并处,那里是值得的 |
| 条件 | 路径取决于节点发现的内容 | 分支前的分类调用 |
| 循环 | 你不知道工作有多大 | 如果永不收敛则失控支出 |
## 14. 让 Claude 绘制图
最后一步是停止为你无法提前计划的任务手工绘制图。
使用动态工作流,你描述目标,Claude 自己编写编排脚本:分解任务,选择扇出,启动协调的子智能体集群,综合结果。你最终得到一个针对**这次**运行定制的图,而不是一个你希望适合的固定图。
有三种进入方式。
在你的提示词中说 workflow 这个词,Claude 就会为任务编写一个。
运行一个保存的或捆绑的。/deep-research 是一个现在就在生产环境中运行的真实图:范围界定、并行搜索、获取、对抗性验证、综合。这正是本文的骨架。
打开 ultracode,Claude 为会话中的每个重要任务规划一个工作流。当一次运行结果良好时,按 s 将其脚本保存到 .claude/workflows/。现在它是版本控制的,可以按名称重新运行,任何克隆仓库的人都可以启动的图。
```
> Run a workflow to audit every route under src/routes/
for missing auth.
Spawn one agent per route file, then verify each
finding before reporting.
• Claude wrote an orchestration script · launching in
background...
/workflows > auth-audit · running
✓ Scope 1/1 2.1k tok · 4s
✓ Fan-out 18/18 one agent per route file
○ Verify 11/18 3-vote skeptics per finding...
○ Synthesize 0/1 waiting on verify
session stays responsive, keep working while the fleet
runs
```
## 本周值得构建的六个图
- 跨每条路由的安全扫描。每个路由文件一个子智能体,每个寻找缺失的认证检查,然后一个验证器通过,在报告前确认每个发现。单个上下文无法容纳的广度。
- 使用 /deep-research 的引用报告。Claude 将你的问题拆分成不同角度,并行运行搜索,对来源去重,然后在写一个字之前用三个投票怀疑者对抗性验证每个声明。
- 逐文件移植的模块。Bun 天花板,缩小到你的仓库。Claude 将翻译扇出到文件,运行测试套件作为每个文件的关口,并将失败循环回来,对抗性审查捕获单次通过会发布损坏的东西。
- 对 diff 的对抗性审查。Claude 根据 diff 大小路由:小改动一次快速通过,大改动触发完整并行审计,审查者使用不同视角,然后评审团综合裁决。
- 按计划进行的生态系统扫描。保存一次,永远重新运行。Claude 并行检查许多来源,发布、博客、讨论,在屏障处按影响排序,写摘要。版本控制在 .claude/workflows/,按名称启动。
- 未知规模的发现任务。你不知道里面有多少 bug。Claude 并行运行查找器,对每个新发现与一切见过的去重,验证幸存者,持续循环直到两轮没有新东西。
## 为什么这真的很重要
这些步骤中的每一个都指向同一个底层事物。你的智能体的天花板几乎从来不是模型。而是你交给它的工作形状。
链迫使一个上下文持有所有东西,一个故障停止一切,每个快速步骤等待最慢的。图将上下文分散到整个集群,在节点处遏制故障,并为你购买可以围绕信心构建的结构:节点处的模式,边上的验证器,每次都以相同方式运行的路由。
而编排层是代码。这是人们低估的部分。十八个智能体之间的协调消耗零模型令牌,因为脚本不是对话。
## 这里真正重要的是什么
如果你只从这带走三件事:切断不携带数据的箭头,默认使用 pipeline() 而不是屏障,对一切见过的去重而不是一切确认的。
仅这三件事就会使你的智能体更快、更便宜、远比给队列加另一步更难破坏。
线性智能体从来不是天花板。它只是每个人都首先想到的形状,因为它匹配我们打字的方式。一行,一个大脑,一次一件事。
提示者问问题。架构师画图。
那么你的智能体现在是什么,一条线还是一个图?
如果你读到这里,这个话题远不止十四步和几个代码块。
@seeconvm 是我持续拆解的地方。
更多内容即将到来。
## 相关链接
- [seeco](https://x.com/seeconvm)
- [@seeconvm](https://x.com/seeconvm)
- [4.2K](https://x.com/seeconvm/status/2088199384580108339/analytics)
- [@seeconvm](https://x.com/@seeconvm)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [5:41 PM · Aug 14, 2026](https://x.com/seeconvm/status/2088199384580108339)
- [4,209 Views](https://x.com/seeconvm/status/2088199384580108339/analytics)
- [View quotes](https://x.com/seeconvm/status/2088199384580108339/quotes)
---
*导出时间: 2026/8/15 20:44:31*