# Build self-improving agent system with Fable 5 in 14 steps : loops, dynamic workflows, routines
**作者**: Codez
**日期**: 2026-05-28T17:42:45.000Z
**来源**: [https://x.com/0xCodez/status/2065089060104720776](https://x.com/0xCodez/status/2065089060104720776)
---
Most people are using Claude Fable 5 like Sonnet 4.6 with a bigger context window. They prompt it. It works for 5 minutes. They close the tab.
9 out of 10 users have never run an agent system that compounds - where every run leaves the next run smarter, every state file accumulates, every skill sharpens.
Fable 5 was built to run for days. You’re using it for minutes. This is the 14-step roadmap to build the self-improving system Fable 5 was designed for.
> Follow my Substack to get fresh AI alpha: movez.substack.com
Claude Fable 5 launched June 9, 2026 - the first publicly available Mythos-class model, the tier Anthropic put one rung above Opus.
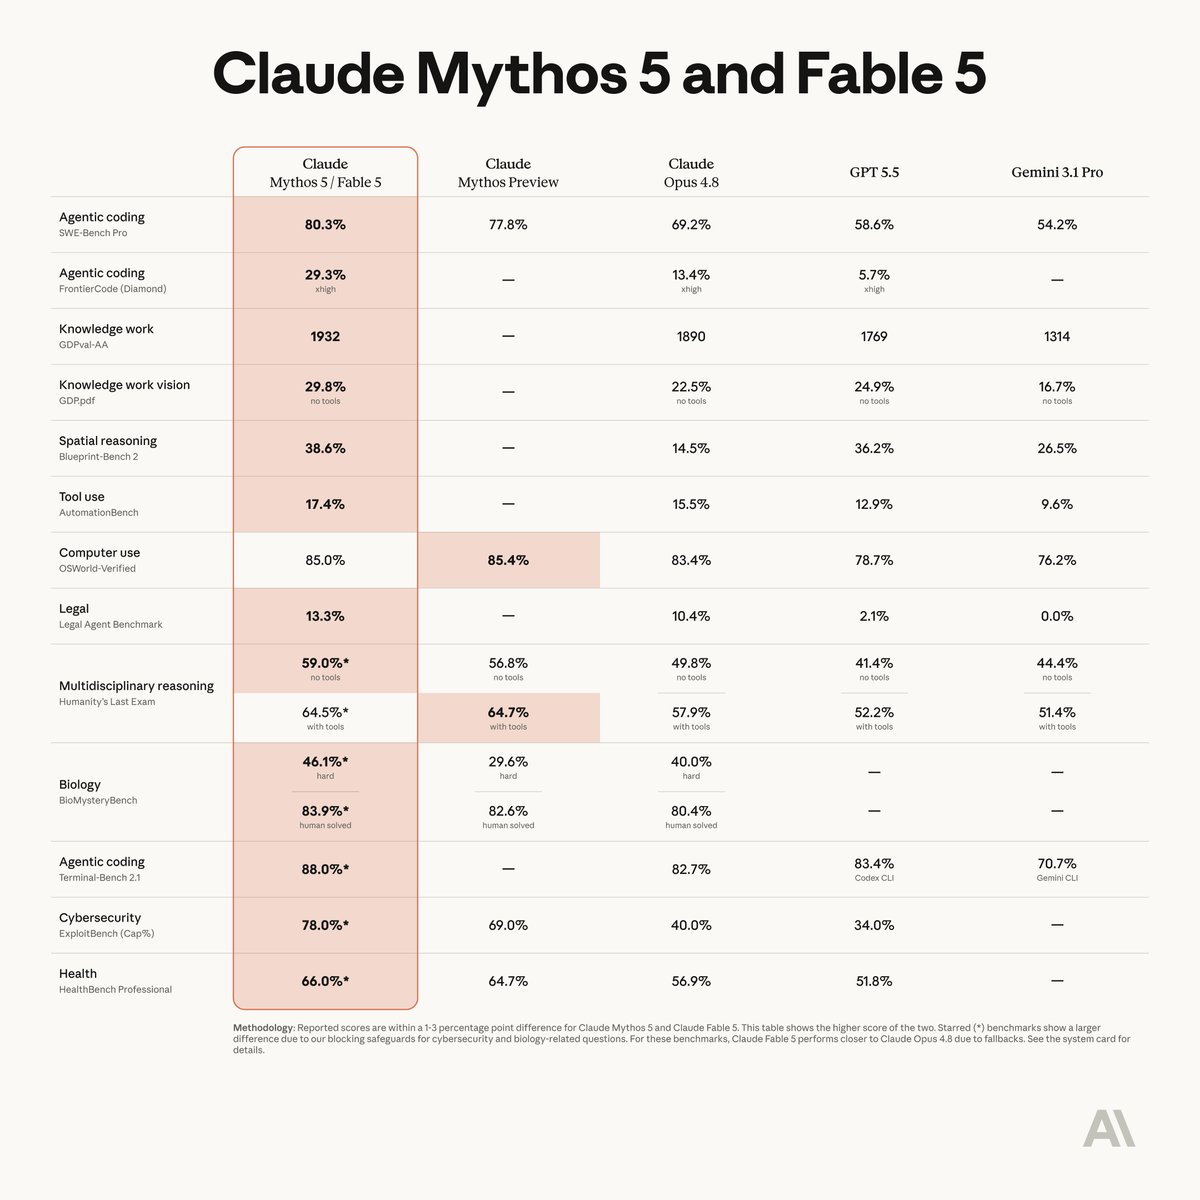
This is the 14-step roadmap to build the self-improving system Fable 5 was designed for - sourced from Anthropic engineering posts, the team’s public experiments, and verified against the launch documentation as of June 2026.
Three tiers: what Fable 5 actually unlocks, the three primitives that make it compound (loops, dynamic workflows, routines), and the self-improvement layer that turns it into a system.

14 steps. 3 tiers. Stop prompting. Start building a system that compounds.
PART 1 · What Fable 5 actually unlocks
## 01. Fable 5 is a Mythos-class model. Days-long autonomy is the headline.
Claude Fable 5 launched June 9, 2026 as the first publicly available Mythos-class model - the tier Anthropic introduced one rung above Opus.
Mythos Preview shipped in April through Project Glasswing to a handful of critical-infrastructure partners; Fable 5 is the version Anthropic considered safe for general release, with built-in safety classifiers that decline requests in high-risk areas.
Mythos 5 (without those classifiers) remains Glasswing-only.
What Fable 5 actually does that previous Claude models couldn’t sustain, from Anthropic’s launch documentation:
- Days-long autonomous sessions. Run inside an agent harness like Claude Code or Claude Managed Agents (CMA), Fable 5 can work for days - planning across stages, delegating to sub-agents, and checking its own work.
- Self-verification built in. Writes its own tests to check its work. Uses vision to check outputs against goals. Distills lessons into general rules. Tests its own assumptions.
- Most ambitious code work. Large migrations, complex implementations, multi-day autonomous coding sessions. The headline use case Anthropic puts forward is “hand off large projects and review completed deliverables.”
- Multi-stage knowledge work. Deep research and analysis to deliverables ready for review - with minimal oversight.
The pricing matches the tier: $10 per million input tokens, $50 per million output tokens, with the existing 90% input token discount for prompt caching.
Available on Claude API, AWS, Amazon Bedrock, Vertex AI, Microsoft Foundry, and the consumption-based Enterprise plan. This is not a subscription model. Heavy use earns its own bill.
## 02. Self-improving is not self-learning.
The phrase “self-improving agent system” gets thrown around carelessly. The version that’s real and the version that’s hype are very different things, and the gap is worth understanding before you build anything.
- Self-learning - the agent updates its own weights based on what it learns. Fable 5 does not do this. No publicly available model does this in production.
Recursive self-improvement (RSI) is the long-term direction Anthropic itself warned about in May 2026, not the capability shipping today.
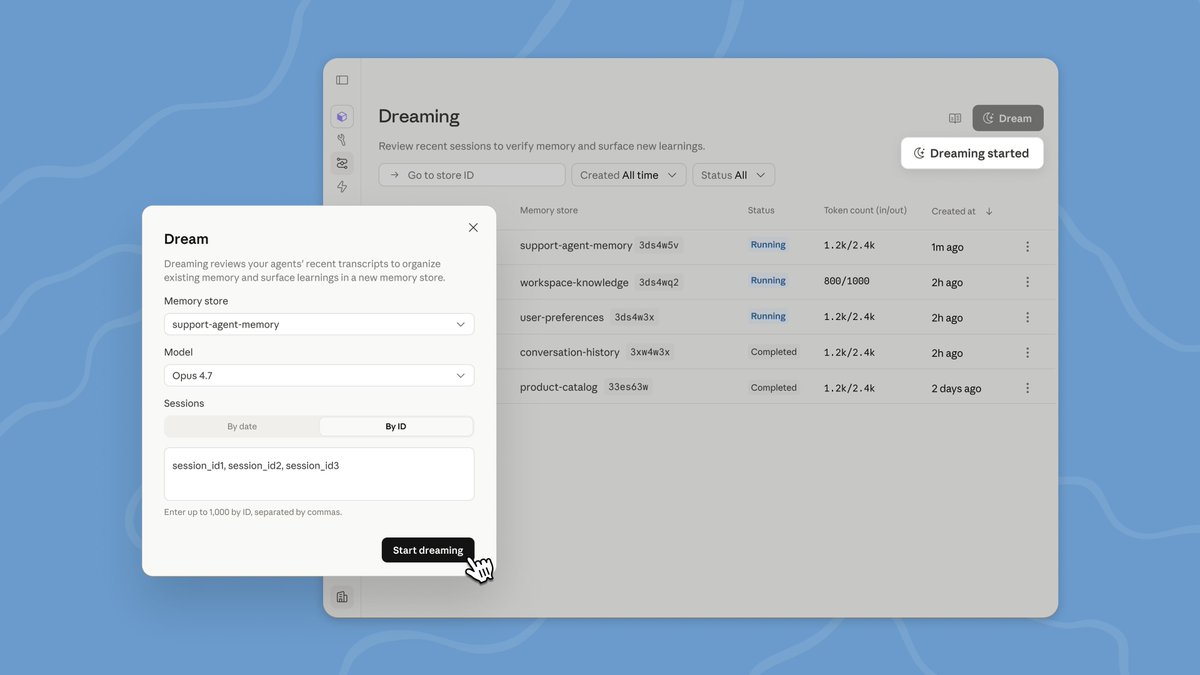
- Self-improving - the system around the agent compounds. Each session writes lessons to memory. Skills sharpen as edge cases get added.
State files accumulate verified facts. Eval loops refine prompts and rubrics. The model stays the same; the environment it runs in gets sharper.
Self-improvement, in this sense, is a property of the system you build. Fable 5 has the raw capability - long context, sub-agent delegation, vision self-check, days-long stamina - that turns the environment-feedback loop into something that actually compounds run over run.
> Anthropic’s engineering team puts it directly:
“Rather than directly prompting and steering Fable 5, it’s often better to design loops that let the model self-correct in response to environment feedback (e.g., /goal or Outcomes) and manage its own context (e.g., via memory).”
## 03. The compound stack: four layers, one feedback loop.
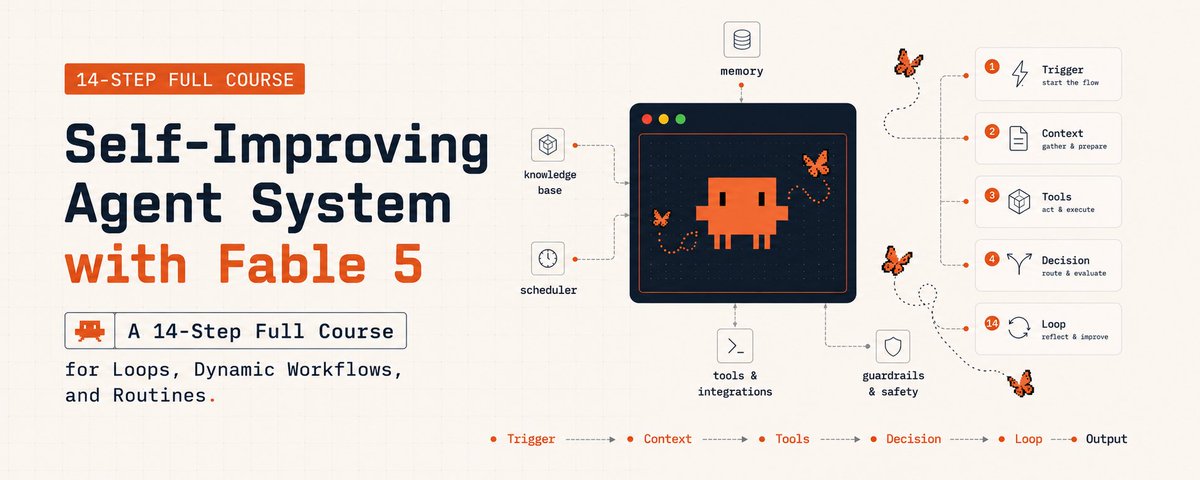
Figure 1 at the top of this article shows the architecture in one diagram. Read it from the bottom up - that’s the order the system gets built, and the order the leverage compounds.
- Layer 1 · Primitives. Fable 5 itself, sub-agents, worktrees, the tools the agent reaches for. Raw capability with no system around it yet. This is what most people use today.
- Layer 2 · Orchestration. /goal and Outcomes for self-correcting loops. Dynamic Workflows for complex multi-step orchestration. Routines for laptop-off cloud runs. This is what turns the primitives into a workflow.
- Layer 3 · Memory. State files, Skills, Knowledge Bases, lessons written down. Memory is what makes tomorrow’s session resume instead of restart.
- Layer 4 · Self-improvement. Vision self-checks, eval loops, rule distillation. The agent grades its own output, refines the Skill that produced it, writes the lesson back to memory. The loop closes.
The reason this architecture compounds: every output from layer 1 flows up through layer 4, where it gets graded, distilled, and written back to layer 3. Tomorrow’s run at layer 1 inherits the sharpened memory and refined Skills from yesterday. The model is stateless; the system around it isn’t.
## 04. When to use Fable 5 vs Opus 4.8 vs Sonnet 4.6. The cost-capability matrix.
Fable 5 costs ~5× what Opus 4.8 does per token. Not every step in a self-improving system needs the top tier. The teams running this in production route by task complexity, not by default:
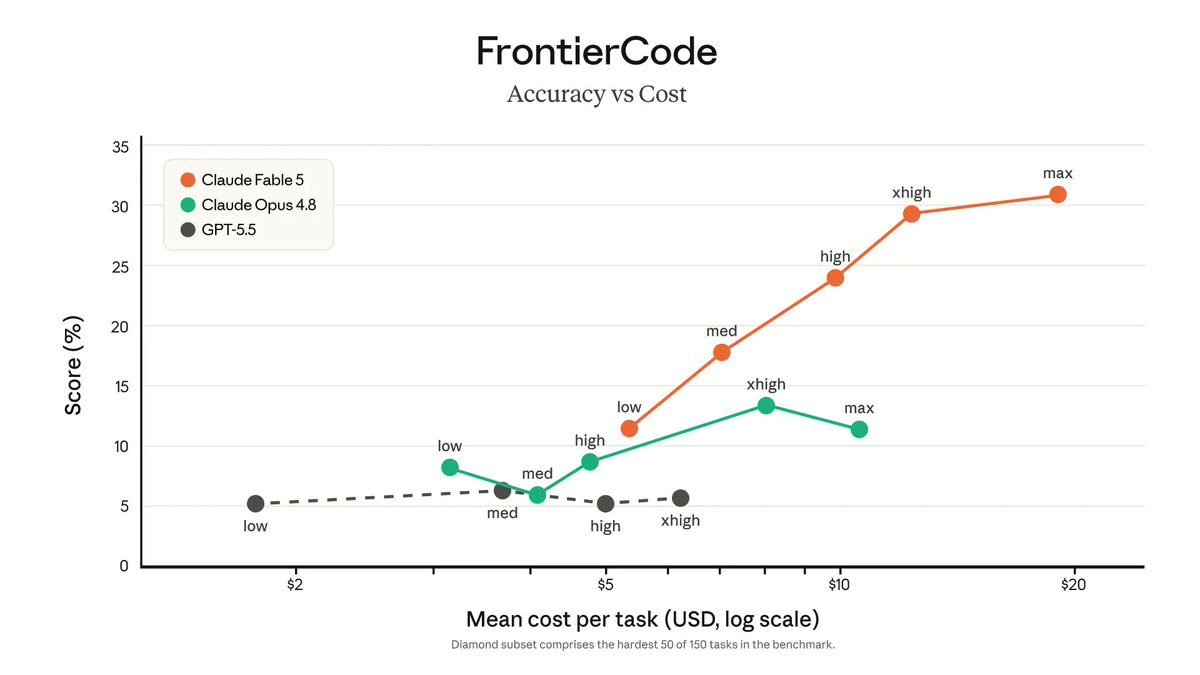
- Fable 5 for the heavy-lift orchestrator role: planning across days, delegating to sub-agents, checking work with vision, distilling rules from accumulated evidence.
Use Fable 5 where the “days at a time” capability earns its pricing.
- Opus 4.8 for hard-but-bounded subtasks the orchestrator delegates: architecture decisions, complex debugging, deep code reviews. Also the explicit fallback for any request Fable 5’s classifiers block (cyber, bio, chem, distillation).
- Sonnet 4.6 for high-volume worker tasks: lint passes, simple refactors, test scaffolding, doc updates. The bulk of fan-out work runs here.
- Haiku 4.5 for grader sub-agents and cheap classifiers. Independent context window, low cost - ideal for the verifier role Anthropic explicitly recommends.
The cost pattern that makes a self-improving system economical, used by teams running this in production: orchestrator on Fable 5, workers on Sonnet 4.6, graders on Haiku 4.5, fallback to Opus 4.8 on classifier blocks. Same pattern Anthropic engineers use internally.
PART 2 · The three Primitives
## 05. /goal vs Outcomes. Two implementations of the same idea.
The Anthropic Claude Code team publishes two near-identical primitives for goal-driven loops one in each harness.
They share the same shape: an independent grader checks the work, a not-met verdict starts the next iteration, the loop exits when the grader passes.
The implementations differ in surface details that matter for which you use.
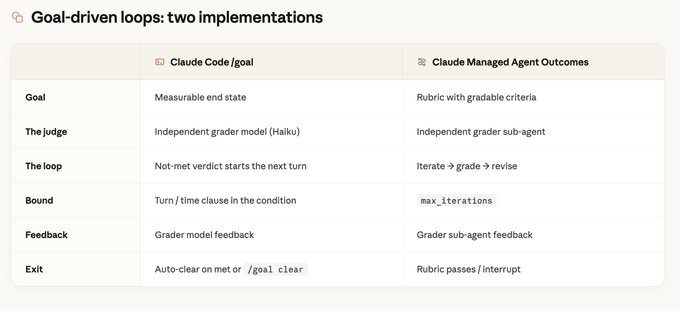
The decision rule between them is short:
- Use /goal in Claude Code when the work happens at your machine and you want a quick, in-session loop with a measurable end state. Best for hands-on coding, debugging flaky tests, refining a single file. Plain text goal, model grader, in-terminal feedback.
- Use Outcomes in CMA when the work needs to run for hours or days on Anthropic-hosted infrastructure with a sandbox, GPUs, or a controlled environment. Best for ML training, long-running migrations, multi-day research. File-based rubric with gradable criteria, sub-agent grader, hard max_iterations bound.
Both share the structural move that makes them work: the agent that wrote the code is not the agent that grades it. We go deeper on why that matters in step 6.
## 06. Verifier sub-agent beats self-critique.
Anthropic engineer Prithvi Rajasekaran wrote a piece on the engineering blog showing models have a hard time self-critiquing their own outputs. The Claude Code team confirmed this empirically with Fable 5:
> “We’ve found that a verifier sub-agent tends to outperform self-critique with Fable 5"
The mechanism is structural, not about “trying harder.” A model evaluating its own output sees its own reasoning trail and prefers conclusions consistent with what it already wrote.
A separate model evaluating the same output sees only the artifact and the rubric. The verifier has no skin in the maker’s game.
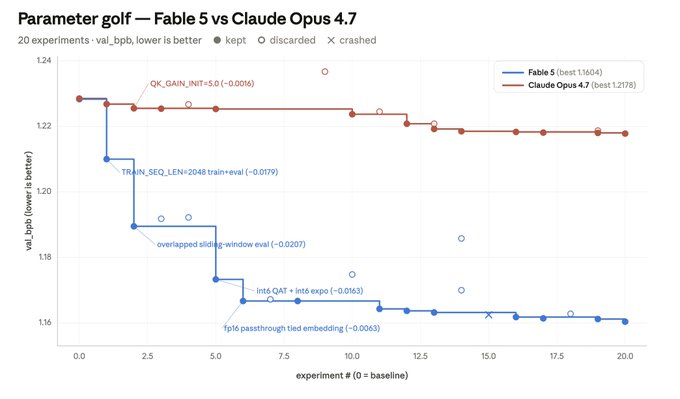
What the chart actually shows, beyond the headline numbers:
- Fable 5 made larger structural changes - TRAIN_SEQ_LEN=2048 train+eval (−0.0179), overlapped sliding-window eval (−0.0207), int6 QAT + int6 expo (−0.0163). Each is an architecture-level move, not a constant tweak.
- Fable 5 pushed through a quantization regression to its biggest win - instead of reverting after a failed experiment, it continued investigating.
- Opus 4.7’s first experiment (QK_GAIN_INIT=5.0) produced a small win. Nearly everything that followed used the same template: adjust a scalar, measure, keep if positive. The shape is safer, not better.
The takeaway for system design: Fable 5 with an independent verifier explores larger hypothesis spaces and recovers from negative intermediate results. Without the verifier, the same model has nothing forcing it past the first “good enough.”
## 07. Dynamic Workflows compose self-correction patterns.
Dynamic Workflows shipped in Claude Code on May 28, 2026.
The idea: Claude writes its own JavaScript harness on the fly - a file with agent(), parallel(), and pipeline() primitives, plus standard JS to process the data flowing between them. The harness is custom-built for the task, not generic.
> **cat@_catwu**: [原文链接](https://x.com/_catwu/status/2060054180379689074)
>
> Excited to share our most powerful new Claude Code feature: dynamic workflows!
> Mention "workflow" in a prompt and Claude will dynamically create an orchestration plan that it strictly follows, allowing you to confidently trust that every stage happens in the right order even
>
> 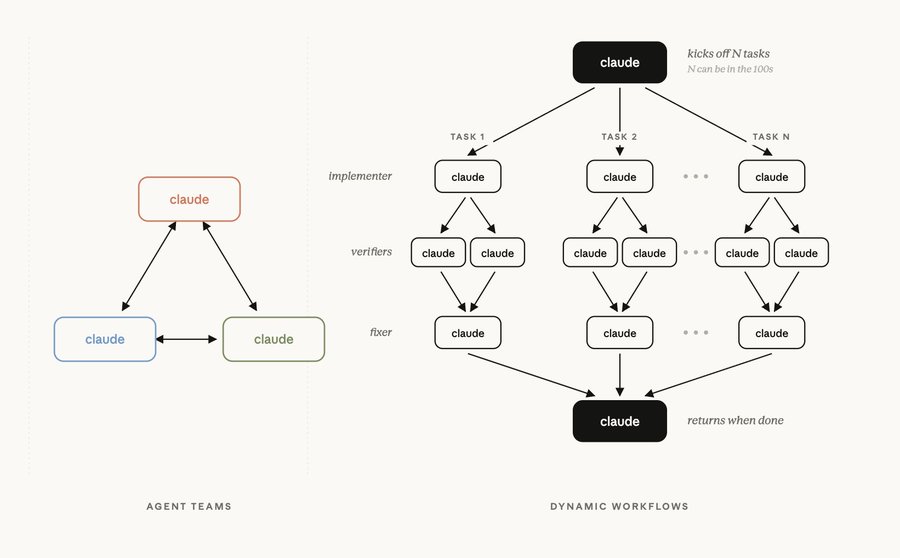
For self-improving systems with Fable 5, three of the six documented Dynamic Workflow patterns earn their place:
- Fan-out-and-synthesize. Split the work into N independent pieces, run an agent on each in parallel, synthesize results. Best when each step benefits from its own clean context window - e.g., evaluating each rule in a Skill against historical examples.
- Adversarial verification. For each maker agent, spawn an independent verifier with no exposure to the maker’s reasoning. The structural fix for self-preferential bias from step 6, applied per task.
- Loop until done. Loop spawning agents until a stop condition is met -no new findings, no more errors in the logs, theory verified. Pair with /goal to set a hard completion requirement.
The two patterns that don’t typically appear in self-improving systems but are worth knowing: classify-and-act (route the task to the right model based on a classifier) and tournament (pairwise comparison for taste-based ranking). The first is useful for model routing (step 4).
The second is rare in coding loops but useful for design or naming tasks.
## 08. Worktrees for parallel safety. Days-long Fable 5 sessions, no file collisions.
The moment a self-improving system spawns more than one agent, files start colliding. Two agents writing the same file is the same problem as two engineers committing to the same lines without talking first.
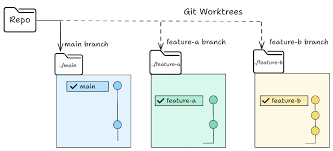
A git worktree fixes it - a separate working directory on its own branch sharing the same repo history, so one agent’s edits literally cannot touch the other’s checkout.
For self-improving systems where Fable 5 spawns sub-agents to verify or specialize, worktrees are non-optional:
- Maker writes in worktree A. Verifier reads in worktree B (or runs against the worktree A checkout with read-only filesystem). No risk the verifier’s exploration touches the maker’s state.
- Parallel structural experiments. If Fable 5 explores multiple architecture changes (like in Parameter Golf), each experiment runs in its own worktree. The orchestrator collects results from all of them; the best one merges.
- Days-long runs with checkpoints. Each major phase can be a separate worktree. A failed phase doesn’t poison the rest.
In Claude Code, worktrees are exposed three ways: git worktree directly, a --worktree flag to open a session in its own checkout, and an isolation: worktree setting on subagents so each helper gets a fresh checkout that cleans itself up after the session ends.
## 09. Routines for days-long orchestration. Laptop closed. Fable 5 working.
Routines launched April 14, 2026 in research preview. They’re saved Claude Code configurations - a prompt, repositories, connectors, permissions - that run on Anthropic-managed cloud infrastructure on a trigger.
Your laptop can be off. The run still happens.
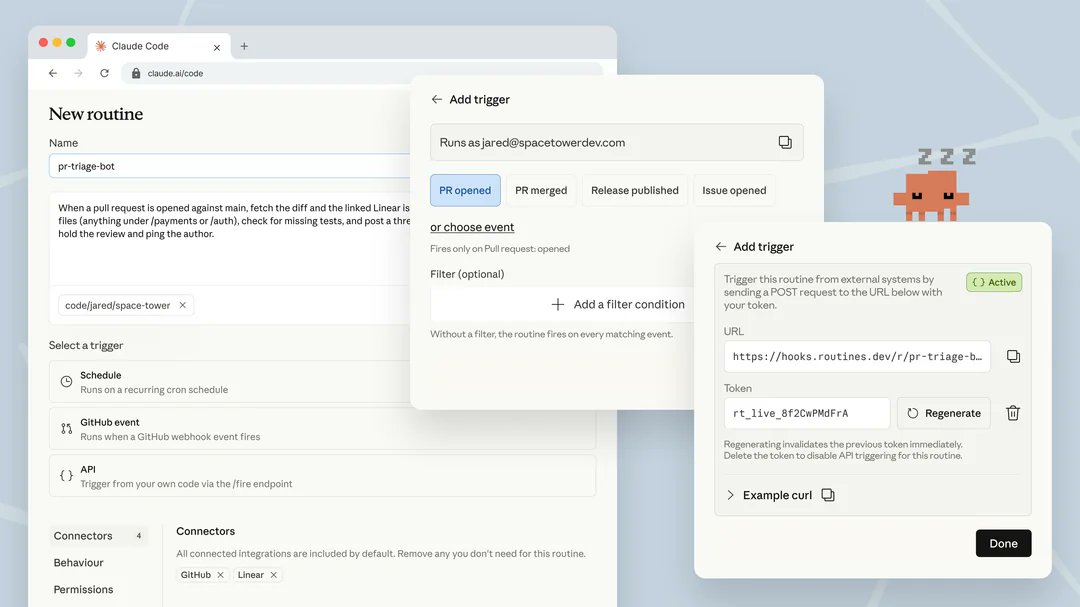
For Fable 5 specifically, Routines are the trigger layer that earns the model’s capability. Anthropic measures Fable 5’s “days at a time” on Claude Managed Agents - a hosted sandbox with full tools and no local machine constraint.
The Parameter Golf experiment ran for up to 8 hours on 8×H100 GPUs. That class of run doesn’t happen on your laptop.
The three Routine trigger types, mapped to self-improvement patterns:
- Schedule triggers - the morning briefing pattern. Daily at 7am: re-run yesterday’s eval suite, distill any new failure modes into Skills, write the digest to Slack. The agent gets sharper while you sleep.
- API triggers - the “fire on event” pattern. CI fails → fire a Routine to investigate. Sentry alert → fire a Routine to triage. The self-improving system reacts to your real environment, not a fixed schedule.
- GitHub event triggers - the “learn from real work” pattern. On PR open, run an evaluation against the latest Skills. On merge, write any new patterns the PR introduced back to the Skill. Repository state and Skill state stay in sync.
```
> /schedule daily at 7am, use Fable 5 in CMA
Goal: Re-run yesterday’s eval suite against the latest skills.
Any test that newly passes → distill the pattern into the skill.
Any test that newly fails → investigate, document in STATE.md.
Post the digest to #engineering. /goal don’t stop until digest is
posted and STATE.md is updated.
▲ Claude
Creating routine: nightly-eval-compounding
- model: claude-fable-5
- harness: claude managed agent (sandbox)
- trigger: schedule (0 7 * * *)
- grader: independent Haiku sub-agent (Outcomes)
✓ Active. First run tomorrow 07:00 local. Skill set will compound.
```
PART 3 · The Self-Improvement Layer
## 10. The 5-stage memory progression.
The single most useful framing for what “agent memory” means in practice comes from the Anthropic team’s Continual Learning Bench 1.0 experiment. Effective use of memory requires a progression of five stages. Each stage is a structural move; each model exits the progression at a different point.
- 1. Fail - the agent gets something wrong and documents the failure with enough detail to be useful later.
- 2. Investigate — before moving on, the agent figures out why the failure happened.
- 3. Verify - the agent turns the diagnosis into a checked fact, not a guess.
- 4. Distill - the agent turns the verification into a general rule that applies beyond the specific case.
- 5. Consult - on the next task, the agent reads the rule instead of re-deriving the fact from scratch.
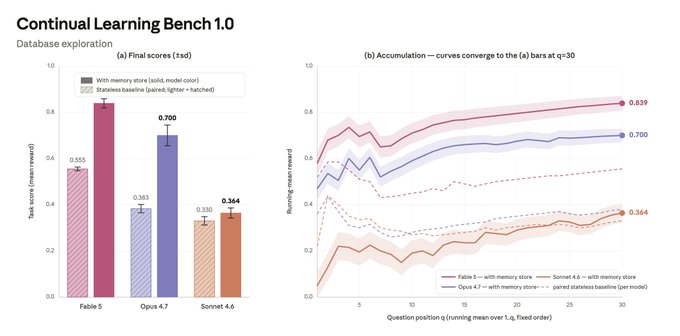
The measured difference between models on a SQL exploration task from the Continual Learning Bench, each model with memory provided:
- Sonnet 4.6 exits at step 1. Its memory store is a list of failure notes and open guesses (“maybe prc instead of prc_usd?”). It rarely consults prior notes. Memory exists but doesn’t compound.
- Opus 4.7 exits at step 3. It creates a schema reference with uncertainty flagged (“possibly prc in cents? Verify.”). Verification coverage runs 7–33% (median ~17%) of questions.
- Fable 5 tends to complete the progression. In its strongest runs, verification coverage reaches 73% (22 of 30), and it distills learnings into general rules that help with future tasks.
## 11. The state file. Where memory actually lives.
The 5-stage progression is the mental model. The state file is where the model writes each stage’s output. For Fable 5 running in Claude Managed Agents, memory is a mounted filesystem that survives between sessions; in Claude Code locally, a markdown file or a Linear board does the same job.
The structure of a state file that actually supports the 5-stage progression:
```
# Project memory · trading-platform
## Verified facts # stage 3 — stop guessing about these
- prc is in dollars, not cents. Verified via SELECT MIN(prc), MAX(prc) FROM trades.
- user_id matches auth_users.uid via JOIN, not auth_users.id. Confirmed 2026-06-09.
- Test database uses Stripe sandbox keys; production uses real keys via env.
## General rules # stage 4 — consult before re-deriving
- When querying time-bucketed metrics, always include timezone (default UTC mismatches).
- Auth middleware order matters: rate_limit -> jwt -> rbac. Reversing causes 401s.
- For migrations, never use ALTER on tables >1M rows without batching.
## Open failures (investigate next session) # stage 1 → 2
- 2026-06-09: tests/e2e/checkout flakes ~1 in 50 runs. Hypothesis: webhook race.
Reproduction steps in debug/checkout-flake.md.
## Lessons learned # stage 4 distillations
- PowerShell hits TLS 1.2 issue on Windows CI runners. Always shell out to bash.
- Stripe webhook tests require STRIPE_WEBHOOK_SECRET. Skip with clear message if missing.
## Last session # stage 5 — resume, don’t restart
2026-06-10 03:30 UTC · 7 failures classified, 3 fixes drafted (claude/fix-*), 4 escalated.
Next: verify the auth middleware fix in claude/fix-rate-limit-order against production load.
```
The file has five sections matching the five stages. Verified facts is stage 3 output - things the agent stopped guessing about. General rules is stage 4 - distilled rules that apply beyond the specific case. Open failures is stages 1–2 work in progress. Lessons learned is more stage 4 output.
Last session is the resume pointer for stage 5.
Two operational rules that decide whether this file actually compounds or just grows:
- Write before walking away. Every Fable 5 session ends by updating STATE.md - what was tried, what passed, what failed, what new rules survived. If the session doesn’t finish with a write, the next one restarts from zero.
- Read at session start. Every new session begins by reading STATE.md and the most relevant Skills. The Continual Learning Bench data shows that without this, Sonnet-class memory behavior shows up even in Fable 5.
## 12. Skills that compound. Write the lesson into the Skill, not just the chat.
STATE.md is for project memory. Skills are for procedural memory - the “how to do this kind of thing” that should apply across projects.
The compounding pattern: after any non-trivial failure, write the lesson into the Skill itself. The Skill gets sharper every time the system runs.
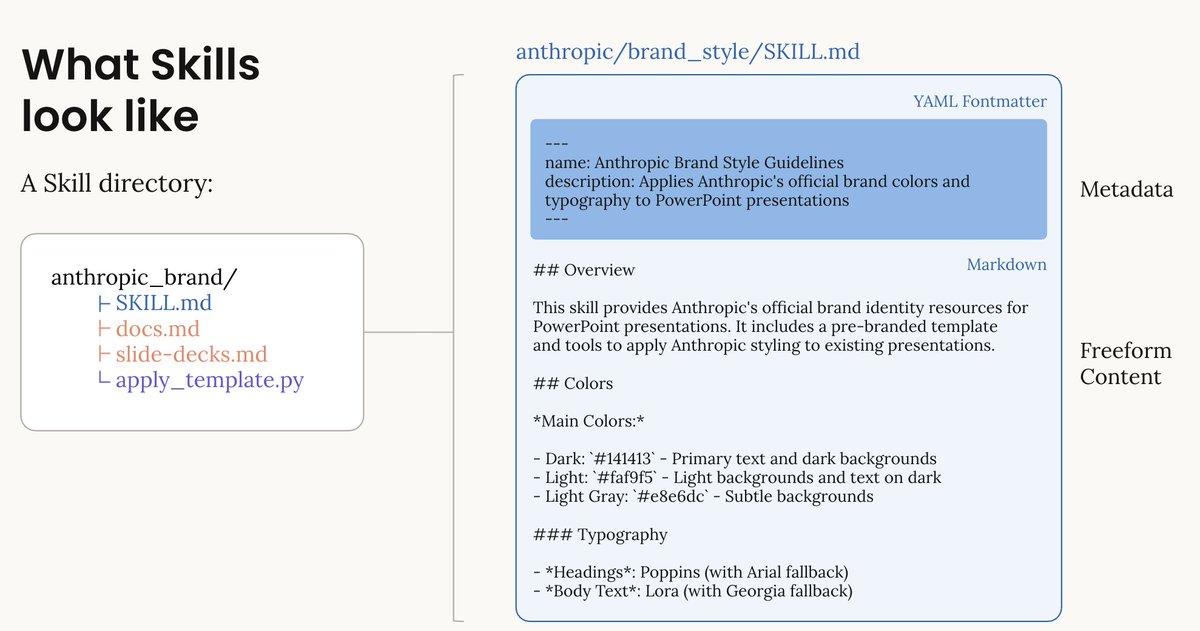
A Skill that’s been compounding for two weeks looks different from a fresh one. New sections appear: known failure modes, rules that came out of post-mortems, anti-patterns observed in production.
The Skill is no longer a static set of instructions; it’s an accumulating record of what the team has actually learned.
```
---
name: ci-triage
description: Classify CI failures, draft fixes for easy ones, escalate the rest.
Trigger on workflow_run.failure or on the morning triage routine.
---
# CI triage skill
## Classification rules
- env: missing secret, wrong env var. # escalate to human, never auto-fix
- flake: passes on retry without code change. # retry once, then file
- bug: deterministic failure tied to recent commit. # draft fix
- dependency: tied to version bump. # draft rollback
- infra: timeout, OOM, runner issue. # escalate
## Known failure modes # added by the loop over 14 days
- webhook-race: e2e checkout flakes when Stripe webhook arrives mid-test.
Fix: add 2s settle delay in tests/utils/webhook.ts.
- tls-handshake: Windows runners fail TLS 1.2 in PowerShell. Use bash.
- db-migration: ALTER on trades table >1M rows times out at 30s. Batch in 10k chunks.
## Anti-patterns (do NOT do) # added after real incidents
- Never disable a failing test to make CI green. File it instead.
- Never modify .github/workflows/ without human approval.
- Never touch src/payments/ or src/billing/ without security review.
## State
Update STATE.md after each run with classifications, fixes drafted, escalations.
## Eval suite # step 13 — the loop verifies the skill
Run against eval/ci-triage-cases.jsonl weekly. Any newly-failing case →
add to known failure modes after Outcomes verifier confirms.
```
The compounding contract: every confirmed lesson goes into a Skill, not just STATE.md. STATE.md is project-scoped and dies with the project. Skills live in ~/.claude/skills/ and travel with you.
Two weeks of disciplined writing produces a Skill that materially outperforms whatever Fable 5 would derive from scratch on a fresh project.
## 13. Self-verification via vision. Fable 5 checks its own UI against the goal.
One of the headline capabilities Anthropic ships with Fable 5 is “uses vision to check outputs against goals.” This sounds abstract until you see what it actually replaces: the human eyeballing a screenshot to confirm the UI looks right.
Fable 5 does that step itself, in the loop, before declaring done.
The pattern in production:
- Maker sub-agent writes the UI code. Renders the result to a screenshot.
- Verifier sub-agent reads the screenshot with vision, compares it against the goal description, against design tokens in the project Skill, and against the previous screenshot from STATE.md.
- Verdict goes back to the loop. Match → mark task complete. Mismatch → describe the gap, hand back to maker with a structured diff.
This pattern is what Anthropic measured in the Parameter Golf experiment under the same harness: Fable 5 looked at training charts (visual artifact) and decided whether the curve matched the criterion.
No human in the loop reading the chart. The verifier read the chart.
## 14. The Mythos safety boundary. What Fable 5 won’t do, and how to design around it.
he last step is the one most easily skipped on day one and most expensive to learn the hard way.
Fable 5 ships with built-in safety classifiers that decline to respond in specific high-risk domains - cybersecurity vulnerability research, biology, chemistry, and model distillation. In those domains, Anthropic falls Fable 5 back to Claude Opus 4.8 automatically. This is documented; it’s not a bug.
What this means for a self-improving system that runs autonomously:
- If your system touches security tooling (SAST scans, exploit research, penetration testing logic, even some classes of code review), expect classifier blocks. Architect for the fallback: route those tasks to Opus 4.8 explicitly, or surface the block to a human reviewer.
- Same for biology, chemistry, and distillation domains. The classifier is broad. A scientific computing workflow might trigger it; a code review of crypto primitives might trigger it.
- Design your Skills to surface the fallback gracefully. A Skill should know which kinds of tasks it produces that may hit the classifier and document the expected behavior. A loop that silently fails on a classifier block looks identical to a loop that fails on a real error — until you debug it.
- Audit the system card. Fable 5’s 319-page system card documents the classifier’s scope. The launch generated controversy in mid-June 2026 because some downgrade behaviors were discovered buried in the document. Read it before deploying to production.
The general design principle: treat the safety boundary as a known fallback, not as a failure mode. A self-improving system that ships with explicit handling of the boundary stays robust as the classifier evolves. A system that ignores it produces silent regressions when Anthropic updates the policy.
## § The mistakes that keep Fable 5 at 10% of its potential
- Using Fable 5 like Sonnet 4.6 with more context. A 5-minute prompt-and-close session burns Mythos-tier pricing for no compound effect.
- Self-critique instead of an independent verifier. The maker grades its own homework. Anthropic measured the difference; the team explicitly documents the verifier sub-agent pattern.
- No STATE.md. Every session restarts from zero. The Continual Learning Bench data shows this is where 70%+ of Fable 5’s memory advantage disappears.
- Skills that never get written to. A static Skill is fine; a Skill that doesn’t accumulate lessons after real failures is wasted scaffolding.
- Fable 5 on tasks Sonnet 4.6 would handle. Doc updates, simple refactors, lint fixes. Route by complexity; reserve Fable 5 for the orchestrator role.
- Running long sessions on a laptop. Days-long capability requires cloud infrastructure (CMA or Routines). A closed laptop kills the session.
- Ignoring the Mythos safety boundary. Classifier blocks on cyber/bio/chem produce silent regressions. Architect for the fallback explicitly.
- No vision-verify on visual tasks. UI, dashboards, design fidelity — checking these with text-only verifiers misses the failure mode that matters.
- Skipping /goal or Outcomes. Without an objective stop condition checked by an independent grader, loops stop at “handled enough” instead of done.
- No retention policy review. Sensitive data through a Fable 5 routine without checking the 30-day / 2-year terms creates compliance issues silently.
## Conclusion:
Fable 5 isn’t a faster chat tool. It’s the substrate for a system that compounds.
The first publicly available Mythos-class model didn’t ship to be prompted faster. It shipped to be the orchestrator of a self-improving system you build around it.
The capability headlines - days-long sessions, sub-agent delegation, vision self-check, accumulated memory - only earn their pricing if the system around the model is doing its job.
The Anthropic team’s own experiments make the gap visible. Parameter Golf: Fable 5 with an independent verifier explored larger architectural changes and pushed through negative intermediate results to land ~6× more improvement than Opus 4.7.
Continual Learning Bench: Fable 5 with memory completed the full 5-stage progression with 73% verification coverage, against Opus 4.7’s 17%. The model is the same in both halves of every comparison. The system around it is what changed.
Pick one layer of the compound stack you weren’t doing - probably the verifier sub-agent (step 6), the state file (step 11), or vision-verify (step 13) - and add it tomorrow. Then the next.
Self-improvement is a property of the system, not the model. Build the system.
## 相关链接
- [Codez](https://x.com/0xCodez)
- [@0xCodez](https://x.com/0xCodez)
- [4.2M](https://x.com/0xCodez/status/2065089060104720776/analytics)
- [movez.substack.com](https://movez.substack.com/)
- [May 29](https://x.com/_catwu/status/2060054180379689074)
- [1.6M](https://x.com/_catwu/status/2060054180379689074/analytics)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [11:09 PM · Jun 11, 2026](https://x.com/0xCodez/status/2065089060104720776)
- [4.2M Views](https://x.com/0xCodez/status/2065089060104720776/analytics)
- [View quotes](https://x.com/0xCodez/status/2065089060104720776/quotes)
---
*导出时间: 2026/7/9 09:12:56*
---
## 中文翻译
# 用 Fable 5 构建自我改进的智能体系统的 14 个步骤:循环、动态工作流、例程
**作者**: Codez
**日期**: 2026-05-28T17:42:45.000Z
**来源**: [https://x.com/0xCodez/status/2065089060104720776](https://x.com/0xCodez/status/2065089060104720776)
---

大多数人把 Claude Fable 5 当作拥有更大上下文窗口的 Sonnet 4.6 来用。他们输入提示词,它运行 5 分钟,然后他们关闭标签页。
10 个用户中有 9 个从未运行过一个能够复利累积的智能体系统——即每一次运行都让下一次运行更聪明,每一个状态文件不断累积,每一项技能不断精进。
Fable 5 是为连续运行数天而打造的,而你只用了几分钟。这就是构建 Fable 5 所设计的自我改进系统的 14 步路线图。
> 关注我的 Substack 获取最新的 AI 情报:movez.substack.com
Claude Fable 5 于 2026 年 6 月 9 日发布——这是首个公开发布的 Mythos 级模型,是 Anthropic 排在 Opus 之上一个等级的层级。

这是构建 Fable 5 所设计的自我改进系统的 14 步路线图——来源包括 Anthropic 的工程博客、团队的公开实验,并已根据截至 2026 年 6 月的发布文档进行了核实。
三个层级:Fable 5 究竟解锁了什么、使其能够复利累积的三个基本要素(循环、动态工作流、例程),以及将其转化为一个系统的自我改进层。

14 个步骤。3 个层级。别再输入提示词了。开始构建一个能够复利累积的系统。
第 1 部分 · Fable 5 究竟解锁了什么
## 01. Fable 5 是一个 Mythos 级模型。连续数天的自主运行是其最大亮点。
Claude Fable 5 于 2026 年 6 月 9 日发布,是首个公开发布的 Mythos 级模型——这是 Anthropic 推出的排在 Opus 之上一个等级的层级。

Mythos Preview 于 4 月通过 Project Glasswing 面向少数关键基础设施合作伙伴发布;而 Fable 5 是 Anthropic 认为可以安全公开发布的版本,内置了安全分类器,会在高风险领域拒绝请求。
Mythos 5(不含这些分类器)仍然仅限于 Glasswing 使用。
根据 Anthropic 的发布文档,Fable 5 能够做到此前 Claude 模型无法持续做到的事情:
- 连续数天的自主会话。在 Claude Code 或 Claude Managed Agents (CMA) 等智能体框架内运行时,Fable 5 可以连续工作数天——跨阶段进行规划、委派给子智能体,并检查自己的工作。
- 内置自我验证。它会编写自己的测试来检查工作。利用视觉能力对照目标检查输出。将经验提炼为通用规则。测试自己的假设。
- 最具雄心的代码工作。大型迁移、复杂实现、连续数天的自主编码会话。Anthropic 提出的主打用例是“交接大型项目并审查已完成的交付物”。
- 多阶段知识工作。从深度研究与分析到可供审查的交付物——只需最少的监督。
定价与该层级相匹配:每百万输入 token 10 美元,每百万输出 token 50 美元,提示词缓存仍可享受现有的 90% 输入 token 折扣。
可通过 Claude API、AWS、Amazon Bedrock、Vertex AI、Microsoft Foundry 以及基于用量的企业计划使用。这不是订阅模式。重度使用会产生相应的账单。
## 02. 自我改进不等于自我学习。
“自我改进的智能体系统”这个说法常被随意使用。真实的版本与炒作的版本是完全不同的两回事,在构建任何东西之前,值得先理解这个差距。

- 自我学习——智能体根据所学内容更新自身的权重。Fable 5 不做这件事。目前没有任何公开发布的模型在生产环境中做到这一点。
递归自我改进(RSI)是 Anthropic 自己在 2026 年 5 月警告过的长期方向,而不是今天所发布的能力。
- 自我改进——智能体周围的系统在复利累积。每次会话将经验写入记忆。随着边界情况不断加入,技能不断精进。
状态文件累积已验证的事实。评估循环优化提示词和评分标准。模型保持不变;而它运行的环境却变得越来越精细。
从这个意义上说,自我改进是你所构建的系统的一种属性。Fable 5 具备将环境反馈循环转变为真正能够随运行而累积的东西的原始能力——长上下文、子智能体委派、视觉自我检查、连续数天的续航能力。
> Anthropic 的工程团队直接指出:
“与其直接提示和引导 Fable 5,更好的做法往往是设计出让模型根据环境反馈(例如 /goal 或 Outcomes)进行自我纠正的循环,并让它管理自己的上下文(例如通过记忆)。”
## 03. 复利堆栈:四层,一个反馈循环。
本文顶部的图 1 用一张图表展示了这一架构。请自下而上阅读——这既是系统构建的顺序,也是杠杆作用复利累积的顺序。
- 第 1 层 · 基本要素。Fable 5 本身、子智能体、worktree、智能体所调用的工具。尚无系统围绕的原始能力。这就是大多数人今天的使用方式。
- 第 2 层 · 编排。用于自我纠正循环的 /goal 和 Outcomes。用于复杂多步骤编排的动态工作流(Dynamic Workflows)。用于笔记本合盖后云端运行的例程(Routines)。这是将基本要素转化为工作流的关键。
- 第 3 层 · 记忆。状态文件、技能(Skills)、知识库(Knowledge Bases)、记录下来的经验。记忆让明天的会话得以延续,而不是从头开始。
- 第 4 层 · 自我改进。视觉自我检查、评估循环、规则提炼。智能体给自己的输出打分,优化产出该输出的技能,并将经验写回记忆。循环就此闭合。
这种架构能产生复利效应的原因在于:第 1 层的每一项输出都会向上流入第 4 层,在那里被打分、提炼,并回写到第 3 层。明天的第 1 层运行将继承今天打磨过的记忆和优化后的 Skills。模型本身是无状态的,但它周围的系统不是。
## 04. 何时使用 Fable 5、Opus 4.8 还是 Sonnet 4.6:成本-能力矩阵
Fable 5 每 token 的成本约为 Opus 4.8 的 5 倍。并非自我改进系统中的每一步都需要顶级模型。在生产环境中运行这套系统的团队会按任务复杂度进行路由,而不是一刀切:

- Fable 5 用于重量级的编排者角色:跨天规划、向子代理委派任务、用视觉检查工作、从积累的证据中提炼规则。
在“一次运行数天”的能力物有所值的地方,使用 Fable 5。
- Opus 4.8 用于编排者委派的困难但有边界的子任务:架构决策、复杂调试、深度代码审查。同时也是任何被 Fable 5 分类器拦截的请求(网络、生物、化学、蒸馏)的显式后备选项。
- Sonnet 4.6 用于高吞吐量的执行者任务:lint 检查、简单重构、测试脚手架、文档更新。大部分扇出工作在这里运行。
- Haiku 4.5 用于评分子代理和廉价分类器。独立的上下文窗口,低成本——是 Anthropic 明确推荐的验证者角色的理想选择。
让自我改进系统在经济上可行的成本模式(生产环境中运行该系统的团队所采用的):编排者用 Fable 5,执行者用 Sonnet 4.6,评分者用 Haiku 4.5,分类器拦截时回退到 Opus 4.8。这与 Anthropic 工程师内部使用的模式相同。
第 2 部分 · 三个原语
## 05. /goal 与 Outcomes:同一思想的两种实现
Anthropic 的 Claude Code 团队发布了两个几乎相同的面向目标循环的原语——分别存在于各自的 harness 中。
它们具有相同的结构:一个独立的评分者检查工作,“未达标”的判定会启动下一轮迭代,评分者通过时循环退出。
两者的实现差异在于一些影响使用选择的表面细节。

两者之间的决策规则很简短:
- 当工作发生在你自己的机器上,且你想要一个快速的、会话内的循环并有可度量的终点状态时,在 Claude Code 中使用 /goal。最适合动手编码、调试不稳定的测试、打磨单个文件。纯文本目标、模型评分者、终端内反馈。
- 当工作需要在 Anthropic 托管的基础设施上运行数小时或数天,并配备沙箱、GPU 或受控环境时,在 CMA 中使用 Outcomes。最适合 ML 训练、长时间迁移、多天研究。基于文件的评分标准(含可评分的条目)、子代理评分者、硬性 max_iterations 上限。
两者共享一个使其生效的结构性设计:编写代码的代理不是给代码打分的代理。我们将在第 6 步深入探讨这为什么重要。
## 06. 验证者子代理胜过自我批评
Anthropic 工程师 Prithvi Rajasekaran 在工程博客上撰文指出,模型很难对自身的输出进行自我批评。Claude Code 团队通过 Fable 5 在实证上证实了这一点:
> “我们发现,验证者子代理往往比 Fable 5 的自我批评表现更好”
其机制是结构性的,与“更加努力”无关。模型在评估自己的输出时,会看到自己的推理轨迹,并倾向于与已有结论一致的判断。
而一个独立的模型在评估同一输出时,只看到产出物本身和评分标准。验证者在制造者的博弈中没有利益牵连。

除了标题数字之外,图表真正展示的内容是:
- Fable 5 做出了更大规模的结构性改动——TRAIN_SEQ_LEN=2048 训练+评估(−0.0179)、重叠滑动窗口评估(−0.0207)、int6 QAT + int6 expo(−0.0163)。每一项都是架构层面的举措,而非调整某个常数。
- Fable 5 在经历一次量化性能倒退后仍坚持并取得了最大收益——它在实验失败后没有回滚,而是继续研究。
- Opus 4.7 的第一个实验(QK_GAIN_INIT=5.0)带来了小幅收益。之后的几乎所有操作都沿用同一个模板:调整一个标量、测量、若有正收益就保留。这种模式更安全,但不更好。
对系统设计的启示:配备独立验证者的 Fable 5 能探索更大的假设空间,并能从中间的负面结果中恢复。没有验证者,同一个模型就没有任何机制迫使它越过第一个“足够好”。
## 07. Dynamic Workflows 组合自我修正模式
Dynamic Workflows 于 2026 年 5 月 28 日在 Claude Code 中发布。
其理念是:Claude 即时编写自己的 JavaScript harness——一个包含 agent()、parallel() 和 pipeline() 原语以及标准 JS 代码的文件,用于处理在它们之间流动的数据。这个 harness 是为任务量身定制的,而非通用模板。
> **cat@_catwu**: [原文链接](https://x.com/_catwu/status/2060054180379689074)
>
> 很高兴分享我们最强大的 Claude Code 新功能:动态工作流!
> 在提示词中提到 "workflow",Claude 就会动态创建一个编排计划并严格执行,让你可以放心地相信每个阶段都按正确的顺序发生,甚至
>
> 
对于使用 Fable 5 的自我改进系统,六种官方文档记载的 Dynamic Workflow 模式中有三种值得采用:
- 扇出并综合(Fan-out-and-synthesize)。将工作拆分为 N 个独立部分,并行地为每个部分运行一个代理,然后综合结果。最适合每一步都能受益于自己干净的上下文窗口的场景——例如,针对历史示例评估 Skill 中的每条规则。
- 对抗性验证(Adversarial verification)。为每个制造者代理生成一个独立验证者,且该验证者不会接触到制造者的推理过程。这是第 6 步中自我偏好偏差的结构性修复方案,按任务应用。
- 循环直至完成(Loop until done)。循环生成代理,直到满足停止条件——没有新发现、日志中没有更多错误、理论得到验证。与 /goal 搭配以设定硬性的完成要求。
通常不会出现在自我改进系统中的两种模式,但值得了解:分类-执行(classify-and-act,通过分类器将任务路由到合适的模型)和锦标赛(tournament,通过两两比较进行基于品味的排名)。前者对模型路由(第 4 步)很有用。
后者在编码循环中很少见,但对设计或命名任务很有用。
## 08. Worktree 保障并行安全。长达数天的 Fable 5 会话,没有文件冲突。
一旦自我改进系统产生多个代理,文件就会开始冲突。两个代理写同一个文件,和两个工程师没有先沟通就提交同一行代码,是同一个问题。

Git worktree 可以解决这个问题——它是一个独立的工作目录,拥有自己的分支但共享同一个仓库历史,因此一个代理的修改在物理上不可能触及另一个代理的检出内容。
对于 Fable 5 会派生子代理进行验证或专项处理的自我改进系统来说,worktree 是必不可少的:
- Maker 在 worktree A 中写入。Verifier 在 worktree B 中读取(或以只读文件系统方式针对 worktree A 的检出运行)。Verifier 的探索绝不会触及 Maker 的状态。
- 并行结构实验。如果 Fable 5 探索多个架构变更(如 Parameter Golf),每个实验都在自己的 worktree 中运行。编排器收集所有结果,最优的那个被合并。
- 带检查点的多天运行。每个主要阶段都可以是一个独立的 worktree。某个阶段失败不会污染其余部分。
在 Claude Code 中,worktree 有三种使用方式:直接使用 git worktree、使用 --worktree 标志在独立检出的会话中打开,以及在子代理上设置 isolation: worktree,让每个辅助代理获得一个全新的检出,会话结束后自动清理。
## 09. Routines 实现多天编排。合上笔记本电脑。Fable 5 在工作。
Routines 于 2026 年 4 月 14 日以研究预览版形式发布。它们是保存下来的 Claude Code 配置——包括提示词、仓库、连接器、权限——由触发器启动,在 Anthropic 管理的云基础设施上运行。
你的笔记本电脑可以关机。运行仍会进行。

具体到 Fable 5,Routines 是释放模型能力的触发层。Anthropic 在 Claude Managed Agents——一个拥有完整工具、不受本地机器限制的托管沙箱——上衡量 Fable 5 的“连续数天”能力。
Parameter Golf 实验在 8×H100 GPU 上运行了长达 8 小时。这类运行不会发生在你的笔记本电脑上。
三种 Routine 触发类型,对应到自我改进模式:
- 定时触发器——“晨间简报”模式。每天早上 7 点:重新运行昨天的评估套件,将新的失败模式提炼为 Skills,将摘要写入 Slack。你睡觉时,代理变得更敏锐。
- API 触发器——“事件触发”模式。CI 失败 → 触发一个 Routine 进行调查。Sentry 告警 → 触发一个 Routine 进行分诊。自我改进系统对你的真实环境做出反应,而非固定的时间表。
- GitHub 事件触发器——“从真实工作学习”模式。PR 打开时,针对最新的 Skills 运行评估。合并时,将 PR 引入的任何新模式写回 Skill。仓库状态和 Skill 状态保持同步。
```
> /schedule daily at 7am, use Fable 5 in CMA
Goal: Re-run yesterday’s eval suite against the latest skills.
Any test that newly passes → distill the pattern into the skill.
Any test that newly fails → investigate, document in STATE.md.
Post the digest to #engineering. /goal don’t stop until digest is
posted and STATE.md is updated.
▲ Claude
Creating routine: nightly-eval-compounding
- model: claude-fable-5
- harness: claude managed agent (sandbox)
- trigger: schedule (0 7 * * *)
- grader: independent Haiku sub-agent (Outcomes)
✓ Active. First run tomorrow 07:00 local. Skill set will compound.
```
第 3 部分 · 自我改进层
## 10. 五阶段记忆进阶。
关于“代理记忆”在实践中意味着什么,最有用的框架来自 Anthropic 团队的 Continual Learning Bench 1.0 实验。有效使用记忆需要经历五个阶段的进阶。每个阶段都是一次结构性动作;每个模型在进阶过程中退出的位置各不相同。
- 1. 失败——代理出错,并以足够的细节记录失败,以便日后使用。
- 2. 调查——在继续之前,代理弄清楚失败为什么会发生。
- 3. 验证——代理将诊断结果转化为经过核实的事实,而不是猜测。
- 4. 提炼——代理将验证结果转化为超越特定案例的通用规则。
- 5. 查阅——在下一个任务中,代理直接读取该规则,而不是从头重新推导事实。

在 Continual Learning Bench 的一项 SQL 探索任务中测得的模型间差异(每个模型都提供了记忆):
- Sonnet 4.6 在第 1 步退出。它的记忆存储是一份失败笔记和未验证的猜测列表(“也许是 prc 而不是 prc_usd?”)。它很少查阅之前的笔记。记忆存在,但无法累积。
- Opus 4.7 在第 3 步退出。它创建了标注了不确定性的模式参考(“prc 可能是美分?待验证。”)。验证覆盖率为问题的 7–33%(中位数约 17%)。
- Fable 5 倾向于完成整个进阶。在其表现最佳的运行中,验证覆盖率达到 73%(30 个中的 22 个),并且它将学到的内容提炼成有助于未来任务的通用规则。
## 11. 状态文件。记忆真正所在之处。
五阶段进阶是心智模型。状态文件则是模型写入每个阶段输出的地方。对于在 Claude Managed Agents 中运行的 Fable 5,记忆是一个跨会话存续的挂载文件系统;在本地 Claude Code 中,一个 markdown 文件或 Linear 看板可以起到同样的作用。
真正支持五阶段进阶的状态文件结构:
```
# Project memory · trading-platform
## 已验证的事实 # 阶段 3 — 别再瞎猜这些了
- prc 的单位是美元,不是美分。已通过 SELECT MIN(prc), MAX(prc) FROM trades 验证。
- user_id 通过 JOIN 匹配 auth_users.uid,而不是 auth_users.id。已于 2026-06-09 确认。
- 测试数据库使用 Stripe 沙盒密钥;生产环境通过环境变量使用真实密钥。
## 通用规则 # 阶段 4 — 重新推导之前先查阅
- 查询按时间分桶的指标时,务必包含时区(默认 UTC 常导致不匹配)。
- 认证中间件的顺序很重要:rate_limit -> jwt -> rbac。颠倒顺序会导致 401 错误。
- 对于数据库迁移,超过 100 万行的表绝不要在不分批的情况下直接使用 ALTER。
## 未解决的故障(下次会话调查)# 阶段 1 → 2
- 2026-06-09:tests/e2e/checkout 大约每 50 次运行中有 1 次不稳定。假设:webhook 竞态。
复现步骤见 debug/checkout-flake.md。
## 经验教训 # 阶段 4 的提炼
- PowerShell 在 Windows CI 运行器上会遇到 TLS 1.2 问题。始终调用 bash 来执行。
- Stripe webhook 测试需要 STRIPE_WEBHOOK_SECRET。如果缺失,以清晰的提示信息跳过。
## 上次会话 # 阶段 5 — 恢复,而非重启
2026-06-10 03:30 UTC · 7 个失败已分类,3 个修复已起草(claude/fix-*),4 个已上报。
下一步:针对生产负载验证 claude/fix-rate-limit-order 中的认证中间件修复。
```
这个文件有五个部分,对应五个阶段。已验证的事实是阶段 3 的输出——即代理不再瞎猜的内容。通用规则是阶段 4——从具体案例中提炼出的、适用于更广范围的规则。未解决的故障是阶段 1–2 的进行中工作。经验教训是更多的阶段 4 输出。
上次会话是阶段 5 的恢复指针。
两条决定这个文件是真正在复利积累还是仅仅在增长的操作规则:
- 离开前先写入。每个 Fable 5 会话都以更新 STATE.md 结束——尝试了什么、什么通过了、什么失败了、哪些新规则被保留下来。如果会话结束时没有写入,下一个会话就会从零开始。
- 会话开始时先读取。每个新会话都从读取 STATE.md 和最相关的 Skills 开始。持续学习基准(Continual Learning Bench)的数据表明,如果没有这一步,即使是 Fable 5 也会表现出 Sonnet 级别的记忆行为。
## 12. 会复利的 Skills。把经验教训写进 Skill,而不仅仅写在聊天里。
STATE.md 用于项目记忆。Skills 用于程序性记忆——即“如何做这类事情”,应该跨项目适用。
复利的模式是:任何一次不小的失败之后,把经验教训写进 Skill 本身。系统每运行一次,Skill 就会变得更锋利。

一个已经复利积累了两周的 Skill,与一个全新的 Skill 看起来不同。会出现新的章节:已知故障模式、从事后复盘(post-mortem)中得出的规则、在生产环境中观察到的反模式。
这个 Skill 不再是一套静态的指令,而是团队实际学到内容的累积记录。
```
---
name: ci-triage
description: 对 CI 失败进行分类,为简单的问题起草修复,其余上报。
在 workflow_run.failure 或早晨的分类例程时触发。
---
# CI 分诊技能
## 分类规则
- env: 缺失密钥、环境变量错误。# 上报给人类,绝不自动修复
- flake: 重试即通过,代码未变。# 重试一次,然后登记
- bug: 与近期提交相关的确定性失败。# 起草修复
- dependency: 与版本升级相关。# 起草回滚
- infra: 超时、OOM、运行器问题。# 上报
## 已知故障模式 # 由循环在 14 天内添加
- webhook-race: 当 Stripe webhook 在测试进行中到达时,e2e checkout 不稳定。
修复:在 tests/utils/webhook.ts 中添加 2 秒的稳定延迟。
- tls-handshake: Windows 运行器在 PowerShell 中 TLS 1.2 失败。使用 bash。
- db-migration: trades 表超过 100 万行时 ALTER 在 30 秒超时。以 1 万为单位分批处理。
## 反模式(不要做)# 在真实事故之后添加
- 绝不为了使 CI 变绿而禁用失败的测试。改为登记该问题。
- 绝不在没有人类批准的情况下修改 .github/workflows/。
- 绝在没有安全审查的情况下触碰 src/payments/ 或 src/billing/。
## 状态
每次运行后,将分类、起草的修复、上报事项更新到 STATE.md。
## 评估套件 # 步骤 13 — 循环验证该技能
每周针对 eval/ci-triage-cases.jsonl 运行。任何新失败的用例 →
在结果验证器(Outcomes verifier)确认后,添加到已知故障模式中。
```
复利契约:每一条被确认的经验教训都写进 Skill,而不仅仅是 STATE.md。STATE.md 是项目范围的,随项目消亡。Skills 存放在 ~/.claude/skills/ 中,会随你迁移。
两周的规范写作产出的 Skill,其表现会明显优于 Fable 5 在一个全新项目上从零推导出的任何东西。
## 13. 通过视觉进行自我验证。Fable 5 会对照目标检查自己的 UI。
Fable 5 随附的招牌能力之一是“使用视觉对照目标检查输出”。这听起来很抽象,直到你看到它实际取代了什么:由人眼查看截图来确认 UI 是否正确的这一步。
Fable 5 自己完成这一步,在循环内、在宣告完成之前。
生产中的模式:
- Maker 子代理编写 UI 代码。将结果渲染为截图。
- Verifier 子代理用视觉读取截图,将其与目标描述、项目 Skill 中的设计令牌(design tokens)以及 STATE.md 中的上一张截图进行比较。
- 结论返回给循环。匹配 → 将任务标记为完成。不匹配 → 描述差距,连同结构化的差异一起交回给 Maker。
这个模式正是 Anthropic 在同一测试框架下的 Parameter Golf 实验中所测量的:Fable 5 查看训练图表(视觉产物),并判断曲线是否符合标准。
没有人在循环中读图表。是验证器读了图表。
## 14. Mythos 安全边界。Fable 5 不会做什么,以及如何围绕它进行设计。
最后这一步是第一天最容易跳过、也是最需要付出惨痛代价才能学到的一步。
Fable 5 内置了安全分类器,在特定高风险领域会拒绝响应——包括网络安全漏洞研究、生物学、化学和模型蒸馏。在这些领域中,Anthropic 会自动将 Fable 5 回退到 Claude Opus 4.8。这是有文档记录的行为,不是 bug。
对于一个自主运行的自改进系统来说,这意味着:
- 如果你的系统涉及安全工具(SAST 扫描、漏洞利用研究、渗透测试逻辑,甚至某些类型的代码审查),就要预期会遇到分类器拦截。为回退做好架构设计:将这些任务显式路由到 Opus 4.8,或将拦截情况呈现给人工审查者。
- 生物学、化学和蒸馏领域同样如此。分类器的覆盖范围很广。一个科学计算工作流可能会触发它;对密码学原语的代码审查也可能触发它。
- 设计你的 Skills 时要让回退被优雅地呈现出来。一个 Skill 应该清楚它可能产生哪些类型的任务会命中分类器,并记录预期行为。一个因分类器拦截而静默失败的循环,与因真实错误而失败的循环看起来完全一样——直到你调试时才发现区别。
- 审查系统卡。Fable 5 长达 319 页的系统卡记录了分类器的适用范围。2026 年 6 月中旬,该模型的发布引发了争议,因为一些降级行为被发现埋藏在文档深处。在生产环境部署之前务必通读。
总体设计原则:将安全边界视为一种已知的回退机制,而不是一种失败模式。自带明确边界处理机制的自改进系统,会随着分类器的演进保持稳健。而忽视它的系统,会在 Anthropic 更新策略时产生静默的性能退化。
## § 让 Fable 5 只发挥 10% 潜力的错误做法
- 把 Fable 5 当作上下文更长的 Sonnet 4.6 来用。一次 5 分钟的“提问即关”会话,白白消耗 Mythos 级别的定价,却没有任何复利效应。
- 用自我批判代替独立验证器。出题人给自己批改作业。Anthropic 测量了这种差异,并在文档中明确记录了验证器子代理模式。
- 没有 STATE.md。每次会话都从零开始。Continual Learning Bench 的数据表明,Fable 5 的记忆优势有 70% 以上正是因此而流失。
- 从不更新的 Skills。静态的 Skill 没问题;但在真实失败后不积累经验教训的 Skill 就是浪费的脚手架。
- 把 Fable 5 用在 Sonnet 4.6 就能处理的任务上。文档更新、简单重构、lint 修复。按复杂度路由;把 Fable 5 留给编排者的角色。
- 在笔记本电脑上运行长会话。持续数天的能力需要云基础设施(CMA 或 Routines)。合上笔记本电脑就等于杀死会话。
- 忽视 Mythos 安全边界。网络/生物/化学领域的分类器拦截会产生静默退化。显式地为回退做架构设计。
- 视觉任务不做视觉验证。UI、仪表盘、设计还原度——用纯文本验证器检查这些会漏掉真正重要的失败模式。
- 跳过 /goal 或 Outcomes。没有由独立评分者检查的客观停止条件,循环会在“处理得差不多了”而不是“完成”时停止。
- 不审查数据保留策略。未经检查 30 天 / 2 年条款就让敏感数据流经 Fable 5 例程,会悄悄制造合规问题。
## 结语:
Fable 5 不是一个更快的聊天工具。它是一个能产生复利的系统的基底。
首个公开可用的 Mythos 级模型发布出来,不是为了让你更快地输入提示词,而是为了充当你在它之上构建的自改进系统的编排者。
能力头条——数天级会话、子代理委派、视觉自检、积累式记忆——只有当围绕模型的系统真正发挥作用时,才配得上它的定价。
Anthropic 团队自己的实验让这一差距清晰可见。Parameter Golf:配备独立验证器的 Fable 5 探索了更大规模的架构变更,并在经历负面的中间结果后坚持下来,最终获得了约 6 倍于 Opus 4.7 的改进幅度。
Continual Learning Bench:带记忆的 Fable 5 以 73% 的验证覆盖率完成了全部 5 个阶段的进阶,而 Opus 4.7 仅为 17%。每次对比中,两组的模型都是同一个。改变的是围绕它的系统。
从复利栈中挑选一个你还没做的一层——可能是验证器子代理(第 6 步)、状态文件(第 11 步)或视觉验证(第 13 步)——明天就加上它。然后再加下一层。
自我改进是系统的属性,而不是模型的属性。去构建那个系统。
## 相关链接
- [Codez](https://x.com/0xCodez)
- [@0xCodez](https://x.com/0xCodez)
- [4.2M](https://x.com/0xCodez/status/2065089060104720776/analytics)
- [movez.substack.com](https://movez.substack.com/)
- [May 29](https://x.com/_catwu/status/2060054180379689074)
- [1.6M](https://x.com/_catwu/status/2060054180379689074/analytics)
- [升级至 Premium](https://x.com/i/premium_sign_up)
- [2026年6月11日 23:09](https://x.com/0xCodez/status/2065089060104720776)
- [420万次浏览](https://x.com/0xCodez/status/2065089060104720776/analytics)
- [查看引用](https://x.com/0xCodez/status/2065089060104720776/quotes)
---
*导出时间: 2026/7/9 09:12:56*