# How to Build a Self-Improving Outbound System on Codex
**作者**: Nicolas Finet
**日期**: 2026-07-19T14:36:13.000Z
**来源**: [https://x.com/nifinet/status/2078851409068654639](https://x.com/nifinet/status/2078851409068654639)
---
Earlier this year, Andrej Karpathy (@karpathy) pointed an agent at his own training code and let it run for two days. It ran 700 experiments, kept the 20 that beat the benchmark, and made the model train 11% faster. Then he said something quite interesting: any metric you can evaluate cheaply can be handed to an agent swarm.
Reply rate is a metric you can evaluate cheaply. I have spent some time since working out what that loop looks like pointed at outbound.
My build:
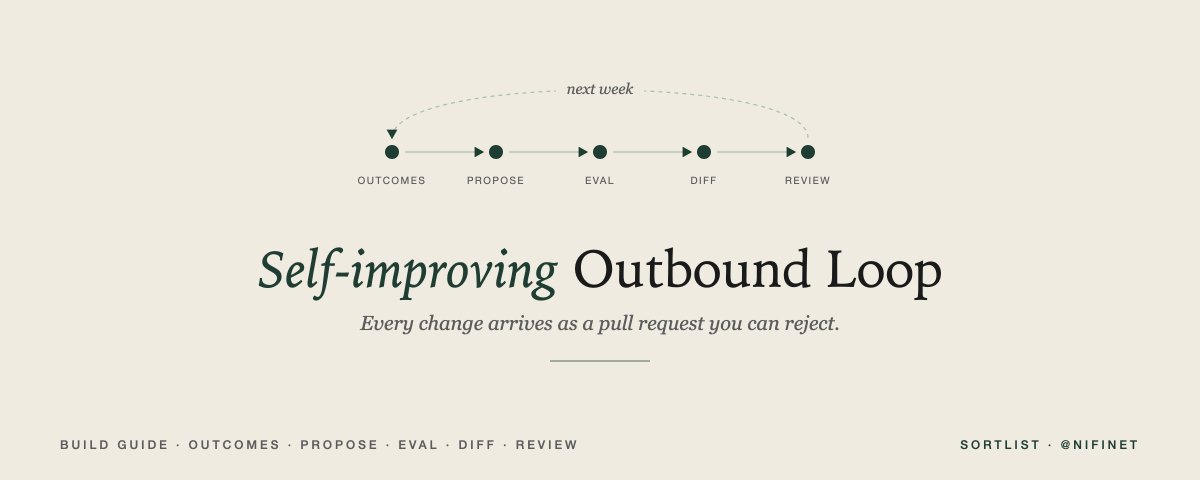
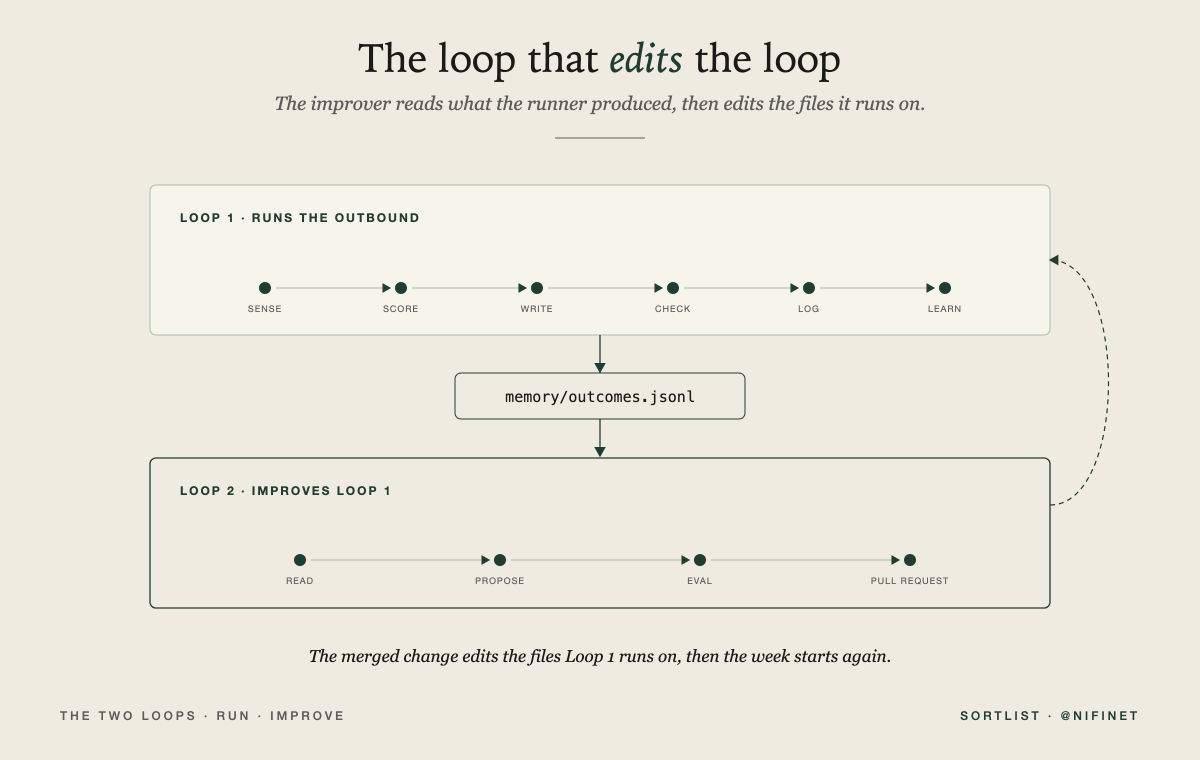
Codex reads last week's outcomes, edits the scoring and play files the outbound system runs on, runs a test, and opens a pull request. It proposes a change to the playbook with the evidence and the score attached, then waits for a human to approve it. Sending and merging stay outside the loop.
I have built the first loop a few times: sense the market, score the account, write from the signal, check the message, log the outcome, learn from the reply. This article is about the second loop, the one that edits the first.
That is the build: GTM as versioned code that improves from the market.
## The repo
Start with the folder. The shape matters because Codex can only improve what it can read and edit.
```
codex-self-improving-outbound/
AGENTS.md
README.md
config/
scoring.yaml
plays.yaml
prompts/
improve_scoring.md
improve_prompt.md
pr_summary.md
memory/
outcomes.jsonl
evals/
fixtures.yaml
score.py
scripts/
append_outcome.py
run_codex_step.sh
propose_improvement.py
open_pr.sh
weekly_tune.sh
examples/
outcomes.sample.jsonl
weekly-pr.md
```
The repo is intentionally plain. config/scoring.yaml holds the rules that decide which signals matter. prompts/ holds the plays that write the messages. memory/outcomes.jsonl holds what the market did. evals/score.py is the gate that says whether a proposed change helped. AGENTS.md is the law Codex reads before it touches anything.
Run the first version offline. No CRM, no enrichment, no delivery system. The improvement loop should prove itself on local files before it gets anywhere near a real outbound machine.
## Step 1. Write the law first
Before the scoring file, before the prompt files, write AGENTS.md. This is the file that keeps the agent useful and contained.
```
# Self-Improving Outbound Rules
You improve an outbound system from outcomes.
Hard rules:
- Never send messages.
- Never scrape or enrich real people.
- Never self-merge.
- Edit only files in this repo.
- Change one concept at a time.
- Cite outcomes from memory/outcomes.jsonl for every proposed change.
- Improve evals/score.py before a change can become a PR.
- If the eval does not improve, revert your edit and stop.
Allowed edits:
- config/scoring.yaml
- config/plays.yaml
- prompts/*.md
Required output:
- changed files
- reason for each change
- before score
- after score
- pull request summary
```
The law has one job: narrow the work. Without it, Codex will try to help by expanding scope. It will add more data, touch more files, call more tools, or automate a step that should stay under human control. Here the job is smaller: read outcomes, propose one file change, prove it helped, then wait.
What good looks like. You can read the law before approving a PR and know exactly what Codex was allowed to do.
Where it breaks. The law becomes a compliance document. If AGENTS.md needs a table of contents, it is already too large. Keep it operational.
## Step 2. Move judgment into config
Most outbound judgment lives in someone's head. Then the team buys software and expects the software to improve a decision it cannot see.
Move the judgment into a file.
```
signals:
competitor_comparison:
weight: 8
reason: "buyer is comparing alternatives"
implementation_page_visit:
weight: 6
reason: "buyer is checking whether this can be installed"
job_repost:
weight: 5
reason: "role is still open and urgent"
funding_event:
weight: 5
reason: "budget or mandate may have changed"
generic_download:
weight: 1
reason: "content interest, weak buying intent"
thresholds:
draft: 6
human_review: 10
negative_signals:
student_research: -8
vendor_pitch: -6
competitor: -10
```
This file starts as a visible hypothesis. If a generic download should count for zero, the team can point to the exact line and change it. If an implementation page visit is a stronger signal than you thought, Codex can propose the diff and show the outcome rows that justify it.
Do not bury this logic in a Python function. If the rule is visible, the team can review it, argue with it, and improve it without turning a sales judgment into an engineering refactor.
What good looks like. The file is small enough to argue with. Five signals is a good first version.
Where it breaks. The scoring file becomes a junk drawer. Twenty signals, six thresholds, and exception rules for every edge case will make the improver overfit. Start narrow and let the outcomes tell you where the next knob belongs.
## Step 3. Write outcomes as memory
The most important file is memory/outcomes.jsonl.
One line per touch, written when the outcome is known:
```
{"date":"2026-07-01","account":"Northwind Finance","signal":"competitor_comparison","play":"migration_note","score":8,"outcome":"reply","reason":"asked for migration notes"}
{"date":"2026-07-01","account":"Bluepeak Studio","signal":"generic_download","play":"resource_followup","score":1,"outcome":"no_reply","reason":"content-only intent"}
{"date":"2026-07-02","account":"KiteOps","signal":"implementation_page_visit","play":"implementation_angle","score":6,"outcome":"reply","reason":"asked about implementation timeline"}
{"date":"2026-07-02","account":"Atlas Recruiting","signal":"job_repost","play":"hiring_angle","score":5,"outcome":"bad_fit","reason":"student research request"}
```
The reason field is the whole point. no_reply tells you almost nothing. content-only intent tells the next run that this signal might not deserve a draft. bad_fit is useful only when the reason explains why. asked about implementation timeline is the kind of detail that can change a weight.
Build the validator before you build the improver:
```
Build scripts/append_outcome.py.
It accepts:
- date
- account
- signal
- play
- score
- outcome: reply | meeting | no_reply | bad_fit | bounced
- reason
It rejects:
- missing fields
- unknown outcomes
- empty reason
- dates in the future
Append valid rows to memory/outcomes.jsonl.
Print the appended row.
```
This is where the compounding starts. A dashboard can tell you a campaign is down. A clean outcome log can tell Codex which signal, play, or phrase should change before the next run.
What good looks like. After a week, a stranger can read the file and tell which signals created replies, which plays created bad-fit conversations, and which internal favorite the market ignored.
Where it breaks. The team backfills outcomes on Friday from memory. The wins survive, the bad-fit reasons blur, and the system learns from fiction. Write the row when the outcome lands.
## Step 4. Build the eval gate
Before Codex edits anything, it needs a test it cannot explain away.
Create evals/fixtures.yaml:
```
cases:
- account: Northwind Finance
signals: [competitor_comparison, implementation_page_visit]
expected: human_review
note: "two strong signals on one account"
- account: Bluepeak Studio
signals: [generic_download]
expected: ignore
note: "content-only intent"
- account: KiteOps
signals: [implementation_page_visit]
expected: draft
note: "implementation intent should clear draft threshold"
- account: Atlas Recruiting
signals: [job_repost, student_research]
expected: ignore
note: "bad-fit marker cancels the signal"
```
Then create evals/score.py:
```
Build evals/score.py.
Read config/scoring.yaml and evals/fixtures.yaml.
For each case:
1. Sum weights for every signal.
2. Add negative signal penalties.
3. Route the account:
- score >= thresholds.human_review => human_review
- score >= thresholds.draft => draft
- otherwise => ignore
4. Compare route to expected.
Print each prediction.
Print final accuracy as score=0.00 to score=1.00.
Exit 0 only when accuracy is 1.00.
```
The first gate should be small enough to understand and sharp enough to catch a real miss. In my first run, the baseline failed one case:
```
Northwind Finance: predicted=human_review expected=human_review
Bluepeak Studio: predicted=ignore expected=ignore
KiteOps: predicted=ignore expected=draft
Atlas Recruiting: predicted=ignore expected=ignore
score=0.75
```
That was good. The system had implementation intent below the draft threshold, so it ignored an account the fixture said deserved a message. Better to catch that in a test than after a month of missed accounts.
What good looks like. One command gives one number, and every failed case is easy to inspect.
Where it breaks. The fixture only includes obvious wins. Then every reckless change passes. Put ugly cases in the gate: weak intent, bad fit, no reply, stale signals, and the accounts you wish the system had skipped.
## Step 5. Let Codex propose one scoring change
Now Codex can edit.
Create prompts/improve_scoring.md:
```
You improve the outbound scoring system.
Read:
- AGENTS.md
- config/scoring.yaml
- memory/outcomes.jsonl
- evals/fixtures.yaml
Your job:
1. Find one scoring rule that should change.
2. The reason must cite memory/outcomes.jsonl.
3. Change only config/scoring.yaml.
4. Run python3 evals/score.py.
5. If the score improves, keep the change.
6. If the score stays flat or drops, revert your change and stop.
Output:
- the exact line changed
- the outcome rows that caused it
- before score
- after score
- whether the change should become a PR
Do not edit prompts.
Do not add new signals.
Do not touch delivery.
```
Run it through the repo wrapper:
```
scripts/run_codex_step.sh improve_scoring
```
The first version of my improver made a useful mistake. It chased the cleanest-looking reply signal. competitor_comparison had the strongest reply rate in the tiny outcome log, so the improver wanted to increase that weight. The eval stayed at 0.75, so the change was rejected.
That is exactly why the gate exists. A weaker system would have accepted the story because it sounded reasonable. This one asked a better question: did the change fix the known miss?
The second pass found the smallest edit that helped:
```
- implementation_page_visit: 4
+ implementation_page_visit: 6
```
The eval passed:
```
Northwind Finance: predicted=human_review expected=human_review
Bluepeak Studio: predicted=ignore expected=ignore
KiteOps: predicted=draft expected=draft
Atlas Recruiting: predicted=ignore expected=ignore
score=1.00
```
That is the moment the loop becomes useful. It changed one rule, for one reason, and proved the change against a fixture.
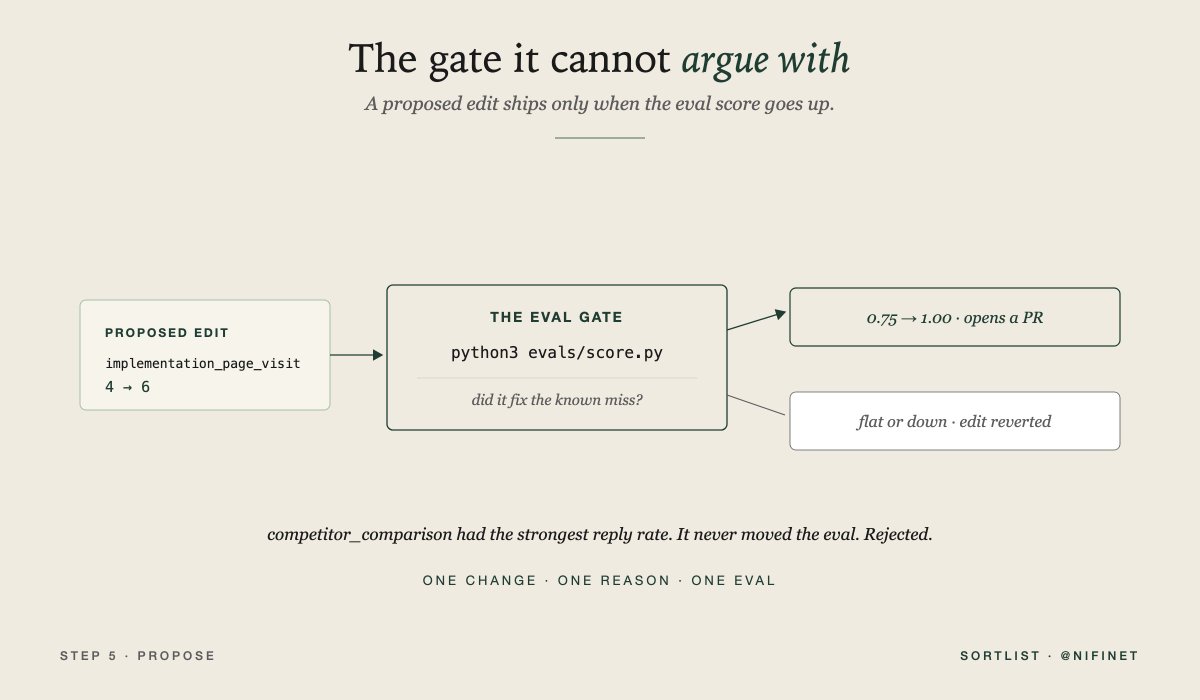
What good looks like. The proposed diff is boring and traceable: one line changed, one outcome-backed reason attached, one eval improved.
Where it breaks. Codex changes three weights and two prompts at once. Now nobody can tell which change helped. Keep the law strict: one concept per proposal.
## Step 6. Improve prompt files separately
Scoring is only half the system. The message templates decay too.
A line that worked last month starts sounding familiar. A question that earns replies in one segment gets ignored in another. A phrase that feels sharp internally gets punished by the market. Treat prompt improvement as a separate lane so Codex does not mix scoring and copy in the same PR.
Create config/plays.yaml:
```
plays:
migration_note:
prompt_file: prompts/plays/migration_note.md
use_when:
- competitor_comparison
banned_lines:
- "thought this might be relevant"
- "quick question"
implementation_angle:
prompt_file: prompts/plays/implementation_angle.md
use_when:
- implementation_page_visit
banned_lines:
- "checking out our solution"
- "would love to chat"
```
Then create prompts/improve_prompt.md:
```
You improve one outbound play.
Read:
- AGENTS.md
- config/plays.yaml
- memory/outcomes.jsonl
- the prompt file for the chosen play
Pick one play with at least 10 outcomes.
Find:
- lines or structures that appear in positive outcomes
- lines or structures that appear in no_reply or bad_fit outcomes
- any phrase that should be banned
Make one small edit to that play's prompt.
Rules:
- Do not change scoring.
- Do not create a new play.
- Do not add a new channel.
- Cite outcome rows.
- Write the before and after instruction.
Then run the copy eval if present.
If no copy eval exists, open the PR as review_required.
```
Some improvements can be scored automatically. Others still need taste. If there is no copy eval, Codex can propose the prompt edit, but it should mark the PR for review instead of pretending the edit is proven.
What good looks like. Codex says, "This phrase appeared in seven no-reply outcomes, so I added it to banned_lines," or "positive replies quoted the implementation detail in sentence one, so I tightened the play to require that."
Where it breaks. The improver rewrites the whole voice because one message got a reply. Prompt edits should be smaller than your instinct.
## Step 7. Ship changes as pull requests
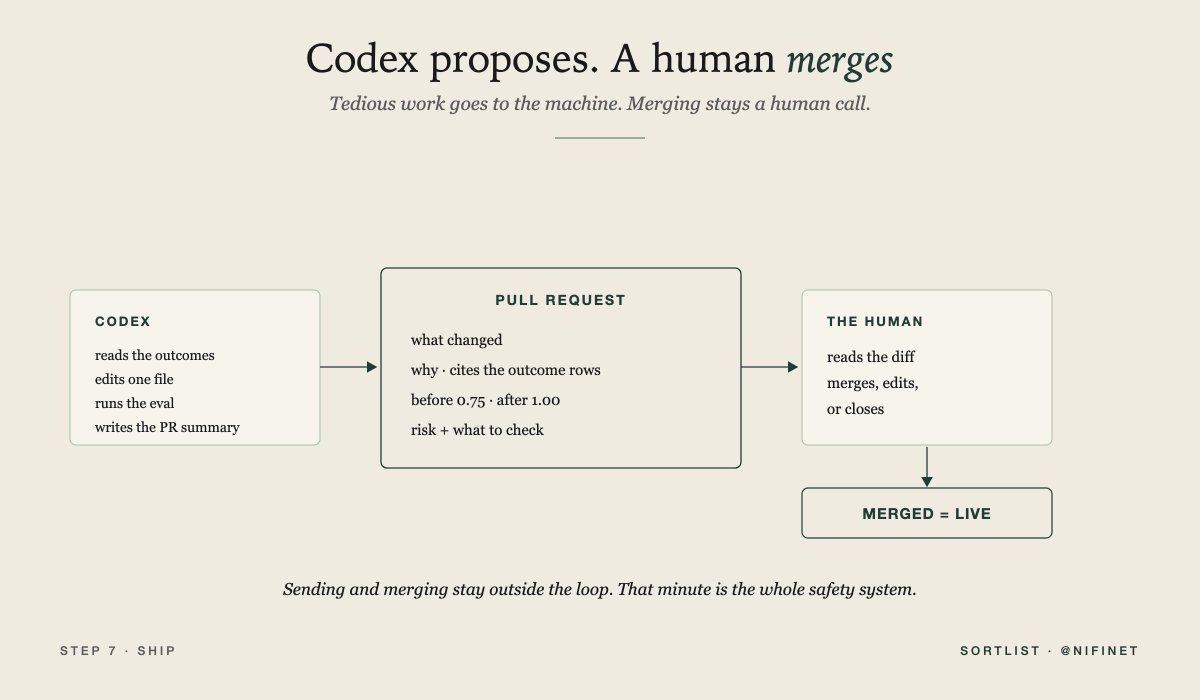
This is the control layer. Codex edits files, runs the eval, and writes the PR summary. A human reviews and merges.
Create prompts/pr_summary.md:
```
Write a pull request summary for this outbound improvement.
Include:
1. What changed.
2. Why it changed, citing outcome rows.
3. Before score.
4. After score.
5. Files changed.
6. Risk.
7. What the human reviewer should check.
Keep it short.
Do not claim the change is live.
```
Create `scripts/open_pr.sh`:
```
#!/usr/bin/env bash
set -euo pipefail
branch="codex/weekly-tune-$(date +%Y-%m-%d)"
git checkout -b "$branch"
git add config prompts evals memory
git commit -m "Codex weekly outbound tune"
body="$(cat outputs/pr-summary.md)"
python3 scripts/create_pr.py \
"$branch" \
"Codex weekly outbound tune" \
"$body"
```
The PR should read like a teammate wrote it:
```
Changed:
- Raised implementation_page_visit from 4 to 6.
Why:
- KiteOps had implementation-page intent and replied with implementation timing.
- The previous score routed this account to ignore.
Before:
- eval score 0.75
After:
- eval score 1.00
Reviewer check:
- Make sure implementation intent is specific enough.
- Keep generic downloads low.
- Merge only if this matches actual sales judgment.
```
That is the safety system. Codex does the tedious work. The operator keeps the standard.
What good looks like. One PR a week, small diff, clear reason, passing eval.
Where it breaks. Someone gives Codex permission to merge because review feels like friction. That minute separates a system that improves from a system that drifts.
## Step 8. Put it on a cadence
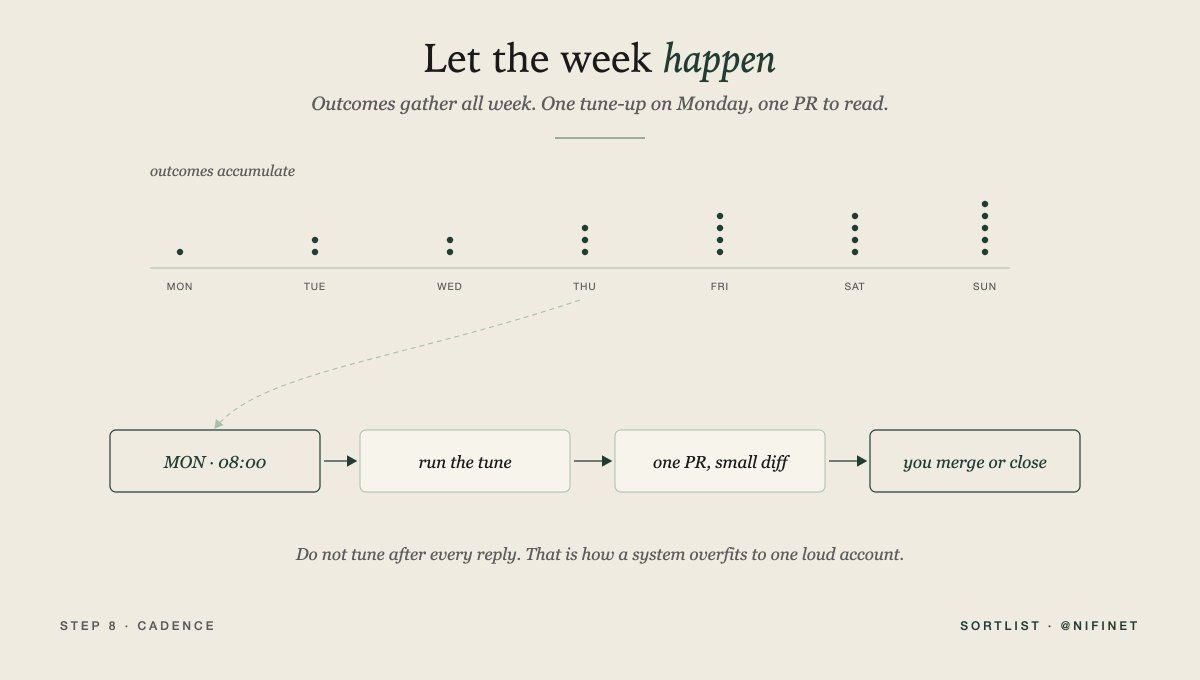
Do not run this after every reply. That is how a system overfits to one loud account.
Let the week happen, let outcomes accumulate, then tune.
Create scripts/weekly_tune.sh:
```
#!/usr/bin/env bash
set -euo pipefail
cd "$(dirname "$0")/.."
python3 evals/score.py || true
scripts/run_codex_step.sh improve_scoring
python3 evals/score.py
scripts/run_codex_step.sh pr_summary > outputs/pr-summary.md
scripts/open_pr.sh
```
Then cron:
```
0 8 * * MON cd ~/codex-self-improving-outbound && scripts/weekly_tune.sh
```
If you use GitHub Actions, keep the same shape:
```
name: weekly-outbound-tune
on:
schedule:
- cron: "0 8 * * 1"
workflow_dispatch:
jobs:
tune:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- uses: actions/setup-python@v5
with:
python-version: "3.11"
- run: pip install -r requirements.txt
- run: python3 evals/score.py || true
- run: scripts/weekly_tune.sh
```
Run the first two tune-ups by hand. Read every diff. Watch what Codex tries to change when the sample is thin. Once the proposals are boring, put it on a schedule.
What good looks like. A weekly PR appears with the evidence, the diff, and the eval result. You merge, edit, or close it.
Where it breaks. The job runs, nobody reviews, and PRs pile up. A self-improving system still has one human habit: read the diff.
## The clone-and-run version
The repo should ship with four commands:
```
git clone <repo>
cd codex-self-improving-outbound
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
python3 evals/score.py
python3 scripts/propose_improvement.py
```
Expected first run:
```
score=0.75
changed config/scoring.yaml
implementation_page_visit: 4 -> 6
score=1.00
open PR for human review
```
The offline demo proves the file contracts. The Codex run proves the editing loop. After that, replace the sample outcomes with your own, rename the signals, add your plays, and build a fixture that reflects the accounts you wish the system had routed differently.
Do not start by wiring delivery. Start by proving the improvement loop.
## The full version: max
This repo is the manual layer. It runs from files, public signals, and your Codex plan. It teaches the shape because every rule is exposed.
yourmax.ai is the same system with the seams hidden.
Instead of a repo you wire together yourself, max is the agent you use directly. It detects movement in the market, decides who is worth contacting and why now, drafts the outreach across email and LinkedIn for your approval, and keeps improving from the outcomes.
The repo shows the self-tuning layer most teams never build: outcomes become proposed rule changes, proposed rule changes run through a gate, and the human merge decides what becomes live. max takes that same operating logic and runs it as a managed system.
If you want the full repo, you can let me know and I will send it your way.
## 相关链接
- [Nicolas Finet](https://x.com/nifinet)
- [@nifinet](https://x.com/nifinet)
- [153K](https://x.com/nifinet/status/2078851409068654639/analytics)
- [@karpathy](https://x.com/@karpathy)
- [yourmax.ai](http://yourmax.ai/)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [10:36 PM · Jul 19, 2026](https://x.com/nifinet/status/2078851409068654639)
- [153.3K Views](https://x.com/nifinet/status/2078851409068654639/analytics)
- [View quotes](https://x.com/nifinet/status/2078851409068654639/quotes)
---
*导出时间: 2026/7/20 23:37:46*
---
## 中文翻译
# 如何在 Codex 上构建自我改进的外呼系统
**作者**: Nicolas Finet
**日期**: 2026-07-19T14:36:13.000Z
**来源**: [https://x.com/nifinet/status/2078851409068654639](https://x.com/nifinet/status/2078851409068654639)
---

今年早些时候,Andrej Karpathy(@karpathy)让一个智能体去处理他自己的训练代码,并让它运行了两天。它运行了 700 次实验,保留了击败基准的 20 次,让模型训练速度提高了 11%。然后他说了一句非常有意思的话:任何你能低成本评估的指标,都可以交给智能体集群来处理。
回复率就是一个可以低成本评估的指标。从那以后,我花了一些时间思考当这个循环被应用到外呼(outbound)时会是什么样子。
我的构建方式:
Codex 读取上周的结果,编辑外呼系统所依赖的评分和打法文件,运行一次测试,然后发起一个 pull request。它提出对 playbook 的一处修改,并附上证据和评分,然后等待人工批准。发送和合并保持在循环之外。
我已经搭建过几次第一个循环:感知市场、为账户评分、根据信号撰写内容、检查消息、记录结果、从回复中学习。这篇文章讲的是第二个循环,也就是编辑第一个循环的那个循环。
这就是构建方式:把 GTM 变成能从市场中改进的版本化代码。

## 代码仓库
从文件夹开始。结构很重要,因为 Codex 只能改进它能读取和编辑的内容。
```
codex-self-improving-outbound/
AGENTS.md
README.md
config/
scoring.yaml
plays.yaml
prompts/
improve_scoring.md
improve_prompt.md
pr_summary.md
memory/
outcomes.jsonl
evals/
fixtures.yaml
score.py
scripts/
append_outcome.py
run_codex_step.sh
propose_improvement.py
open_pr.sh
weekly_tune.sh
examples/
outcomes.sample.jsonl
weekly-pr.md
```
这个仓库刻意保持简单。config/scoring.yaml 存放决定哪些信号重要的规则。prompts/ 存放撰写消息的打法。memory/outcomes.jsonl 存放市场的反应。evals/score.py 是判断一项提议的修改是否有效的关卡。AGENTS.md 是 Codex 在动手之前必须阅读的法律。
先离线运行第一版。不用 CRM,不用数据增强,不用投递系统。改进循环应该先在本地文件上证明自己,之后才能接触真正的外呼机器。
## 第 1 步:先写法律
在评分文件之前,在 prompt 文件之前,先写 AGENTS.md。这是让智能体保持有用且受到约束的文件。
```
# 自我改进外呼规则
你根据结果来改进一个外呼系统。
硬性规则:
- 永远不要发送消息。
- 永远不要抓取或增强真实的人的数据。
- 永远不要自行合并。
- 只编辑本仓库中的文件。
- 每次只改一个概念。
- 每一项提议的修改都必须引用 memory/outcomes.jsonl 中的结果。
- 在一项修改能成为 PR 之前,先改进 evals/score.py。
- 如果评估没有改善,回滚你的修改并停止。
允许编辑的文件:
- config/scoring.yaml
- config/plays.yaml
- prompts/*.md
必需的输出:
- 修改的文件
- 每处修改的原因
- 修改前评分
- 修改后评分
- pull request 摘要
```
这份法律只有一个职责:收窄工作范围。没有它,Codex 会通过扩大范围来试图提供帮助。它会添加更多数据、修改更多文件、调用更多工具,或者把本应处于人类控制之下的步骤自动化。这里的工作更小:读取结果,提议一处文件修改,证明它有效,然后等待。
好的标志:你可以在批准 PR 之前阅读这份法律,并确切知道 Codex 被允许做什么。
失效的标志:法律变成了合规文档。如果 AGENTS.md 需要目录,那它已经太大了。保持它的可操作性。
## 第 2 步:把判断力移入配置
大多数外呼判断都存在于某人的脑子里。然后团队购买软件,并期望软件改进一个它看不见的决策。
把判断力移入一个文件。
```
signals:
competitor_comparison:
weight: 8
reason: "buyer is comparing alternatives"
implementation_page_visit:
weight: 6
reason: "buyer is checking whether this can be installed"
job_repost:
weight: 5
reason: "role is still open and urgent"
funding_event:
weight: 5
reason: "budget or mandate may have changed"
generic_download:
weight: 1
reason: "content interest, weak buying intent"
thresholds:
draft: 6
human_review: 10
negative_signals:
student_research: -8
vendor_pitch: -6
competitor: -10
```
这个文件最初是一个可见的假设。如果一次普通下载的得分应该是零,团队可以指向确切的那一行并修改它。如果一次实施页面访问是比你以为的更强的信号,Codex 可以提出 diff,并展示支持它的结果数据行。
不要把这种逻辑埋在 Python 函数里。如果规则是可见的,团队就可以审查它、质疑它并改进它,而不必把销售判断变成一次工程重构。
好的标志:文件足够小,可以拿来争论。五个信号是很好的第一版。
失效的标志:评分文件变成一个杂物抽屉。二十个信号、六个阈值以及针对每个边缘情况的例外规则会让改进器过拟合。从狭窄的范围开始,让结果告诉你下一个调节旋钮应该放在哪里。
## 第 3 步:把结果写为记忆
最重要的文件是 memory/outcomes.jsonl。
每次触达一行,在得知结果时写入:
{"date":"2026-07-01","account":"Northwind Finance","signal":"competitor_comparison","play":"migration_note","score":8,"outcome":"reply","reason":"asked for migration notes"}
{"date":"2026-07-01","account":"Bluepeak Studio","signal":"generic_download","play":"resource_followup","score":1,"outcome":"no_reply","reason":"content-only intent"}
{"date":"2026-07-02","account":"KiteOps","signal":"implementation_page_visit","play":"implementation_angle","score":6,"outcome":"reply","reason":"asked about implementation timeline"}
{"date":"2026-07-02","account":"Atlas Recruiting","signal":"job_repost","play":"hiring_angle","score":5,"outcome":"bad_fit","reason":"student research request"}
```
reason 字段才是关键所在。no_reply 几乎提供不了任何信息。content-only intent 会告诉下一轮运行:这个信号可能不值得起草邮件。bad_fit 只有在 reason 解释了原因时才有用。asked about implementation timeline 这类细节,是能够改变某个权重的东西。
在构建改进器之前,先构建校验器:
```
Build scripts/append_outcome.py.
It accepts:
- date
- account
- signal
- play
- score
- outcome: reply | meeting | no_reply | bad_fit | bounced
- reason
It rejects:
- missing fields
- unknown outcomes
- empty reason
- dates in the future
Append valid rows to memory/outcomes.jsonl.
Print the appended row.
```
复利效应就是从这里开始的。仪表盘可以告诉你某次活动表现下滑了。而一份干净的结果日志,可以让 Codex 在下一轮运行之前就知道该调整哪个信号、打法或措辞。
理想状态。一周之后,一个陌生人也能读懂这个文件,并分辨出哪些信号带来了回复、哪些打法导致了 bad-fit 对话,以及哪些内部偏爱的做法被市场无视了。
失效场景。团队在周五凭记忆补录结果。成功案例被保留下来,bad-fit 的原因变得模糊,系统从虚构中学习。结果一产生,就立刻写入这条记录。
## 第 4 步. 构建 eval 门禁
在 Codex 修改任何东西之前,它需要一个无法被它搪塞过去的测试。
创建 evals/fixtures.yaml:
```
cases:
- account: Northwind Finance
signals: [competitor_comparison, implementation_page_visit]
expected: human_review
note: "two strong signals on one account"
- account: Bluepeak Studio
signals: [generic_download]
expected: ignore
note: "content-only intent"
- account: KiteOps
signals: [implementation_page_visit]
expected: draft
note: "implementation intent should clear draft threshold"
- account: Atlas Recruiting
signals: [job_repost, student_research]
expected: ignore
note: "bad-fit marker cancels the signal"
```
然后创建 evals/score.py:
```
Build evals/score.py.
Read config/scoring.yaml and evals/fixtures.yaml.
For each case:
1. Sum weights for every signal.
2. Add negative signal penalties.
3. Route the account:
- score >= thresholds.human_review => human_review
- score >= thresholds.draft => draft
- otherwise => ignore
4. Compare route to expected.
Print each prediction.
Print final accuracy as score=0.00 to score=1.00.
Exit 0 only when accuracy is 1.00.
```
第一版门禁应该足够小以便于理解,同时又足够敏锐,能抓住真正的失误。在我第一次运行时,基线失败了一个用例:
```
Northwind Finance: predicted=human_review expected=human_review
Bluepeak Studio: predicted=ignore expected=ignore
KiteOps: predicted=ignore expected=draft
Atlas Recruiting: predicted=ignore expected=ignore
score=0.75
```
这是好事。系统将实施意向的分数置于起草阈值之下,因此它忽略了一个测试夹具认为值得发送消息的账户。在测试中抓住这一点,总比错过账户一个月之后才发现要好。
理想状态。一条命令输出一个数字,且每个失败的用例都易于检查。
失效场景。测试夹具只包含显而易见的成功案例。这样任何鲁莽的改动都能通过。把丑陋的用例放进门禁里:弱意向、bad fit、无回复、过时信号,以及那些你希望系统当初就应该跳过的账户。
## 第 5 步. 让 Codex 提出一个评分调整
现在 Codex 可以进行修改了。
创建 prompts/improve_scoring.md:
```
You improve the outbound scoring system.
Read:
- AGENTS.md
- config/scoring.yaml
- memory/outcomes.jsonl
- evals/fixtures.yaml
Your job:
1. Find one scoring rule that should change.
2. The reason must cite memory/outcomes.jsonl.
3. Change only config/scoring.yaml.
4. Run python3 evals/score.py.
5. If the score improves, keep the change.
6. If the score stays flat or drops, revert your change and stop.
Output:
- the exact line changed
- the outcome rows that caused it
- before score
- after score
- whether the change should become a PR
Do not edit prompts.
Do not add new signals.
Do not touch delivery.
```
通过仓库封装脚本运行它:
```
scripts/run_codex_step.sh improve_scoring
```
我的改进器的第一个版本犯了一个有意义的错误。它追逐了看起来最干净利落的回复信号。在这个小小的结果日志中,competitor_comparison 拥有最高的回复率,所以改进器想调高那个权重。但 eval 停留在 0.75,因此该改动被拒绝了。
这正是门禁存在的意义。一个较弱的系统会因为这个故事听起来合理而接受它。而这个系统问出了一个更好的问题:这个改动修复了已知的失误吗?
第二轮找到了那个有效且最小的改动:
```
- implementation_page_visit: 4
+ implementation_page_visit: 6
```
eval 通过了:
```
Northwind Finance: predicted=human_review expected=human_review
Bluepeak Studio: predicted=ignore expected=ignore
KiteOps: predicted=draft expected=draft
Atlas Recruiting: predicted=ignore expected=ignore
score=1.00
```
这就是整个循环开始发挥作用的时刻。它基于一个理由修改了一条规则,并用一个测试夹具证明了这次改动。

理想状态。提议的 diff 是枯燥且可追溯的:改动一行代码,附带一个有结果支撑的理由,一个 eval 得到改善。
它在哪里会失效。Codex 同时修改了三个权重和两个提示词。现在没有人能说清哪个改动起了作用。保持规则严格:每个提案只改一个概念。
## 第 6 步:分别改进提示词文件
评分只是系统的一半。消息模板也会退化。
上个月有效的一句开场白开始听起来耳熟。在某个细分人群中能获得回复的问题,在另一个群体里却被无视。团队内部觉得犀利的措辞,到了市场上却遭到反感。把提示词改进作为一条独立的通道来处理,这样 Codex 就不会在同一个 PR 里把评分和文案混在一起。
创建 config/plays.yaml:
```
plays:
migration_note:
prompt_file: prompts/plays/migration_note.md
use_when:
- competitor_comparison
banned_lines:
- "thought this might be relevant"
- "quick question"
implementation_angle:
prompt_file: prompts/plays/implementation_angle.md
use_when:
- implementation_page_visit
banned_lines:
- "checking out our solution"
- "would love to chat"
```
然后创建 prompts/improve_prompt.md:
```
You improve one outbound play.
Read:
- AGENTS.md
- config/plays.yaml
- memory/outcomes.jsonl
- the prompt file for the chosen play
Pick one play with at least 10 outcomes.
Find:
- lines or structures that appear in positive outcomes
- lines or structures that appear in no_reply or bad_fit outcomes
- any phrase that should be banned
Make one small edit to that play's prompt.
Rules:
- Do not change scoring.
- Do not create a new play.
- Do not add a new channel.
- Cite outcome rows.
- Write the before and after instruction.
Then run the copy eval if present.
If no copy eval exists, open the PR as review_required.
```
有些改进可以自动评分,有些仍需要人的品味。如果没有文案评估,Codex 可以提出提示词修改建议,但它应该将 PR 标记为需要审核,而不是假装这个修改已被证明有效。
理想状态的示例。Codex 会说:"这个短语出现在七条 no-reply 结果中,所以我把它加进了 banned_lines",或者"正面回复引用了第一句中的实现细节,所以我收紧了这个 play,要求必须包含它。"
它在哪里会失效。改进者仅仅因为一条消息得到了回复,就重写整个语气风格。提示词的修改应该比你直觉上想做的更小。
## 第 7 步:以 Pull Request 的形式发布变更
这是控制层。Codex 编辑文件、运行评估、撰写 PR 摘要。由人来审核并合并。

创建 prompts/pr_summary.md:
```
Write a pull request summary for this outbound improvement.
Include:
1. What changed.
2. Why it changed, citing outcome rows.
3. Before score.
4. After score.
5. Files changed.
6. Risk.
7. What the human reviewer should check.
Keep it short.
Do not claim the change is live.
```
创建 `scripts/open_pr.sh`:
```
#!/usr/bin/env bash
set -euo pipefail
branch="codex/weekly-tune-$(date +%Y-%m-%d)"
git checkout -b "$branch"
git add config prompts evals memory
git commit -m "Codex weekly outbound tune"
body="$(cat outputs/pr-summary.md)"
python3 scripts/create_pr.py \
"$branch" \
"Codex weekly outbound tune" \
"$body"
```
PR 应该读起来像一个同事写的:
```
Changed:
- Raised implementation_page_visit from 4 to 6.
Why:
- KiteOps had implementation-page intent and replied with implementation timing.
- The previous score routed this account to ignore.
Before:
- eval score 0.75
After:
- eval score 1.00
Reviewer check:
- Make sure implementation intent is specific enough.
- Keep generic downloads low.
- Merge only if this matches actual sales judgment.
```
这就是安全系统。Codex 做繁琐的工作,运营者守住标准。
理想状态的示例。每周一个 PR,改动很小,理由清晰,评估通过。
它在哪里会失效。有人因为觉得审核麻烦,就给了 Codex 合并权限。正是这一分钟的审核,区分了一个不断改进的系统和一个逐渐漂移的系统。
## 第 8 步:把它放到固定节奏上
不要在每次收到回复后都运行这个系统。那样会让系统对某一个"声音很大"的客户过拟合。
让一周自然过去,让结果积累起来,然后再调整。

创建 scripts/weekly_tune.sh:
```
#!/usr/bin/env bash
set -euo pipefail
cd "$(dirname "$0")/.."
python3 evals/score.py || true
scripts/run_codex_step.sh improve_scoring
python3 evals/score.py
scripts/run_codex_step.sh pr_summary > outputs/pr-summary.md
scripts/open_pr.sh
```
然后设置 cron:
```
0 8 * * MON cd ~/codex-self-improving-outbound && scripts/weekly_tune.sh
```
如果你使用 GitHub Actions,保持同样的结构:
```
name: weekly-outbound-tune
on:
schedule:
- cron: "0 8 * * 1"
workflow_dispatch:
jobs:
tune:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- uses: actions/setup-python@v5
with:
python-version: "3.11"
- run: pip install -r requirements.txt
- run: python3 evals/score.py || true
- run: scripts/weekly_tune.sh
```
前两次调优请手动运行。阅读每一个 diff。观察当样本稀薄时 Codex 试图改什么。一旦提案变得"无聊"( predictable),就把它放上定期任务。
理想状态的示例。每周出现一个 PR,附上证据、diff 和评估结果。你来合并、修改或关闭它。
它在哪里会失效。任务照常运行,却没人审核,PR 堆积如山。一个自我改进的系统仍然依赖一个人类习惯:阅读 diff。
## 克隆即用版本
这个代码库应该附带四条命令即可跑通:
```
git clone <repo>
cd codex-self-improving-outbound
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
python3 evals/score.py
python3 scripts/propose_improvement.py
```
预期首次运行结果:
```
score=0.75
changed config/scoring.yaml
implementation_page_visit: 4 -> 6
score=1.00
open PR for human review
```
离线演示证明了文件契约的有效性。Codex 运行证明了编辑循环。之后,用你自己的结果替换示例结果,重命名信号,添加你的打法,并构建一个能反映你希望系统以不同方式处理的账户的测试夹具。
不要从搭建交付管道开始。要从验证改进循环开始。
## 完整版本:max
这个仓库是手动层。它基于文件、公开信号和你的 Codex 计划运行。它教会你系统的形态,因为每条规则都是公开可见的。
yourmax.ai 是同一套系统,只是隐藏了接缝。
max 不是需要你自己组装的仓库,而是你可以直接使用的智能体。它检测市场动向,判断谁值得联系以及为什么是现在,起草跨邮件和 LinkedIn 的外联内容供你审批,并根据结果持续改进。
这个仓库展示了大多数团队从未构建过的自我调优层:结果转化为规则修改提案,规则修改提案经过一道关卡审核,由人工合并决定哪些上线。max 采用同样的运营逻辑,并将其作为一个托管系统来运行。
如果你想要完整仓库,可以告诉我,我会发送给你。
## 相关链接
- [Nicolas Finet](https://x.com/nifinet)
- [@nifinet](https://x.com/nifinet)
- [153K](https://x.com/nifinet/status/2078851409068654639/analytics)
- [@karpathy](https://x.com/@karpathy)
- [yourmax.ai](http://yourmax.ai/)
- [升级到 Premium](https://x.com/i/premium_sign_up)
- [10:36 PM · 2026年7月19日](https://x.com/nifinet/status/2078851409068654639)
- [15.33万次浏览](https://x.com/nifinet/status/2078851409068654639/analytics)
- [查看引用](https://x.com/nifinet/status/2078851409068654639/quotes)
---
*导出时间: 2026/7/20 23:37:46*