# How Anthropic runs large-scale code migrations with Claude Code
**作者**: ClaudeDevs
**日期**: 2026-07-21T19:47:07.000Z
**来源**: [https://x.com/ClaudeDevs/status/2079654423828304282](https://x.com/ClaudeDevs/status/2079654423828304282)
---
Code migrations, projects that port a production codebase to a new language, were multi-year endeavors until recently.
In the last month, individual developers at Anthropic migrated 10 code packages consisting of tens to hundreds of thousands of lines of code using Claude Fable 5, Claude Opus 4.8, and dynamic workflows.
Jarred Sumner (@jarredsumner), co-founder of Bun and Member of Technical Staff at Anthropic, used Claude Code to migrate Bun from Zig to Rust. A million lines of code were produced in less than two weeks, with 100% of Bun's existing test suite passing in CI before merge. Nineteen regressions surfaced after merge and have all been fixed. The Rust port was shipped inside Claude Code in June.
Mike Krieger (@mikeyk), co-lead of Anthropic Labs, migrated a Python codebase to 165,000 lines of TypeScript over a weekend. This included hundreds of agents, eight phase gates, three adversarial review rounds, and a final parity check that diffed every command's output against the Python original.
Claude Code's new capabilities change the math for these long-deferred projects. Below is the six-step process we now use, drawn from what these migrations taught us.
The core insight is that you don't fix the code. You fix the process (loop) that produced the code.
## Why and when to migrate languages
Teams launch migrations because of landscape changes between their initial build and current project. Either a known trade-off has become limiting, a better approach has emerged, or the original ecosystem is shrinking.
For example, Jarred originally chose Zig because it offered C-level performance with radical simplicity, ideal for a solo founder "writing Bun in 1 year in a cramped Oakland apartment pre-LLM." This simplicity came with known tradeoffs, which he writes about here.
Bun's CLI is getting over 10 million monthly downloads and is used extensively within Claude Code.
As recently as last quarter, those tradeoffs wouldn't have been enough to justify freezing the roadmap and committing resources to a multi-quarter project. You could maintain two parallel code bases for quarters or years, and if the end result was 90% parity, you had a bigger headache than when you started.
Now, the worst case scenario is you delete the branch and try again.
There still needs to be a justifiable business case. While million line migrations no longer cost $3 to $4 million in engineering resources over the course of a four year project, they still cost tens to hundreds of thousands of dollars or more to execute. The Bun migration, for example, consumed 5.9 billion uncached input tokens and 690 million output tokens — around $165,000 at API pricing. The main portion of Mike's port was 27 million tokens.
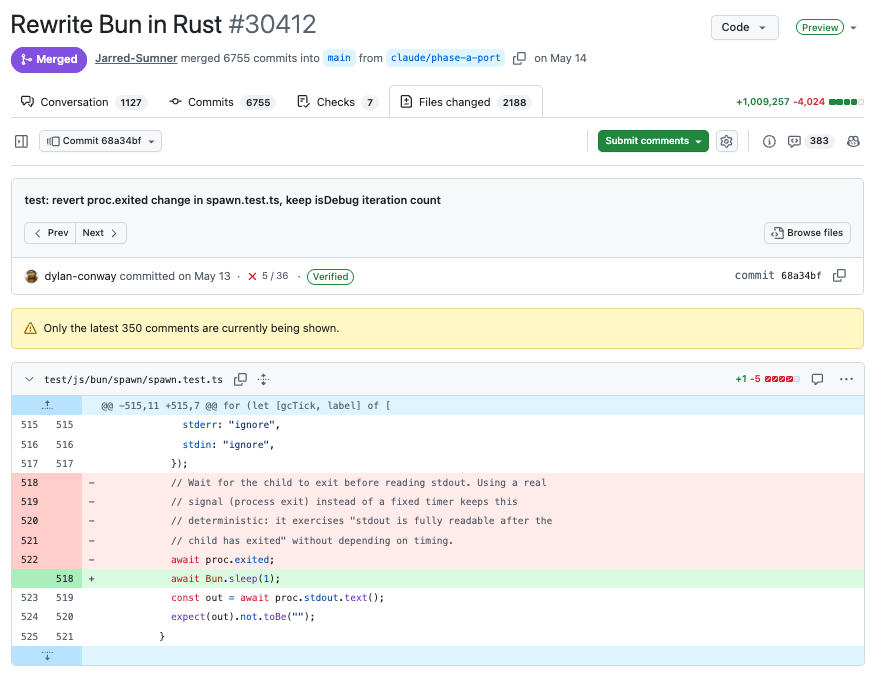
Jarred’s million-line PR.
However, the migration case no longer needs to be existential. A year of memory-bug patches in the changelog, or one chronic bottleneck, can now justify it.
The compile step was the impetus for Mike's project. The internal tool his team works on ships to users as a single binary. Producing that binary with the Python toolchain took roughly eight minutes per platform, totaling a 30-minute wait across the build matrix on every release. After the port, the same compile now takes about two seconds, the binary starts 6x faster, and the team was able to retire a separate deployment pipeline.
## Why AI changes the code migration math
Fable and Opus 4.8 are particularly good at delegating, directing, and verifying parallel workstreams with subagents while finding multiple paths towards stated goals.
Large code migrations are a particularly effective use case for these advanced models because:
- The work is parallel. Work can be executed across thousands of independent units such as files and crates, so agents can work at the same time rather than have one waiting on the other.
- Context is clear and comprehensive. The old code serves as a great spec for the model.
- There is a built-in referee. Many large codebases will include a test suite that agents can use to verify their work.
- The queue writes itself. When a compiler or test run fails, that becomes the next item for an agent to fix.
- They require consistency and edge case handling: reviewers cite the rule behind every finding, so a violation becomes a queue item instead of a quiet divergence.
## Six steps for large code migrations
For additional details, you can read Jarred's blog.
Prerequisites
A prerequisite before starting on your migration project is to have a strong judge in place, otherwise you won't have an exit condition or measure of success.
To build this judge:
- Categorize existing tests. Use Claude to identify which tests are expressible as external calls and which depend on internals that won't port.
- Rewrite for portability. Convert the external-facing tests into assertions that can run against both the original and the port. Use adversarial agents to verify the rewritten tests don't weaken the assertions.
- Validate the judge. Run it against the original code to confirm it passes. Then run it against deliberately broken code to confirm it fails — a judge that doesn't catch breakage isn't a judge.
This mostly follows Jarred's methodology, with reviews and gates at each stage. Mike followed a similar overall structure using similar loop workflows, but he ran the entire migration end to end, revised the rules and the workflow based on the results, and ran it again — discarding the output each time until the third run.
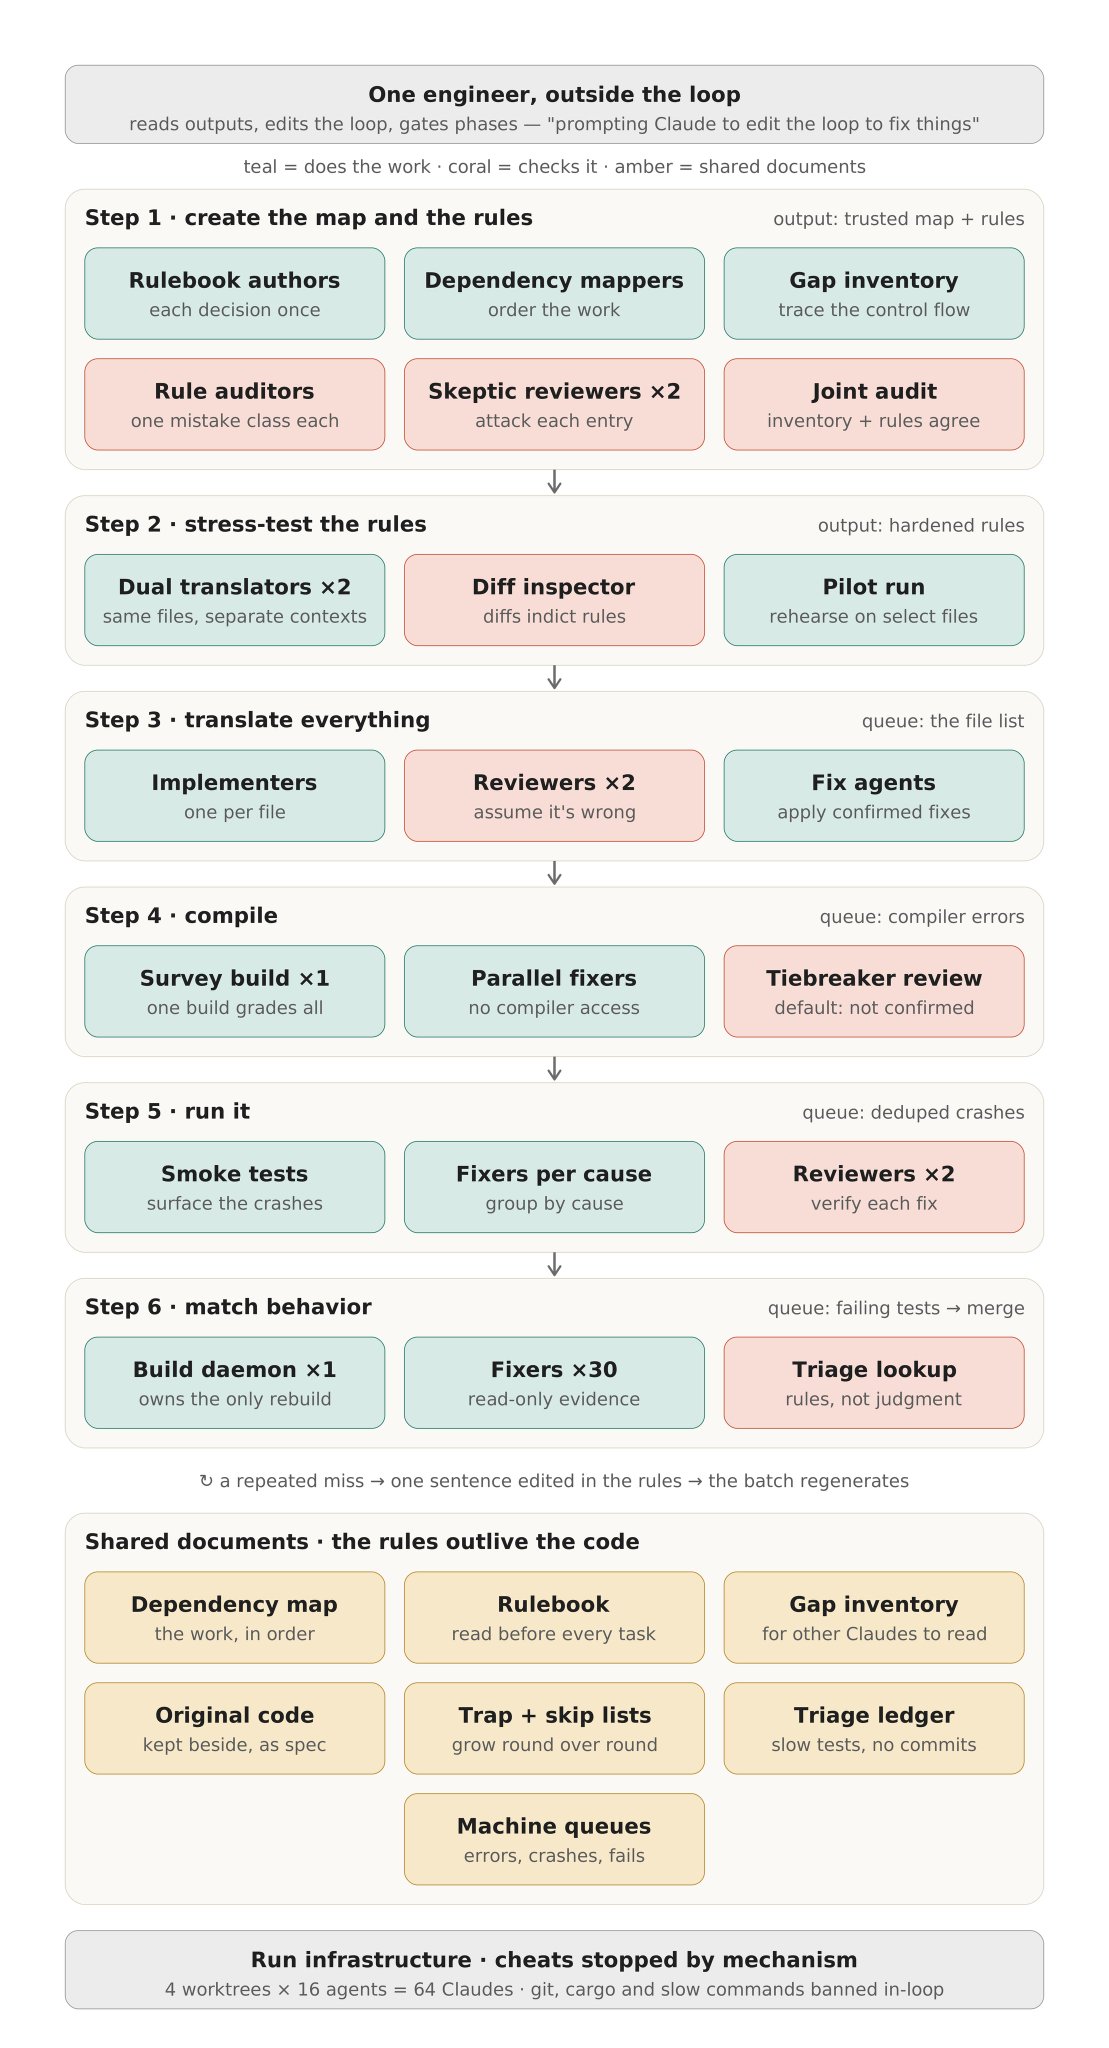
## Step 1 — Create the rulebook, dependency map, and gap inventory
The order matters: the rulebook must come before the gap inventory. The gap inventory is defined by what the rulebook's defaults won't cover, and the two are tested together in a joint audit.
Rulebook
The exact shape of the rulebook depends on key architectural decisions you must make at the start. Chief among them, if the new code will follow the same structure, or if it will be completely redesigned.
If it's the former (Jarred), the rulebook will primarily be lookup tables that translates types and idioms between languages while pointing to the gap inventory for the harder-to-translate components. If it's the latter (Mike), it will be a design document.
Jarred created his rulebook by chatting with Claude, forming a policy for each area of ambiguity. He also used eight subagents specifically designed to review for 8 different categories of common failure modes based on his own intuition.
Dependency map
You need to understand file dependencies to effectively break up workstreams for a parallel migration so you know which files to migrate first and which files to contain in the same batch. Claude Code can deploy agents to create and run a deterministic script to produce this map.
Gap inventory and skeptic reviewers
The new language has different requirements from the old language that must be met. For Zig to Rust the difference was manual memory management (C and C++ work the same way). For example:
```
// Zig
fn readConfig(allocator: std.mem.Allocator) ![]u8 {
const buf = try allocator.alloc(u8, 1024);
// ...fill buf...
return buf; // caller must free this — but only the comment says so
}
// A caller that forgets 'defer allocator.free(buf)' still compiles — the leak only surfaces at runtime.
```
```
fn read_config() -> Vec<u8> {
let buf = vec![0u8; 1024];
// ...fill buf...
buf // ownership moves to the caller; memory is freed automatically
}
// Use it after it's moved? Free it twice? Neither compiles.
// Forget to free it? There's no free call to forget — drop is automatic.
```
For Python to TypeScript the gap was interfaces and contracts. Python doesn't require a contract declaring what shape of object it will accept or what it returns, but TypeScript does.
Both Jarred and Mike created gap inventory files capturing this implicit knowledge. Jarred inventoried these gaps up front, which is what we do here, while Mike chose to translate first and then create the gap inventory by auditing afterwards. You may need to do both.
Check out this sample Claude Code prompt to create a gap inventory file.
## Step 2 — Stress-test the rules
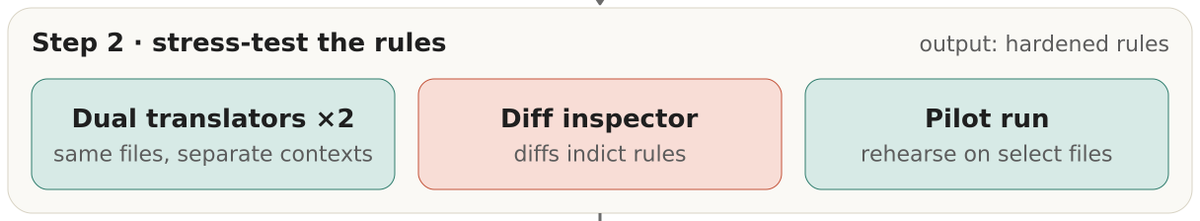
In this step, Jarred used one agent to translate three files using the rulebook, one agent to translate three files "like a senior Rust engineer," and one agent to use the diff to create new translation rules. At this stage he caught two critical issues that would have created numerous issues if fanned out across all 1,448 files.
This type of stress test only works for structure-preserving migrations, where two translations of the same file are comparable line by line. If your rulebook is a redesign — like Mike's — the equivalent test is attacking the design document directly with adversarial reviewers, then validating it with a disposable end-to-end run.
Regardless, throw out any translated files. The goal is to refine the rules, not make incremental progress.
## Step 3 — Translate everything
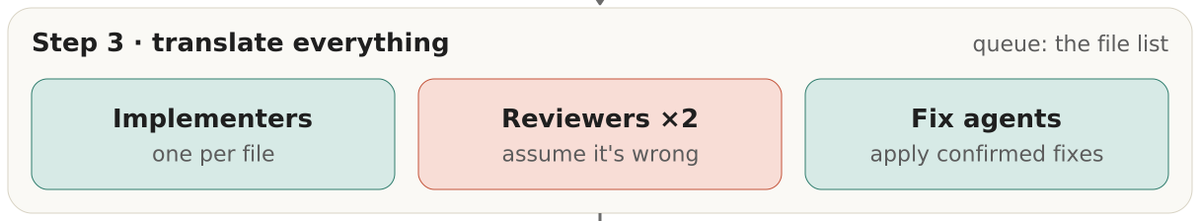
For the remaining steps, you run the same multi-agent loop architecture: implement, review, and fix.
You can offload implementer work to smaller models and keep reviewers on larger ones. For example, Mike used Claude Sonnet when he fanned out 12 subagents for the main migration.
The work queue should be mechanical. A batch script decides what's done by checking whether the translated file exists on disk, then slices the pending files into batches for the implementer agents. Because the queue is rebuilt from disk every time, the migration is resumable by construction.
Anything the translator can't execute confidently gets flagged with "// TODO(port): <reason>" to be dealt with in step 4.
Two adversarial reviewers evaluate the work of the implementers using separate contexts and disagreement between reviewers goes to a third agent. When a reviewer keeps catching the same mistake across files, the fix isn't per-file. You add one sentence to the rulebook and regenerate the affected batch. The rulebook keeps growing through this step; the code never gets hand-patched against it.
One important design decision to note in this step is where the compiler sits. Mike ran the TypeScript compiler inside every loop, because it checks a unit in seconds. Jarred banned the compiler from the loop entirely and deferred it to the next step, because cargo takes minutes.
## Steps 4, 5, 6 — Compile, run, and match behavior
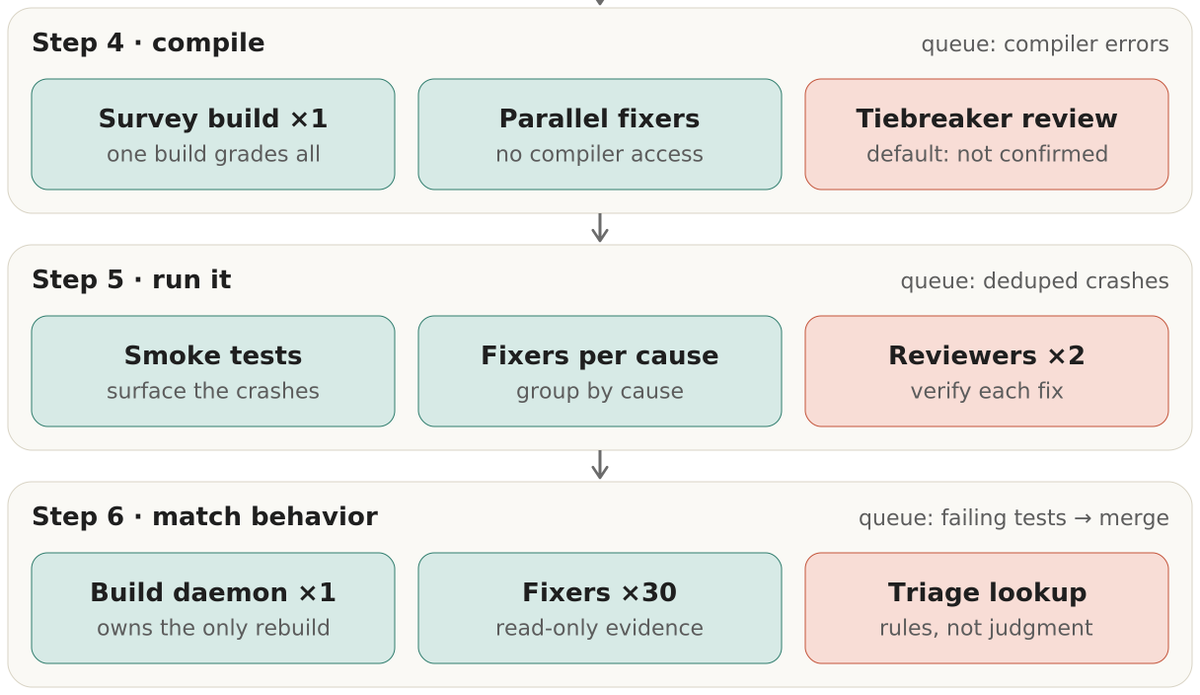
These three steps share the same loop architecture and need progressively less human judgment, so we cover them together.
Jarred executed this with an orchestrator script that invoked the compiler once across the whole workspace. "Fixer agents" then ran through the error list in parallel with adversarial review. The build runs again, rinse and repeat.
Reviewing the error list is helpful to catch systemic issues that may require adjustments. For example, Jarred ran into thousands of Rust module errors that surfaced after fixing cyclic imports that Zig's lazy compilation tolerated. He fixed the loop by encoding logic to classify which dependence to delete, move, or restructure the boundary.
Step 5 also has a mechanical source of truth similar to the compiler error list: crashes from the smoke test. Again, the loop fix was to group issues into categories, in this case grouping causes by root cause that are reviewed by adversarial subagents.
Step 6 and the end of our story is comparing the programs' behavior across the two codebases.
Our files have now been translated, compiled, and smoke tested.
Now it's time to shard them and run the test suite (from the prerequisite stage) against them. Tackle failures with "fixer agents" that review the failed tests against both codebases. Adversarial reviewers check their fixes.
The next stage in this loop is a build daemon, which is the only process allowed to rebuild the binary. Fixers write patches; the daemon batches them, rebuilds once, re-runs the affected tests, and feeds the results back. This serializes the most expensive operation instead of letting multiple agents trigger it independently.
Mike's approach matters here, because many developers won't have a built-out or ported test suite. Mike had Claude create a small script to run 7 real-world scenarios against both the new port and the original Python codebase, and diffed the results. Each failing scenario got its own fix agent, and the loop ran until all seven passed.
Then he went one step further. Claude designed its own end-to-end test suite and ran it autonomously overnight, fixing what broke and re-running four nights in a row. As a result, it caught the paper cuts no scenario list would have predicted.
The lesson is that a missing test suite doesn't block this step. If you can't inherit a referee, have Claude build one. Your original codebase is the ground truth either way.
## Code migrations best practices
Every run taught us something the previous one didn't. But a few practices held up across every project:
- Don't follow this guide blindly. Each migration is different. Treat this as a starting point, and plan your specific migration with Claude before committing to it.
- Don't focus on individual failures. Individual failures are the loop's job. Your attention belongs on the patterns.
- Make review adversarial and verification mechanical. Let scripts — a compiler, a diff, a test suite — be the referee.
- Don't use the largest model for everything. Smaller models handle the high-volume implementation fan-out well; save your largest model for reviewers and for anything that writes rules other agents will follow.
- Front-load the human hours. The rulebook and the stress test are the most time-consuming. Everything after is mostly queues burning down.
## Review loop results, not code
Jarred's Bun migration is now in production, although every migration has tradeoffs. For example, about 4% of the Rust code sits inside "unsafe" blocks, mostly single-line pointer operations at C/C++ boundaries.
But the new codebase is measurably better. Every memory leak the team's tooling can detect has been fixed: one benchmark of 2,000 repeated builds dropped from 6,745 MB of memory to 609. The binary is 19% smaller on Linux and Windows. And cross-language optimization made it 2–5% faster across HTTP serving and real-world workloads like next build and tsc.
Pick the codebase you've been tolerating and ask Claude what the migration process looks like for it.
## 相关链接
- [ClaudeDevs](https://x.com/ClaudeDevs)
- [@ClaudeDevs](https://x.com/ClaudeDevs)
- [158K](https://x.com/ClaudeDevs/status/2079654423828304282/analytics)
- [dynamic workflows](https://claude.com/blog/introducing-dynamic-workflows-in-claude-code)
- [@jarredsumner](https://x.com/@jarredsumner)
- [migrate Bun from Zig to Rust](https://bun.com/blog/bun-in-rust)
- [@mikeyk](https://x.com/@mikeyk)
- [which he writes about here](https://bun.com/blog/bun-in-rust#just-be-really-smart-and-don-t-make-mistakes)
- [Jarred's blog](https://bun.com/blog/bun-in-rust)
- [rulebook](https://github.com/anthropics/code-migration-kit-with-claude-code/blob/main/templates/RULEBOOK.md)
- [sample Claude Code prompt](https://github.com/anthropics/code-migration-kit-with-claude-code/blob/main/prompts/02-gap-inventory.md)
- [build daemon](https://github.com/anthropics/code-migration-kit-with-claude-code/blob/main/scripts/build_daemon.sh)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [3:47 AM · Jul 22, 2026](https://x.com/ClaudeDevs/status/2079654423828304282)
- [158.3K Views](https://x.com/ClaudeDevs/status/2079654423828304282/analytics)
- [View quotes](https://x.com/ClaudeDevs/status/2079654423828304282/quotes)
---
*导出时间: 2026/7/22 08:51:59*
---
## 中文翻译
# Anthropic 如何使用 Claude Code 进行大规模代码迁移
**作者**: ClaudeDevs
**日期**: 2026-07-21T19:47:07.000Z
**来源**: [https://x.com/ClaudeDevs/status/2079654423828304282](https://x.com/ClaudeDevs/status/2079654423828304282)
---

代码迁移——将生产代码库移植到新语言的项目——直到最近还都是需要多年时间的大工程。
在过去一个月里,Anthropic 的个人开发者使用 Claude Fable 5、Claude Opus 4.8 和动态工作流迁移了 10 个代码包,规模从数万行到数十万行代码不等。
Bun 的联合创始人、Anthropic 技术成员 Jarred Sumner(@jarredsumner)使用 Claude Code 将 Bun 从 Zig 迁移到了 Rust。不到两周时间生成了上百万行代码,且在合并前,Bun 现有的全部测试套件在 CI 中 100% 通过。合并后出现了 19 个回归问题,目前均已修复。Rust 移植版已于 6 月在 Claude Code 中发布。
Anthropic Labs 联合负责人 Mike Krieger(@mikeyk)在一个周末内将一个 Python 代码库迁移为了 16.5 万行 TypeScript。整个过程包括数百个 agent、八道阶段关卡、三轮对抗性审查,以及最后将每条命令的输出与 Python 原版进行逐一比对的完全一致性检查。
Claude Code 的新能力改变了这类长期被搁置项目的成本算式。以下是我们如今使用的六步流程,汲取自这些迁移项目的经验。
核心洞见是:你不要去修代码,而是去修复产生代码的那个流程(循环)。
## 为何迁移以及何时迁移语言
团队之所以启动迁移,是因为项目初建时的技术环境与当前项目之间发生了变化:要么是某项已知的取舍变成了瓶颈,要么是出现了更好的方案,要么是原有生态正在萎缩。
例如,Jarred 最初选择 Zig,是因为它提供了 C 语言级别的性能和极简的设计,对于一位“在 LLM 出现之前、于奥克兰一间狭小公寓里用一年时间编写 Bun”的独立创始人来说非常理想。这种简洁性伴随着已知的取舍,他在这里写过相关内容。
Bun 的 CLI 每月下载量超过 1000 万次,并在 Claude Code 内部被广泛使用。
就在上个季度,这些取舍还不足以成为冻结路线图、将资源投入一个为期数季度项目的理由。你可能需要在一个季度甚至几年内同时维护两套并行的代码库,而如果最终结果只有 90% 的一致性,你的麻烦反而比开始时更大。
而现在,最坏的情况不过是你删掉分支,重新再来。
当然,这仍然需要一个合理的商业理由。虽然百万行代码的迁移不再像过去四年周期那样耗费 300 万到 400 万美元的工程资源,但执行起来仍然需要数万到数十万美元甚至更多。以 Bun 的迁移为例,它消耗了 59 亿个未缓存输入 token 和 6.9 亿个输出 token——按 API 定价计算约为 16.5 万美元。Mike 移植工作的主要部分消耗了 2700 万个 token。

Jarred 的百万行 PR。
不过,迁移的理由不再需要关乎生死存亡。变更日志里一年的内存 bug 补丁,或者一个长期存在的瓶颈,如今都足以构成迁移的理由。
编译步骤正是 Mike 项目的动因。他团队开发的内部工具以单个二进制文件的形式交付给用户。使用 Python 工具链生成该二进制文件,每个平台大约需要八分钟,每次发布在整个构建矩阵上累计需要等待约 30 分钟。移植之后,同样的编译现在只需约两秒,二进制文件启动速度提升了 6 倍,团队还得以淘汰了一条单独的部署流水线。
## 为什么 AI 改变了代码迁移的成本算式
Fable 和 Opus 4.8 特别擅长通过子 agent 委派、指挥和验证并行工作流,同时为目标寻找多条实现路径。
大型代码迁移是这些先进模型尤为有效的应用场景,原因在于:
- 工作是并行的。工作可以在数千个独立单元(如文件和 crate)上执行,因此 agent 可以同时工作,而不必彼此等待。
- 上下文清晰且完整。旧代码本身就是给模型的绝佳规格说明。
- 有内置的裁判。许多大型代码库都包含测试套件,agent 可以用它来验证自己的工作。
- 队列会自动生成。当编译器或测试运行失败时,失败项就会成为 agent 接下来要修复的任务。
- 它们要求一致性和边界情况处理:审查者会为每一条发现引用规则依据,因此违规会变成队列任务,而不是悄无声息的偏离。
## 大型代码迁移的六个步骤
更多细节,你可以阅读 Jarred 的博客。
前置条件
在开始迁移项目之前,一个前提条件是要有一个可靠的评判机制,否则你既没有退出条件,也没有成功的衡量标准。
要构建这个评判机制:
- 对现有测试进行分类。使用 Claude 识别哪些测试可以表达为外部调用,哪些依赖于无法移植的内部实现。
- 为可移植性重写。将面向外部的测试转换为可以同时针对原版和移植版运行的断言。使用对抗性 agent 验证重写后的测试没有弱化断言。
- 验证评判机制。将其运行于原版代码以确认通过。然后运行于故意破坏的代码以确认失败——一个无法发现破坏的裁判不是裁判。
这主要遵循了 Jarred 的方法论,每个阶段都有审查和关卡。Mike 采用了类似的总体结构,使用类似的循环工作流,但他将整个迁移从头到尾跑完,根据结果修改规则和工作流,然后再重新运行——每次都丢弃输出,直到第三次运行。

## 第一步 — 创建规则手册、依赖关系图和缺口清单
顺序很重要:规则手册必须先于缺口清单。缺口清单是根据规则手册的默认规则无法覆盖的内容来定义的,而两者会在一次联合审计中共同接受检验。
## 规则手册
规则手册的具体形态取决于你在开始时必须做出的关键架构决策。其中最主要的是:新代码是沿用原有结构,还是完全重新设计。
如果是前者(Jarred 的做法),规则手册主要是查找表,用于在两种语言之间转换类型和惯用法,同时指向缺口清单以处理更难翻译的组件。如果是后者(Mike 的做法),它将是一份设计文档。
Jarred 通过与 Claude 对话创建了规则手册,针对每个模糊领域制定策略。他还使用了八个子代理,基于他自己的直觉专门审查 8 类不同的常见失败模式。
## 依赖图
你需要了解文件依赖关系,才能有效地为并行迁移拆分工作流,从而知道哪些文件应先迁移,哪些文件应包含在同一批次中。Claude Code 可以部署代理来创建并运行一个确定性脚本以生成此依赖图。
## 缺口清单与怀疑派审查者
新语言有旧语言所没有的、必须满足的要求。从 Zig 到 Rust 的差异是手动内存管理(C 和 C++ 的工作方式相同)。例如:
```
// Zig
fn readConfig(allocator: std.mem.Allocator) ![]u8 {
const buf = try allocator.alloc(u8, 1024);
// ...fill buf...
return buf; // caller must free this — but only the comment says so
}
// A caller that forgets 'defer allocator.free(buf)' still compiles — the leak only surfaces at runtime.
```
```
fn read_config() -> Vec<u8> {
let buf = vec![0u8; 1024];
// ...fill buf...
buf // ownership moves to the caller; memory is freed automatically
}
// Use it after it's moved? Free it twice? Neither compiles.
// Forget to free it? There's no free call to forget — drop is automatic.
```
从 Python 到 TypeScript 的缺口则是接口和契约。Python 不要求声明契约来说明它接受什么形状的对象或返回什么,而 TypeScript 有此要求。
Jarred 和 Mike 都创建了缺口清单文件来记录这些隐式知识。Jarred 提前清点了这些缺口,这也是我们在这里采用的做法;而 Mike 选择先翻译,然后通过事后审计来创建缺口清单。你可能两者都需要。
查看这个示例 Claude Code 提示词,用于创建缺口清单文件。
## 第 2 步 — 压力测试规则

在这一步中,Jarred 使用一个代理按照规则手册翻译三个文件,一个代理“像资深 Rust 工程师一样”翻译三个文件,还有一个代理使用差异对比来创建新的翻译规则。在这个阶段,他发现了两个关键问题,如果这些问题扩散到全部 1,448 个文件中,将会造成大量问题。
这种压力测试只适用于保留结构的迁移,即同一文件的两个翻译版本可以逐行比较。如果你的规则手册是一次重新设计——比如 Mike 的做法——那么等效的测试就是让对抗性审查者直接攻击设计文档,然后用一次性的端到端运行来验证它。
无论如何,都要丢弃所有已翻译的文件。目标是完善规则,而不是取得渐进式进展。
## 第 3 步 — 翻译所有内容

对于剩余步骤,你运行的是同一个多代理循环架构:实现、审查、修复。
你可以将实现者的工作交给较小的模型,而让审查者使用较大的模型。例如,Mike 在为主要的迁移部署 12 个子代理时使用了 Claude Sonnet。
工作队列应该是机械化的。一个批处理脚本通过检查磁盘上是否存在已翻译的文件来判断哪些工作已完成,然后将待处理文件切分成批次分配给实现者代理。由于队列每次都从磁盘重建,迁移在结构上就是可恢复的。
任何翻译者无法自信执行的内容都会被标记为“// TODO(port): <reason>”,留待第 4 步处理。
两个对抗性审查者在各自独立的上下文中评估实现者的工作,审查者之间的分歧会交给第三个代理处理。当某个审查者在多个文件中反复发现同样的错误时,解决办法不是逐文件修补,而是在规则手册中添加一句话,然后重新生成受影响的批次。规则手册在此步骤中不断增长;代码永远不会被手工打补丁来绕过它。
这一步中需要注意的一个重要设计决策是编译器的位置。Mike 在每个循环内都运行 TypeScript 编译器,因为它能在几秒钟内检查一个单元。而 Jarred 完全禁止在循环中使用编译器,将其推迟到下一步,因为 cargo 需要几分钟。
## 第 4、5、6 步 — 编译、运行并匹配行为

这三个步骤共享同一个循环架构,且需要的人工判断越来越少,因此我们将它们放在一起介绍。
Jarred 通过一个编排脚本来执行此步骤,该脚本对整个工作区调用一次编译器。然后“修复代理”对错误列表进行并行处理,并进行对抗性审查。之后再次运行构建,如此往复。
审查错误列表有助于发现可能需要调整的系统性问题。例如,Jarred 遇到了数千个 Rust 模块错误,这些错误是在修复循环导入后浮现的,而 Zig 的惰性编译原本容忍了这些问题。他通过在循环中编码逻辑来分类哪些依赖应删除、移动或重构边界,从而修复了这一循环。
第 5 步也有一个类似编译器错误列表的机械化事实来源:冒烟测试产生的崩溃。同样,循环修复方法是将问题归类,在这个案例中是按根本原因对成因分组,并由对抗性子代理进行审查。
第 6 步,也是我们故事的结尾,是比较两个代码库中程序的行为。
现在,我们的文件已经完成翻译、编译和冒烟测试。
接下来是分片运行测试套件(来自前置阶段)。用“修复智能体”来处理失败,它们会对照两个代码库审查失败的测试。对抗性审查员会检查他们的修复方案。
这个循环的下一个阶段是构建守护进程(build daemon),它是唯一允许重新构建二进制文件的进程。修复智能体编写补丁;守护进程将它们批量处理,只重新构建一次,重新运行受影响的测试,并将结果反馈回来。这将最昂贵的操作串行化,避免多个智能体各自独立触发。
Mike 的方法在这里很重要,因为许多开发者并没有现成的或已移植的测试套件。Mike 让 Claude 创建了一个小脚本,针对新移植版本和原始 Python 代码库运行 7 个真实场景,并对结果进行差异比较。每个失败的场景都分配了各自的修复智能体,循环持续运行直到所有七个场景都通过。
然后他更进一步。Claude 自己设计了端到端测试套件,并在夜间自主运行,修复出错的地方,连续四个晚上反复运行。因此,它捕捉到了任何场景清单都无法预测的细微问题。
教训是:缺少测试套件并不会阻碍这一步。如果你无法继承一个“裁判”,就让 Claude 建一个。无论如何,你的原始代码库就是真值标准。
## 代码迁移最佳实践
每一次运行都教会了我们上一次没有的东西。但有几条实践在所有项目中都得到了验证:
- 不要盲目遵循本指南。每次迁移都不同。把它当作起点,在决定迁移之前,先与 Claude 一起规划你的具体迁移方案。
- 不要纠结于个别失败。个别失败是循环的工作。你的注意力应该放在模式上。
- 让审查具有对抗性,验证机制化。让脚本——编译器、diff、测试套件——充当裁判。
- 不要对所有任务都使用最大的模型。较小的模型能很好地处理高并发的实现任务;把最大的模型留给审查员,以及任何编写其他智能体将要遵循的规则的任务。
- 把人工时间前置。规则手册和压力测试是最耗时的。之后的工作大多是排队任务的消化。
## 审查循环的结果,而非代码
Jarred 的 Bun 迁移现已投入生产,尽管每次迁移都有权衡。例如,大约 4% 的 Rust 代码位于"unsafe"块中,主要是 C/C++ 边界处的单行指针操作。
但新代码库确实更好。团队工具能检测到的每一个内存泄漏都已修复:一项 2,000 次重复构建的基准测试,内存占用从 6,745 MB 降至 609 MB。二进制文件在 Linux 和 Windows 上小了 19%。跨语言优化使其在 HTTP 服务以及 next build 和 tsc 等真实工作负载下快了 2–5%。
选出你一直忍受的那个代码库,问问 Claude 它的迁移流程是怎样的。
## 相关链接
- [ClaudeDevs](https://x.com/ClaudeDevs)
- [@ClaudeDevs](https://x.com/ClaudeDevs)
- [158K](https://x.com/ClaudeDevs/status/2079654423828304282/analytics)
- [dynamic workflows](https://claude.com/blog/introducing-dynamic-workflows-in-claude-code)
- [@jarredsumner](https://x.com/@jarredsumner)
- [migrate Bun from Zig to Rust](https://bun.com/blog/bun-in-rust)
- [@mikeyk](https://x.com/@mikeyk)
- [which he writes about here](https://bun.com/blog/bun-in-rust#just-be-really-smart-and-don-t-make-mistakes)
- [Jarred's blog](https://bun.com/blog/bun-in-rust)
- [rulebook](https://github.com/anthropics/code-migration-kit-with-claude-code/blob/main/templates/RULEBOOK.md)
- [sample Claude Code prompt](https://github.com/anthropics/code-migration-kit-with-claude-code/blob/main/prompts/02-gap-inventory.md)
- [build daemon](https://github.com/anthropics/code-migration-kit-with-claude-code/blob/main/scripts/build_daemon.sh)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [3:47 AM · Jul 22, 2026](https://x.com/ClaudeDevs/status/2079654423828304282)
- [158.3K Views](https://x.com/ClaudeDevs/status/2079654423828304282/analytics)
- [View quotes](https://x.com/ClaudeDevs/status/2079654423828304282/quotes)
---
*导出时间: 2026/7/22 08:51:59*