# The Harness Is the Backend
**作者**: Mike Piccolo
**日期**: 2026-04-28T14:49:59.000Z
**来源**: [https://x.com/mfpiccolo/status/2049139067359568032](https://x.com/mfpiccolo/status/2049139067359568032)
---
The most important architectural question in AI infrastructure right now isn’t which model to use. It’s how much infrastructure is required to build something useful with it.
Anthropic, OpenAI, CrewAI, LangChain all call that wrapping the agent harness. The harness includes the orchestration loop, tools (MCP, A2A), memory, context management, and error handling that make a model useful. They all agree the model isn’t the product. The infrastructure is. They disagree deeply on how much of it should exist.
Anthropic keeps their harness thin. It’s an elegant loop: Assemble the prompt, call the model, execute tool calls, and repeat. The model decides everything. OpenAI adds more structure: instruction stacks, orchestration modes, and explicit handoff patterns. CrewAI takes a multi-pronged approach: deterministic Flows for routing and validation, autonomous agents for the rest. LangGraph has the biggest harness Every decision is a node, every transition a defined edge, the entire workflow encoded in the harness.
The spectrum runs from strongly trusting the model and weakly encoding the logic to weakly trusting the model, and strongly encoding the logic. And every team building with agents has to choose what size of harness they need.
But there’s an assumption buried in the debate that nobody is questioning: that the harness is extrinsic to the traditional backend.
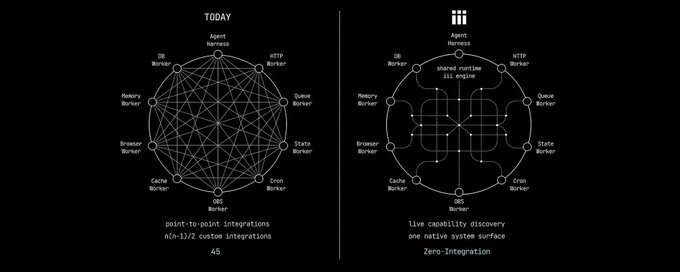
The agent’s loop, its tools, and its memory live in one layer: the harness. While execution infrastructure such as queues, state, HTTP routing, server side rendering, observability, and all other backend components live in another: “the backend”.
I believe that this is temporary and it’s just a small step along the way to true adoption and acceptance of agentic infrastructure into “the backend”.
## How Agents Work Today
Here’s how most agentic architectures work. The harness is a Python process (or TypeScript, or a managed framework) that wraps the model. When the agent decides to act, the harness translates a tool call into an HTTP request which in turn triggers something to happen on the backend like a queue publish or a database write. The backend is its own world that is kept separate from the agents.
The harness retries on its own schedule, the queue retries on its own conditions, and the HTTP layer manages its own timeouts. There is no trace directly connecting these disparate systems. When something breaks debugging means correlating logs across systems and reconstructing observed behavior. This is a common process in backend engineering but whereas prior systems were largely deterministic, agents are stochastic at best. .
With every additional agent the probabilities widen and at the most basic level are agents^2 * services. Put another way, 1 agent and 5 backend systems is 5 stochastic paths to debug. 4 agents and 5 backend systems are 80 stochastic paths to debug.
There is no good way to make agents more deterministic, much of their basic functionality is intended to give varied answers for similar and even identical inputs. They’re not stochastic by chance, they’re stochastic by intention because they make computers useful in a brand new way. The billion dollar question is how to handle agents properly by creating the correct harnesses in the correct contexts.
## Taking a Step Back
The fundamental promise of harnesses today is that they are trying to operate a new paradigm (stochastic LLMs) within an old one (deterministic backends). It’s not that construction of agent harnesses is inherently wrong, it’s that effective solutions must begin with the deconstruction of what a backend is.
Most of us have up until very recently taken the backend and how it works for granted; including myself. Without agents and the LLMs that power them I probably would have never thought about this problem before. So I embarked on a journey to figure out the fundamental building blocks of a backend.
At first I thought that backends are collections of services that exist in categories of products and are assembled with libraries, integrations, architecture diagrams, orchestration code, and the list kept growing. Eventually I realized that I was approaching this solution from the top down instead of bottom up. Once I realized that the backend became very simple:
A backend is composed of three essential elements: workers that orchestrate work, triggers that invoke these services, and functions within the services that do the actual work.
## Abstracting the Backend
Once I realized this it became clear that I, and my very talented team, could build a backend using this abstraction. Far from an academic exercise we’ve found this abstraction has very real utility both in the agentic world and more broadly as our abstraction completely encapsulates the execution context of “the backend”. So we built iii to make that abstraction available to everyone.
iii works just like my description above:
It defines Function as a unit of work with a stable identifier (ex. orders::validate) that receives input, and optionally returns output it can live in any process, and in any language.
A Trigger is what causes a function to run; it can be a direct call to a function, an HTTP endpoint, a cron schedule, a queue subscription, a state change, a stream event, or anything else. Triggers are declarative: the worker says “this function runs when this thing happens,” and iii handles routing, serialization, and delivery.
A Worker is any process that connects to the engine and registers functions and triggers.
A TypeScript API service is a worker. A Python ML pipeline is a worker. A Rust microservice is a worker. And an agent is a worker.
This is the idea that changes everything. An agent connects to the engine, registers functions and triggers, persists context through state::set, hands off work through queue-backed triggers, and broadcasts results via pub/sub. It doesn’t call “the backend” through a separate integration layer. It participates in the same system, with the same primitives, as everything else.
```
const iii = registerWorker('ws://localhost:49134', { workerName: 'agentic-backend' })
iii.registerFunction('agents::researcher', async (data) => { // the unit of work
// Python Worker: requests + duckduckgo-search
const sources = await iii.trigger({
function_id: 'web::search',
payload: { query: data.topic, limit: 10 }
})
// Rust Worker: scraper + tokio, fetched in parallel
const pages = await iii.trigger({
function_id: 'web::scrape',
payload: { urls: sources.map(s => s.url) }
})
// TypeScript Worker: wraps the OpenAI SDK
const findings = await iii.trigger({
function_id: 'llm::summarize',
payload: { topic: data.topic, documents: pages }
})
await iii.trigger({ // Rust Worker: persist to shared state
function_id: 'state::set',
payload: { scope: 'research-tasks', key: data.task_id, value: findings }
})
iii.trigger({ // TypeScript Worker: hand off to the critic
function_id: 'agents::critic',
payload: { task_id: data.task_id },
action: TriggerAction.Enqueue({ queue: 'agent-tasks' }) // run in the queue
})
return findings
})
iii.registerTrigger({ // HTTP entrypoint
type: 'http',
function_id: 'agents::researcher',
config: { api_path: '/agents/research', http_method: 'POST' }
})
iii.registerTrigger({ // also runs on a pending state row
type: 'state',
function_id: 'agents::researcher',
config: { scope: 'research-tasks', condition: 'status == "pending"' }
})
```
Three calls. registerFunction defines the work. registerTrigger binds it to the world — in this case an HTTP endpoint and a state change reaction, for the same function. The researcher is now callable via a POST request and automatically fires whenever a research task enters a pending state. Add another trigger and it also runs on a cron schedule. The function doesn’t change. The triggers compose.
The agent stores state with the same trigger() call a payment service would use. It hands off to the critic through the same queue mechanism an order pipeline would use. The agent’s “tools” are functions. Its “memory” is state. Its “orchestration” is triggers and composition. There is no special agent infrastructure because there doesn’t need to be.
The harness is the backend.
## Workers all the way down
This goes deeper than agents fitting into a backend. It’s about what iii considers a primitive and what happens when one primitive, in just a few lines of code, is the answer to every question.
In most platforms, every new capability is a new category. Need queues? Evaluate queue products. Need streaming? Different product. Sandboxing? Another. Each has its own internals, its own lifecycle, its own integration story. The platform is a catalog. Your job is to shop it and assemble it.
In iii, the answer to almost any question is the same: add a worker, which in turn registers triggers and functions.
I want sandboxing. Add a worker. I want an agent that researches topics. Add a worker. I want real-time streaming. Add a worker. I want go-to-market capabilities like lead scoring, email sequences, CRM sync. Add a worker. I want cron scheduling. It’s already a worker. I want observability. Already a worker.
The worker connects, registers what it can do, and the system absorbs it: live, discoverable, observable. The answer doesn’t change based on what kind of capability you’re adding. It doesn’t change based on language, or whether it’s infrastructure or business logic, or whether a human or an agent is creating it. Add a worker.
This is not just architectural uniformity. It’s a collapse of categories. In traditional systems, every capability lives in its own ontology. Queues have broker semantics, HTTP has routing semantics, cron has scheduling semantics, agents have orchestration semantics. In iii, they are all the same thing: a process that registers functions and triggers. The semantics live in the functions, not in the infrastructure.
Paradigm shifts in software don’t add features. They collapse categories. “Everything is a file” made Unix composable. Components as functions made React’s mental model stick. In iii, the answer is always “add a worker.” That’s the primitives. That’s the whole model.
## A live system
Because everything is a worker, three properties emerge that traditional architectures cannot produce:
Live discovery. When a worker connects, it receives the full catalog of every function registered across every other worker. When new functions appear, every worker gets notified. When a worker disconnects, every worker is notified. The engine is the single source of truth.
For agents, this is also cognitive infrastructure. An agent can see exactly what the entire system can do right now. There is no risk of an agent receiving outdated context.
Live extensibility. Add new workers and capabilities to a running iii system without redeploying or redesigning the architecture. There are no config changes and no restarts, because the system extends at runtime
This is how agentic systems actually want to operate. You don’t ever need to interrupt production to add a new capability. You connect a new worker, its functions distribute across the system, and any agent that can use them at will; or even extend the system with their own workers.
Live observability. iii’s observability is built on OpenTelemetry. Every function invocation carries a trace ID. Every trigger() call propagates it across workers, across languages, across queue handoffs. Every log emitted through the iii Logger is automatically correlated to the active trace and span, emitted as structured OpenTelemetry LogRecords, and routed to whichever backend you use: the iii Console, Grafana, Jaeger, Datadog. This isn’t a separate component to install and integrate, it’s just another worker Traces, metrics, and structured logs are produced by the engine itself, not by application-level middleware.
When an agent calls a tool that enqueues a message that triggers a downstream function that writes to state, the entire chain is one trace. Not three separate systems connected with timestamp correlation or manually tracked trace ids. One trace, across languages, across workers, across the agent-backend boundary. You go from a slow waterfall span directly to the correlated logs that explain what happened.
## Agents that create workers
Here is where the model gets truly recursive.
iii supports hardware-isolated microVM workers with hardware isolation. The sandbox functionality itself is a worker with its own filesystem, network stack, and process tree. You create a worker with a single command: iii worker add ./my-worker. The sandbox worker connects to the engine, registers functions and triggers, and participates in the system exactly like every other worker.
Now consider what happens when an agent can do this.
An agent worker can also spin up a new sandbox worker at runtime. That sandbox gets its own isolated environment. It registers its own functions and triggers. Those functions immediately appear in the live catalog. Other agents and services can invoke them. When the sandbox is no longer needed, it disconnects and its functions unregister.
The sandbox is not a separate “sandbox product.” It is a worker, using the same primitives as everything else it just happens to provide hardware isolation. An agent creating a sandbox worker is just one worker creating another.
This is what it looks like when infrastructure becomes a design pattern instead of a product category. Need isolated execution for untrusted code? That’s a sandbox worker. Need a temporary specialist agent? Spin up a worker, register functions, shut it down when finished. Need a fleet of parallel task executors? Have a worker spin up other workers. The primitive is the same. The pattern varies.
## The distinction disappears
Go back to the harness debate. Anthropic says thin. LangGraph says thick. They’re arguing about how much cognitive structure to encode around the model. The thin-vs-thick debate matters, but it’s a question within a design space, not about the design space itself.
When agents are workers, thin versus thick is just a question of how many functions you register and how you compose them. A thin harness is an agent worker with a few functions that lets the model decide what to trigger() next. A thick harness is an agent worker with more functions, explicit approval gates, and conditional logic before enqueuing the next step. It’s the same primitives and system, but a different pattern.
The scaffolding metaphor shifts too. The industry talks about harness scaffolding as temporary. As models improve, you remove it. Manus has described rebuilding Claude’s agent framework four times, with each rewrite the result of discovering a better way to shape context. Claude Code strips planning steps as new models absorb the capability.
If the harness is built from the same primitives as the rest of the backend, then removing scaffolding just means simplifying a function. You don’t rearchitect an integration layer. You don’t rebuild the interface between two systems. You just register fewer functions, or compose them differently.
## Anything is a worker
A worker is anything that can open a WebSocket, register a function, and speak the primitives interface. There is no constraint on what that thing is or what language it’s written in.
iii ships SDKs for TypeScript, Python, and Rust. But those aren’t the boundaries of the system. They’re three implementations of an open wire protocol: JSON over WebSocket. The engine doesn’t know what language is on the other end of the connection. It sees functions, triggers, and a connection. If your team writes Go, or Java, or Swift, or Zig, you write a small SDK that speaks the protocol and you’re a first-class participant. The primitives interface is the contract. Everything else is a design pattern.
This means the set of what can be a worker is genuinely unbounded. A Node.js service. A Python ML pipeline. An agent. A queue. A sandbox running inside a microVM. A browser. iii ships a browser SDK, so a tab on someone’s laptop can register functions, participate in live discovery, invoke backend functions, and be invoked by backend functions. The browser is in the system the same way a Kubernetes pod is.
A Raspberry Pi is a worker. An IoT sensor at the edge is a worker. A phone running a thin client is a worker. A CI runner that spins up, registers a function, does work, and disconnects is a worker. The engine doesn’t distinguish between these. Every new language, every new device, every new runtime that implements the primitives interface gets the full system for free: live discovery, live extensibility, live observability, durable triggers, cross-everything invocation. Not because we built a special integration for each one, but because the primitive allows this composition.
## The bet
The industry is debating how much scaffolding to wrap around the model. That debate matters, but it takes for granted that the harness is its own world, separate from the backend and separate from the infrastructure that actually runs when a tool fires.
iii makes a different bet: that the right primitives (worker, trigger, function) are small enough and universal enough that the question “what can participate in this system?” has the answer: anything. A cloud service. An agent. A browser. A microcontroller. A sandbox an agent just spun up. They all compose the same way. They all discover each other. They all trace the same.
When you stop treating “agent infrastructure” as separate from “backend infrastructure,” and when you stop treating any category of participant as architecturally different from any other, the system simplifies in a way that adding features never achieves. The boundaries between harness and backend, between cloud and edge, between infrastructure and application, and between human-written services and agent-created workers all dissolve into the same three primitives.
The harness isn’t on top of the backend. The harness is a part of the backend. And the backend is whatever connects to iii.
When you get the primitives right, the categories collapse and complexity is radically simplified.
iii is open source. Get started with our quickstart.
## 相关链接
- [Mike Piccolo](https://x.com/mfpiccolo)
- [@mfpiccolo](https://x.com/mfpiccolo)
- [113K](https://x.com/mfpiccolo/status/2049139067359568032/analytics)
- [has described](https://vrungta.substack.com/p/claude-code-architecture-reverse)
- [iii](https://iii.dev/)
- [Get started](https://iii.dev/docs/quickstart)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [10:49 PM · Apr 28, 2026](https://x.com/mfpiccolo/status/2049139067359568032)
- [113.9K Views](https://x.com/mfpiccolo/status/2049139067359568032/analytics)
- [View quotes](https://x.com/mfpiccolo/status/2049139067359568032/quotes)
---
*导出时间: 2026/4/29 17:23:31*
---
## 中文翻译
# 挽具即后端
**作者**: Mike Piccolo
**日期**: 2026-04-28T14:49:59.000Z
**来源**: [https://x.com/mfpiccolo/status/2049139067359568032](https://x.com/mfpiccolo/status/2049139067359568032)
---

当前 AI 基础设施中最重要的架构问题不是选择哪个模型,而是需要多少基础设施才能用模型构建出有用的东西。
Anthropic、OpenAI、CrewAI、LangChain 都把这种基础设施称为包裹智能体的“挽具”(harness)。挽具包括编排循环、工具(MCP、A2A)、记忆、上下文管理和错误处理,正是这些使模型变得有用。他们都同意:模型不是产品,基础设施才是。但对于这套基础设施应该有多大规模,他们分歧很深。
Anthropic 的挽具保持轻量。它是一个优雅的循环:组装提示词、调用模型、执行工具调用,然后重复。一切由模型决定。OpenAI 增加了更多结构:指令栈、编排模式以及显式的交接模式。CrewAI 采取多管齐下的方式:用确定性的 Flow 进行路由和验证,其余部分交给自主智能体。LangGraph 拥有最庞大的挽具:每个决策都是一个节点,每次转换都是一条定义好的边,整个工作流都编码在挽具中。
这个光谱从“强烈信任模型、弱编码逻辑”一直延伸到“弱信任模型、强编码逻辑”。每一个构建智能体应用的团队都必须选择自己需要多大规模的挽具。
但这场辩论中埋藏着一个无人质疑的假设:挽具独立于传统后端之外。
智能体的循环、工具和记忆位于一层:挽具。而执行基础设施——如队列、状态、HTTP 路由、服务端渲染、可观测性以及所有其他后端组件——则位于另一层:“后端”。
我相信这只是暂时的,这只是智能体基础设施被真正采纳和接受进“后端”的一小步。
## 智能体如今的工作方式
大多数智能体架构是这样工作的:挽具是一个 Python 进程(或 TypeScript,或托管框架),包裹着模型。当智能体决定执行动作时,挽具将工具调用转化为一个 HTTP 请求,进而触发后端发生某些事情,比如发布到队列或写入数据库。后端是独立的世界,与智能体彼此分离。
挽具按自己的节奏重试,队列按自己的条件重试,HTTP 层管理自己的超时。这些彼此割裂的系统之间没有直接的追踪链路。当出现故障时,调试意味着跨系统关联日志并重构观察到的行为。这在后端工程中是常见流程,但以往的系统基本是确定性的,而智能体充其量是随机的。
每增加一个智能体,概率空间就会扩大,最基本的复杂度是 agents² × services。换句话说,1 个智能体加 5 个后端系统意味着 5 条需要调试的随机路径;4 个智能体加 5 个后端系统则是 80 条随机路径。
没有什么好办法让智能体变得更确定,它们的基本功能本来就是要对相似甚至相同的输入给出不同的答案。它们的随机性不是偶然的,而是有意为之的——正因为如此,计算机才以一种全新的方式变得有用。价值十亿美元的问题是:如何通过在正确的上下文中构建正确的挽具来妥善驾驭智能体。
## 退一步思考
如今挽具的根本承诺,是试图在旧范式(确定性后端)内运行一种新范式(随机性的 LLM)。问题不在于构建智能体挽具本身是错的,而在于有效的解决方案必须从解构“后端是什么”开始。
直到最近,包括我在内,我们大多数人都把后端及其运作方式视为理所当然。如果没有智能体和驱动它们的 LLM,我可能永远不会思考过这个问题。于是我踏上了一段旅程,去弄清后端的基本构成要素。
起初我以为后端就是存在于各类产品类别中的服务集合,由库、集成、架构图、编排代码等组装而成,而且这个清单还在不断增长。最终我意识到自己是从自顶向下的角度来解决这个问题,而不是自底向上。当我意识到这一点后,后端就变得非常简单了:
后端由三个基本要素组成:编排工作的 worker、调用这些服务的 trigger,以及服务内实际执行工作的 function。
## 抽象后端
意识到这一点后,我很清楚,我和我非常优秀的团队可以用这个抽象来构建后端。这远非学术练习——我们发现这个抽象在智能体领域乃至更广泛的领域都有非常实际的用途,因为它完全封装了“后端”的执行上下文。于是我们构建了 iii,让每个人都能使用这个抽象。
iii 的工作方式正如我上面的描述:
它将 Function(函数)定义为一个工作单元,具有稳定标识符(如 orders::validate),接收输入,可选地返回输出;它可以存在于任何进程、任何语言中。
Trigger(触发器)是使函数运行的原因;它可以是对函数的直接调用、HTTP 端点、cron 定时任务、队列订阅、状态变更、流事件,或任何其他东西。触发器是声明式的:worker 声明“当这件事发生时,这个函数就运行”,而 iii 负责路由、序列化和投递。
Worker(工作进程)是连接到引擎并注册函数和触发器的任何进程。
一个 TypeScript API 服务是一个 worker。一个 Python ML 流水线是一个 worker。一个 Rust 微服务是一个 worker。一个智能体也是一个 worker。
这正是改变一切的理念。一个 Agent 连接到引擎,注册函数和触发器,通过 state::set 持久化上下文,通过基于队列的触发器交接工作,并通过 pub/sub 广播结果。它不需要通过单独的集成层去调用“后端”。它与其他所有组件一样,使用相同的原语,参与同一个系统。
```
const iii = registerWorker('ws://localhost:49134', { workerName: 'agentic-backend' })
iii.registerFunction('agents::researcher', async (data) => { // 工作单元
// Python Worker:requests + duckduckgo-search
const sources = await iii.trigger({
function_id: 'web::search',
payload: { query: data.topic, limit: 10 }
})
// Rust Worker:scraper + tokio,并行抓取
const pages = await iii.trigger({
function_id: 'web::scrape',
payload: { urls: sources.map(s => s.url) }
})
// TypeScript Worker:封装了 OpenAI SDK
const findings = await iii.trigger({
function_id: 'llm::summarize',
payload: { topic: data.topic, documents: pages }
})
await iii.trigger({ // Rust Worker:持久化到共享状态
function_id: 'state::set',
payload: { scope: 'research-tasks', key: data.task_id, value: findings }
})
iii.trigger({ // TypeScript Worker:交接给 critic
function_id: 'agents::critic',
payload: { task_id: data.task_id },
action: TriggerAction.Enqueue({ queue: 'agent-tasks' }) // 在队列中运行
})
return findings
})
iii.registerTrigger({ // HTTP 入口
type: 'http',
function_id: 'agents::researcher',
config: { api_path: '/agents/research', http_method: 'POST' }
})
iii.registerTrigger({ // 也可以在待处理的状态行上运行
type: 'state',
function_id: 'agents::researcher',
config: { scope: 'research-tasks', condition: 'status == "pending"' }
})
```
三次调用。registerFunction 定义了工作。registerTrigger 将其绑定到外部世界——在这里,同一个函数绑定了一个 HTTP 端点和一个状态变更反应。现在,这个 researcher 可以通过 POST 请求调用,并且每当有研究任务进入 pending 状态时就会自动触发。再加一个触发器,它还能按 cron 计划运行。函数本身不变,触发器自由组合。
Agent 存储状态所用的 trigger() 调用,与支付服务所用的完全相同。它交接给 critic 的队列机制,与订单流水线所用的完全相同。Agent 的“工具”就是函数,它的“记忆”就是状态,它的“编排”就是触发器和组合。不需要特殊的 Agent 基础设施,因为根本没必要有。
测试框架就是后端。
## 一路向下,全是 Worker
这不仅仅是 Agent 融入后端那么简单。它关乎 iii 把什么视为原语,以及当仅仅几行代码的一个原语就能回答所有问题时会发生什么。
在大多数平台上,每一项新能力都是一个新品类。需要队列?去评估队列产品。需要流式处理?另一个产品。沙箱?又一个。每个都有自己的内部机制、自己的生命周期、自己的集成方式。平台是一个商品目录,你的工作就是挑选并组装。
在 iii 中,几乎任何问题的答案都是一样的:添加一个 Worker,它会注册自己的触发器和函数。
我想要沙箱。添加一个 Worker。我想要一个能做课题研究的 Agent。添加一个 Worker。我想要实时流式传输。添加一个 Worker。我想要 GTM 能力,比如线索评分、邮件序列、CRM 同步。添加一个 Worker。我想要 cron 调度。它本身就已经是一个 Worker。我想要可观测性。它也已经是 Worker。
Worker 连接上来,注册它能做的事,系统将其吸收:实时、可发现、可观测。答案不会因为你添加什么类型的能力而改变,也不会因为语言不同而改变,无论它是基础设施还是业务逻辑,无论是人类还是 Agent 在创建它。添加一个 Worker。
这不仅仅是架构上的统一,而是品类的坍缩。在传统系统中,每种能力都活在各自的本体论里。队列有消息代理语义,HTTP 有路由语义,cron 有调度语义,Agent 有编排语义。而在 iii 中,它们都是同一件事:一个注册函数和触发器的进程。语义存在于函数中,而不是基础设施中。
软件领域的范式转变不是增加功能,而是坍缩品类。“一切皆文件”让 Unix 具备了可组合性。“组件即函数”让 React 的思维模式深入人心。在 iii 中,答案永远是“添加一个 Worker”。这就是原语,这就是整个模型。
## 一个活的系统
因为一切都是 Worker,所以会涌现出三种传统架构无法实现的特性:
实时发现。当一个 Worker 连接时,它会收到跨所有其他 Worker 注册的每个函数的完整目录。当新函数出现时,每个 Worker 都会收到通知。当某个 Worker 断开连接时,每个 Worker 也会收到通知。引擎是唯一的真相来源。
对 Agent 而言,这也是认知基础设施。Agent 能确切地看到整个系统当前能做什么,不存在收到过时上下文的风险。
实时扩展。向运行中的 iii 系统添加新的 Worker 和能力,无需重新部署或重新设计架构。没有配置更改,也不需要重启,因为系统是在运行时扩展的。
这正是 Agent 系统真正期望的运作方式。你从不需要中断生产环境来添加新能力。你只需连接一个新的 Worker,它的函数就会分布到整个系统中,任何 Agent 都可以随意使用它们;甚至还可以用它们自己的 Worker 来扩展系统。
实时可观测性。iii 的可观测性构建在 OpenTelemetry 之上。每次函数调用都携带一个 trace ID。每次 trigger() 调用都会在 worker 之间、语言之间、队列交接之间传播这个 trace ID。每条通过 iii Logger 发出的日志都会自动与当前的 trace 和 span 关联,以结构化的 OpenTelemetry LogRecords 形式发出,并路由到你使用的任意后端:iii Console、Grafana、Jaeger、Datadog。这不是一个需要单独安装和集成的组件,它只是又一个 worker。trace、指标和结构化日志由引擎本身生成,而不是由应用层中间件生成。
当一个 agent 调用一个工具,该工具将一条消息入队,从而触发一个下游函数,该函数写入状态——整条链路就是一个 trace。不是通过时间戳关联或手动追踪 trace id 连接起来的三个独立系统,而是一个 trace,跨越语言、跨越 worker、跨越 agent 与后端的边界。你可以从一个缓慢的瀑布式 span 直接跳转到解释发生了什么的关联日志。
## 能创建 worker 的 Agent
这才是这个模型真正递归的地方。
iii 支持具备硬件隔离的 microVM worker。沙箱功能本身就是一个 worker,拥有自己的文件系统、网络栈和进程树。你只需一条命令即可创建一个 worker:iii worker add ./my-worker。沙箱 worker 连接到引擎,注册函数和触发器,并像其他所有 worker 一样参与整个系统。
现在考虑一下,当一个 agent 能够做到这一点时会发生什么。
一个 agent worker 也可以在运行时启动一个新的沙箱 worker。这个沙箱获得自己隔离的环境。它注册自己的函数和触发器。这些函数立即出现在实时目录中。其他 agent 和服务可以调用它们。当沙箱不再需要时,它会断开连接,其函数也随之注销。
沙箱并不是一个独立的“沙箱产品”。它是一个 worker,使用与其他一切相同的基础原语,只是它恰好提供硬件隔离。一个 agent 创建沙箱 worker,只是一个 worker 创建另一个 worker。
这就是基础设施从一种产品类别变成一种设计模式时的样子。需要为不受信任的代码提供隔离执行?那就是一个沙箱 worker。需要一个临时的专家 agent?启动一个 worker,注册函数,完成后关闭它。需要一群并行的任务执行器?让一个 worker 启动其他 worker。原语是相同的,变化的只是模式。
## 区别消失了
回到关于 harness 的争论。Anthropic 主张薄,LangGraph 主张厚。他们争论的是要在模型周围编码多少认知结构。薄与厚的争论很重要,但这是设计空间内部的问题,而不是关于设计空间本身的问题。
当 agent 就是 worker 时,薄与厚只是你注册多少函数以及如何组合它们的问题。薄 harness 是一个只有少量函数的 agent worker,让模型决定接下来触发什么。厚 harness 是一个拥有更多函数、显式审批门控以及在将下一步入队之前包含条件逻辑的 agent worker。原语和系统是相同的,只是模式不同。
脚手架的比喻也随之改变。业界谈论 harness 脚手架时通常认为它是临时的。随着模型进步,你把它移除。Manus 曾描述过四度重写 Claude 的 agent 框架,每次重写都是因为发现了更好的上下文组织方式。Claude Code 会随着新模型吸收相应能力而逐步剥离规划步骤。
如果 harness 是用与后端其他部分相同的基础原语构建的,那么移除脚手架只是简化一个函数。你不需要重新设计集成层。你不需要重建两个系统之间的接口。你只需注册更少的函数,或者以不同的方式组合它们。
## 万物皆 worker
worker 是任何能够打开 WebSocket、注册函数并使用原语接口的东西。对这个东西是什么、用什么语言编写没有任何限制。
iii 提供了 TypeScript、Python 和 Rust 的 SDK。但这些并不是系统的边界。它们只是开放线路协议的三种实现:基于 WebSocket 的 JSON。引擎不知道连接另一端是什么语言。它看到的只是函数、触发器和一条连接。如果你的团队用 Go、Java、Swift 或 Zig 编写代码,你只需编写一个使用该协议的小型 SDK,你就成了一等公民。原语接口就是契约,其余一切都是设计模式。
这意味着可以成为 worker 的对象集合是真正无界的。一个 Node.js 服务。一个 Python 机器学习流水线。一个 agent。一个队列。一个运行在 microVM 中的沙箱。一个浏览器。iii 提供了浏览器 SDK,因此某人笔记本电脑上的一个标签页就可以注册函数、参与实时发现、调用后端函数,并可以被后端函数调用。浏览器进入系统的方式与 Kubernetes pod 完全相同。
一个树莓派是 worker。边缘的一个物联网传感器是 worker。运行瘦客户端的手机是 worker。一个启动后注册函数、执行工作然后断开连接的 CI runner 是 worker。引擎并不区分这些。每一个实现原语接口的新语言、新设备、新运行时,都能免费获得完整系统:实时发现、实时可扩展性、实时可观测性、持久化触发器、万物互联的调用能力。这不是因为我们为每一个都构建了专门的集成,而是因为原语本身就允许这种组合。
## 这一赌注
业界正在争论应该围绕模型包裹多少脚手架。这场争论很重要,但它默认了一个前提:harness 是一个独立的世界,与后端分离,也与工具真正触发时运行的基础设施分离。
iii 下了一个不同的赌注:正确的原语(worker、trigger、function)足够小、足够通用,以至于“什么可以参与这个系统?”这个问题的答案是:任何东西。一个云服务。一个智能体。一个浏览器。一个微控制器。一个智能体刚启动的沙箱。它们都以同样的方式组合。它们都能相互发现。它们都能以相同方式进行追踪。
当你不再把“智能体基础设施”与“后端基础设施”区别对待,当你不再把任何一类参与者视为在架构上不同于其他参与者时,系统会以单纯增加功能永远无法实现的方式得到简化。harness 与后端之间、云与边缘之间、基础设施与应用之间、以及人工编写的服务与智能体创建的 worker 之间的边界,全部消融为同样的三个原语。
harness 不在后端之上。harness 是后端的一部分。而后端就是任何连接到 iii 的东西。
当你把原语做对了,各种类别就会坍缩,复杂性被彻底简化。
iii 是开源的。通过我们的快速入门开始使用。
## 相关链接
- [Mike Piccolo](https://x.com/mfpiccolo)
- [@mfpiccolo](https://x.com/mfpiccolo)
- [113K](https://x.com/mfpiccolo/status/2049139067359568032/analytics)
- [has described](https://vrungta.substack.com/p/claude-code-architecture-reverse)
- [iii](https://iii.dev/)
- [Get started](https://iii.dev/docs/quickstart)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [10:49 PM · Apr 28, 2026](https://x.com/mfpiccolo/status/2049139067359568032)
- [113.9K Views](https://x.com/mfpiccolo/status/2049139067359568032/analytics)
- [View quotes](https://x.com/mfpiccolo/status/2049139067359568032/quotes)
---
*导出时间: 2026/4/29 17:23:31*