# Prompt caching in LLMs, clearly explained
**作者**: Avi Chawla
**日期**: 2026-04-16T06:52:15.000Z
**来源**: [https://x.com/_avichawla/status/2044670188998803855](https://x.com/_avichawla/status/2044670188998803855)
---
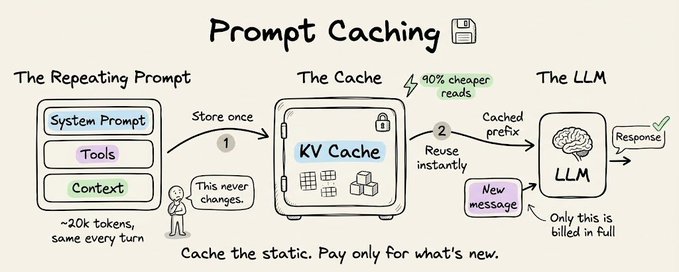
A case study on how Claude achieves 92% cache hit-rate
Every time an AI agent takes a step, it sends the entire conversation history back to the LLM.
That includes the system instructions, the tool definitions, and the project context it already processed three turns ago. All of it gets re-read, re-processed, and re-billed on every single turn.
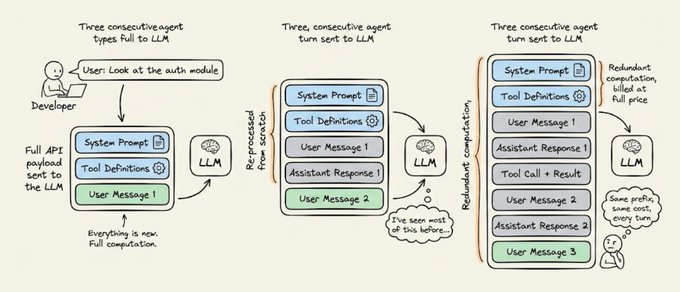
For long-running agentic workflows, this redundant computation is often the most expensive line item in your entire AI infrastructure.
A system prompt with 20,000 tokens running over 50 turns means 1 million tokens of redundant computation billed at full price, producing zero new value. And that cost compounds across every user and every session.
The fix is prompt caching. But to use it well, you need to understand what’s actually happening under the hood.
## Static vs. Dynamic context
Before you can optimize a prompt, you need to understand what changes and what doesn’t.
Every agent request has two fundamentally different parts:
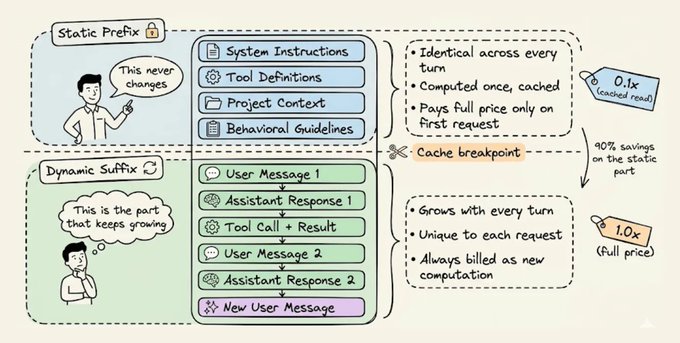
- The static prefix that stays identical across turns: system instructions, tool definitions, project context, and behavioral guidelines.
- The dynamic suffix that grows with every turn: user messages, assistant responses, tool outputs, and terminal observations.
This split is what makes prompt caching possible. The infrastructure stores the mathematical state of the static prefix so that subsequent requests sharing that exact prefix can skip the computation entirely and read from memory.
Once you internalize this, every architectural decision in this article becomes obvious.
## How does the KV Cache work?
To understand why caching is so effective, you need to know what the transformer actually does when it processes your prompt.
Every LLM inference request has two phases:
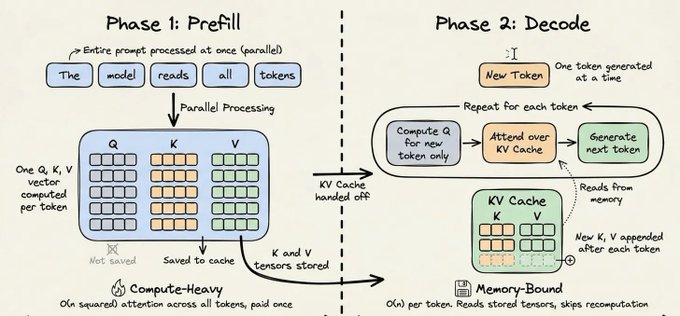
- The prefill phase handles the entire input prompt. It runs dense matrix multiplications across all tokens in context to build the model’s internal representation. This is compute-bound and expensive.
- The decode phase generates tokens one at a time. Each new token gets added to the sequence, and the model predicts the next one. This phase is memory-bound because it mostly reads the historical state rather than doing heavy computation.
During the prefill phase, the transformer computes three vectors for each token: a Query, a Key, and a Value. The attention mechanism uses these to determine how each token relates to every other token. The Key and Value vectors for any given token depend only on the tokens before it, and once computed, they never change.

Without caching, these Key and Value tensors get thrown away after every request, and the next request recomputes them from scratch. For a 20,000-token prefix, that’s 20,000 tokens worth of attention computation that didn’t need to happen again.
The KV cache fixes this by persisting those tensors on the inference servers, indexed by a cryptographic hash of the token sequence. When a new request comes in with the same prefix, the hash matches, the tensors are loaded from memory, and the prefill computation for those tokens is skipped entirely.
This drops computational complexity from O(n²) per generated token to O(n). And for a 20,000-token prefix repeated across 50 turns, that's an enormous reduction.
## The Economics
The pricing structure is what makes this architectural decision so consequential.
Cache reads cost 0.1x the base input price, which is a 90% discount on every cached token. Cache writes cost 1.25x, a 25% premium to store the KV tensors. Extended one-hour caching costs 2.0x.
Here’s what this looks like across Anthropic’s Claude models:
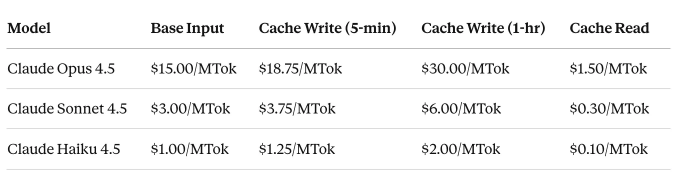
This math only works if the cache hit rate stays high. The best production example of what that looks like is Claude Code.
## A 30-minute coding session with Claude Code
Claude Code is built entirely around one objective: keep the cache hot.
Here’s what a real 30-minute coding session looks like from a billing perspective.
Minute 0: Claude Code loads its system prompt, tool definitions, and the project’s CLAUDE.md file. This payload exceeds 20,000 tokens, and since every token is new, this is the most expensive moment of the entire session. But you only pay this cost once.
Minutes 1 to 5: You start giving instructions, and Claude Code dispatches its Explore Subagent to navigate the codebase, open files, and run grep commands. All of this gets appended to the dynamic suffix. But the 20,000-token static prefix is now reading from cache at $0.30/MTok instead of $3.00/MTok.
Minutes 6 to 15: The Plan Subagent receives a summarized brief rather than the raw results, because passing raw output would bloat the dynamic suffix unnecessarily. It produces an implementation plan, you approve it, and Claude Code starts making changes. Every turn reads the static prefix from cache, the hit rate climbs past 90%, and each access resets the TTL to keep the cache warm.
Minutes 16 to 25: You request changes, which means more tool calls, more terminal output, and more context accumulating in the dynamic suffix. By now the session has processed hundreds of thousands of tokens, but every single turn has read the 20,000-token foundation from cache.
Minute 28: You run /cost in the terminal. Without caching, 2 million tokens at the Sonnet 4.5 rate would cost $6.00. With the cache running at 92% efficiency, 1.84 million tokens were cache reads, bringing the total cost to $1.15. That’s an 81% reduction on a single task.

This is how a hot cache looks. You have to pay for the static foundation once, and then you can read it for free. The dynamic tail is the only thing that is ever charged.
## The fragility of hash-based caching
Here’s the most counterintuitive thing about prompt caching:
“1 + 2 = 3” works but “2 + 1” is a cache miss.
The infrastructure hashes the full token sequence from the beginning. If anything in that sequence changes, even just the order of two elements, the hash changes and the entire prefix gets recomputed at full price.
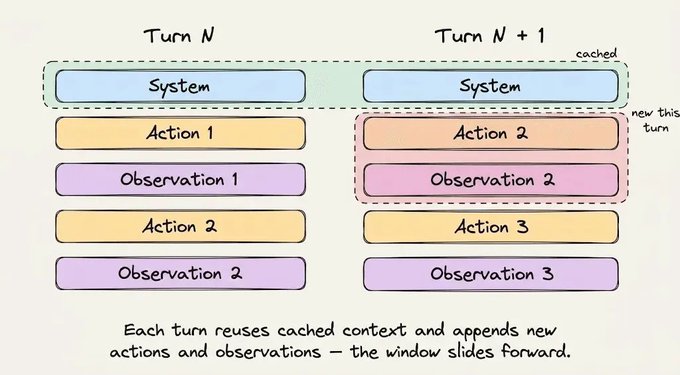
This isn’t a minor implementation detail. It’s the central constraint that every engineering decision in Claude Code is designed around.
Here are real examples of what has broken caches in production:
- A timestamp injected into the system prompt created a unique hash on every request.
- A JSON serializer that sorted tool schema keys differently between requests invalidated the prefix.
- An AgentTool whose parameters were updated mid-session wiped the entire 20,000-token cache.
Three rules follow from this:
Don’t modify tools during a session. The tool definitions are part of the cached prefix, so adding or removing a tool invalidates everything downstream.
Never switch models mid-session. Caches are model-specific, which means switching to a cheaper model mid-conversation requires rebuilding the entire cache from scratch.
Never mutate the prefix to update state. Instead of editing the system prompt, Claude Code appends a reminder tag to the next user message so that the prefix stays untouched.
## Applying this to your own Agents
The same rules apply whether you’re using Claude Code or building your own agent from scratch.
Structure your prompts in this order:
System instructions and behavioral rules at the top. Don’t change them mid-session.
Load all tool definitions upfront. Don’t add or remove them.
Retrieved context and reference documents next. Keep them stable for the session duration.
Conversation history and tool outputs at the bottom. This is your dynamic suffix.
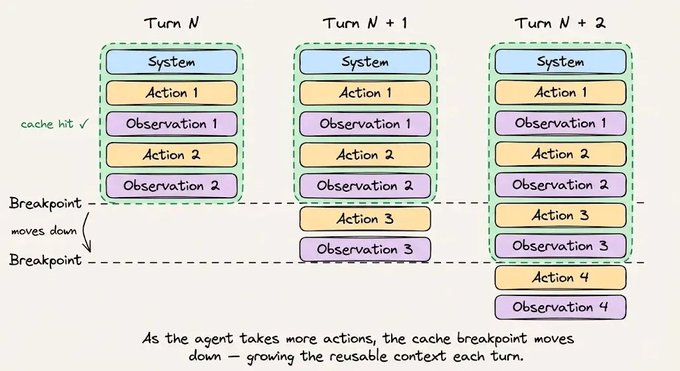
With auto-caching enabled on the Anthropic API, the cache breakpoint advances automatically as the conversation grows. Without it, you’d need to manually track token boundaries, and a wrong boundary means missing the cache entirely.
For context compaction when you’re approaching the context limit, use cache-safe forking. Keep the same system prompt, tools, and conversation history, then append the compaction instruction as a new message. The cached prefix gets reused, and the only new tokens billed are the compaction instruction itself.

To verify your caching is working, monitor these three fields in every API response:
- cache_creation_input_tokens are the tokens written to cache.
- cache_read_input_tokens are the tokens served from cache.
- input_tokens are the tokens processed without caching.
Your cache efficiency is cache_read_input_tokens / (cache_read_input_tokens + cache_creation_input_tokens). Track it the same way you track uptime.
## Key takeaways
Prompt caching isn’t a feature you toggle on. It’s an architectural discipline you design around.
The core idea is simple: structure your prompts so the static content sits at the top and the dynamic content grows at the bottom. The infrastructure hashes the prefix, stores the KV tensors, and gives you a 90% discount on every subsequent read.
But the discipline is in the details. Don’t inject timestamps into system prompts, don’t shuffle tool definitions, don’t switch models mid-session, and don’t mutate anything upstream of the cache breakpoint.
Claude Code demonstrates what this looks like at scale, with a 92% cache hit rate and an 81% cost reduction. If you’re building agents and not designing around prompt caching, you’re leaving most of your margin on the table.
That's a wrap!
If you enjoyed this tutorial:
Find me → @_avichawla
Every day, I share tutorials and insights on DS, ML, LLMs, and RAGs.
## 相关链接
- [Avi Chawla](https://x.com/_avichawla)
- [@_avichawla](https://x.com/_avichawla)
- [1.6K](https://x.com/_avichawla/status/2044670188998803855/analytics)
- [@_avichawla](https://x.com/@_avichawla)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [2:52 PM · Apr 16, 2026](https://x.com/_avichawla/status/2044670188998803855)
- [1,606 Views](https://x.com/_avichawla/status/2044670188998803855/analytics)
---
*导出时间: 2026/4/16 16:12:27*
---
## 中文翻译
# 大语言模型中的提示词缓存,通俗详解
**作者**: Avi Chawla
**日期**: 2026-04-16T06:52:15.000Z
**来源**: [https://x.com/_avichawla/status/2044670188998803855](https://x.com/_avichawla/status/2044670188998803855)
---

一个关于 Claude 如何实现 92% 缓存命中率的案例研究
每当 AI 智能体执行一步操作,它都会把整个对话历史重新发回给大语言模型。
这包括系统指令、工具定义,以及它在三轮对话之前就已经处理过的项目上下文。所有这些内容在每一轮对话中都会被重新读取、重新处理、重新计费。

对于长时间运行的智能体工作流来说,这种冗余计算往往是整个 AI 基础设施中最昂贵的一项开销。
一个包含 20,000 个 token 的系统提示词运行 50 轮,意味着 100 万 token 的冗余计算按全价计费,却没有产生任何新价值。而且这笔成本会随着每个用户和每个会话不断累积。
解决方案就是提示词缓存。但要用好它,你需要理解底层到底发生了什么。
## 静态上下文 vs. 动态上下文
在优化提示词之前,你需要弄清楚哪些内容会变化,哪些不会。
每个智能体请求都包含两个本质上不同的部分:

- 静态前缀,在各轮对话中保持不变:系统指令、工具定义、项目上下文和行为准则。
- 动态后缀,随每一轮对话不断增长:用户消息、助手回复、工具输出和终端观察结果。
正是这种划分使提示词缓存成为可能。基础设施会存储静态前缀的数学状态,这样后续共享完全相同前缀的请求就可以完全跳过计算,直接从内存中读取。
一旦你真正理解了这一点,本文中的每一个架构决策就都变得显而易见了。
## KV 缓存是如何工作的?
要理解为什么缓存如此有效,你需要知道 Transformer 在处理你的提示词时到底在做什么。
每次大语言模型推理请求都有两个阶段:

- 预填充(prefill)阶段处理整个输入提示词。它对上下文中的所有 token 运行密集的矩阵乘法,以构建模型的内部表示。这一阶段是计算受限的,成本很高。
- 解码(decode)阶段逐个生成 token。每个新 token 都会被添加到序列中,模型再预测下一个 token。这一阶段是内存受限的,因为它主要是读取历史状态,而不是进行大量计算。
在预填充阶段,Transformer 会为每个 token 计算三个向量:查询、键和值。注意力机制利用这些向量来确定每个 token 与其他所有 token 之间的关系。任意给定 token 的键向量和值向量只取决于它之前的 token,而且一旦计算出来,就永远不会改变。

在没有缓存的情况下,这些键值张量在每次请求结束后都会被丢弃,下一次请求又要从头重新计算。对于一个 20,000 个 token 的前缀来说,这意味着 20,000 个 token 的注意力计算本不需要再重复进行。
KV 缓存通过在推理服务器上持久化这些张量来解决这个问题,并使用 token 序列的加密哈希值作为索引。当新请求带有相同的前缀时,哈希值匹配,张量直接从内存中加载,这些 token 的预填充计算就被完全跳过了。
这将每个生成 token 的计算复杂度从 O(n²) 降至 O(n)。对于一个 20,000 token 的前缀重复 50 轮的场景,这是一个巨大的节省。
## 经济账
定价结构正是让这一架构决策如此重要的原因。
缓存读取的成本是基础输入价格的 0.1 倍,也就是每个缓存 token 享受 90% 的折扣。缓存写入的成本是 1.25 倍,即为存储 KV 张量支付 25% 的溢价。延长至一小时缓存的成本是 2.0 倍。
以下是 Anthropic 各 Claude 模型的具体定价:

只有当缓存命中率保持在高水平时,这笔账才划算。生产环境中最好的范例就是 Claude Code。
## 使用 Claude Code 进行 30 分钟的编程会话
Claude Code 完全围绕一个目标构建:保持缓存热度。
以下是从计费角度看,一个真实的 30 分钟编程会话是什么样的。
第 0 分钟:Claude Code 加载其系统提示词、工具定义和项目的 CLAUDE.md 文件。这个负载超过 20,000 个 token,由于每个 token 都是新的,这是整个会话中最昂贵的时刻。但这笔成本你只需支付一次。
第 1 到 5 分钟:你开始下达指令,Claude Code 派出它的 Explore 子智能体去浏览代码库、打开文件并运行 grep 命令。所有这些都会被追加到动态后缀中。但那 20,000 个 token 的静态前缀现在是从缓存中读取的,价格为 $0.30/百万 token,而不是 $3.00/百万 token。
第 6 到 15 分钟:Plan 子智能体收到的是摘要简报,而不是原始结果,因为传递原始输出会不必要地膨胀动态后缀。它产出一个实现方案,你批准后,Claude Code 开始进行修改。每一轮都从缓存读取静态前缀,命中率攀升至 90% 以上,且每次访问都会重置 TTL 以保持缓存热度。
第 16 到 25 分钟:你提出修改请求,这意味着更多的工具调用、更多的终端输出,以及动态后缀中不断累积的更多上下文。此时会话已经处理了数十万个 token,但每一轮都从缓存读取了那 20,000 个 token 的基础内容。
第 28 分钟:你在终端运行 /cost。如果不使用缓存,按 Sonnet 4.5 的费率,200 万 token 将花费 $6.00。而缓存以 92% 的效率运行时,184 万个 token 是缓存读取,总成本降至 $1.15。这是单个任务上 81% 的成本削减。

这就是热缓存的样子。静态基础只需付费一次,之后就可以免费读取。唯一会被计费的只有动态尾部。
## 基于哈希的缓存的脆弱性
关于提示词缓存,最违反直觉的事情是:
"1 + 2 = 3" 有效,但 "2 + 1" 会导致缓存未命中。
基础设施会从头开始对完整的 token 序列进行哈希计算。如果该序列中有任何内容发生变化,哪怕只是两个元素的顺序,哈希值就会改变,整个前缀就需要以全价重新计算。

这并不是一个微不足道的实现细节。它是 Claude Code 中所有工程决策所围绕的核心约束。
以下是一些在生产环境中破坏缓存的真实例子:
- 系统提示词中注入的时间戳导致每次请求都生成唯一的哈希值。
- 一个 JSON 序列化器在不同请求之间对工具 schema 键的排序不同,导致前缀失效。
- 一个 AgentTool 在会话中途更新了参数,清除了整个 20,000 token 的缓存。
由此得出三条规则:
不要在会话期间修改工具。工具定义是缓存前缀的一部分,因此添加或删除工具会使下游的一切失效。
永远不要在会话中途切换模型。缓存是特定于模型的,这意味着在对话中途切换到更便宜的模型需要从头重建整个缓存。
永远不要通过修改前缀来更新状态。Claude Code 不是编辑系统提示词,而是将提醒标签附加到下一条用户消息中,从而使前缀保持不变。
## 将此应用到你自己的 Agent 中
无论你是使用 Claude Code 还是从零开始构建自己的 Agent,这些规则同样适用。
按以下顺序组织你的提示词:
系统指令和行为规则放在顶部。不要在会话期间更改它们。
预先加载所有工具定义。不要添加或删除它们。
检索到的上下文和参考文档放在接下来。在会话期间保持它们稳定。
对话历史和工具输出放在底部。这是你的动态后缀。

在 Anthropic API 上启用自动缓存后,缓存断点会随着对话的增长自动推进。如果没有启用,你就需要手动跟踪 token 边界,而错误的边界意味着完全错过缓存。
当接近上下文限制时需要进行上下文压缩,请使用缓存安全的分支方法。保持相同的系统提示词、工具和对话历史不变,然后将压缩指令作为新消息追加。缓存前缀得以复用,唯一被计费的新 token 就是压缩指令本身。

要验证缓存是否正常工作,请在每个 API 响应中监控以下三个字段:
- cache_creation_input_tokens 是写入缓存的 token 数。
- cache_read_input_tokens 是从缓存中读取的 token 数。
- input_tokens 是未经缓存处理的 token 数。
你的缓存效率是 cache_read_input_tokens / (cache_read_input_tokens + cache_creation_input_tokens)。像跟踪系统正常运行时间一样跟踪它。
## 关键要点
提示词缓存不是一个可以开启的功能。它是一种你需要围绕其进行设计的架构纪律。
核心思想很简单:组织你的提示词,让静态内容位于顶部,动态内容在底部增长。基础设施对前缀进行哈希计算,存储 KV 张量,并为后续的每次读取提供 90% 的折扣。
但纪律体现在细节中。不要在系统提示词中注入时间戳,不要打乱工具定义,不要在会话中途切换模型,也不要修改缓存断点上游的任何内容。
Claude Code 展示了这在大规模场景下的样子:92% 的缓存命中率以及 81% 的成本降低。如果你在构建 Agent 却没有围绕提示词缓存进行设计,你就把大部分利润空间白白放弃了。
本期到此结束!
如果你喜欢本教程:
关注我 → @_avichawla
我每天都会分享有关数据科学、机器学习、大语言模型和 RAG 的教程与见解。
## 相关链接
- [Avi Chawla](https://x.com/_avichawla)
- [@_avichawla](https://x.com/_avichawla)
- [1.6K](https://x.com/_avichawla/status/2044670188998803855/analytics)
- [@_avichawla](https://x.com/@_avichawla)
- [升级到 Premium](https://x.com/i/premium_sign_up)
- [2026年4月16日 下午2:52](https://x.com/_avichawla/status/2044670188998803855)
- [1,606 次浏览](https://x.com/_avichawla/status/2044670188998803855/analytics)
---
*导出时间: 2026/4/16 16:12:27*