# 5 Agent Design patterns for Long-running AI Agents
**作者**: Google Cloud Tech
**日期**: 2026-04-22T16:30:13.000Z
**来源**: [https://x.com/GoogleCloudTech/status/2046989964077146490](https://x.com/GoogleCloudTech/status/2046989964077146490)
---
Developers spend weeks perfecting prompt engineering, tool calling, and response latency. None of it matters when your agent needs to stay alive for five days.
The workflows that actually matter in production (processing thousands of insurance claims, running week-long sales sequences, reconciling financial data across systems) don't fit inside a single conversation turn. They take days, not seconds.
The moment you try to build these long-running agents, you realize most agent architectures are stateless. They reconstruct context from databases on every interaction. They lose the reasoning chain, the soft signals, and the confidence gradients that made the agent's previous decisions make sense.
At Cloud Next 26, we announced that Agent Runtime now supports long-running agents that maintain state for up to seven days. In this article, we’ll share five essential agent design patterns for building long-running agents with Agent Runtime.
By @addyosmani and @Saboo_Shubham_
Here are five design patterns that separate production systems from demos.
## Pattern 1: Checkpoint-and-Resume
The most common failure mode in multi-day workflows is context loss. An agent processes 200 documents over four hours, then hits an error on document 201. Without checkpointing, you restart from scratch.
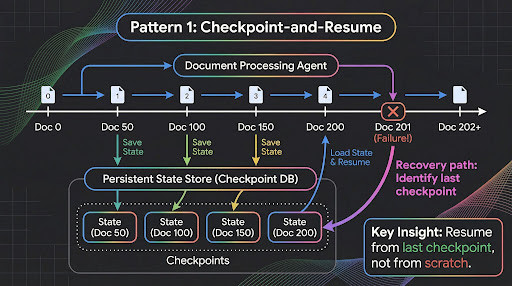
Long-running agents on Agent Runtime maintain persistent execution state in a secure cloud sandbox. The agent has full access to bash commands and a sandboxed file system, so you can write intermediate results to disk, maintain processing logs, and recover from failures.
Treat your agent like a long-running server process, not a request handler. The same way you build a data pipeline that processes millions of records: checkpoint progress, handle partial failures, ensure idempotency.
Here is how you structure a document processing agent that checkpoints after every batch using Google Agent Development Kit:
Notice the checkpoint granularity. Not after every document (wasteful). Not only at the end (risky). Fifty documents per batch balances durability against overhead. Your specific number depends on how expensive each unit of work is.
## Pattern 2: Delegated Approval (Human-in-the-Loop)
Every framework advertises human-in-the-loop.
But in practice, most implementations are: serialize state to JSON, send a webhook, hope someone checks it. The problems compound fast. JSON serialization loses implicit reasoning context. Notifications compete with dozens of alerts.
When the human responds hours later, the agent has to deserialize, re-establish context, and hope nothing changed.
Long-running agents handle this differently. When the agent hits an approval gate, it pauses in place. Full execution state stays intact: reasoning chain, working memory, tool call history, pending action.
Here's what that looks like in practice:
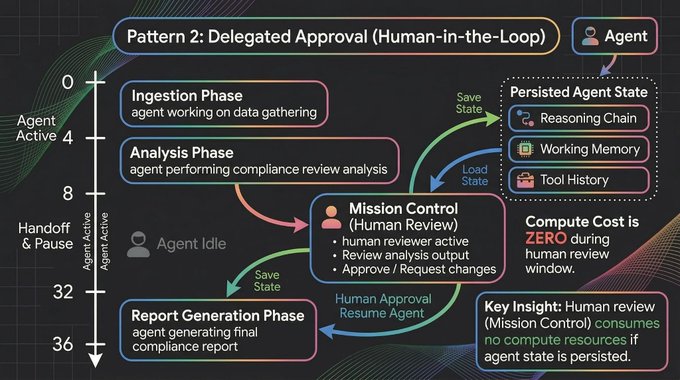
The critical detail: hours 8 through 32 are dead time for the agent but active time for the human. The agent consumes zero compute while paused. Sub-second cold starts mean zero latency penalty when it resumes.
Mission Control provides the inbox that makes this manageable at scale. Notifications categorized into "Needs your input," "Errors," and "Completed." If you're managing twenty long-running agents, you're not hunting through Slack channels to figure out which ones need attention.
## Pattern 3: Memory-Layered Context
A seven-day agent needs more than session state. It needs to remember things from previous sessions, user preferences from weeks ago, and organizational context that no single conversation could contain.
This is where Memory Bank and the new Memory Profiles work together.

Memory Bank (now available for everyone) dynamically generates and curates memories from conversations, organized by topic. Memory Profiles add low-latency access to specific, high-accuracy details. Think of Memory Bank as long-term memory and Memory Profiles as working memory.
But here's the problem most developers don't anticipate until production: memory drift. Your agent's behavior isn't shaped only by its code and prompts. It's shaped by accumulated experience. If an agent "learns" from a few atypical interactions that a procedural shortcut is acceptable, it might start applying that shortcut broadly. And if multiple agents read and write to shared memory pools, data leakage between distinct workflows becomes a real risk.
You can't let agents write to a vector database unchecked. You need to govern them the same way you govern microservices. This is where Agent Identity, Agent Registry, and Agent Gateway come in. They bring standard infrastructure concepts into the agent lifecycle:
Agent Identity works like IAM for agents. Just as a microservice needs a service account, an agent needs a cryptographic identity that determines exactly which memory banks and tools it's authorized to access.
Agent Registry works like service discovery. When you have dozens of long-running agents, you need a centralized way to track which agents are active, what version of the prompt and code they're running, and what their current execution state is.
Agent Gateway works like an API gateway tailored for LLMs. It sits between the agent and its memory and tools, evaluating requests against organizational policies. If an agent tries to commit PII to its long-term Memory Bank, the Gateway blocks the transaction.
Build auditing into your memory layer from day one. The question isn't just "what are my agents doing?" It's "what are my agents remembering, and how is that changing their behavior?"
## Pattern 4: Ambient Processing
Not every long-running agent interacts with humans. Some are ambient. They watch for events, process data streams, and take action in the background without any user prompting.
Batch and Event-Driven Agents connect directly to BigQuery tables and Pub/Sub streams.
Here's a concrete example: a content moderation agent that processes user-generated content as it arrives.
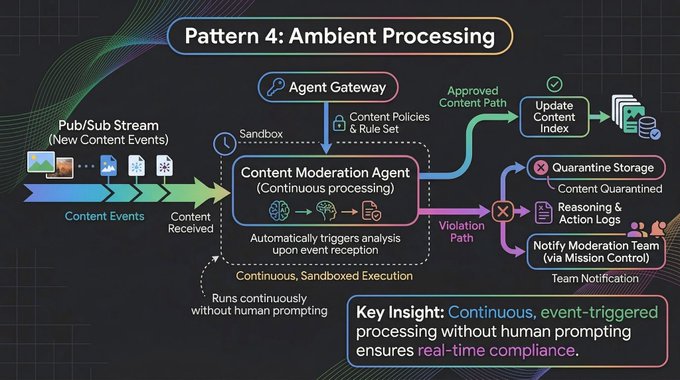
This agent runs for days. It doesn't wait for someone to ask it to moderate content. It processes events as they arrive, maintains its own state about trends and patterns, and escalates only when necessary.
The important architectural decision here ties back to the governance layer from Pattern 3.
Don't hardcode content policies into the agent. Define them in Agent Gateway and the agent enforces them at runtime. When policies change, you update Gateway once and every ambient agent picks up the new rules. The agent's identity (from Agent Identity) determines which policies apply to it, and the Registry tracks which version of the agent is running against which policy set.
This separation matters because ambient agents run unsupervised for long stretches. If you hardcode policies, every policy change requires redeploying every agent. If you externalize policies through the Gateway, you update once and the fleet adapts.
## Pattern 5: Fleet Orchestration
The final pattern is about managing multiple long-running agents as a coordinated fleet. In production, you rarely have a single agent working alone. You have a coordinator agent that delegates sub-tasks to specialist agents, each running independently for different durations.
Consider a sales prospecting sequence:

Each specialist has its own Agent Identity (so it can only access the tools and memory it needs), its own policy enforcement through Agent Gateway (so the Outreach Agent can't access financial data meant for the Scoring Agent), and its own entry in the Agent Registry (so you can track versions and execution state across the fleet).
The coordinator maintains global state and handles handoffs between specialists. This is the same coordinator/worker pattern used in distributed systems for decades. What's new is that ADK handles this natively with graph-based workflows that define coordination logic declaratively.
The operational advantage of treating each specialist as an independent unit is that you can update them independently too.
If your Scoring Agent's ranking logic needs improvement, you can deploy the new version, monitor its performance through Agent Observability, and promote it only when the results hold up. And because each agent runs in its own container (with Bring Your Own Container support for your existing CI/CD and security requirements), a bad deployment in one specialist never cascades to the others.
## Choosing the Right Pattern
These patterns compose. A compliance system might use Checkpoint-and-Resume for document processing, Delegated Approval for review gates, Memory-Layered Context for cross-session knowledge, and Fleet Orchestration to coordinate specialists.
The key question: what is the longest uninterrupted unit of work your agent needs to perform? If it's minutes, you probably don't need long-running agents. If it's hours or days, these patterns are where you start.
## Get started
Long-running agents are available today on Gemini Enterprise Agent Platform. Build with ADK, deploy on Agent Runtime, monitor via Mission Control. The combination of 7-day persistence, human-in-the-loop approvals, and long-term memory is what turns an agent from a chatbot into an autonomous worker.
Start here: https://cloud.google.com/gemini-enterprise/agents
## 🚢 Put These Patterns into Practice: Google for Startups AI Agents Challenge
Don't just read about agent architecture - build it. We’re inviting startups to a 6-week global challenge to build, optimize, or refactor AI agents on the Gemini Enterprise Agent Platform. You'll get $500 in cloud credits, full platform access and a shot at the $90,000 prize pool.
Sign up today to start building!
## 相关链接
- [Google Cloud Tech](https://x.com/GoogleCloudTech)
- [@GoogleCloudTech](https://x.com/GoogleCloudTech)
- [66K](https://x.com/GoogleCloudTech/status/2046989964077146490/analytics)
- [@addyosmani](https://x.com/@addyosmani)
- [@Saboo_Shubham_](https://x.com/@Saboo_Shubham_)
- [https://cloud.google.com/gemini-enterprise/agents](https://cloud.google.com/gemini-enterprise/agents)
- [Sign up today to start building](https://devpost.team/hackathon_guest_invites/4fb181b4-2722-415d-a442-285a57dcaba5?utm_source=twitter&utm_medium=social&utm_campaign=google-for-startups-ai-agents-challenge&utm_content=twitter-post)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [12:30 AM · Apr 23, 2026](https://x.com/GoogleCloudTech/status/2046989964077146490)
- [66.4K Views](https://x.com/GoogleCloudTech/status/2046989964077146490/analytics)
- [View quotes](https://x.com/GoogleCloudTech/status/2046989964077146490/quotes)
---
*导出时间: 2026/4/23 10:44:01*
---
## 中文翻译
# 长时运行 AI 智能体的 5 种设计模式
**作者**: Google Cloud Tech
**日期**: 2026-04-22T16:30:13.000Z
**来源**: [https://x.com/GoogleCloudTech/status/2046989964077146490](https://x.com/GoogleCloudTech/status/2046989964077146490)
---

开发者们花费数周时间打磨提示词工程、工具调用和响应延迟。但当你的智能体需要持续运行五天时,这些全都无济于事。
生产环境中真正重要的工作流(处理数千份保险理赔、运行为期一周的销售序列、跨系统对账财务数据)无法塞进单轮对话中。它们需要的是几天,而不是几秒钟。
当你尝试构建这些长时运行的智能体时,你会发现大多数智能体架构都是无状态的。它们在每次交互时都从数据库重建上下文。它们丢失了推理链、软信号和置信度梯度——正是这些让智能体之前的决策显得合理。
在 Cloud Next 26 大会上,我们宣布 Agent Runtime 现已支持可保持状态长达七天的长时运行智能体。在本文中,我们将分享使用 Agent Runtime 构建长时运行智能体的五种关键设计模式。
作者:@addyosmani 和 @Saboo_Shubham_
以下是五种区分生产系统与演示系统的设计模式。
## 模式 1:检查点与恢复
多天工作流中最常见的故障模式是上下文丢失。智能体在四小时内处理了 200 份文档,然后在第 201 份文档上遇到错误。没有检查点机制,你就得从头开始。

Agent Runtime 上的长时运行智能体在安全的云端沙箱中维护持久化的执行状态。智能体可以完全访问 bash 命令和沙箱文件系统,因此你可以将中间结果写入磁盘、维护处理日志,并从故障中恢复。
把你的智能体当作一个长时运行的服务器进程,而不是一个请求处理器。就像你构建处理数百万条记录的数据管道一样:对进度做检查点、处理部分故障、确保幂等性。
下面展示了如何使用 Google Agent Development Kit 构建一个每批次完成后创建检查点的文档处理智能体:
注意检查点的粒度。不是每份文档之后都做(浪费)。也不是只在最后做(风险大)。每批 50 份文档在持久性与开销之间取得了平衡。具体数字取决于每个工作单元的成本有多高。
## 模式 2:委托审批(人在回路中)
每个框架都在宣传“人在回路中”。
但在实践中,大多数实现是:把状态序列化为 JSON、发送一个 webhook,然后指望有人会去看。问题会迅速叠加。JSON 序列化丢失了隐式的推理上下文。通知与数十条警报相互竞争。
当人类几小时后回复时,智能体必须反序列化、重建上下文,并祈祷期间什么都没变。
长时运行智能体以不同的方式处理这个问题。当智能体遇到审批关卡时,它会原地暂停。完整的执行状态保持不变:推理链、工作记忆、工具调用历史、待执行的操作。
实际效果如下:

关键细节:第 8 到第 32 小时对智能体来说是死时间,但对人类来说是活跃时间。智能体在暂停期间消耗零计算资源。亚秒级冷启动意味着恢复时没有延迟惩罚。
Mission Control 提供了一个收件箱,使得大规模管理变得可行。通知被归类为“需要你的输入”、“错误”和“已完成”。如果你在管理二十个长时运行智能体,你就不必在 Slack 频道中翻找哪些智能体需要关注。
## 模式 3:分层记忆上下文
一个运行七天的智能体需要的不仅仅是会话状态。它需要记住之前会话中的内容、几周前的用户偏好,以及任何单一对话都无法涵盖的组织上下文。
这正是 Memory Bank 与新的 Memory Profiles 协同发挥作用的地方。

Memory Bank(现已向所有人开放)从对话中动态生成和整理记忆,并按主题组织。Memory Profiles 提供对特定、高精度细节的低延迟访问。可以把 Memory Bank 看作长期记忆,把 Memory Profiles 看作工作记忆。
但有一个大多数开发者直到进入生产环境才意识到的问题:记忆漂移。智能体的行为不仅由其代码和提示词塑造,还由积累的经验塑造。如果智能体从几次非典型的交互中“学到”某种流程捷径是可以接受的,它可能会开始广泛套用这个捷径。如果多个智能体读写共享记忆池,不同工作流之间的数据泄露就会成为真实的风险。
你不能放任智能体不受约束地写入向量数据库。你需要像治理微服务那样来治理它们。这正是 Agent Identity、Agent Registry 和 Agent Gateway 发挥作用的地方。它们将标准的基础设施概念引入智能体生命周期:
Agent Identity 就像智能体的 IAM。正如微服务需要服务账号,智能体需要加密身份来确切决定它有权访问哪些记忆库和工具。
Agent Registry 就像服务发现。当你有数十个长时运行智能体时,你需要一个集中的方式来追踪哪些智能体处于活跃状态、它们运行的是哪个版本的提示词和代码,以及它们当前的执行状态如何。
Agent Gateway 就像为 LLM 量身定制的 API 网关。它位于智能体与其记忆和工具之间,根据组织策略评估请求。如果智能体试图将 PII(个人身份信息)提交到其长期 Memory Bank,Gateway 会阻止该事务。
从第一天起就为你的记忆层构建审计机制。问题不仅仅是“我的智能体在做什么?”而是“我的智能体记住了什么,这些记忆如何改变它们的行为?”
## 模式 4:环境式处理
并非每个长时间运行的智能体都需要与人交互。有些智能体是环境式的。它们监视事件、处理数据流,并在后台自主采取行动,无需用户提示。
批处理和事件驱动智能体直接连接 BigQuery 表和 Pub/Sub 流。
举一个具体的例子:一个内容审核智能体,在用户生成内容到达时对其进行处理。

这个智能体可以连续运行数天。它不需要等待某人请求它审核内容。它在事件到达时进行处理,自行维护关于趋势和模式的状态,并且只在必要时才上报。
这里重要的架构决策与模式 3 中的治理层相关联。
不要将内容策略硬编码到智能体中。在 Agent Gateway 中定义它们,智能体在运行时执行它们。当策略发生变化时,你只需更新一次 Gateway,每个环境式智能体都会采用新规则。智能体的身份(来自 Agent Identity)决定了哪些策略适用于它,而 Registry 则追踪哪个版本的智能体在哪个策略集上运行。
这种分离很重要,因为环境式智能体会在无人监督的情况下长时间运行。如果硬编码策略,每次策略变更都需要重新部署每个智能体。如果通过 Gateway 将策略外部化,你只需更新一次,整个机群就会自动适应。
## 模式 5:机群编排
最后一个模式是关于将多个长时间运行的智能体作为一个协调的机群来管理。在生产环境中,你很少会让单个智能体独自工作。你会有一个协调器智能体,它将子任务委派给专家智能体,每个专家智能体独立运行不同的时长。
考虑一个销售线索挖掘流程:

每个专家智能体都有自己的 Agent Identity(因此它只能访问所需的工具和记忆)、通过 Agent Gateway 进行的独立策略执行(因此 Outreach Agent 无法访问本应属于 Scoring Agent 的财务数据),以及在 Agent Registry 中的独立条目(因此你可以追踪整个机群的版本和执行状态)。
协调器维护全局状态并处理专家之间的交接。这与分布式系统中使用数十年的协调器/工作者模式相同。新的地方在于,ADK 原生支持这一点,通过基于图的工作流以声明式方式定义协调逻辑。
将每个专家视为独立单元的运维优势在于,你也可以独立地更新它们。
如果你的 Scoring Agent 的排序逻辑需要改进,你可以部署新版本,通过 Agent Observability 监控其性能,并且只有当结果可靠时才将其提升。而且由于每个智能体都在自己的容器中运行(支持自带容器以满足你现有的 CI/CD 和安全需求),一个专家中的糟糕部署永远不会级联影响其他专家。
## 选择合适的模式
这些模式可以组合使用。一个合规系统可能使用“检查点与恢复”来处理文档,使用“委托审批”作为审核关口,使用“分层记忆上下文”实现跨会话知识,并使用“机群编排”来协调各专家。
关键问题是:你的智能体需要执行的最长不间断工作单元是什么?如果是几分钟,你可能不需要长时间运行的智能体。如果是几小时或几天,这些模式就是你的起点。
## 开始使用
长时间运行的智能体现在已在 Gemini Enterprise Agent Platform 上可用。使用 ADK 构建,部署到 Agent Runtime,通过 Mission Control 监控。7 天持久化、人机协同审批和长期记忆的结合,正是将智能体从聊天机器人转变为自主工作者的关键。
从这里开始:https://cloud.google.com/gemini-enterprise/agents
## 🚢 将这些模式付诸实践:Google for Startups AI Agents 挑战赛
不要只阅读智能体架构——去构建它。我们邀请初创公司参加为期 6 周的全球挑战赛,在 Gemini Enterprise Agent Platform 上构建、优化或重构 AI 智能体。你将获得 500 美元的云积分、完整的平台访问权限,并有机会争夺 90,000 美元的奖金池。
立即注册开始构建!
## 相关链接
- [Google Cloud Tech](https://x.com/GoogleCloudTech)
- [@GoogleCloudTech](https://x.com/GoogleCloudTech)
- [66K](https://x.com/GoogleCloudTech/status/2046989964077146490/analytics)
- [@addyosmani](https://x.com/@addyosmani)
- [@Saboo_Shubham_](https://x.com/@Saboo_Shubham_)
- [https://cloud.google.com/gemini-enterprise/agents](https://cloud.google.com/gemini-enterprise/agents)
- [立即注册开始构建](https://devpost.team/hackathon_guest_invites/4fb181b4-2722-415d-a442-285a57dcaba5?utm_source=twitter&utm_medium=social&utm_campaign=google-for-startups-ai-agents-challenge&utm_content=twitter-post)
- [升级到 Premium](https://x.com/i/premium_sign_up)
- [2026年4月23日 12:30 AM](https://x.com/GoogleCloudTech/status/2046989964077146490)
- [66.4K 次浏览](https://x.com/GoogleCloudTech/status/2046989964077146490/analytics)
- [查看引用](https://x.com/GoogleCloudTech/status/2046989964077146490/quotes)
---
*导出时间: 2026/4/23 10:44:01*