# Multi-Agents: What's Actually Working
**作者**: Walden
**日期**: 2026-04-22T20:46:16.000Z
**来源**: [https://x.com/walden_yan/status/2047054401341370639](https://x.com/walden_yan/status/2047054401341370639)
---

10 months ago, I wrote Don't Build Multi-Agents, arguing that most people shouldn't try to build multi-agent systems [1]. Parallel agents make implicit choices about style, edge cases, and code patterns. At the time, these decisions often conflicted with each other, leading to fragile products. A lot has changed since then.
At Cognition, we've begun to deploy multi-agent systems that actually work in practice. Our original observations still hold today for parallel-writer swarms: most of the sexy ideas in that space still don’t see meaningful adoption. But we've found a narrower class of patterns that do: setups where multiple agents contribute intelligence to a task while writes stay single-threaded. In this post, I'll summarize what we've learned building them.
A Refresher on Context Engineering
In the last post, we encouraged readers to reframe agent-building from “prompt engineering” to “context engineering”. Prompt engineering encourages gimmicky techniques like “you’re a senior software engineer” or “think for longer.” Context engineering is more durable and focuses on giving the right context to models while assuming the models become more capable over time. For many reasons, context engineering can get very challenging in a multi-agent setup. In the past, we recommended the following principles:
Share as much context as possible between the agents. Make sure they see the same sources of information, stay on the same page (todo list, plan files), and share the same priors about the overall task they are meant to accomplish. Help them communicate if needed
Actions carry implicit decisions. When one agent makes certain changes or edits, it might make implicit choices (style, code patterns, how certain edge cases should be handled) that might conflict with the implicit choices of other parallel agents. As a result, decision-making can get quite fragmented in a multi-agent world where multiple agents are taking write actions.
Though many things have changed in the last few months, the need for thoughtful context engineering has not. As a consequence of principle 2, most multi-agent setups in the world are limited to “readonly” subagents, like web search subagents and code search subagents. For example, Devin can call out to a Deepwiki subagent to acquire codebase context. But these types of subagents mostly resemble tool calls rather than true multi-agent collaboration. We wanted to explore what capabilities we can unlock when agents collaborate in a more interactive way.
What Changed in the Last 10 Months
To start, models have become way more naturally “agentic.” They intuitively understand tool use, their own context limits, and how to distill their context for collaborators (human or otherwise). As a result, usage of agents has grown … a shit ton. Even when we look at Devin usage in our largest enterprises segment, the segment that has traditionally been cautious toward adopting new technologies, we see an explosion over the last 6 months (~8x).

This explosion of usage has led to both a push and a pull to multi-agents.
On the push side of things, the increased capabilities have led users to naturally experiment with many more multi-agent setups. When you are using so many agents, you naturally start to become bottlenecked on everything around those agents: the management, planning, and reviewing. For instance, some have created scripts for Devins to manage other Devins. Many have also leaned into having their coding agents iterate back and forth with their review agents.
On the pull side of things, the explosion of agent usage has resulted in an explosion of costs. With a new Mythos class of even larger & more capable models on the horizon, the natural question of how one can achieve frontier capabilities at a lower cost arises. And multi-agent systems may be a natural answer.
There's also been a wave of sensational demos of throwing tons of agents at large engineering projects. Notable examples include building a web browser (200k LOC), building a C compiler (100k LOC), and optimizing an LLM training script (10k+ iterations). These are exciting but they all share a property most real software doesn't: a simple, verifiable success criterion. Real software requires a system that scales human taste and decision-making, which is the context in which we set out to explore multi-agent systems.
## Some Practical Multi-agent Experiments
1) The Code-Review-Loop that’s so stupid it shouldn’t work
You would think that making a model review its own code would not result in any useful findings. But even on PRs written by Devin, Devin Review catches an average of 2 bugs per PR, of which roughly 58% are severe (logic errors, missing edge cases, security vulnerabilities). Often the system will loop through multiple code-review cycles, finding new bugs each time (which isn't always great since it can take a while). Today, we make Devin and Devin Review natively iterate against one another, so that most bugs are already resolved by the time a human opens the PR.
The counterintuitive part. Interestingly, we found this technique to work best when the coding and review agents do not share any context beforehand. Why?
There’s a mix of philosophical and technical justifications for this. To start, we must remember that putting the same model in two agents, even if the agent harness is exactly the same, does not quite make them self-biased/correlated in the same way you might imagine one human doing both tasks would be. These agents are ultimately systems that perform based on their context. They don’t have egos, and any shared bias that might exist ultimately comes from their training process, which nowadays we can assume is quite high-quality.
The review agent having a completely clean context also helps it go deeper into areas the original coding agent may not. For one, this is because it is forced to reason backward from the implementation without the spec, and can openly question things which the original agent might have overlooked due to errors in user instruction (ex. a user telling the agent to implement an insecure pattern). Perhaps more importantly though, having a clean context makes the agent smarter because of the math of attention. Context Rot is a well-documented phenomenon that is a result of models making less intelligent decisions at longer and longer context lengths. Models usually have a limited number of attention heads, and when they need to work on a growing context of instructions, prompts, code, etc, important details may not be fully incorporated into its decision-making. When the coding agent has been working for hours on a task, reading through the repo, running commands, thinking about different approaches, fixing errors, it quickly builds up a large context. The dedicated review agent gets to skip this extraneous context, only look at the diff, and re-discover any context it needs as it reads the code from scratch. With a shorter context, the improved intelligence naturally leads to increased detection of nuanced issues.
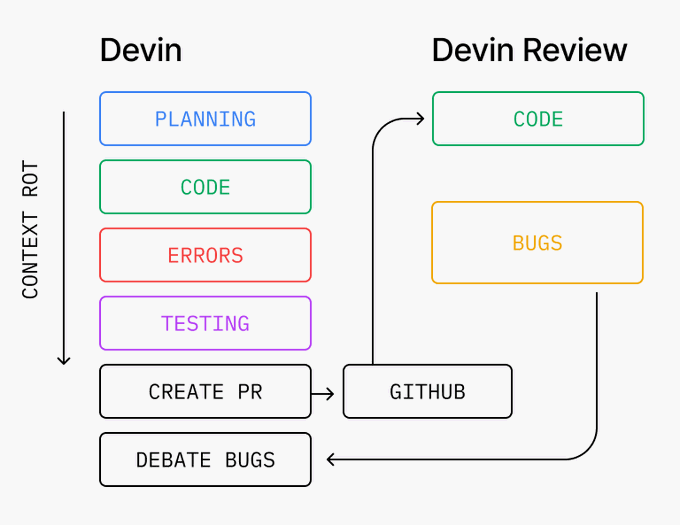
The final key part to making this system work really well is the communication bridge between the coding agent and review agent. Basically, does Devin properly use its broader context of user instructions, decisions, etc. to filter the bugs that come back from Devin Review? This is key to preventing looping, disobeying the user, doing work that is out of scope, and so on. We found that with some dedicated prompting, models today can make reasonable judgment calls here, and you end up getting some very interesting interactions between the two agents and humans.
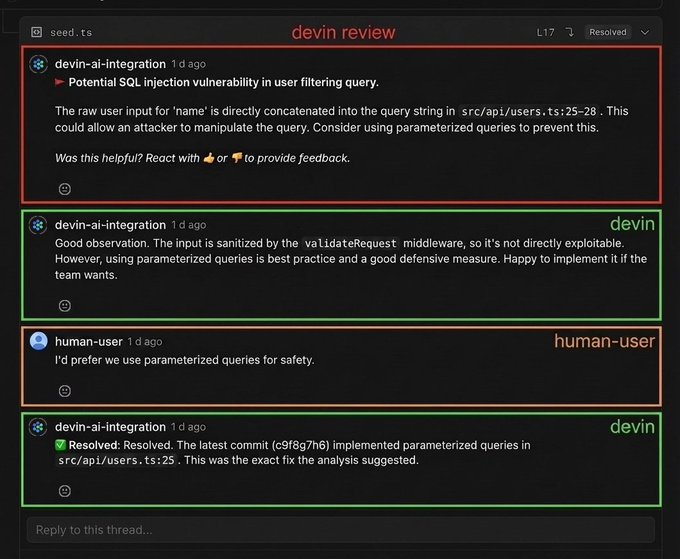
> Takeaways: clean context leads to a notable improvement in capabilities when using a generator-verifier loop. But clear communication and synthesis with the overall context is important for a cohesive experience.
2) Large, expensive models are back - introducing “Smart Friend”
If you look at the most popular models over the last few months, you see a distinct shift from mid-sized models like Anthropic’s Sonnet-class models to large models like Anthropic’s Opus-class models for the sake of performance. And with Mythos coming, we can basically say “scaling is back”
The quiet implication of this is that frontier intelligence will soon be too expensive (and perhaps slow) for most day-to-day tasks. At the same time, you face a dilemma with smaller models that a task might prove more difficult than originally expected.
How can we get the best of both worlds? In Windsurf, we tried an experiment with this goal when we launched SWE-1.5 in October, a 950 tok/sec sub-frontier model. We found that when paired with Sonnet 4.5 for “planning”, we were able to make up for a small bit of the performance gap while keeping the low cost and fast speeds.
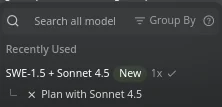
The actual architecture we used to achieve this was by offering the smarter/expansive model as a “smart friend” tool that the primary/smaller model could make a call out to. Basically, let the primary/smaller model decide when a situation was tricky enough to be worth consulting the smarter/expensive model. But we soon found that engineering the context transfer and communication was tricky:
1. The primary model needs to know how to talk to smart friend.
The core trickiness of this setup comes from the problem of “how does a dumber model know it’s at its limits?” Unlike the more popular inverted setup with a smart primary model delegating tasks to smaller subagents, the model deciding when to delegate isn’t the smarter one. There’s a few potential solutions here. For one, you might encourage the primary agent to always make at least one call to the smart agent to evaluate whether it thinks there is some trickiness that was missed. You might also prompt-tune or train the primary model to be more calibrated on this decision. Depending on the intelligence of the primary model, certain kinds of domain-specific prescriptive guidance may be necessary, such as always invoking the smart friend for merge conflicts.
The other tricky question with this communication method is what context should the primary model share with the smart friend? Moreover, what should the primary model ask the smart friend? If the primary model only shares a subset of its total context, then the smart model might not make a fully-informed decision. We found that for today’s models, a reasonable 80/20 solution is to just share a fork of the full context of the primary model with the smart model. Similarly, we found that encouraging the primary model to ask broad questions (”what should I do?”) and letting the smart model decide what is interesting to discuss is better.
2. The smart friend needs to know how to talk back to the primary model
No matter how well you tune (1) you will likely find there are still gaps in quality due to context loss. Tuning the communication in the other direction can make up for these gaps. For instance, suppose the primary model never looked at important_file.py and asked the smart model about something that requires knowledge of the contents of this file. In this case, the right answer from the smart model is not to make up some theories (which is often the default behavior), but to specifically instruct the primary model to investigate this file and ask again later. Similarly, it’s often also fruitful to ask the smart friend to look beyond the question the primary model is asking, and suggest any important guidance based on the agent trajectory, even if the primary model didn’t ask for it. We’ve found this “over-scoped” smart friend to generally lead to more interesting interactions.
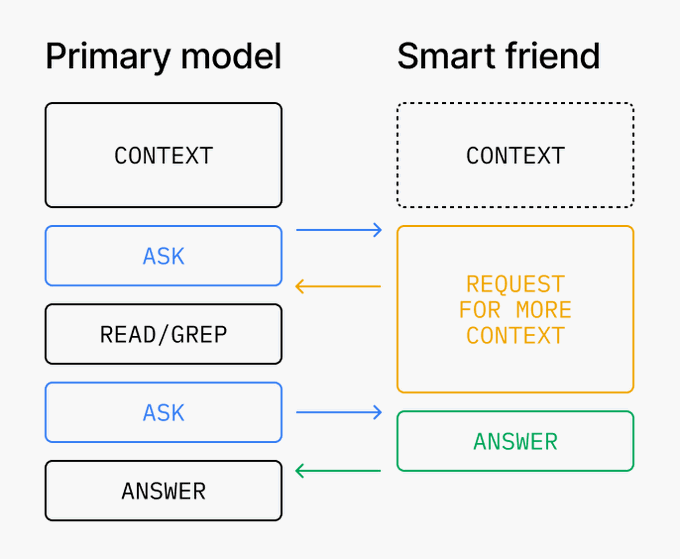
What Actually Happened with Smart Friend
We should be upfront: SWE 1.5 was not good enough at being the primary model for this setup to really work. The gap between it and Sonnet 4.5 was too wide in exactly the places that mattered for this setup: knowing when to escalate, knowing what to ask. The cost and speed wins were real, but the quality ceiling was set by the primary, and the primary wasn't strong enough. SWE 1.6 (a recent followup achieving Opus-4.5 level performance on SWE-bench) is meaningfully better and closes enough of that gap that the pattern starts to pay off, but it's still not where we want it. We're reasonably confident this is a training problem, and future SWE models will be trained with this back-and-forth in mind [2].
Where the pattern did work, and worked well, was across frontier models. We’ve run Claude and GPT together in this setup in production for a meaningful stretch, and it produced real gains in the trickiest scenarios. The interesting finding is that the prompt-tuning problems are different from the small-model-to-large-model case. Cross-frontier communication is less about a weaker model knowing when to ask a stronger one, and more about routing to whichever model is best at the specific sub-task. Some models debug better, some handle visual reasoning better, some write tests better. The delegation logic becomes a capability router rather than a difficulty escalator.
> Takeaways: smart-friend works today when both models are strong. Getting it to work with an asymmetrically weaker primary, which is the version that leads to the biggest unlocks, is still an open problem, and we think it's a training one. Reach out if you want to compare notes.
## Looking Ahead: Higher-Level Delegation
The two patterns above share a structure: one writer, augmented by other agents contributing intelligence around it. The obvious next question is whether this extends to agents owning larger scope, for example, a product feature that spans ten PRs, a migration that touches a dozen services, a week of work rather than an afternoon's.
This is live in Devin today. A manager Devin can break a larger task into pieces, spawn child Devins to work on them, and coordinate their progress through an internal MCP. Getting it to feel coherent took more context engineering than we expected. Managers trained on small-scoped delegation default to being overly prescriptive, which backfires when the manager lacks deep codebase context. Agents assume they share state with their children when they don't. Cross-agent communication, a sub-agent writing messages back to its manager to be passed to other agents in the agent team, doesn't happen by default, because models haven't been trained in environments where it needed to. Each of these took dedicated work to fix, and we're still improving on all of them.
What about unstructured swarms? We think the unstructured-swarm approach, arbitrary networks of agents negotiating with each other, is mostly a distraction. The practical shape is map-reduce-and-manage: a manager splits work, children execute, the manager synthesizes and reports back. Making this type of system feel as coherent as a single agent working on a single task is at the center of some of our upcoming work in 2026.
What We Know Today
There’s a shared through-line with all of these experiments: multi-agent systems work best today when writes stay single-threaded and the additional agents contribute intelligence rather than actions. A clean-context reviewer catches bugs the coder can't see. A frontier-level smart friend catches subtleties a weaker primary misses. A manager coordinates scope across child agents without fragmenting decisions.
The open problems are all communication problems. How does a weaker model learn when to escalate? How does a child agent surface a discovery that should change its siblings' work? How do you transfer context between agents without drowning the receiver? You can get decently far with prompting, but we also expect the next generation of models, including the ones we train ourselves, to start closing these gaps.
We're building toward a world where intelligence is injected at every stage of the software development lifecycle — planning, coding, review, testing, and monitoring — not as a swarm of autonomous actors, but as a coordinated system that scales human taste.
We welcome you to try our work at devin.ai or windsurf.com. And if you would enjoy discovering some of these agent-building principles with us, reach out to walden@cognition.ai
[1] Coincidentally, Anthropic came out the next day with a related blogpost about building a multi-agent research system. Both blogposts touched on similar challenges with context engineering and came to similar conclusions about the first area of applicability being in readonly agents
[2] Recently, Anthropic launched a similar beta experiment to let their smaller models make calls out to their larger models in the same fashion. At a minimum, this suggest the models on the “smart friend” end will also get better at communicating back with the primary model.
## 相关链接
- [Walden](https://x.com/walden_yan)
- [@walden_yan](https://x.com/walden_yan)
- [158K](https://x.com/walden_yan/status/2047054401341370639/analytics)
- [Don't Build Multi-Agents](https://cognition.ai/blog/dont-build-multi-agents)
- [Deepwiki](http://deepwiki.com/)
- [Mythos class](https://www-cdn.anthropic.com/08ab9158070959f88f296514c21b7facce6f52bc.pdf)
- [building a web browser](https://cursor.com/blog/scaling-agents)
- [building a C compiler](https://www.anthropic.com/engineering/building-c-compiler)
- [optimizing an LLM training script](https://github.com/karpathy/autoresearch)
- [Context Rot](https://www.trychroma.com/research/context-rot)
- [launched SWE-1.5](https://cognition.ai/blog/swe-1-5)
- [recent followup](https://cognition.ai/blog/swe-1-6)
- [devin.ai](http://app.devin.ai/)
- [windsurf.com](http://windsurf.com/)
- [walden@cognition.ai](mailto:walden@cognition.ai)
- [came out the next day](https://www.anthropic.com/engineering/multi-agent-research-system)
- [launched a similar beta experiment](https://claude.com/blog/the-advisor-strategy)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [4:46 AM · Apr 23, 2026](https://x.com/walden_yan/status/2047054401341370639)
- [158.5K Views](https://x.com/walden_yan/status/2047054401341370639/analytics)
- [View quotes](https://x.com/walden_yan/status/2047054401341370639/quotes)
---
*导出时间: 2026/4/23 11:37:10*
---
## 中文翻译
# 多智能体:什么才是真正有效的
**作者**: Walden
**日期**: 2026-04-22T20:46:16.000Z
**来源**: [https://x.com/walden_yan/status/2047054401341370639](https://x.com/walden_yan/status/2047054401341370639)
---

10 个月前,我写过一篇《不要构建多智能体》(Don't Build Multi-Agents),主张大多数人不应尝试构建多智能体系统 [1]。并行的智能体会对风格、边缘情况和代码模式做出隐式选择。在当时,这些决定经常相互冲突,导致产品脆弱不堪。而从那以后,很多东西都变了。
在 Cognition,我们已经开始部署在实践中真正有效的多智能体系统。我们当初的观察对于“并行写入者集群”来说至今依然成立:那个领域里大多数光鲜亮丽的想法仍然没有获得实质性的采用。但我们找到了一类更窄的、确实有效的模式:多个智能体为一个任务贡献智能,而写入操作保持单线程的模式。在这篇文章中,我将总结我们在构建这些系统过程中学到的东西。
## 上下文工程回顾
在上一篇文章中,我们鼓励读者把构建智能体的思路从“提示词工程”转变为“上下文工程”。提示词工程鼓励一些花哨的技巧,比如“你是一位资深软件工程师”或“再多思考一会儿”。上下文工程则更加持久,其重点是为模型提供正确的上下文,同时假定模型会随着时间推移变得更强大。出于诸多原因,在多智能体环境下,上下文工程可能变得极具挑战性。过去,我们推荐过以下原则:
在智能体之间尽可能多地共享上下文。确保它们看到相同的信息来源,保持同步(待办事项列表、计划文件),并对它们要完成的整体任务持有相同的先验认知。如有需要,帮助它们相互沟通。
行动承载着隐式的决策。当一个智能体做出某些更改或编辑时,它可能会做出隐式的选择(风格、代码模式、某些边缘情况应如何处理),而这些选择可能与其他并行智能体的隐式选择相冲突。其结果是,在多个智能体都在执行写操作的多智能体世界中,决策可能会变得相当碎片化。
尽管过去几个月很多事情都变了,但对深思熟虑的上下文工程的需求并没有变。作为原则 2 的推论,世界上大多数多智能体架构都被限制在“只读”子智能体的范围内,比如网页搜索子智能体和代码搜索子智能体。例如,Devin 可以调用一个 Deepwiki 子智能体来获取代码库上下文。但这类子智能体更像工具调用,而不是真正的多智能体协作。我们想探索的是:当智能体以更具交互性的方式协作时,我们能解锁哪些能力。
## 过去 10 个月发生了什么变化
首先,模型变得更加自然地具备“智能体属性”了。它们能直观地理解工具的使用、自身的上下文限制,以及如何为自己的协作者(无论是人类还是其他)提炼上下文。因此,智能体的使用量增长……非常非常多。即便看 Devin 在我们最大型企业客户群体(传统上对采用新技术较为谨慎的群体)中的使用情况,过去 6 个月我们也看到了爆炸式增长(约 8 倍)。

这种使用量的爆炸式增长,既推动也牵引着多智能体的发展。
从推动的一面来看,模型能力的提升让用户自然而然地试验更多的多智能体架构。当你同时使用如此多的智能体时,你自然会开始在这些智能体周边的各个环节上遇到瓶颈:管理、规划和审查。例如,有人编写了让 Devin 管理 other Devin 的脚本。也有很多人让他们的编码智能体与审查智能体来回迭代。
从牵引的一面来看,智能体使用量的爆炸带来了成本的爆炸。随着一个新的、规模更大、能力更强的“神话级”(Mythos class)模型即将到来,一个自然而然的问题浮现出来:如何以更低的成本获得前沿能力?而多智能体系统可能是一个天然的答案。
此外,还出现了一波把海量智能体投入大型工程项目的轰动性演示。著名的例子包括构建一个网页浏览器(20 万行代码)、构建一个 C 编译器(10 万行代码),以及优化一个 LLM 训练脚本(迭代 1 万次以上)。这些都很令人兴奋,但它们都具备一个大多数真实软件所不具备的特性:简单且可验证的成功标准。真实的软件需要一个能够放大人类品味和决策的系统,而这正是我们着手探索多智能体系统时的背景。
## 一些实用的多智能体实验
1) 简单到不该有效的“编码-审查循环”
你会以为让一个模型审查自己写的代码不会产生任何有用的发现。但即使针对 Devin 自己写的 PR,Devin Review 平均每个 PR 也能捕获 2 个 bug,其中约 58% 属于严重问题(逻辑错误、遗漏的边缘情况、安全漏洞)。这个系统通常会经历多轮代码审查循环,每轮都能发现新的 bug(这并不总是好事,因为可能耗时较久)。如今,我们让 Devin 和 Devin Review 原生地相互迭代,这样在人类打开 PR 之前,大多数 bug 就已经被解决了。
反直觉之处在于:有趣的是,我们发现当编码智能体和审查智能体事先不共享任何上下文时,这项技术的效果最好。为什么?
这背后既有哲学层面的理由,也有技术层面的理由。首先,我们必须认识到,把同一个模型放入两个 agent 中,即使 agent 的运行框架完全相同,它们产生自我偏见/相关性的方式,也并不像你想象中同一个人做两项任务时那样。这些 agent 本质上是基于其上下文来执行任务的系统。它们没有自我意识,任何可能存在的共同偏见最终都来自其训练过程,而如今我们可以认为这一过程的质量是相当高的。
评审 agent 拥有完全干净的上下文,也帮助它深入到原始编码 agent 可能无法触及的领域。一方面,这是因为它被迫在没有规格说明的情况下从实现反向推理,可以公开质疑原始 agent 可能因用户指令中的错误而忽略的问题(例如,用户指示 agent 实现一个不安全的模式)。但也许更重要的是,干净的上下文能让 agent 变得更聪明,这是由注意力的数学原理决定的。上下文腐化是一个有充分记录的现象,其结果是模型在越来越长的上下文长度下做出不够智能的决策。模型的注意力头数量通常是有限的,当它们需要在不断增长的上下文中处理指令、提示词、代码等内容时,重要细节可能无法完全纳入其决策过程。当编码 agent 已经在一个任务上工作了数小时——阅读仓库、运行命令、思考不同的方法、修复错误——它会迅速积累起庞大的上下文。而专职的评审 agent 则可以跳过这些无关的上下文,只查看 diff,并在从头阅读代码的过程中按需重新发现所需的任何上下文。上下文更短,智能水平的提升自然会带来对细微问题的更多检出。

让这个系统真正高效运作的最后一个关键部分,是编码 agent 与评审 agent 之间的沟通桥梁。基本上,就是 Devin 是否能正确利用其更广泛的上下文——用户指令、决策等——来过滤 Devin Review 返回的 bug。这是防止循环、违背用户意愿、执行超出范围的工作等问题的关键。我们发现,通过一些专门的提示词设计,如今的模型可以在这里做出合理的判断,你会看到两个 agent 与人类之间出现一些非常有趣的互动。

> 要点:在使用生成-验证循环时,干净的上下文能带来显著的能力提升。但与整体上下文进行清晰的沟通和整合,对于连贯的体验同样至关重要。
2) 大型、昂贵的模型回归——引入“聪明朋友”模式
如果观察过去几个月最受欢迎的模型,你会发现一个明显的转变:为了追求性能,从中等规模的模型(如 Anthropic 的 Sonnet 级别)转向了大型模型(如 Anthropic 的 Opus 级别)。随着 Mythos 的到来,我们基本上可以说“扩展定律回归了”。
这一趋势隐含的悄然含义是,前沿智能很快就会变得过于昂贵(也许还太慢),不适合大多数日常任务。与此同时,你还会面临一个两难境地:使用较小的模型时,某个任务可能比最初预期的要困难。
如何才能两全其美?在 Windsurf,我们在 10 月发布 SWE-1.5 时针对这一目标做了一次实验,SWE-1.5 是一个 950 tok/sec 的次前沿模型。我们发现,当它与 Sonnet 4.5 配合进行“规划”时,我们能够弥补一小部分性能差距,同时保持低成本和高速。

我们实现这一目标的实际架构,是将更聪明/更昂贵的模型作为“聪明朋友”工具提供,供主模型/较小模型调用。基本上,就是让主模型/较小模型自行判断某个情况是否足够棘手、值得咨询更聪明/更昂贵的模型。但我们很快发现,工程化地处理上下文传递和沟通相当棘手:
1. 主模型需要知道如何与聪明朋友沟通。
这一设置的核心难点在于“一个较笨的模型如何知道自己已达到极限?”与更常见的反向设置(聪明的主模型将任务委派给较小的子 agent)不同,这里决定何时委派的模型并不是更聪明的那个。这里有几种潜在的解决方案。其一,你可以鼓励主 agent 至少调用一次聪明 agent,以评估是否存在被遗漏的棘手问题。你也可以通过提示词调优或训练,使主模型在这类决策上更有校准度。根据主模型的智能水平,可能还需要某些特定领域的规范性指导,例如在合并冲突时总是调用聪明朋友。
这种沟通方式的另一个棘手问题是:主模型应该与聪明朋友共享哪些上下文?更进一步,主模型应该向聪明朋友问什么?如果主模型只共享其全部上下文的一个子集,那么聪明模型可能无法做出完全知情的决策。我们发现,对于当今的模型,一个合理的 80/20 解决方案是直接将主模型的完整上下文分叉共享给聪明模型。同样地,我们发现鼓励主模型提出宽泛的问题(“我该怎么做?”),并让聪明模型自行决定哪些内容值得讨论,效果更好。
2. 聪明朋友需要知道如何回应主模型
无论你把 (1) 调得多好,你仍然可能发现由于上下文丢失而存在质量上的差距。反方向调整沟通方式可以弥补这些差距。例如,假设主模型从未查看过 important_file.py,却就某个需要了解该文件内容的问题询问聪明的模型。在这种情况下,聪明模型的正确回答不是编造一些理论(这往往是默认行为),而是明确指示主模型去调查这个文件,稍后再来询问。同样,让聪明朋友跳出主模型所提出的问题,基于智能体的执行轨迹提出任何重要的建议,即使主模型并没有要求,通常也是富有成效的。我们发现这种“范围过大”的聪明朋友通常会带来更有趣的互动。

聪明朋友实际发生了什么
我们应该坦诚地说:SWE 1.5 作为主模型还不够好,无法让这一架构真正奏效。它和 Sonnet 4.5 之间的差距,恰恰在这个架构最关键的环节上过于悬殊:知道何时升级,知道该问什么。成本和速度上的优势是真实的,但质量上限由主模型决定,而主模型不够强大。SWE 1.6(最近的后续版本,在 SWE-bench 上达到了 Opus-4.5 级别的性能)明显更好,缩小了足够多的差距,使这一模式开始产生回报,但仍然没有达到我们期望的水平。我们相当有信心这是一个训练问题,未来的 SWE 模型会在训练时把这种来回互动考虑在内 [2]。
这一模式确实奏效且效果良好的,是在前沿模型之间。我们在生产环境中让 Claude 和 GPT 在这一架构下共同运行了相当长的一段时间,在最棘手的场景中产生了实际的收益。有趣的发现是,这里的提示词调优问题不同于小模型到大模型的情形。跨前沿模型的沟通,不在于较弱的模型知道何时去请教更强的模型,而在于把任务路由到在特定子任务上最擅长的模型。有些模型调试能力更强,有些更擅长视觉推理,有些更擅长编写测试。委派逻辑变成了能力路由器,而不是难度升级器。
> 要点:当两个模型都很强时,聪明朋友模式在今天就能发挥作用。让它与一个明显更弱的主模型配合工作——这才是能带来最大解锁的版本——仍然是一个悬而未决的问题,而且我们认为这是一个训练问题。如果你想交流心得,欢迎联系我们。
## 展望未来:更高级别的委派
上述两种模式共享一个结构:一个执行写入的智能体,由其他智能体在其周围贡献智能来增强。显而易见的下一个问题是,这是否能扩展到拥有更大职责范围的智能体,例如一个跨越十个 PR 的产品功能、一个涉及十几个服务的迁移、一周的工作量而非一个下午的。
这在今天的 Devin 中已经上线了。一个管理者 Devin 可以把较大的任务拆分成若干部分,派生子 Devin 去处理它们,并通过内部 MCP 协调它们的进度。让它感觉连贯一致,所需做的上下文工程超出了我们的预期。在小范围委派上训练出的管理者,默认会过于事无巨细地发号施令,而当管理者缺乏对代码库的深入理解时,这会适得其反。智能体会误以为自己与子智能体共享状态,而实际上并没有。跨智能体沟通——子智能体把消息写回其管理者以便传递给智能体团队中的其他智能体——默认不会发生,因为模型从未在需要这种能力的环境中接受过训练。每一个问题都需要专门的工作来修复,而我们仍在持续改进。
那么非结构化的蜂群呢?我们认为非结构化蜂群的方法——任意智能体之间相互协商的网络——大多是一种干扰。实际可行的形态是“映射-归约-管理”:管理者拆分工作,子智能体执行,管理者进行综合并汇报。让这类系统感觉像单个智能体处理单个任务那样连贯一致,是我们 2026 年即将开展的工作的核心之一。
我们今天所知道的
所有这些实验都有一个共同的主线:当今多智能体系统运作最好的方式,是让写入保持单线程,而额外的智能体贡献的是智能而非动作。一个拥有干净上下文的审查者能发现编码者看不到的 bug。一个前沿水平的聪明朋友能捕捉到较弱的主模型遗漏的微妙之处。一个管理者能在子智能体之间协调工作范围而不碎片化决策。
尚未解决的问题都是沟通问题。较弱的模型如何学会何时升级?子智能体如何提出一个应该改变其兄弟智能体工作的发现?如何在智能体之间传递上下文而不把接收方淹没?通过提示词你可以走得相当远,但我们也期待下一代模型,包括我们自己训练的模型,能够开始弥合这些差距。
我们正在构建这样一个世界:在软件开发生命周期的每个阶段——规划、编码、审查、测试和监控——都注入智能,不是作为一群自主行动者,而是作为一个扩展人类品味的协调系统。
欢迎你在 devin.ai 或 windsurf.com 体验我们的工作。如果你也乐于与我们一同探索这些构建智能体的原则,请联系 walden@cognition.ai
[1] 巧合的是,Anthropic 在第二天发布了一篇关于构建多智能体研究系统的相关博文。两篇博文都涉及了上下文工程的类似挑战,并就得出的第一个适用领域是只读智能体这一点得出了相似的结论。
[2] 最近,Anthropic 也启动了一个类似的 beta 实验,让他们的小模型以同样的方式调用大模型。至少这说明,“聪明朋友”端的模型在向主模型回传信息方面也会做得越来越好。
## 相关链接
- [Walden](https://x.com/walden_yan)
- [@walden_yan](https://x.com/walden_yan)
- [158K](https://x.com/walden_yan/status/2047054401341370639/analytics)
- [不要构建多智能体系统](https://cognition.ai/blog/dont-build-multi-agents)
- [Deepwiki](http://deepwiki.com/)
- [Mythos class](https://www-cdn.anthropic.com/08ab9158070959f88f296514c21b7facce6f52bc.pdf)
- [构建网页浏览器](https://cursor.com/blog/scaling-agents)
- [构建 C 编译器](https://www.anthropic.com/engineering/building-c-compiler)
- [优化 LLM 训练脚本](https://github.com/karpathy/autoresearch)
- [Context Rot](https://www.trychroma.com/research/context-rot)
- [发布 SWE-1.5](https://cognition.ai/blog/swe-1-5)
- [最近的后续文章](https://cognition.ai/blog/swe-1-6)
- [devin.ai](http://app.devin.ai/)
- [windsurf.com](http://windsurf.com/)
- [walden@cognition.ai](mailto:walden@cognition.ai)
- [第二天发布](https://www.anthropic.com/engineering/multi-agent-research-system)
- [启动了类似的 beta 实验](https://claude.com/blog/the-advisor-strategy)
- [升级到 Premium](https://x.com/i/premium_sign_up)
- [4:46 AM · 2026年4月23日](https://x.com/walden_yan/status/2047054401341370639)
- [158.5K 次浏览](https://x.com/walden_yan/status/2047054401341370639/analytics)
- [查看引用](https://x.com/walden_yan/status/2047054401341370639/quotes)
---
*导出时间: 2026/4/23 11:37:10*