# Own the Outer Loop
**作者**: Addy Osmani
**日期**: 2026-07-08T18:44:08.000Z
**来源**: [https://x.com/addyosmani/status/2074927530482835916](https://x.com/addyosmani/status/2074927530482835916)
---
In the past year, the conversation around agentic engineering has moved to harnesses and loops, fleets and software factories. My 2c is engineers need to own the outer loop - the accountability for these systems. This only gets more true as powerful models like Fable and GPT-5.6 become available.
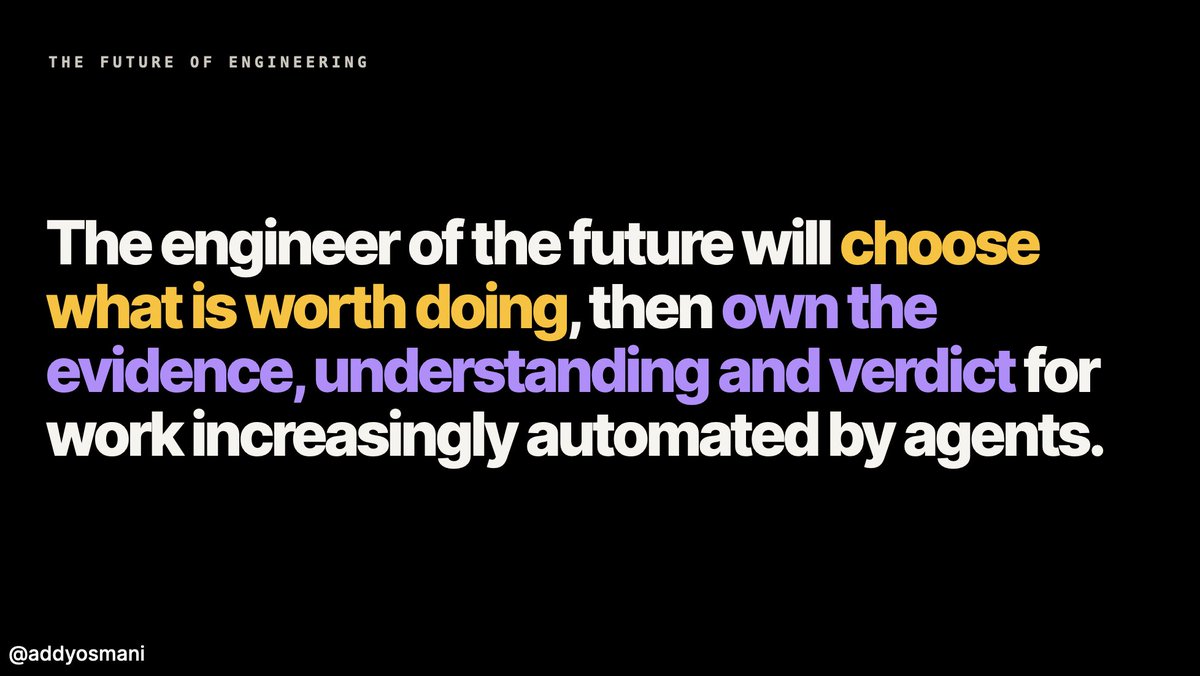
Agents have leverage, and leverage creates obligations. Someone must be able to explain exactly what changed, why it was safe, and what will happen if they're wrong. Otherwise, their actions can't be justified. Which makes it unlikely their organization will ask for them in the first place.
And so I want to talk about three terms. The first, Quality, refers to all the checks we install before we let the system loose. Those checks produce evidence, and from that evidence we derive a Verdict.
The second, Verdict, refers to the final decision we make before work enters our dependent system: I'm the line-producer of this content. I run the team whose work is shipped under my name. The model may write the line, but the Verdict is mine. The work of my team will not enter our dependent systems without my decision. A Verdict is the production decision: should we ship, block, redirect, narrow the response, add a guardrail, or reject outright?
The third, Answerability, refers to the guarantee that if someone asks, I can explain why.
To say this another way: our agent (which I define as a model plus a harness of files, tools, memory, skills, sandboxes, permissions, observability, and recovery) is what runs our loop (which I define as investigation, implementation, verification, and repeat). And it's what creates our software factory.
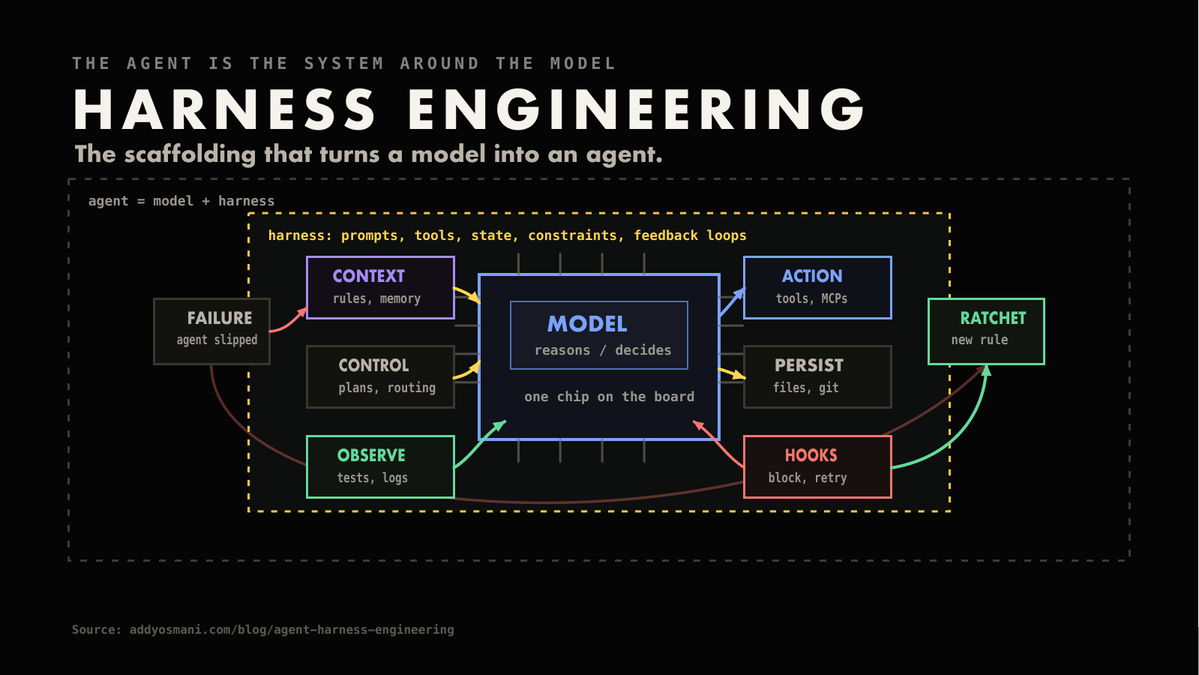
The model is just the engine. The harness - tools, memory, permissions, sandboxes, tests - is the car you build around it so it can do real work safely.
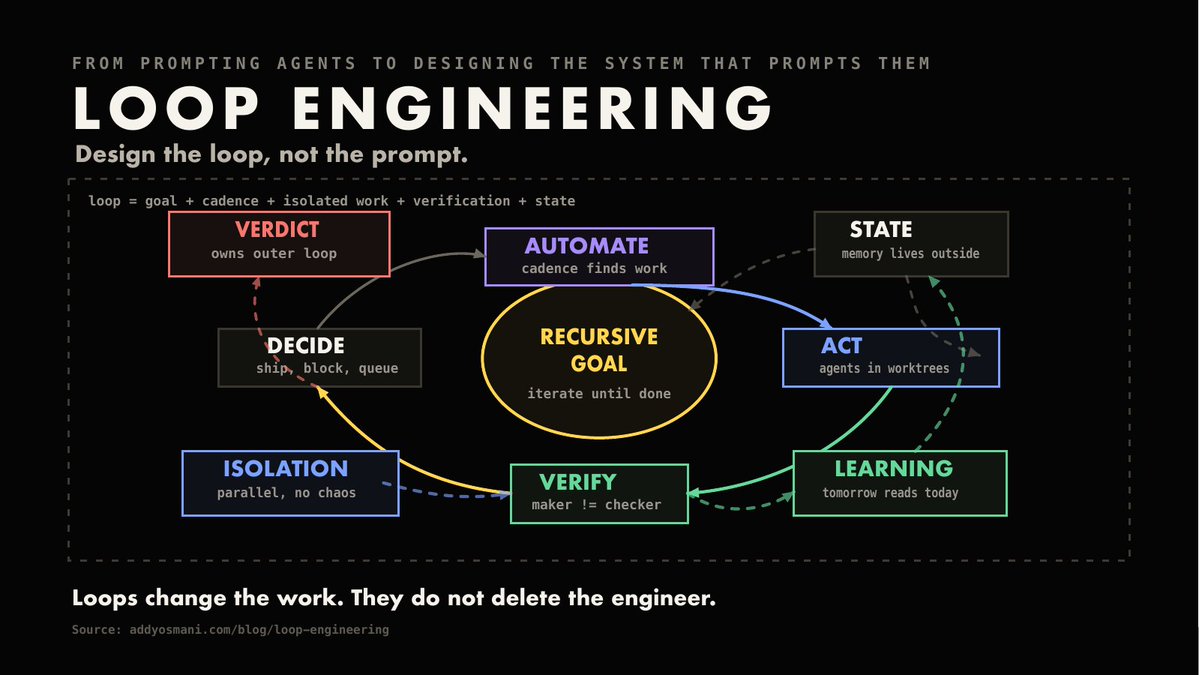
Wrap that harness in a repeatable cycle: investigate, implement, verify, repeat. The loop is how one good run becomes a process you can trust to run again. Wrap that harness in a repeatable cycle - investigate, implement, verify, repeat - where an independent check, not the model's own say-so, decides when the work is done.
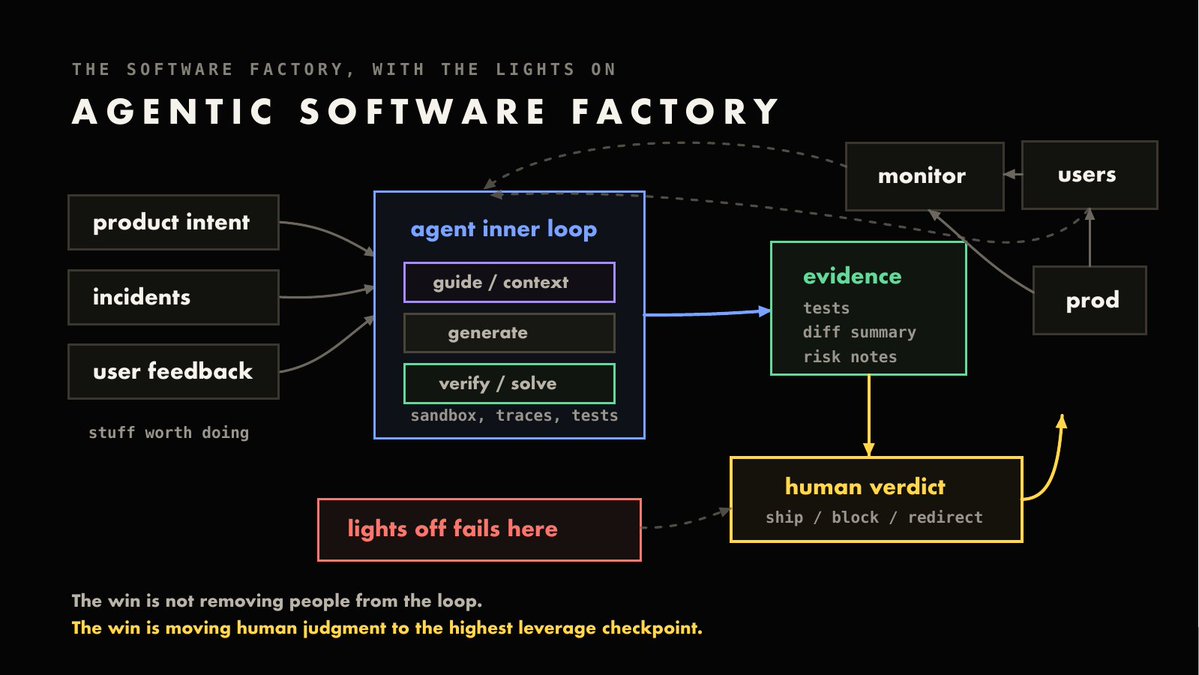
Now run many loops at once. A factory is loops at scale - the agents ship the work inside, while humans own the decisions at the boundary.
And at the heart of that factory is a careful boundary between what's inside the system and what's outside it. Inside the system: we collect inputs (from the product team's intent, or knowledge of previously shipped work, or of recent incidents, or of specific feedback from users). The agent loop investigates the task, implements a plan, and verifies the result. Then, evidence crosses that boundary. A human, who owns the dependent system, sees the evidence and decides whether to proceed.
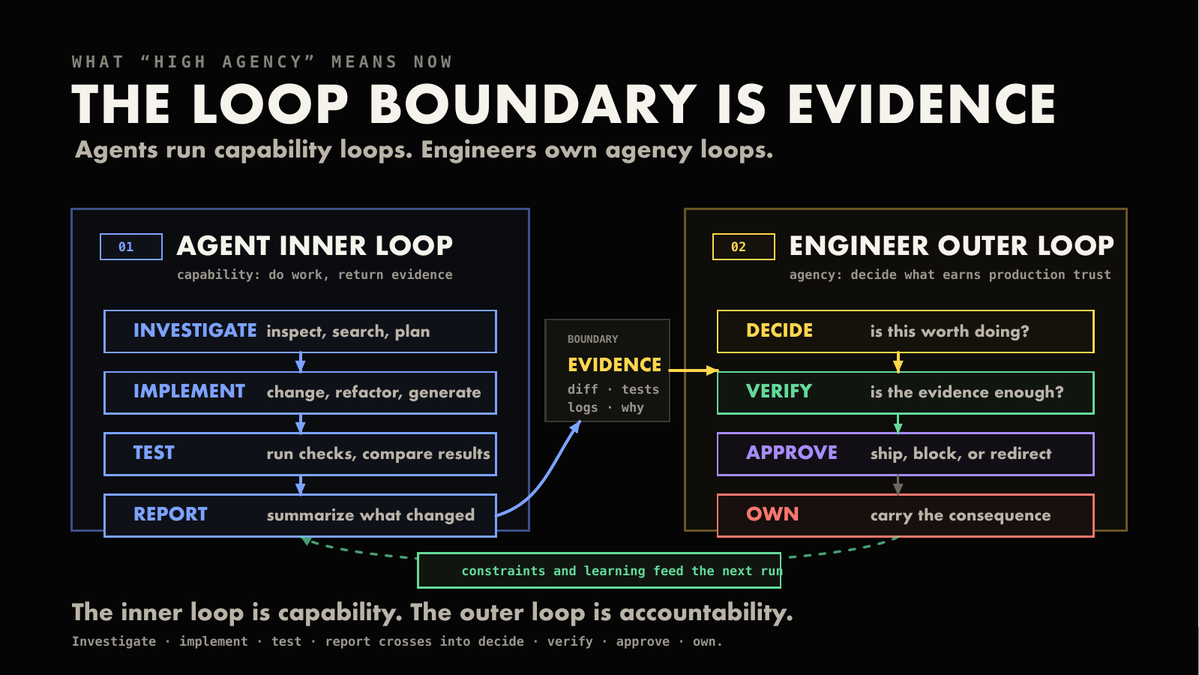
And that, friends, is the shift we're trying to make. Before, our agents were doing the inner loop of the execution loop. Now they run the inner execution loop. Engineers own the outer loop.
Inside the system, there's really just one kind of thing our agents are doing: capability. The capability to investigate tasks, implement plans, test their results, and report back. That's the capability of a model. And as we've said, that future is already here.
Outside the system, there's a single kind of thing: agency. The agency to decide, verify, approve, and own.
We're still talking about code, you see. It just needs to live in a place and be performed by people who know what they're doing.
The potential for AI code is no longer marginal. In a Sonar 2026 survey, we asked teams about the share of their commits that were AI-assisted. It was small but non-trivial. And several of the respondents said they expect the share of AI-assisted commits to grow substantially. Sonar's 2026 State of Code report found that 42% of committed code was AI-generated or significantly AI-assisted, with expectations for that share to keep growing rather than plateauing.
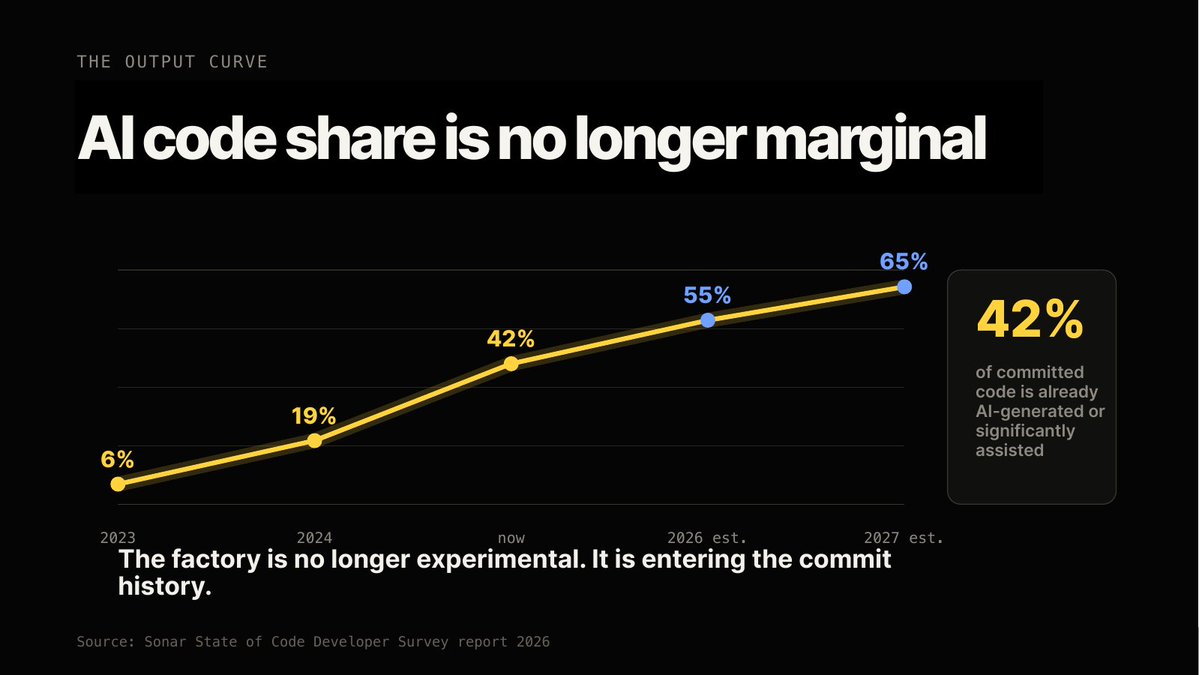
Creation, in other words, is getting cheaper. Scarcer resources are review, validation, understanding, and maintenance.
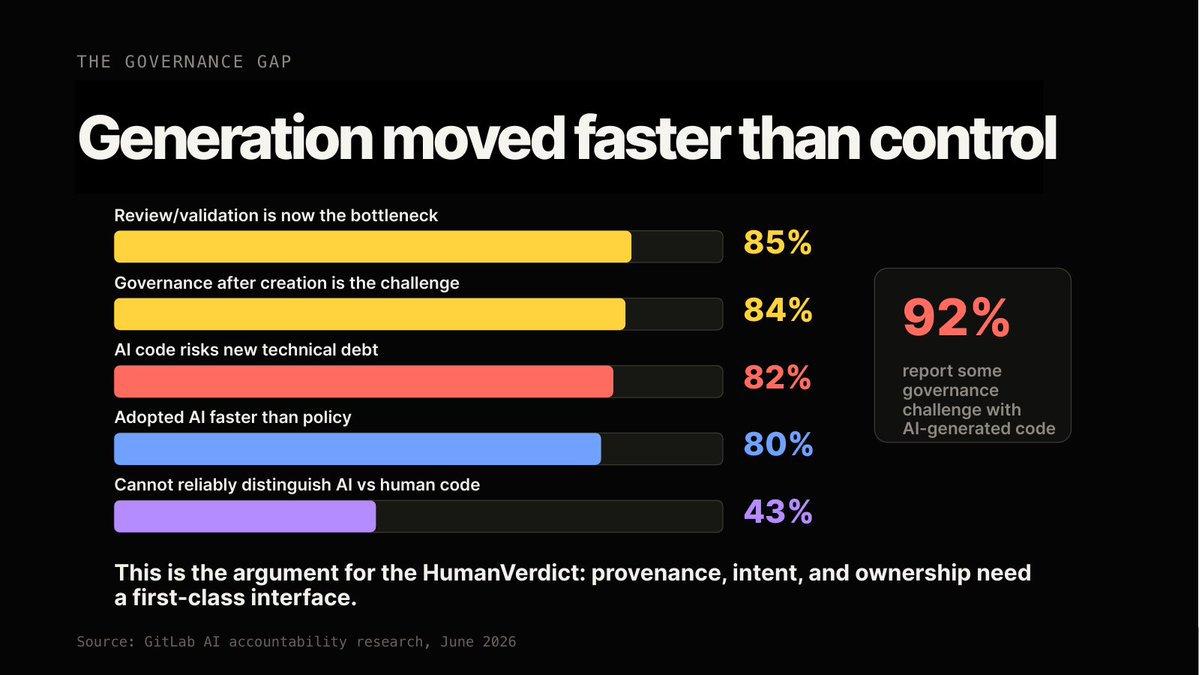
We moved the speed of generation faster than we moved the speed of control. And so we have a trust-verification gap. A lot of people we talk to still express some degree of distrust in AI code. Yet fewer of them seem to consistently build that distrust into their verification processes.
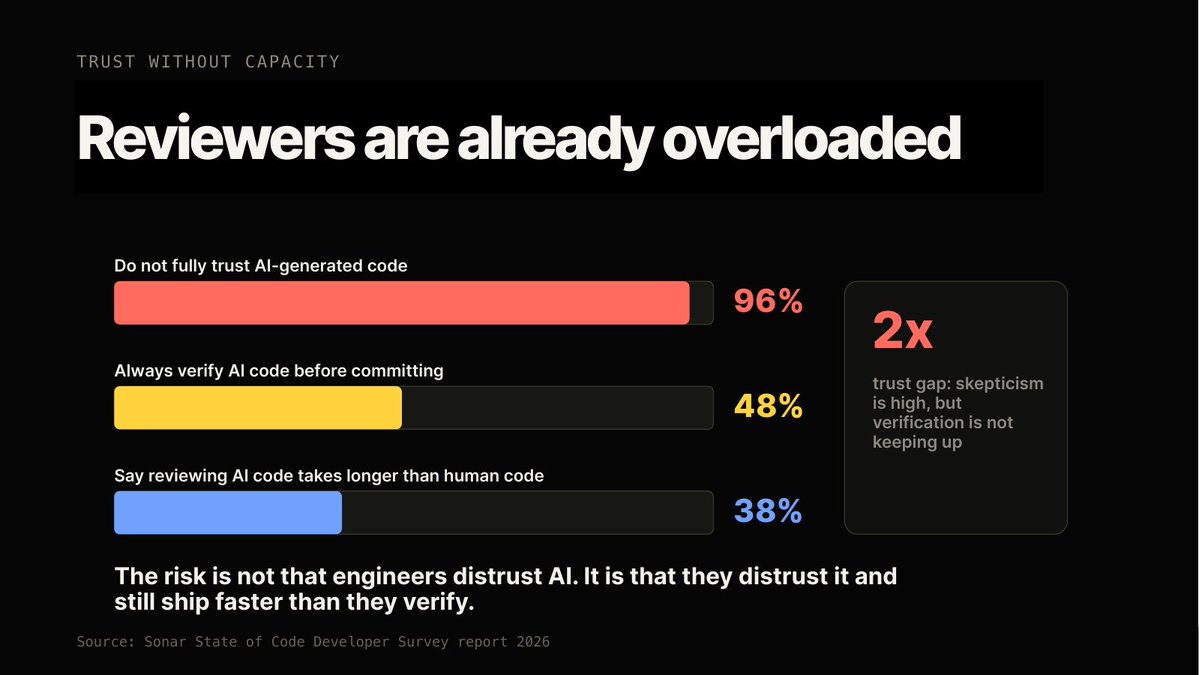
And that's a dangerous place to be in. We're going to need cheaper, clearer ways to verify the trustworthiness of AI code.
If you look at the GitLab June 2026 report, you'll see that governance questions have shifted. GitLab's June 2026 AI accountability research shows that review and validation are the current bottlenecks when using AI and, more worryingly, that governance usually happens after code creation, after we've accepted the risk and lost control over ownership. Today, it's not just about control. It's about what constraints we set on the system. It's about how we'll check the work with evidence, and how we'll hold teams accountable. It's about who will own what part of the AI lifecycle.
So the final distinction in this series is between process and quality. Quality is the concept of back pressure. We mean it literally. We don't want to grant our agents as much autonomy as they can possibly exercise. We want to grant them just enough autonomy that we have enough back pressure to stop them, regulate them, check their work, and ensure our humanity.
Ordinary engineering holds up a lot of signals that indicate that the work being done is doing the right thing. Type checks, tests, hooks, sandbox limits, audit logs, monitors. Our engineering systems are full of these kinds of signals, and they're designed to provide enough back pressure to keep the system honest.
And so as long as our agents are emitting these same signals, we can trust our ordinary engineering to provide appropriate back pressure.
Trusting our systems doesn't mean we don't want a human in the loop. It just means that the human doesn't need to be in the inner loop. We want them in the constraints loop (what inputs, architectures, instructions, or invariants should we set?), the sampling loop (how much output should we sample and review?), the audit loop (what evidence should we keep and how do we make sure our audit log is effective?), and the ownership loop (what part of the production boundary should we own).
But the human doesn't need to be in the inner loop.
The agent can ship more than you can review.
And the scarce resource is your own core human judgment, informed by quality signals like logs or tests.
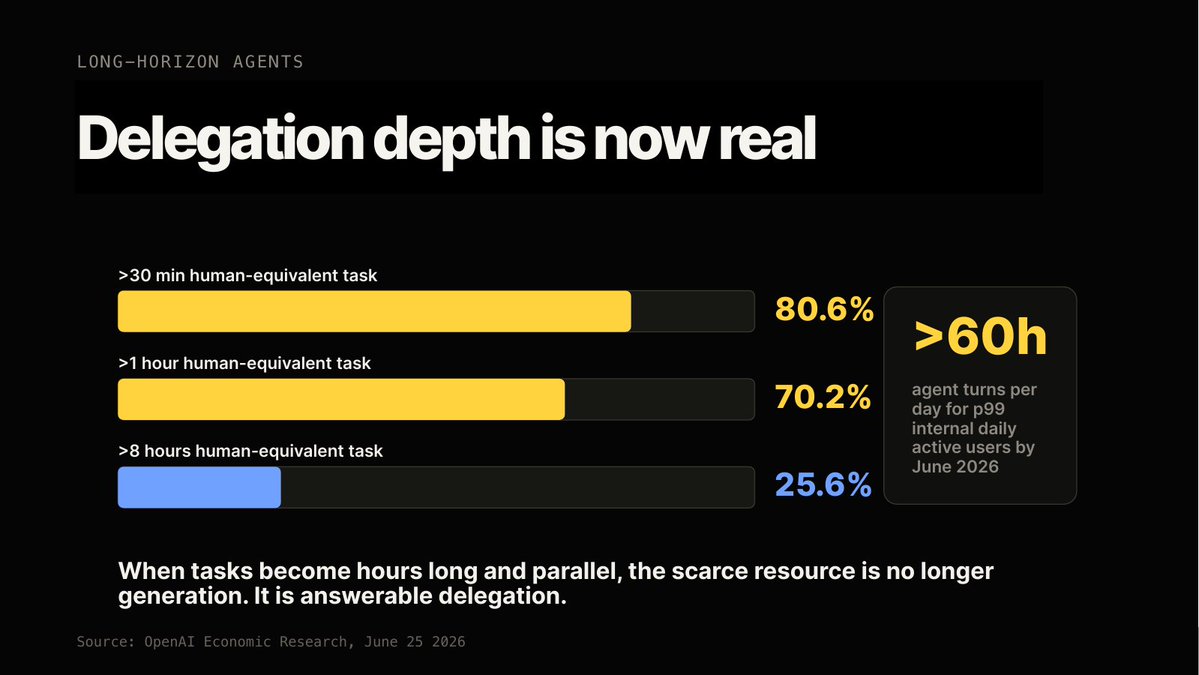
The AI June 2026 report shows that, in the experimental setting, agentic delegation along hour-scale time horizons is essentially here. The work by OpenAI this year on agents and the future of work was a great source for these ideas. So we need to start thinking about how to establish this ownership boundary, as our systems start shipping more than we can review.
And that's where the answerability comes in.
Because with long-horizon agents, the decisions made over hour-scale time horizons are just that - decisions. And not all the decisions are going to be recorded. You can't trace them all back to input tokens. If all you're doing is trusting that the output you get is the correct choice for the problem at hand, the hundreds or even thousands of human hours of work you're going to need to reconstruct the chain of decisions that lead to it become impossible. And so, again, answerability becomes something that must be at the core of our system design.
## Three hidden costs
And there are three hidden costs:
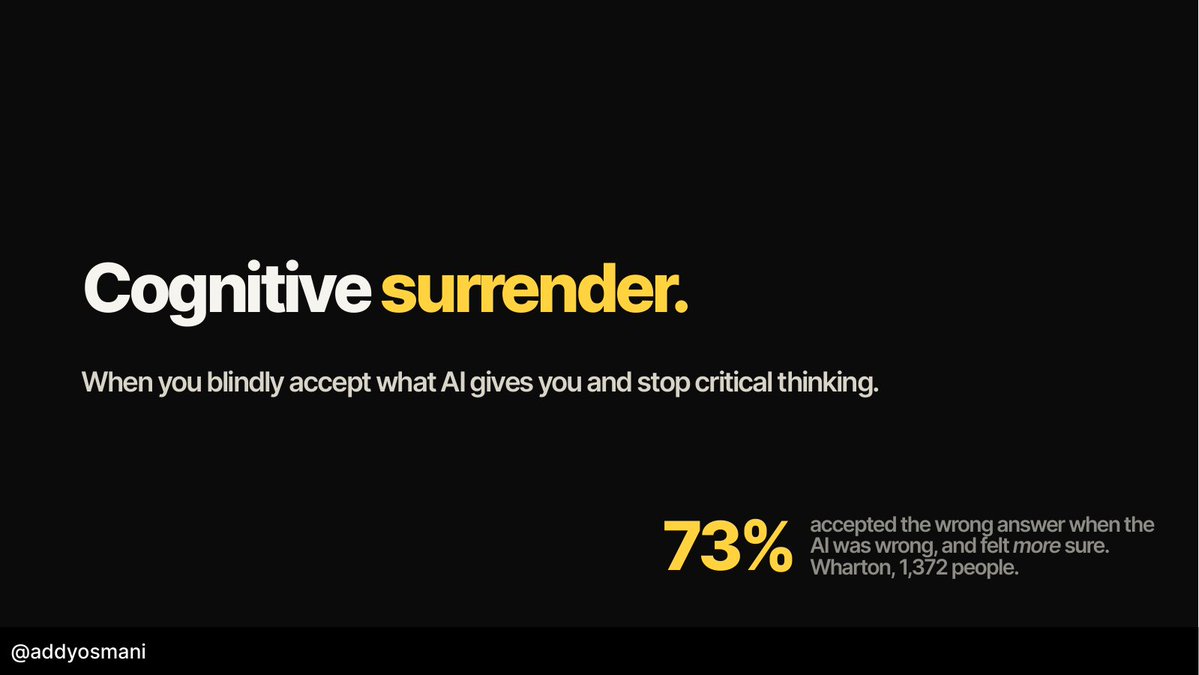
Cognitive surrender ~ blindly accepting what AI gives you. When you delegate work to an agent, the work itself may appear to be the work of the agent. But it's actually your work. It's your reputation. It's your responsibility. And it's your software that suffered the defects in the output. And it's your software that needs to be changed to reflect that output. So the agent's output becomes your answer. And with it comes all the accountability. The Wharton study that put this together is reassuring when the AI is right. But when it's wrong, the news isn't great. When the AI was wrong, nearly three-quarters of people accepted it anyway, and felt more confident than they would have without the AI.
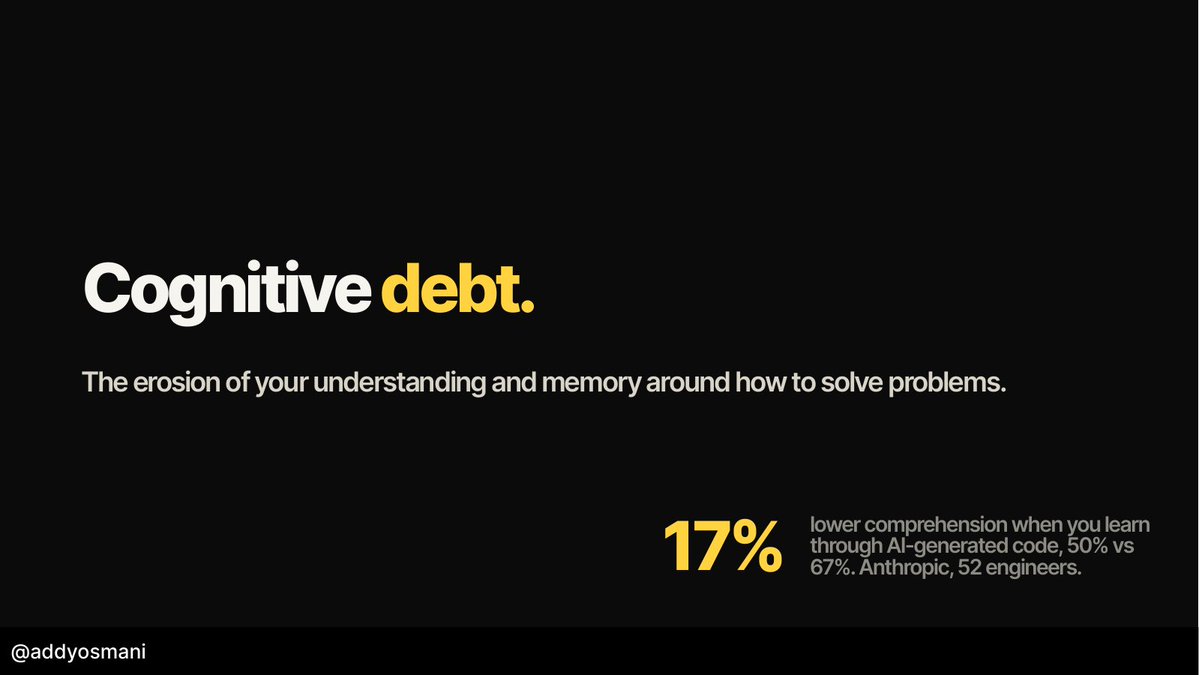
Cognitive debt ~ erosion of your understanding and memory of how to solve problems. When you delegate work to an agent, you're offloading all the thought work to the agent. And while thinking it all out yourself takes time and energy, thinking it out on a massive codebase takes resources that aren't available when you're trying to run up the learning curve. So the output you get is often unattainable by you. And the longer the time horizon of the agentic planning, the bigger the gap between the code the agent produces and your understanding of it becomes. The gap compounds. The debt accumulates. And the cost of climbing the learning curve grows almost exponentially. There's a randomized controlled trial from Anthropic looking at whether engineers who lean on AI to write code understand it as well as engineers who write it themselves. The conclusion was gloomy: on a comprehension quiz, the engineers who worked through AI scored seventeen percentage points lower than those who didn't, 50 percent versus 67 percent.
And then there's the orchestration tax ~ its easy to spin up lots of agents now, but your cognitive bandwidth doesn't parallelize in the same way. Steering your agent away from the worst behaviors, sorting the work the agent produces to identify the ones that need your attention, directing it to focus on the work you care about first, verifying your most important constraints and your most dangerous assumptions before you let it run…
All of that takes work, and it can't be automated.
There's no substitute for human judgment.
Brownfield systems are especially dangerous here, because the system behavior you have to audit doesn't live in the code. It lives in the scars.
Fixes? Make attention the priority in your architectural decisions. Use worktrees, scopes, and evidence to reduce the coupling between your initial plan and the work that emerges from it. Time-box the effort to resolve unactionable steps. And make change in your software strictly an opt-in permission.
Alpha, decay, and taste: these are the three core patterns that shape careers and performances across domains.
Alpha is the lead part taken up by the highest achiever in the competition, when you're playing your highest-value game move. Decays are established patterns that everyone learns through repetition and watching others (plateaus, if you like). Taste is the earliest we can sense the lead in an alpha or the change in a decay. It's our judgment of what's coming before we have any evidence that anything is happening. Paul Graham's point is that when anyone can make anything, choosing what to make matters more, and Mitchell Hashimoto's definition is the operational one: making high-quality qualitative judgments where no objective metric exists yet. From now on, taste drives everything: alpha shifts are taste changes. And decays fade out because we start to taste something different.
Next step? Operationalize your taste. How? Give it a name that reflects what you're trying to move from limbic to conscious. Practice it in critique and examples. Make its rationale explicit.
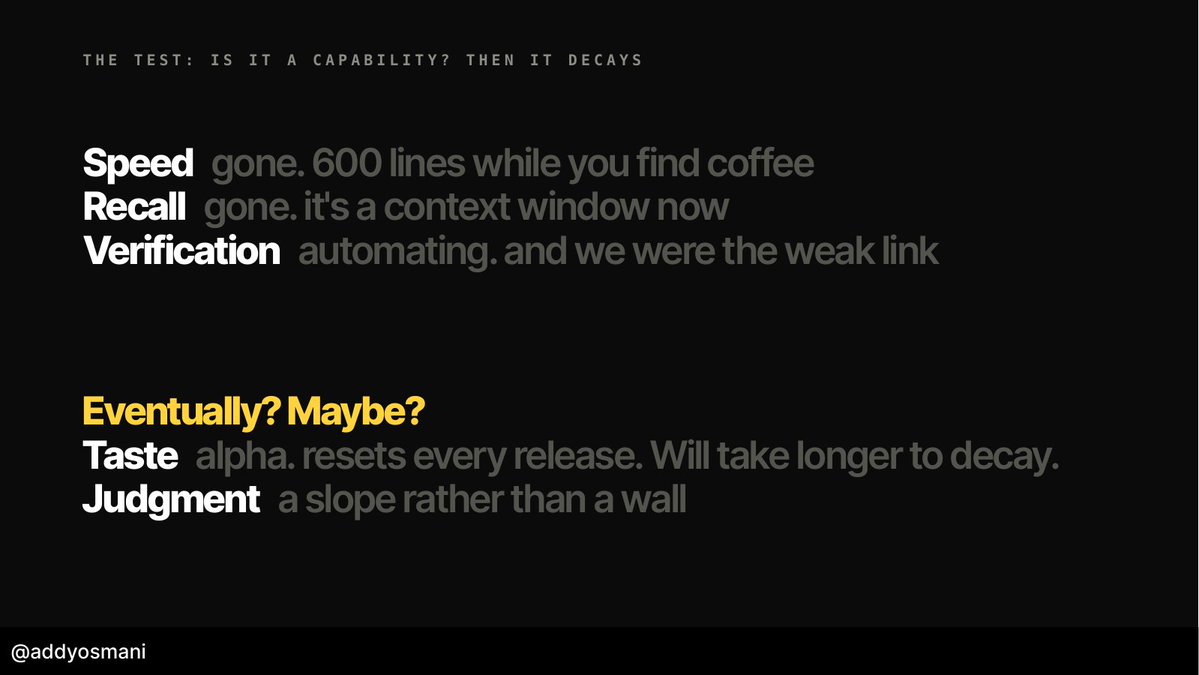
And keep making the move that delivers the most durable competitive advantage in your industry. What's that? Keep moving the edge up from just doing the task to teaching it, systematizing it, deciding when it should be done, and owning the result.
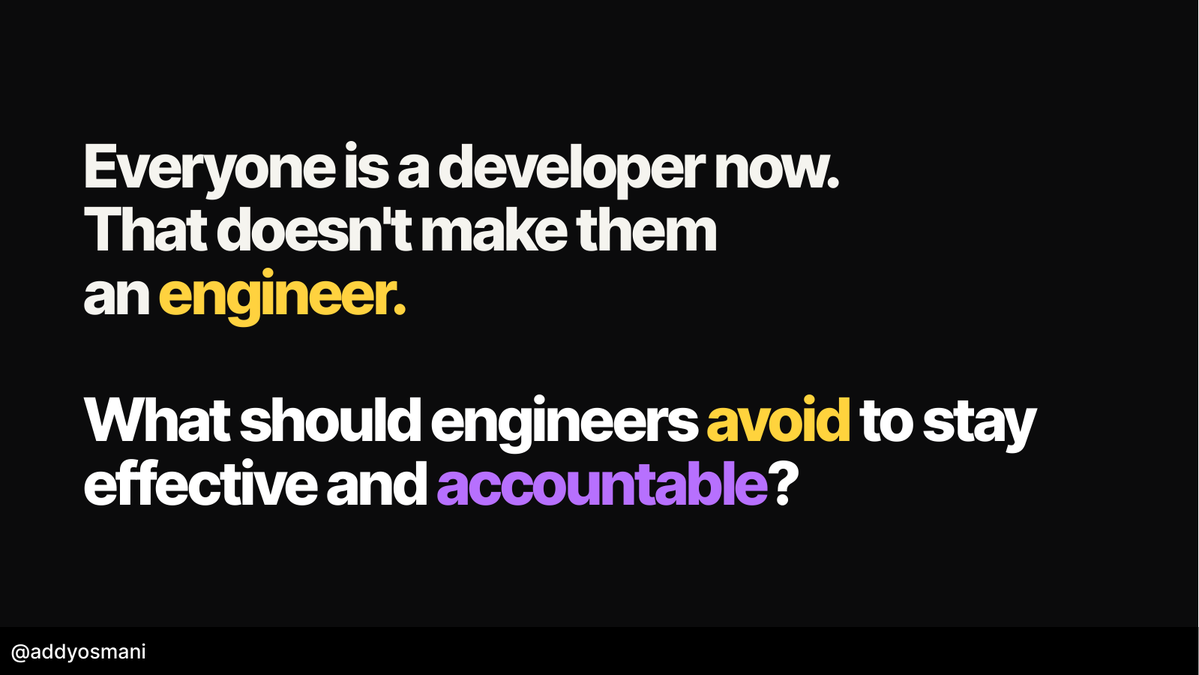
Everyone is a developer, but not everyone is an engineer. Engineering is what a developer turns into when they embrace a work discipline that is more strict: thorough and logically sound reasoning, consideration of constraints and tradeoffs, recognition of risk and exposure, and practical accountability.
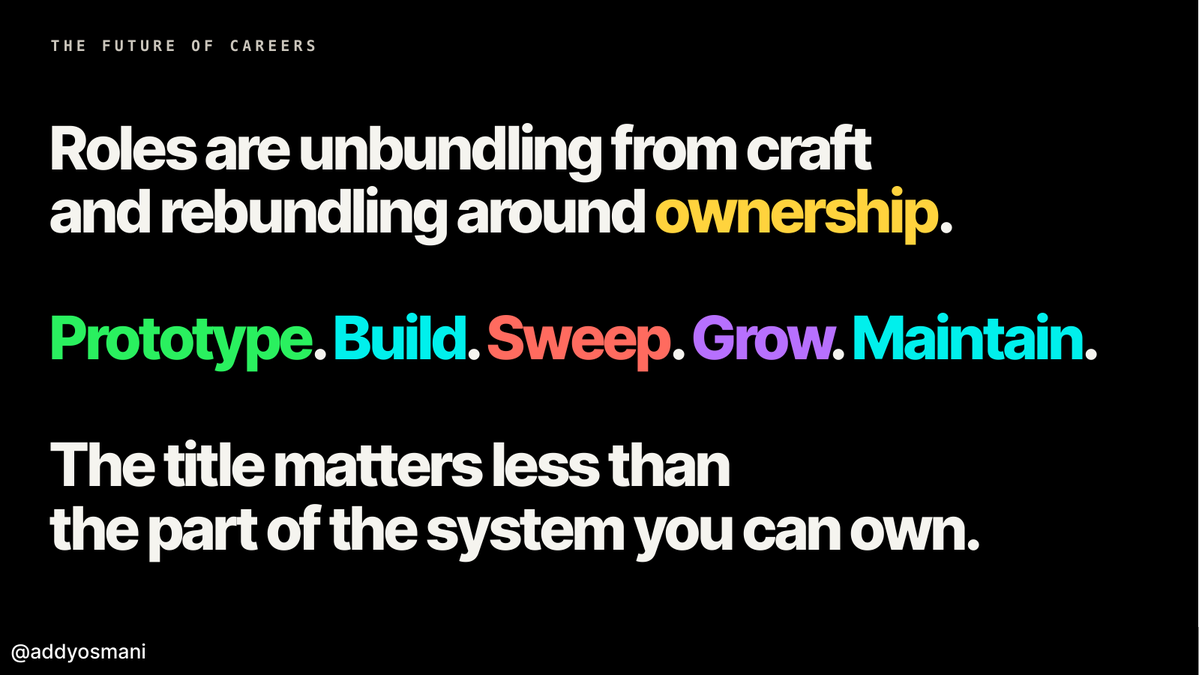
In the future, people will leave the administrative work of engineering and embrace new roles that emerge as engineering becomes more demanding. Roles that are un-bundled from the spirit of craft but make clear what each person does. There will be those who prototype. Those who build. Those who sweep. Those who grow. Those who maintain.
The humans hold the edge of the system in the other direction, too. Increasing the alpha in the other direction: choosing what is worth doing, defining the constraints within which it should be done, deciding if the evidence is sufficient to proceed, and caring for the result. Whether it's a single team or a hundred teams, this is the edge that only humans can hold.
Accountability will scale the factory. Like attention and taste, accountability is also one of the three dualities that makes everything work. Without accountability, there are no rules. No wrangling with questioners. No trade-offs. No risks. No safety nets. If nobody owns the consequence of a decision, then high agency can only bring chaos.
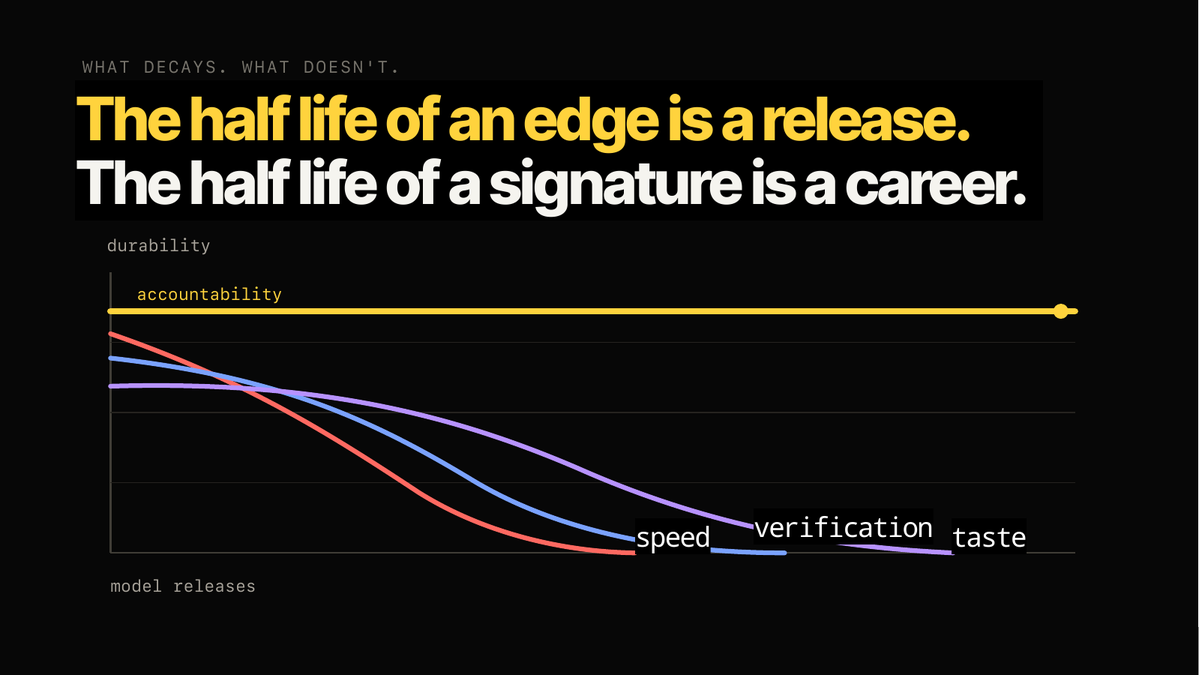
The half-life of an edge is one release, but the half-life of a signature is a career. A signature is your name on the work, such that you feel you can stand behind what was shipped. Skills get you leverage; accountability turns leverage into trust.
Only people can choose. Only people inherit consequence. Agents can be asked to choose, route, merge, and escalate safely inside a policy, but they cannot inherit the consequences.
Every codebase should perhaps come with some kind of accountability contract that explicitly states the checklist that was understood when the change was accepted, the evidence that went into the decision, who was accountable for the change, and the system status after the change was blocked. Just like:
- Your attention and taste
- Your evidence, verdict, and ownership
- Your alpha, decay, and taste
## High agency
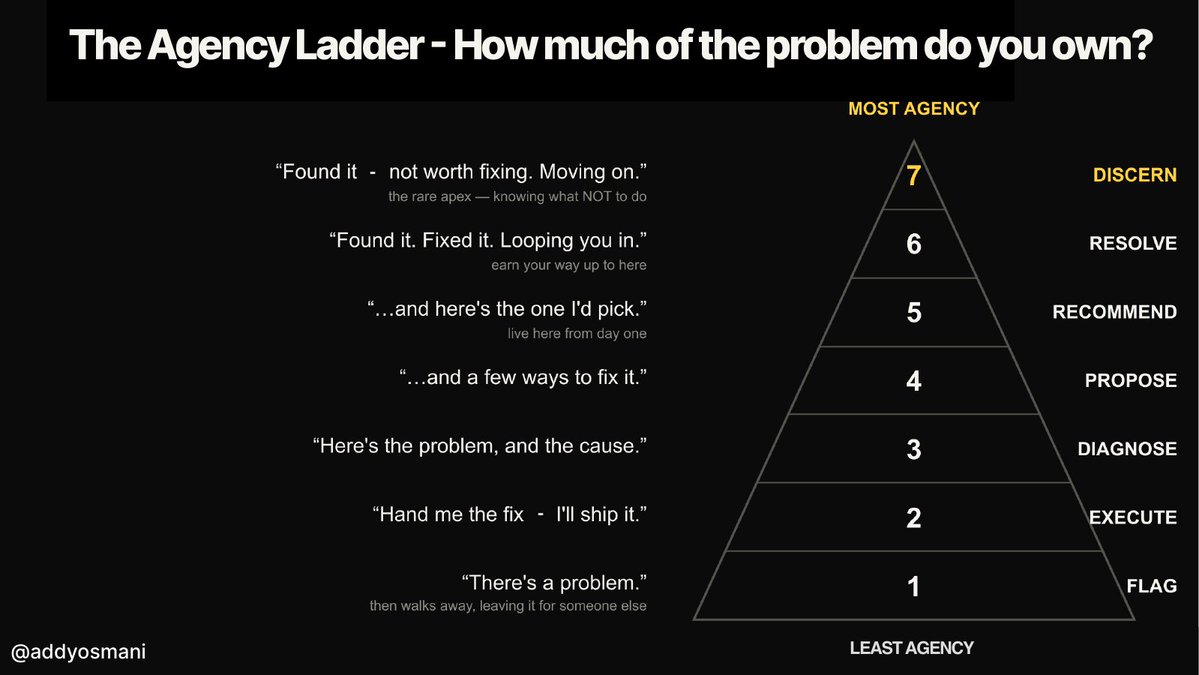
In a typical agentic workflow, high agency is the art of knowing when to delegate, when to inspect, when to stop, and when to own the result of a process. The ladder of agency runs from low to high: flag a potential problem, investigate it, execute against it, diagnose it, propose solutions, recommend fixes, and resolve the issue. A high rung on the agency ladder is discernment: found it, it's not worth fixing, moving on.
## The twelve pillars that hold up the software factory
Brownfield is the frontier for factories that hope to scale. All those clever little innovations may not feel like much yet, but the production environment is a lot. When building an entirely new system, it's much easier to plan and implement sufficient back pressure mechanisms because you have full control. When you're adding intelligent agents to a legacy system, however, it's another matter entirely.
Legacy systems include the entirety of production behavior, future expectations from customers, migration histories, release and budget cycle durations, unspoken assumptions, edge cases, data weirdness, runbook procedurals, and all the scars that accumulated without the will to care for the system.
To be a steward of brownfield requires a form of durable engineering. Work has to be done to turn implicit knowledge into explicit constraints, keep it coherent across teams and through generations, formalize that knowledge into test procedures and functional specifications, and tie that knowledge to objective evidence. All while ratcheting failure into more learning. Because if the system doesn't get the care it has always received, everything will come crashing down.
## New Work is Real Work
The work will get more interesting as you scale. Because when everything else is built, people will want to build new things. They'll want to employ the alpha and taste they have developed through their craft to design new loops that can be grafted onto the software factory. Or they'll want to build greenfield systems that employ all the knowledge of the software factory to one elegant, well meaning, principled effort. They'll want to design and implement new forms of evidence that will rise to the level of verification for the new systems. They'll want to take care of brownfield systems that are now so complex they need dedicated attention. They'll want to design and manage new back-pressure mechanisms. They'll want to design new agents. And they'll want to build agency.
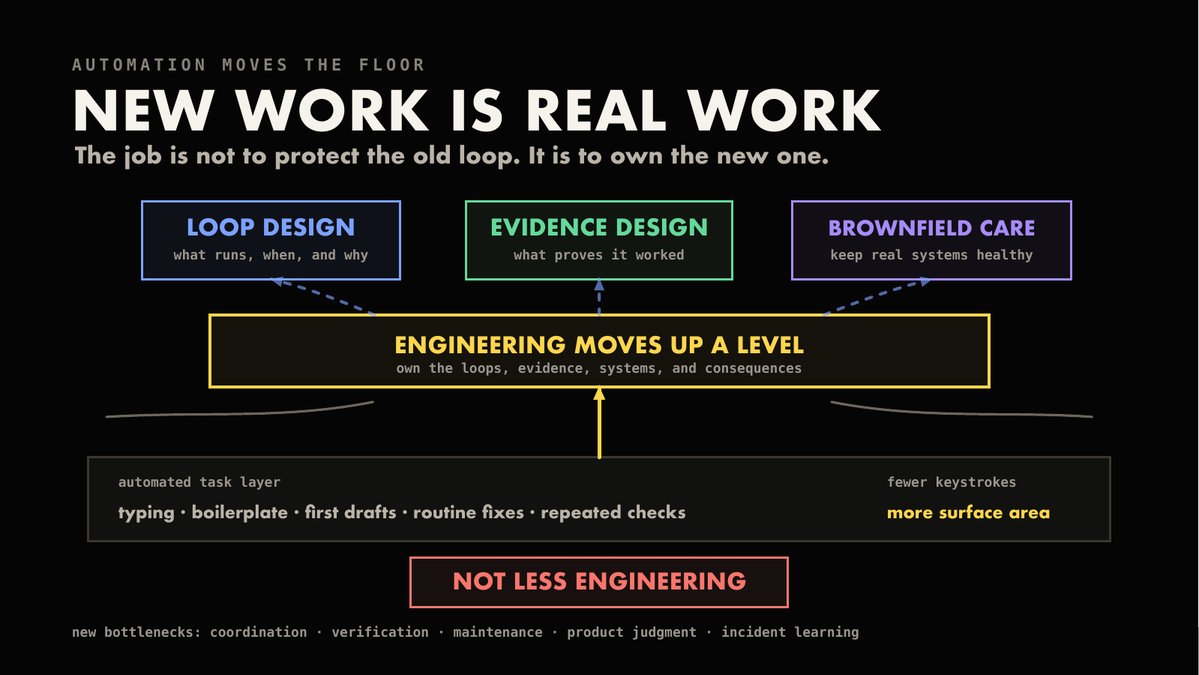
And, as they do, they'll come to see that all this is real work. That's a good thing.
Automation creates bottlenecks. Bottlenecks in production that are worth owning. Because automation gives us control over industrial scale. But there's also new bottlenecks that arise from industrial scale. The bottleneck moves from "can we build this?" to "should this exist, can we answer for it?"
What I'm suggesting is a practical operating model for scaling agentic engineering. There's inner and outer loops. The inner loop is where the work is done. Loops are designed to be as independent as possible. Put all quality assurances and verification inside the loop. Once you've designed and validated the loop itself, the only thing you have left to do is to grant autonomy by putting in place a back-pressure mechanism that acts to control the rate at which the loop is run and its scope of operation. And put humans in their rightful place, on the right decisions. Don't treat understanding as a hand-off or a release gate, but rather as a point of decision where humans are primed to provide their insight. And then for every artifact that exists and is fed back into production and into new teams and engineers, leave behind better artifacts.
Build the factory; keep the lights on; make work legible, verifiable, owned.
An agent can write it. But before it reaches users, someone must explain why it should exist, why it's safe enough to be part of production, and what they will do when it is wrong.
That is agentic engineering at the outer loop - that is the work now.
Pangram has scored this article as 100% human written: https://www.pangram.com/history/ae6caccc-b70f-4336-a019-5c3411516871
## 相关链接
- [Addy Osmani reposted](https://x.com/addyosmani)
- [Addy Osmani](https://x.com/addyosmani)
- [@addyosmani](https://x.com/addyosmani)
- [913K](https://x.com/addyosmani/status/2074927530482835916/analytics)
- [loops](https://x.com/addyosmani/article/2064127981161959567?lang=en)
- [Sonar's 2026 State of Code report](https://www.sonarsource.com/state-of-code-developer-survey-report.pdf)
- [GitLab's June 2026 AI accountability research](https://ir.gitlab.com/news/news-details/2026/GitLab-Research-Reveals-Organizations-Are-Generating-AI-Code-Faster-Than-They-Can-Control-It/default.aspx)
- [OpenAI this year on agents and the future of work](https://openai.com/index/how-agents-are-transforming-work/)
- [Wharton study](https://executiveeducation.wharton.upenn.edu/thought-leadership/wharton-at-work/2026/05/thinking-fast-slow-and-artificially/)
- [randomized controlled trial from Anthropic](https://www.anthropic.com/research/AI-assistance-coding-skills)
- [Paul Graham's point](https://paulgraham.com/taste.html)
- [https://www.pangram.com/history/ae6caccc-b70f-4336-a019-5c3411516871](https://www.pangram.com/history/ae6caccc-b70f-4336-a019-5c3411516871)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [2:44 AM · Jul 9, 2026](https://x.com/addyosmani/status/2074927530482835916)
- [913.4K Views](https://x.com/addyosmani/status/2074927530482835916/analytics)
- [View quotes](https://x.com/addyosmani/status/2074927530482835916/quotes)
---
*导出时间: 2026/7/16 14:48:17*
---
## 中文翻译
# 掌控外环
**作者**: Addy Osmani
**日期**: 2026-07-08T18:44:08.000Z
**来源**: [https://x.com/addyosmani/status/2074927530482835916](https://x.com/addyosmani/status/2074927530482835916)
---

在过去的一年里,关于智能体工程的讨论已经转向了护栏与循环、集群与软件工厂。我的浅见是:工程师需要掌控外环(outer loop)——也就是对这些系统负责。随着像 Fable 和 GPT-5.6 这样强大的模型问世,这一点只会变得愈发真实。

智能体拥有杠杆力量,而杠杆力量带来责任。必须有人能够确切地解释改变了什么、为什么这是安全的、如果判断错了会发生什么。否则,他们的行为就无法被正当化。这也使得组织从一开始就不太可能去要求他们这样做。
因此,我想谈谈三个术语。第一个是“质量”(Quality),指的是我们在放手让系统运行之前所安装的所有检查。这些检查会产生证据,而从这些证据中我们得出一个“裁定”(Verdict)。
第二个是“裁定”(Verdict),指的是在工作进入我们所依赖的系统之前,我们做出的最终决定:我是这些内容的出品人。我管理的团队所完成的工作将以我的名义交付。模型可以撰写内容,但裁定权在我。我团队的工作,未经我的决定,不会进入我们所依赖的系统。裁定就是一个生产决策:我们是发布、阻止、重新导向、缩小响应范围、添加护栏,还是直接否决?
第三个是“可问责性”(Answerability),指的是这样一种保证:如果有人问起,我能够解释原因。
换个说法:我们的智能体(我将其定义为模型加上由文件、工具、内存、技能、沙箱、权限、可观测性和恢复机制组成的护栏体系)负责运行我们的循环(我将其定义为调查、实现、验证、重复)。而这正是创建我们软件工厂的东西。

模型只是引擎。护栏体系——工具、内存、权限、沙箱、测试——则是你围绕它建造的汽车,让它能够安全地做真正的工作。

把这个护栏体系包裹在一个可重复的循环中:调查、实现、验证、重复。循环就是把一次良好的运行变成一个你可以信赖、可以反复运行的过程。把这个护栏体系包裹在一个可重复的循环中——调查、实现、验证、重复——其中由独立检查而非模型自己的判断来决定工作何时完成。

现在,同时运行多个循环。工厂就是规模化运作的循环——智能体在内部交付工作,而人类则掌握边界处的决策权。
而这座工厂的核心,是对系统内部与系统外部的谨慎区分。系统内部:我们收集输入(来自产品团队的意图,或对以往已交付工作的了解,或对近期事故的了解,或来自用户的具体反馈)。智能体循环调查任务、制定计划并验证结果。然后,证据跨越这条边界。拥有所依赖系统的人类看到这些证据,并决定是否继续推进。

朋友们,这就是我们试图实现的转变。以前,我们的智能体是在执行执行循环的内环。现在,它们运行的是内层执行循环。而工程师掌控外环。

在系统内部,我们的智能体真正在做的事情只有一种:能力。调查任务、制定计划、测试结果并汇报的能力。这是模型的能力。正如我们所说,这个未来已经到来。
在系统外部,只有一种东西:能动性(agency)。决定、验证、批准和负责的能动性。
你看,我们仍然在谈论代码。它只是需要栖身于一个合适的位置,并由知道自己在做什么的人来执行。
AI 代码的潜力已不再边缘化。在 Sonar 2026 年的一项调查中,我们询问了各团队其提交中由 AI 辅助的比例。这个比例虽小但不可忽视。而且一些受访者表示,他们预计 AI 辅助提交的比例将大幅增长。Sonar 的 2026 年《代码状态》报告发现,42% 的已提交代码是 AI 生成或得到 AI 大幅辅助的,并且预计这一比例将继续增长而非趋于平稳。

换言之,创造正变得越来越廉价。更稀缺的资源是审查、验证、理解和维护。
我们让生成速度的提升快于控制速度的提升。于是我们出现了信任-验证鸿沟。与我们交谈的许多人仍然对 AI 代码表达某种程度的不信任。然而,他们中更少有人似乎始终把这种不信任融入他们的验证流程中。

这是一种危险的处境。我们将需要更廉价、更清晰的方法来验证 AI 代码的可信度。
如果你看看 GitLab 2026 年 6 月的报告,你会发现治理问题已经发生了转变。GitLab 2026 年 6 月的 AI 问责研究显示,审查和验证是当前使用 AI 时的瓶颈,更令人担忧的是,治理通常发生在代码创建之后,也就是在我们已经接受了风险并失去了对所有权的控制之后。今天,这不仅仅是关于控制。而是关于我们对系统设定什么约束。而是关于我们将如何用证据来检查工作,以及我们将如何让团队承担责任。而是关于谁将拥有 AI 生命周期的哪个部分。

所以,本系列的最后一个区分是流程与质量。质量就是背压(back pressure)的概念。我们是按字面意思说的。我们不想给智能体它们可能行使的最大自主权。我们只想给它们恰到好处的自主权,使我们拥有足够的背压来阻止它们、调节它们、检查它们的工作,并守护我们的人性。
普通工程实践依靠许多信号来表明正在进行的工作做的是正确的事情:类型检查、测试、钩子、沙箱限制、审计日志、监控器。我们的工程系统充满了这类信号,它们的设计目的就是提供足够的反向压力,让系统保持诚实。
因此,只要我们的智能体发出同样的信号,我们就可以相信普通工程会提供适当的反向压力。
信任我们的系统并不意味着我们不需要人参与其中。它只是意味着人不需要参与内层循环。我们要人参与的是约束循环(我们应该设置哪些输入、架构、指令或不变量?)、抽样循环(我们应该抽样审查多少输出?)、审计循环(我们应该保留什么证据,如何确保审计日志有效?)以及所有权循环(生产边界的哪些部分应该由我们掌控)。
但人不需要在内层循环中。
智能体能交付的成果比你所能审查的更多。

而稀缺资源是你自己的人类核心判断力,并由日志或测试等质量信号来提供依据。
2026 年 6 月的 AI 报告显示,在实验环境中,小时级时间范围内的智能体委派基本上已经实现。OpenAI 今年关于智能体和未来工作的研究是这些想法的重要来源。所以当我们的系统交付的成果超出我们所能审查的范围时,我们需要开始思考如何建立这种所有权边界。

而这正是“可问责性”发挥作用的地方。
因为对于长时程智能体来说,在小时级时间范围内做出的决策就只是——决策。而且并非所有决策都会被记录下来。你无法把它们全部追溯到输入的 token。如果你所做的一切只是相信你得到的输出对于当前问题是正确的选择,那么你需要花费数百甚至数千个人类小时才能重建导致该输出的决策链,这将变得不可能。所以,再次强调,可问责性必须成为我们系统设计的核心。
## 三种隐性成本
这里有三种隐性成本:
认知放弃——盲目接受 AI 给你的东西。当你把工作委派给一个智能体时,工作本身看起来可能是智能体的工作。但它实际上是你的工作。它是你的声誉。它是你的责任。在输出中出现缺陷的是你的软件,需要修改以体现该输出的也是你的软件。所以智能体的输出变成了你的答案。随之而来的是全部的责任。沃顿商学院的这项研究在 AI 正确时令人安心。但当它出错时,情况就不妙了。当 AI 出错时,近四分之三的人仍然接受了它,而且比没有 AI 时感觉更自信。

认知债务——你对于如何解决问题的理解和记忆的侵蚀。当你把工作委派给智能体时,你把所有的思考工作都转给了智能体。虽然自己把一切想清楚需要时间和精力,但在一个庞大的代码库上想清楚这些问题所需的资源,在你试图爬上学习曲线时是不具备的。所以你得到的输出往往是你自己无法企及的。智能体规划的时间范围越长,智能体产生的代码与你对它的理解之间的差距就越大。差距会复利式扩大。债务不断累积。而爬上学习曲线的成本几乎呈指数级增长。Anthropic 有一项随机对照试验,研究依赖 AI 编写代码的工程师是否像自己动手写代码的工程师一样理解代码。结论令人沮丧:在一次理解力测验中,通过 AI 完成工作的工程师比没有这样做的工程师低了十七个百分点,50% 对 67%。

然后还有编排税——现在启动大量智能体很容易,但你的认知带宽无法以同样的方式并行化。引导你的智能体远离最糟糕的行为,对智能体产出的工作进行分拣以识别需要你关注的部分,指引它优先专注于你关心的工作,在放行运行之前验证你最重要的约束和最危险的假设……
所有这些都需要工作量,而且无法被自动化。
人类判断没有替代品。

遗留系统(brownfield system)在这方面尤其危险,因为你必须审计的系统行为并不存在于代码中。它存在于伤疤之中。
解决办法?把注意力作为你架构决策中的优先事项。使用工作树(worktree)、范围和证据来减少初始计划与从中涌现的实际工作之间的耦合。为解决不可操作步骤的努力设定时间限制。并且让你的软件的变更严格成为一种需要明确授权(opt-in)的权限。
阿尔法、衰减与品味:这是塑造各领域职业生涯与表现的三大核心模式。

Alpha 是竞争中最顶尖的胜者所占据的领先位置,也就是你打出最高价值一步棋的时候。Decay(衰减)是既定的模式,每个人通过重复和观察他人来学会(可以说是平台期)。Taste(品味)是我们最早能察觉到 alpha 中的领先或 decay 中的变化的方式。它是我们在没有任何证据表明某事正在发生之前,对即将到来之事的判断。Paul Graham 的观点是,当任何人都能创造任何东西时,选择创造什么就更重要了,而 Mitchell Hashimoto 的定义是操作性的:在尚无客观指标的情况下做出高质量的定性判断。从现在起,品味驱动一切:alpha 的转变就是品味的变化。而 decay 会逐渐消退,因为我们开始品出不同的东西。

下一步?把你的品味操作化。怎么做?给它起一个名字,以反映你试图从边缘系统提升到意识层面的东西。在批评和实例中练习它。把它的依据明确表达出来。

并继续走出那个能在你的行业中带来最持久竞争优势的一步。那是什么?继续把边界向上移动:从仅仅完成任务,到教会它、将其系统化、决定它应该在什么时候完成,并对结果负责。

每个人都是开发者,但并非每个人都是工程师。工程师是开发者拥抱更严格的工作纪律后所转变成的角色:彻底且逻辑严密的推理、对约束和权衡的考量、对风险和暴露的识别,以及切实的责任担当。

在未来,人们将脱离工程中的行政事务,转而拥抱随着工程要求日益提高而涌现的新角色。这些角色从工匠精神中解绑出来,但明确了每个人各自的职责。将有负责原型的人、负责构建的人、负责清扫的人、负责增长的人、负责维护的人。

人类在另一个方向上也守住了系统的边界:在另一个方向上提升 alpha——选择什么值得做,界定完成它的约束条件,判断证据是否足以推进,以及对结果负责。无论是一个团队还是一百个团队,这都是只有人类才能守住的边界。
责任担当将使工厂得以规模化。与注意力和品味一样,责任担当也是让一切运转起来的三大二元性之一。没有责任担当,就没有规则。没有与质疑者的反复交锋。没有权衡取舍。没有风险。没有安全网。如果没有人对决策的后果负责,那么高度能动只会带来混乱。

边界的半衰期是一次发布,而署名的半衰期是整个职业生涯。署名就是把你的名字签在作品上,让你觉得你可以为所发布的东西负责。技能带给你杠杆;责任担当把杠杆转化为信任。

只有人才能做出选择。只有人承担后果。可以要求智能体在策略范围内安全地进行选择、路由、合并和升级,但它们无法承担后果。

每个代码库或许都应该附带某种责任契约,明确说明变更被接受时所理解的检查清单、决策所依据的证据、谁对该变更负责,以及变更被阻止后的系统状态。就像:
- 你的注意力和品味
- 你的证据、判断和责任归属
- 你的 alpha、decay 和 taste
## 高度能动
在典型的智能体工作流中,高度能动是一种艺术:知道何时委派、何时检查、何时停止、何时对流程的结果负责。能动性的阶梯从低到高:标记潜在问题、调查它、针对它执行、诊断它、提出解决方案、建议修复方法、解决问题。能动阶梯的高处是辨识力:发现了问题,但不值得修复,继续前进。

## 支撑软件工厂的十二大支柱
棕地(Brownfield)是希望实现规模化的工厂的前沿阵地。所有那些巧妙的小创新可能还感觉不算什么,但生产环境就大不一样了。在构建全新系统时,规划和实现足够的背压机制要容易得多,因为你拥有完全的控制权。然而,当你把智能体加入遗留系统时,那就完全是另一回事了。
遗留系统包含了生产行为的全部内容、客户对未来的期望、迁移历史、发布和预算周期的时长、未言明的假设、边缘情况、数据的怪异之处、运维手册流程,以及所有在无人愿意维护系统的情况下累积下来的伤疤。
成为棕地的守护者需要一种持久性的工程。必须做工作把隐含知识转化为明确的约束,让它在团队之间和代际之间保持连贯,把这些知识形式化为测试流程和功能规格说明,并将其与客观证据绑定。同时还要让每一次失败都转化为更多的学习。因为如果系统得不到它一直以来所得到的呵护,一切都将轰然倒塌。
## 新工作是真正的工作
随着规模的扩大,这项工作会变得越来越有趣。因为当其他一切都建成后,人们会想要构建新的东西。他们会想运用通过自己的技艺培养出的“阿尔法”和品味,去设计新的循环,嫁接到这个软件工厂上。或者,他们会想构建全新的绿地系统,将软件工厂的全部知识运用于一项优雅、善意且有原则的努力之中。他们会想设计和实现新形式的证据,使其达到对新系统进行验证的水准。他们会想维护那些如今已经复杂到需要专人关注的棕地系统。他们会想设计和管理新的背压机制。他们会想设计新的智能体。而且,他们会想要构建能动性(agency)。

当他们这样做时,他们会发现这一切都是实实在在的工作。这是件好事。
自动化会制造瓶颈。这些是值得拥有的生产瓶颈。因为自动化让我们掌握了工业级规模的控制权。但工业级规模本身也会带来新的瓶颈。瓶颈从“我们能不能把它造出来?”转移到了“它是否应该存在,我们能否为它负责?”
我所提出的是一个扩展智能体工程的实用运营模型。它有内循环和外循环。内循环是完成工作的地方。每个循环都设计得尽可能独立。把所有的质量保证和验证都放进循环内部。一旦你设计并验证了循环本身,剩下要做的就是通过建立背压机制来授予自主权,该机制用于控制循环运行的速率及其操作范围。并将人类放在他们应有的位置上——做正确的决策。不要把理解当作一种交接或发布门槛,而要把它当作一个决策点,让人类在这种时刻准备提供他们的洞见。然后,对于每一个已存在并被反馈到生产中、传递给新团队和新工程师的产物,都要留下更好的产物。
建好工厂;保持运转;让工作清晰可读、可验证、有人负责。
一个智能体可以把它写出来。但在它触达用户之前,必须有人解释它为什么应该存在,为什么它足够安全、可以作为生产的一部分,以及当它出错时他们会怎么做。
这就是外循环层面的智能体工程——这就是当下的工作。
Pangram 对这篇文章的评分为 100% 人类撰写:https://www.pangram.com/history/ae6caccc-b70f-4336-a019-5c3411516871
## 相关链接
- [Addy Osmani reposted](https://x.com/addyosmani)
- [Addy Osmani](https://x.com/addyosmani)
- [@addyosmani](https://x.com/addyosmani)
- [913K](https://x.com/addyosmani/status/2074927530482835916/analytics)
- [loops](https://x.com/addyosmani/article/2064127981161959567?lang=en)
- [Sonar 的 2026 年代码状态报告](https://www.sonarsource.com/state-of-code-developer-survey-report.pdf)
- [GitLab 2026 年 6 月的 AI 责任研究](https://ir.gitlab.com/news/news-details/2026/GitLab-Research-Reveals-Organizations-Are-Generating-AI-Code-Faster-Than-They-Can-Control-It/default.aspx)
- [OpenAI 今年关于智能体与工作未来的研究](https://openai.com/index/how-agents-are-transforming-work/)
- [沃顿商学院研究](https://executiveeducation.wharton.upenn.edu/thought-leadership/wharton-at-work/2026/05/thinking-fast-slow-and-artificially/)
- [Anthropic 的随机对照试验](https://www.anthropic.com/research/AI-assistance-coding-skills)
- [Paul Graham 的观点](https://paulgraham.com/taste.html)
- [https://www.pangram.com/history/ae6caccc-b70f-4336-a019-5c3411516871](https://www.pangram.com/history/ae6caccc-b70f-4336-a019-5c3411516871)
- [升级到 Premium](https://x.com/i/premium_sign_up)
- [2026年7月9日 凌晨2:44](https://x.com/addyosmani/status/2074927530482835916)
- [913.4K 次浏览](https://x.com/addyosmani/status/2074927530482835916/analytics)
- [查看引用](https://x.com/addyosmani/status/2074927530482835916/quotes)
---
*导出时间: 2026/7/16 14:48:17*