# How To Build A Full Team Of Agents To Improve Workflow (Full Course).
**作者**: NeilXbt
**日期**: 2026-05-17T13:32:38.000Z
**来源**: [https://x.com/neil_xbt/status/2056004969430450276](https://x.com/neil_xbt/status/2056004969430450276)
---
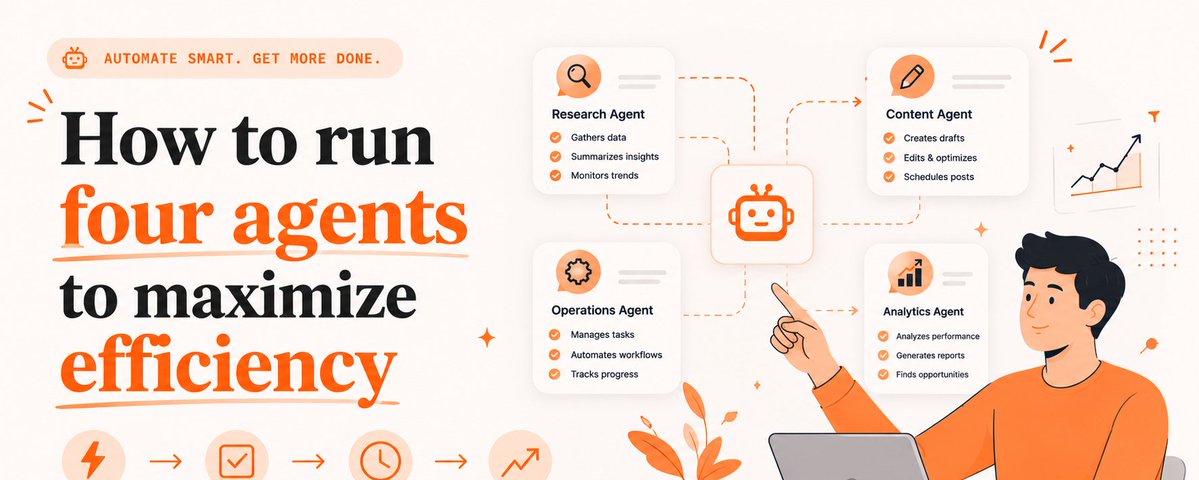
There is a version of your content operation where you do not write, research, edit, or publish manually.
A research agent finds the non-obvious angle on any topic you give it. A production agent turns that research into a first draft that sounds like you wrote it at your best. A quality agent rejects anything below your defined standard and tells the production agent exactly what to fix. A distribution agent takes the approved output and formats it correctly for every platform you use.
You create the system once. Then you give it a topic and walk away.
This is not a hypothetical. It is a specific architecture that any person who uses Claude can build over a weekend, without a computer science degree, without DevOps experience, and without writing a single line of code beyond the configuration files the system needs.
The principle behind it is the same principle behind every high-performing team. Specialists consistently outperform generalists doing many things at once. When you ask one Claude session to research, write, review, and publish in the same conversation, you get context-switching, conflicting quality standards, and output that is mediocre across every phase. When you build four agents with distinct roles and clear handoffs, you get output that is excellent across every phase because each agent is doing exactly one thing.
Here is the complete architecture and exactly how to build it.
## Why Four Agents and Why This Structure
The number four is not arbitrary. It maps directly onto the four phases that every piece of knowledge work passes through, whether you have ever named them or not.
The first phase is intake and research. Raw information is gathered, synthesized, and shaped into a structured foundation that everything downstream will be built on. The second phase is production. The research foundation is turned into a finished first draft. The third phase is quality control. The draft is evaluated against defined standards and either approved or returned with specific instructions for revision. The fourth phase is output and distribution. Approved content is formatted correctly for each target platform and deployed.
Every complex knowledge work task passes through these four phases. A single agent context-switching between all four phases is slow, inconsistent, and difficult to debug when something goes wrong. Four specialized agents produce work that is consistent because each has one job, fast because agents can run their phases simultaneously where the workflow allows, and easy to debug because failures are isolated to the agent where they occur.
There is also a parallelism argument worth stating clearly. One agent running four phases sequentially takes four times as long as four agents running their phases in parallel. For anyone producing consistent content output, that time difference compounds quickly.
## Before You Build Anything: The Foundation That Makes It Work
Three things need to be in place before you build a single agent.
First, Claude Code installed and configured. If you do not have it yet, install it with npm install -g @anthropic-ai/claude-code and authenticate through the standard flow.
Second, a project directory with the folder structure your agents will use. Create the directory and build these folders inside it: inbox, research-briefs, drafts, approved-content, distribution, and logs. The inbox is where tasks enter the system. Each subsequent folder receives the output of the agent that precedes it in the workflow. Logs records every agent action in one place, which is what makes the system debuggable when something goes wrong.
Third, a master CLAUDE.md file at the root of your project. This file is the shared context every agent reads before taking any action. It defines the system, establishes the shared standards, names the agents and their roles, and sets the hard rules that govern every interaction.
Your CLAUDE.md should contain six sections. A system overview describing what the system does in two or three sentences. An agent roster naming each agent and its specific role. The folder structure with a one-line description of what belongs in each folder. Shared standards covering naming conventions, logging requirements, and minimum quality thresholds for each agent. The quality bar that production must meet before the quality agent will approve. And the hard rules: never delete files (archive to a timestamped backup instead), never publish without quality approval recorded in the file header, log every action before taking it, and when uncertain stop and flag for human review rather than guessing.
That last hard rule is the most important. An agent that halts and flags uncertainty produces one problem. An agent that guesses incorrectly in the wrong direction produces a different class of problem that is significantly more expensive to resolve.
## Agent 1: The Research Agent
The Research Agent is the most consequential agent in your system because the quality of every agent that follows depends entirely on what it produces.
A weak research brief produces a weak draft. A strong research brief produces a strong draft. The production agent cannot add insight the research agent did not find. The output quality ceiling of your entire system is set here.
The Research Agent's job is narrow and specific. Given a topic or a brief from the inbox folder, it produces a structured research document with exactly the following components: the core insight in one sentence, the non-obvious angle that most people miss; the target audience described specifically; at least three supporting pieces of evidence with sources; the counterintuitive angle that creates genuine interest; two or three specific data points or quotes; and three ranked content angles with one-sentence descriptions of each.
The quality standard for the research brief has one non-negotiable criterion. If the core insight is something most people already know, it fails. The research agent must produce a genuinely non-obvious insight or be directed to search further. Generic research produces generic content. The quality of your content operation scales directly with this standard.
The Research Agent's system prompt ends with a logging instruction: before completing the task, append a timestamped entry to logs/operations.md documenting what was researched and where the brief was saved. Every agent logs before completing, not after. The log is the paper trail that makes the system auditable.
## Agent 2: The Production Agent
The Production Agent turns research briefs into finished content. It reads the brief, selects the strongest angle, and writes a complete draft that matches your voice profile and meets the quality standards defined in the CLAUDE.md.
The most important configuration decision in your entire system is the voice profile you give the Production Agent. This is what determines whether the output sounds like you or sounds like a generic AI assistant. Generic AI content fails because it sounds generic. A precisely calibrated voice profile produces content that sounds like you wrote it at your best.
Before you write the Production Agent's system prompt, invest thirty minutes in this preparatory exercise. Take ten of your best-performing pieces of content and ask Claude to analyze them and extract: your average sentence length, your capitalization patterns and what you capitalize strategically, your structural patterns for opening and developing and closing, your vocabulary level and specific word choices, what you never do (the hedges and filler phrases you consistently avoid), how you handle transitions between ideas, and your call-to-action style.
Save that analysis. It becomes the voice profile section of your Production Agent's system prompt. The agent does not guess at your style. It works from a documented, analyzed, example-based profile that reflects your actual best work.
The Production Agent's output includes a metadata header at the top of every draft file that records which research brief it used, which content angle it selected and why, the word count, and the production date. This header is what allows the Quality Agent to trace decisions and the Orchestrator to track the workflow.
## Agent 3: The Quality Agent
The Quality Agent is the gate between production and publication. Most multi-agent systems skip this step and wonder why their outputs are inconsistent.
Without a quality gate, every piece of content that exits the production agent goes directly to distribution regardless of quality. Good days produce good content. Bad days produce bad content. There is no floor.
With a quality gate, nothing gets published below a defined standard. The floor is consistent because the evaluation is consistent.
The Quality Agent evaluates every draft on five criteria, each scored from one to ten. Voice match: does this sound exactly like the configured voice profile? Hook strength: does the first line stop a scroll? Information density: does every sentence earn its place? Call-to-action clarity: is the CTA specific and compelling? Format compliance: does the piece follow all format requirements?
The passing threshold is eight or above on all five criteria. Not an average of eight. Eight on every criterion individually. A piece that scores ten on four criteria and six on one fails and is returned with specific revision instructions.
The critical design principle here is in the word "specific." The quality agent must never give vague feedback. Not "make it more engaging." Not "the hook needs work." The revision brief must name the exact criterion that failed, describe the precise problem in that criterion, specify the exact change required, and ideally show a short example of the correct approach. Vague feedback produces vague revisions. The production agent can only fix what it understands clearly.
When all five criteria score eight or above, the quality agent adds an approval header to the file noting the date and the score on each criterion, and moves the file to the approved-content folder. That approval header is what authorizes the distribution agent to act. Nothing that lacks the approval header gets distributed. This is a hard rule the distribution agent enforces regardless of context.
## Agent 4: The Distribution Agent
The Distribution Agent is the final agent in the chain. Its job sounds simple but is consistently executed poorly when done manually: taking approved content and formatting it correctly for each target platform before publishing.
Different platforms require genuinely different content. A LinkedIn post that works at 400 words with a narrative structure fails on X where 280 characters per tweet is the constraint and every tweet must stand alone. A newsletter section with headers and clear structural hierarchy looks wrong reformatted without adjustment for a shorter social post. A single piece of content published identically across platforms performs worse on every platform than the same content formatted specifically for each.
The Distribution Agent solves this by maintaining platform-specific formatting guidelines and applying them automatically to every approved piece based on the target platforms listed in the content header. It never publishes to a platform without platform-specific formatting. It records every deployment in a timestamped log. And it verifies the quality approval header before taking any distribution action.
## The Orchestrator: The Brain That Connects Them
The Orchestrator is not a fifth agent. It is the routing logic that connects the four agents into a coherent workflow.
The Orchestrator receives an incoming task, routes it to the Research Agent, monitors for the research brief's appearance in the research-briefs folder, passes the brief to the Production Agent, monitors for the draft, passes the draft to the Quality Agent, handles either the approval path or the revision routing path, and confirms completion when the Distribution Agent records a successful deployment.
Two failure scenarios require specific handling in the Orchestrator's design.
A quality rejection routes back to the Production Agent with the revision brief. This is an expected path, not a failure state. The system anticipates that some drafts will require revision and routes them cleanly.
A distribution failure logs the failure and alerts for human review. It does not retry automatically. Distribution failures often have context-specific causes that require human judgment, and an agent that retries a distribution failure without that judgment can produce duplicate posts or compounding errors.
The Orchestrator makes no creative decisions. It routes and manages. That constraint is what keeps the system predictable.
## Running Your First End-to-End Task
With all four agents configured, create a task file in your inbox folder. It should contain the topic or content type, the target platforms for distribution, any specific requirements for this piece, and the deadline.
Trigger the Orchestrator with: claude "Read CLAUDE.md. You are the Orchestrator. A new task has arrived in inbox/[TASK-FILENAME]. Begin the workflow. Route to Research Agent first."
Then watch the output folders. Each folder in the chain receives a file when the preceding agent completes its work. The logs/operations.md file receives an entry at every step. The first end-to-end run will take fifteen to thirty minutes depending on topic complexity and research depth.
After ten runs the workflow becomes predictable and the quality of each component is clear. After fifty runs the system has accumulated enough operational history to reveal its own improvement opportunities, which agents are producing weak output that needs quality configuration tuning, which platform formats are working and which need adjustment, which topics the research agent finds easy versus where it consistently hits limitations.
## The Compounding Mechanism
A well-configured 4-agent system does not just produce better output than a single agent. It produces output that improves over time.
After each week of operation, spend ten minutes reviewing what worked and what did not. Update the CLAUDE.md with performance observations. Improve the voice profile in the Production Agent with examples from drafts that the Quality Agent approved with high scores. Tighten the Quality Agent's rubric wherever it allowed something through that, in retrospect, should not have passed. Add platform-specific formatting lessons to the Distribution Agent when a deployment underperformed.
The system learns what you feed it. Every week you feed it better information about what good looks like in your specific operation. Every week the output reflects that information.
One person running a 4-agent team with consistent weekly calibration produces the output of a team of four, with more consistency, faster turnaround, and a feedback loop that most human content teams do not build into their operations.
The first agent is the hardest to build because the whole system feels abstract until something runs end-to-end. After the first complete workflow, the pattern is clear. After the second agent, the architecture makes sense. After the third and fourth, the system feels less like a collection of configurations and more like a team that shows up every day and does what you trained it to do.
Build the Research Agent this weekend. Let it run on one real topic. Read what it produces.
That single output will tell you more about what the system can become than anything in this article.
## 相关链接
- [NeilXbt](https://x.com/neil_xbt)
- [@neil_xbt](https://x.com/neil_xbt)
- [5.9K](https://x.com/neil_xbt/status/2056004969430450276/analytics)
- [@anthropic](https://x.com/@anthropic)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [9:32 PM · May 17, 2026](https://x.com/neil_xbt/status/2056004969430450276)
- [5,911 Views](https://x.com/neil_xbt/status/2056004969430450276/analytics)
- [View quotes](https://x.com/neil_xbt/status/2056004969430450276/quotes)
---
*导出时间: 2026/5/18 14:31:31*
---
## 中文翻译
# 如何搭建一整套智能体团队来提升工作流(完整教程)。
**作者**: NeilXbt
**日期**: 2026-05-17T13:32:38.000Z
**来源**: [https://x.com/neil_xbt/status/2056004969430450276](https://x.com/neil_xbt/status/2056004969430450276)
---

有一种内容运营模式,你无需手动写作、调研、编辑或发布。
一个调研智能体会为你给出的任何主题找到非显而易见的角度。一个生产智能体将调研结果转化为初稿,读起来就像你在最佳状态下亲笔所写。一个质检智能体会拒绝任何低于你设定标准的内容,并明确告诉生产智能体需要修改什么。一个分发智能体会获取已批准的内容,并为你使用的每个平台进行正确的格式化。
你只需一次性创建这套系统。然后给它一个主题,就可以离开了。
这并非假设。这是一个具体的架构,任何使用 Claude 的人都可以在一个周末内搭建完成,不需要计算机科学学位,不需要 DevOps 经验,除了系统所需的配置文件之外,无需编写任何一行代码。
其背后的原则与每个高绩效团队的原则相同。专家始终优于同时处理多项事务的多面手。当你让一个 Claude 会话在同一次对话中既调研、写作、审核又发布时,你会遇到上下文切换、质量标准冲突,以及每个阶段都平庸的产出。而当你构建四个角色分明、交接清晰的智能体时,每个阶段的产出都会非常出色,因为每个智能体只做一件事。
以下是完整的架构以及具体的搭建方法。
## 为什么是四个智能体,为什么采用这种结构
“四”这个数字并非随意而定。它直接对应每项知识型工作都要经历的四个阶段,无论你是否曾经为它们命名过。
第一个阶段是接收与调研。原始信息被收集、综合,并塑造成一个结构化的基础,后续所有工作都将建立在这个基础之上。第二个阶段是生产。调研基础被转化为一份完成的初稿。第三个阶段是质量控制。初稿根据既定标准进行评估,要么获得批准,要么连同具体的修改指示被退回。第四个阶段是输出与分发。已批准的内容针对每个目标平台进行正确格式化并部署。
每项复杂的知识型工作任务都要经过这四个阶段。让单个智能体在这四个阶段之间来回切换,速度慢、不稳定,而且一旦出问题也很难调试。四个专业化的智能体产出的工作具有一致性,因为每个智能体只有一项工作;速度快,因为在工作流允许的情况下,各智能体可以同时运行各自的阶段;而且易于调试,因为故障会被隔离在发生问题的那个智能体中。
还有一个关于并行的论点值得明确说明。一个智能体按顺序运行四个阶段所需的时间,是四个智能体并行运行各自阶段的四倍。对于任何持续产出内容的人来说,这种时间差异会迅速累积。
## 在搭建任何东西之前:让系统运转的基础
在构建任何一个智能体之前,需要先准备好三件事。
第一,安装并配置好 Claude Code。如果你还没有安装,可以通过 npm install -g @anthropic-ai/claude-code 安装,并按照标准流程完成认证。
第二,创建一个项目目录,其中包含你的智能体将要使用的文件夹结构。创建该目录,并在其中建立这些文件夹:inbox、research-briefs、drafts、approved-content、distribution 和 logs。inbox 是任务进入系统的地方。后续的每个文件夹接收工作流中前一个智能体的输出。logs 将所有智能体的操作记录在一个地方,这正是让系统在出现问题时可以调试的关键。
第三,在项目根目录下创建一个主 CLAUDE.md 文件。这个文件是每个智能体在执行任何操作之前都会读取的共享上下文。它定义了系统、确立了共享标准、命名了各个智能体及其角色,并设定了约束所有交互的硬性规则。
你的 CLAUDE.md 应包含六个部分。一个系统概述,用两三句话描述系统的功能。一个智能体名册,列出每个智能体及其具体角色。文件夹结构,对每个文件夹的用途附上一行说明。共享标准,涵盖命名规范、日志要求以及每个智能体的最低质量阈值。质量标准,即生产智能体的产出必须达到、质检智能体才会批准的水准。还有硬性规则:绝不删除文件(而是归档到带时间戳的备份中),未经质检批准并记录在文件头中绝不发布,每次操作前先记录日志,遇到不确定的情况就停下来标记等待人工审查,而不是凭猜测行事。
最后那条硬性规则是最重要的。一个停下来标记不确定性的智能体只会产生一个问题。而一个朝错误方向猜测的智能体会产生另一类问题,其解决成本要高得多。
## 智能体 1:调研智能体
调研智能体是你系统中影响最深远的智能体,因为后续每个智能体的产出质量完全取决于它的成果。
一份薄弱的调研简报会产生一份薄弱的初稿。一份扎实的调研简报会产生一份扎实的初稿。生产智能体无法补充调研智能体没有发现的洞见。你整个系统的产出质量上限就在这里决定。
研究代理(Research Agent)的职责范围狭窄而具体。给定一个主题或来自收件箱文件夹的任务简报,它会生成一份结构化的研究文档,其中恰好包含以下组成部分:一句话概括的核心洞察;大多数人容易忽略的反直觉视角;具体描述的目标受众;至少三条附带来源的支撑证据;能够激发真正兴趣的反直觉角度;两到三个具体的数据点或引言;以及三个经过排序的内容角度,每个角度附一句话描述。
研究简报的质量标准只有一条不可妥协的准则。如果核心洞察是大多数人都已经知道的东西,那就不合格。研究代理必须产出真正非显而易见的洞察,否则就要被指派继续搜索。平庸的研究产出平庸的内容。你内容运营的质量直接取决于这一标准的高低。
研究代理的系统提示词以一条日志指令结尾:在完成任务之前,向 logs/operations.md 追加一条带时间戳的记录,说明研究了什么内容以及简报保存到了哪里。每个代理都在完成任务之前记录日志,而不是之后。日志就是让整个系统可审计的书面痕迹。
## 代理 2:生产代理(Production Agent)
生产代理将研究简报转化为成品内容。它阅读简报,选出最有力的角度,撰写一篇完整的初稿,使其符合你的声音画像,并满足 CLAUDE.md 中定义的质量标准。
整个系统中最重要的配置决策,就是赋予生产代理的声音画像。这决定了输出内容听起来像你本人,还是像一个平庸的 AI 助手。千篇一律的 AI 内容之所以失败,是因为它听起来千篇一律。一个精确校准的声音画像能产出仿佛你在最佳状态下亲自写出的内容。
在编写生产代理的系统提示词之前,请先投入三十分钟做这个准备工作。挑选你表现最好的十篇内容,让 Claude 分析它们并提取:你的平均句子长度;你的大小写习惯以及你在哪些地方策略性地使用大写;你在开头、展开和结尾的结构模式;你的词汇水平和具体的用词选择;你从不做的事情(你一贯避免的模糊限定词和填充短语);你如何处理观点之间的过渡;以及你的行动号召(CTA)风格。
保存这份分析。它将成为生产代理系统提示词中的声音画像部分。代理不会猜测你的风格,而是基于一份经过文档化、分析、以实例为依据的画像工作,这份画像反映了你真正的最佳作品。
生产代理的输出会在每个草稿文件顶部包含一个元数据头部,记录它使用了哪份研究简报、选择了哪个内容角度以及原因、字数和生产日期。正是这个头部让质量代理能够追溯决策,让编排器(Orchestrator)能够追踪工作流。
## 代理 3:质量代理(Quality Agent)
质量代理是生产与发布之间的关卡。大多数多代理系统都跳过了这一步,然后纳闷为什么自己的输出质量参差不齐。
没有质量关卡,每一篇离开生产代理的内容都会不分好坏直接进入分发环节。状态好的日子产出好内容,状态差的日子产出差内容,没有下限。
有了质量关卡,任何低于既定标准的内容都无法发布。下限之所以稳定,是因为评估标准是稳定的。
质量代理依据五项标准评估每篇草稿,每项按一到十分打分。声音匹配度:这篇内容听起来是否与配置的声音画像完全一致?钩子强度:第一句话能否让人停下划动的手指?信息密度:每一句话是否都名副其实?行动号召清晰度:CTA 是否具体且具有说服力?格式合规性:文章是否遵循了所有格式要求?
通过门槛是五项标准全部达到八分及以上。不是平均八分,而是每一项单独都要达到八分。一篇在四项标准上得十分、在另一项上得六分的文章将被判为不合格,并附带具体的修改指示被退回。
这里的关键设计原则就体现在"具体"这个词上。质量代理绝不能给出模糊的反馈。不能说"让它更有吸引力一点",也不能说"钩子还需要打磨"。修改简报必须指明未通过的具体标准,描述该标准中的确切问题,明确要求进行的具体修改,最好还能展示一个体现正确做法的简短示例。模糊的反馈只能带来模糊的修改。生产代理只能修复它清晰理解的问题。
当五项标准都达到八分及以上时,质量代理会在文件中添加一个批准头部,注明日期以及每项标准的得分,并将文件移动到 approved-content(已批准内容)文件夹。正是这个批准头部授权分发代理采取行动。任何缺少批准头部的内容都不会被分发。这是分发代理无论任何情境下都强制执行的硬性规则。
## 代理 4:分发代理(Distribution Agent)
分发代理是链条中的最后一个代理。它的工作听起来简单,但一旦手动执行往往做得很糟糕:把已批准的内容正确地格式化,适配各个目标平台后再发布。
不同的平台需要真正不同的内容。一篇以叙事结构写成、400 词左右的 LinkedIn 帖子,在 X 上行不通,因为那里每条推文限 280 个字符,且每条推文都必须独立成立。一个带有标题和清晰层级结构的newsletter板块,如果不加调整就直接改写成更短的社交帖子,效果会很糟。同一篇内容在所有平台上原样发布,其表现不如针对每个平台专门格式化的版本。
分发代理(Distribution Agent)通过维护针对各平台的格式规范,并根据内容头部中列出的目标平台,自动将其应用到每一篇已批准的内容来解决这个问题。它绝不在没有平台特定格式的情况下发布到任何平台。它会将每次发布记录在带有时间戳的日志中。并且在执行任何分发操作之前,它会先验证质量批准头部。
## 编排器:连接一切的大脑
编排器(Orchestrator)并不是第五个代理。它是将四个代理连接成一个完整工作流的路由逻辑。
编排器接收传入的任务,将其路由给研究代理(Research Agent),监控研究简报是否出现在 research-briefs 文件夹中,将简报传递给生产代理(Production Agent),监控草稿,将草稿传递给质量代理(Quality Agent),处理批准路径或修订路由路径,并在分发代理记录成功发布时确认完成。
有两个失败场景需要在编排器的设计中进行特殊处理。
质量拒绝会将修订简报路由回生产代理。这是一条预期中的路径,而不是失败状态。系统预料到某些草稿需要修订,并将它们干净地进行路由。
分发失败会记录失败并提醒人工审查。它不会自动重试。分发失败往往有特定情境下的原因,需要人工判断,而在没有这种判断的情况下自动重试分发失败的代理可能会产生重复发布或不断放大的错误。
编排器不做任何创意决策。它只负责路由和管理。正是这一约束让系统保持可预测性。
## 运行你的第一个端到端任务
配置好全部四个代理后,在收件箱文件夹中创建一个任务文件。它应包含主题或内容类型、分发目标平台、这篇内容的任何具体要求,以及截止日期。
用以下命令触发编排器:claude "Read CLAUDE.md. You are the Orchestrator. A new task has arrived in inbox/[TASK-FILENAME]. Begin the workflow. Route to Research Agent first."
然后观察输出文件夹。链条中的每个文件夹会在前一个代理完成工作后收到一个文件。logs/operations.md 文件会在每一步都收到一条记录。第一次端到端运行大约需要十五到三十分钟,取决于主题的复杂程度和研究深度。
运行十次之后,工作流就会变得可预测,每个组件的质量也一目了然。运行五十次之后,系统已经积累了足够的运行历史,能够显现出自身的改进机会——哪些代理产出的结果较弱,需要调整质量配置;哪些平台格式有效,哪些需要调整;哪些主题对研究代理来说轻松,而哪些主题它总是遇到瓶颈。
## 复利机制
一个配置良好的四代理系统不仅仅比单个代理产出更好的内容。它产出的内容会随时间不断改进。
每周运行结束后,花十分钟回顾哪些有效、哪些无效。将性能观察更新到 CLAUDE.md 中。用质量代理给出高分批准的草稿作为示例,改进生产代理的声音画像(voice profile)。凡是质量代理放行了某些事后看来不应通过的内容,就收紧它的评分标准。当某次发布表现不佳时,将平台格式的经验教训添加到分发代理中。
系统会学习你输入的内容。每周你都在向它输入更好的信息,告诉它在你具体的业务中什么才是好的内容。每周产出都会反映出这些信息。
一个人运行一个每周持续校准的四代理团队,可以产出一个四人团队的产出量,而且一致性更高、周转更快,还拥有大多数人工内容团队从未建立的反馈闭环。
第一个代理是最难构建的,因为在某件事完整地跑通端到端之前,整个系统都显得抽象。在第一次完整工作流之后,模式就清晰了。第二个代理之后,架构就讲得通了。第三个和第四个之后,系统就不再像一堆配置的集合,而更像一个每天准时出现、并按你训练的方式执行任务的团队。
这个周末就构建研究代理吧。让它在一个真实的主题上运行。读一读它产出的内容。
仅这一次产出,就能让你比这篇文章中的任何内容都更了解这个系统可以变成什么。
## 相关链接
- [NeilXbt](https://x.com/neil_xbt)
- [@neil_xbt](https://x.com/neil_xbt)
- [5.9K](https://x.com/neil_xbt/status/2056004969430450276/analytics)
- [@anthropic](https://x.com/@anthropic)
- [升级至 Premium](https://x.com/i/premium_sign_up)
- [2026年5月17日 下午9:32](https://x.com/neil_xbt/status/2056004969430450276)
- [5,911 次浏览](https://x.com/neil_xbt/status/2056004969430450276/analytics)
- [查看引用](https://x.com/neil_xbt/status/2056004969430450276/quotes)
---
*导出时间: 2026/5/18 14:31:31*