# Nobody is talking seriously about AI demand
**作者**: Giovanni Cattani
**日期**: 2026-09-01T15:51:31.000Z
**来源**: [https://x.com/giovannicatt3/status/2094815425972539565](https://x.com/giovannicatt3/status/2094815425972539565)
---

AI capex for 2028 is forecast to be larger than the budget of France. Frontier AI labs’ revenue ramp justifies almost any number. Reflexivity in AI demand is a double-edged sword, and it's now a good time to start talking about it.
On his latest podcast, [@dwarkesh_sp](https://x.com/@dwarkesh_sp) wonders why the frontier labs are not spending even more on compute, given expectations of $100B/GW in revenue for frontier intelligence. At these rates, if Anthropic were to monetize all of its expected capacity, it could be at $500B ARR by the end of 2026 - enough to be the third-largest company in the world by revenue.
Nobody is talking seriously about AI demand. Today, analysts model infinite demand for AI for any level of supply, without really breaking down where that demand is coming from. But demand is extremely important, it dictates how much capital frontier labs can invest, which models will be used, and where the value will accrue.
Below is my framework for thinking about AI demand, the case for frontier tokens, and a few adjacent topics.
I am extremely optimistic about future demand for AI. But my framework suggests that demand for frontier tokens may be partly reflexive, fueled by the AI boom itself. This is great and accelerates growth, but it may also spiral in the opposite direction.
All numbers are estimates.
## Tokens as units of time
METR’s long-horizon chart is possibly the most important chart in the world today.
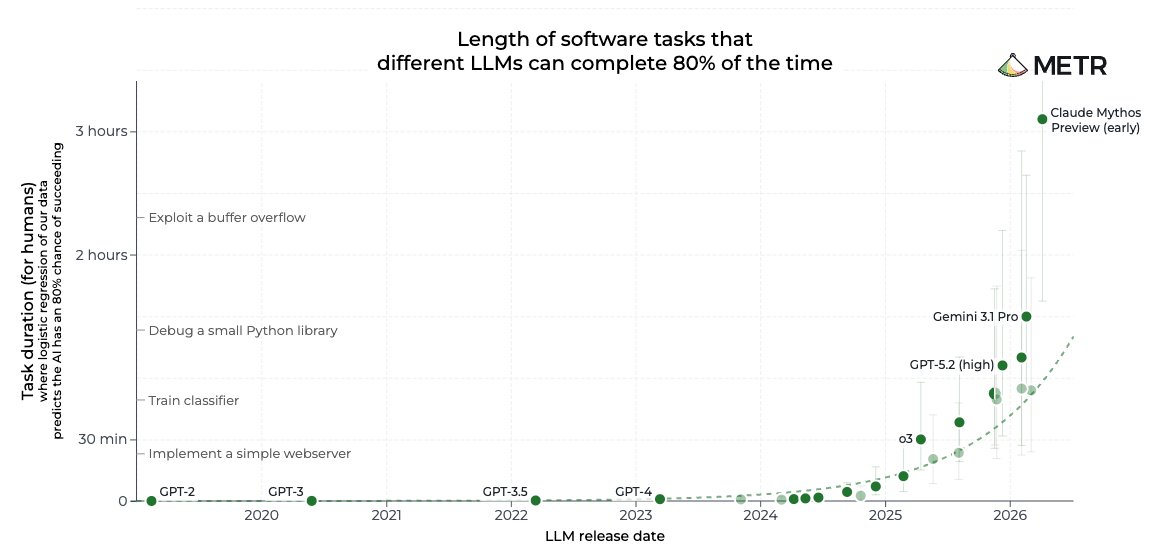
"Length of software tasks that different LLMs can complete 80% of the time" (METR).
Based on the chart, I often say we can think about tokens as units of time. Tokens from each model represent a certain task-horizon, and frontier models have the longest duration. On the chart, o3 is ~ 30 min, while Mythos is ~ 3h. A software engineer using o3 can delegate tasks of up to 30 min, while one using Mythos is significantly sped up - delegating up to 3h.
The chart also provides a framework for structuring human activities. Let’s define:
- Long-horizon vs. short-horizon tasks. “Long-horizon” tasks are the ones that no model succeeds at yet - i.e., above the curve which runs from GPT-2 to Mythos. Everything else, below the curve, is “short-horizon” - effectively, it’s already been solved by AI.
- Bounded vs. unbounded tasks. “Bounded” tasks are those for which, at some point, the curve stops scaling: doing taxes is a bounded task, there’s a limit to its complexity. “Unbounded” tasks are those for which you can always do more: AI research, exploring space, longevity.
## Labor taxonomy
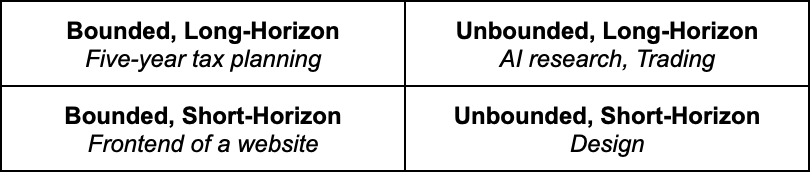
Demand for AI is ultimately demand for labor. And to think about AI demand-side dynamics, we need a new labor taxonomy. Imagine a 2-by-2 matrix, combining the bounded-unbounded categories with long-horizon and short-horizon ones:
Bounded Tasks
For these tasks, AI will soon saturate all benchmarks: one can just trust METR’s trendline. You can easily one-shot a simple frontend (bounded, short-horizon) with any AI model today, while tax planning (bounded, long-horizon) may take another year or two, but we’ll get there.
Bounded tasks are also those for which one would generally like to spend the least amount of time possible (little upside, mostly just a matter of not making mistakes). Here, demand for AI will be extremely high, but converge on the cheapest possible option: the ROI for bounded tasks is mostly a function of cost savings rather than additional revenue (there’s only so much demand for accounting).
Therefore, non-frontier models will dominate: no need to pay for the labs’ margins, great inference providers are available, and post-training of smaller models is effective. And open source models will continue to catch up with the frontier - with a lag that is mostly irrelevant for these tasks, since you just have to automate them once.
Unbounded Tasks
Unbounded tasks are very different: by definition, you can always do more. Exploring space, you can always explore further. Shrinking the node on a chip, you can always shrink it more. Improving AI, you will always be able to make it better. And you can always build more software, and you always need to update trading strategies.
In other words, unbounded tasks are those for which you’d want to spend as much time as possible - that’s why frontier tokens are mostly non-negotiable. These are the kinds of tasks for which one life is often not enough. Due to the very convex, power-law nature of these tasks, the ROI equation is mostly focused on additional revenue rather than cost savings. Going faster is strictly better, and competitive dynamics mean that being first is the single most important thing. You want the best AI model, the best software in the category, the trading strategy with the most alpha.
Frontier models will dominate here. Just like in F1, it doesn't matter if the car only lasts 9 months - you always need to drive the best possible one.
## Reflexive demand
The framework described above is already playing out today, in real time.
My view is that the unprecedented revenue ramp for frontier models is driven by a small set of unbounded, long-horizon tasks. My best guess is: (1) AI R&D, (2) software engineering, and (3) trading.
In that order:
1. AI R&D: Rumor has it that labs today spend 60% of their compute budget on training and only 40% on inference, and it’s fair to assume that 50% of the world’s AI compute capacity is used for training. That would already make AI R&D the clear #1 use case. But I’d also expect a significant portion of the inference bucket to be some form of AI R&D. For instance, runner-up AI labs using frontier models for research and synthetic data generation, or the applied AI companies doing post-training. Let’s say ~ 20% of inference revenue for the frontier AI labs is coming from AI R&D.
2. Software engineering: Software engineering is the obvious task category for AI demand, but the nuance is that a large chunk of the demand for frontier tokens here is coming from startups and AI companies - not traditional F500 companies. Startups are unconstrained by corporate bureaucracy, and can just ship more code, faster. The more they ship, the more money from clients and investors. Additionally, startups compete fiercely with each other for market share, talent, and VC money - and competition forces them to use frontier tokens. The same goes for the mature AI companies (NVIDIA, Amazon, etc.). Let’s say this is another ~ 15% of inference revenue for the frontier AI labs.
3. Trading: If rumors that quant trading firms are some of the largest spenders on frontier AI tokens are true, and if rumors that spend on frontier AI tokens by customers is power-law distributed are true, then it wouldn’t surprise me to see trading as a double-digit percentage of frontier token revenue. This holds for other investment firms as well. Let’s say this too is 15% of inference revenue for the frontier AI labs.
If this attribution is roughly right, then we could say that these three categories of tasks alone account for ~ 50% of frontier AI lab inference revenue.
What is especially interesting is that these three sets share a tight feedback loop between token spend and revenue, such that revenue growth is reflexive:
1. AI R&D: AI labs have consistently translated AI R&D spend into stronger model capabilities, which increase revenue and the ability to raise capital almost instantaneously, and in turn allow the labs to spend more on R&D, and so on;
2. Software engineering: A startup using AI can build a lot of software fast, use that to scale revenue and raise equity, and quickly deploy those resources on even more tokens, and so on;
3. Trading: A trading firm can test the impact of token spend instantaneously on the market, and the higher the profits, the more it can reinvest in AI-powered strategies, and so on.
I describe demand for these tasks as reflexive because they all share the same pattern: larger spend on tokens yields more revenue and a stronger ability to raise capital, which in turn gives them more resources to invest in tokens, and so on - seemingly with no upper bound.
For these tasks, the only constraint is how many tokens you can allocate to the problem. The best companies are the ones that can raise enough capital and allocate it to the right bets - as Anthropic did by being the first to narrow its focus to coding. And the cool thing here is that the total addressable market is roughly infinite - token spend expands the horizon of what we can accomplish, and ROI is driven by higher revenue.
And for these tasks, only frontier models matter. This is what makes frontier models such a great business today. Reflexive demand is only for frontier models, even a six-month lead over open source is more than enough to capture the whole market.
By contrast, bounded tasks are being addressed by dozens and dozens of startups. This is great and inevitable. However, there is no reflexivity for this kind of revenue. You can perhaps cut costs, but there is no immediate feedback loop between lower costs and increased revenue. And a percentage of the cost savings has to be shared with the RLaaS provider, and there’s a ceiling on cost cuts.
On the debate between open and closed source, or on consumer versus enterprise, I will leave the implications to the reader.
## Reflexivity is double-edged
Reflexive demand for frontier tokens is a double-edged sword. Reflexivity is great on the way up, awful on the way down.
The numbers at stake are so large that one has to consider the scenario where, at least temporarily, demand for frontier tokens contracts. In such a case, the issue is that the key demand drivers are correlated and super procyclical.
Correlation
Demand contraction for any of the three key tasks could hit up to 15–20% of frontier token revenue directly and, due to correlation, up to 50%.
Right now: (i) higher revenue for frontier AI drives the equity value of the labs up, which (ii) encourages more investment in VC, a large share of which is spent on tokens, which (iii) increases the value of both labs and startups, and in turn (iv) makes the public markets go up, with the quant firms profiting from it and (v) increasing their spend on frontier tokens. This is just one example, but contagion could start from any of the steps in this loop.
Super procyclicality
These tasks are super procyclical because their demand accelerates as the cycle goes up, and may accelerate in the opposite direction when the cycle goes down.
The state of the market directly impacts demand for all three key drivers. Market going up allows quant trading firms to spend more on tokens, but also grants AI labs and startups more capital to invest.
Under this framework, you may only need one simple trigger to start a reflexive correction downwards. As examples, off the top of my head:
1. Regulation slowing down progress in AI capabilities;
2. Higher interest rates slowing down the buildout;
3. Any exogenous shock.
## A model for AI demand
Obviously, we need a model for frontier token demand.
Super procyclical, heavily correlated demand is fragile. While there have been some bumps along the way, the first ChatGPT release almost coincided with the most recent NASDAQ relative bottom, and both private and public markets have gone up and to the right. We haven’t even explored how a potential slowdown in revenue for the AI labs could impact the markets. It’s unlikely that this will happen anytime soon (next-generation models may be a catalyst for acceleration), but precisely for this reason it is now a great time to think about the topic.
Given current levels of annual AI capex and revenue, a model for AI demand would complement the one we currently have for supply, and inform critical investment decisions - from financing to investing - especially for the companies exposed to the buildout. The framework above may be a starting point.
## Value beyond
A model for demand should also inform capital allocation beyond the buildout. Value will keep accruing to the physical AI supply chain. But while less discussed, value will also accrue to teams going after unbounded, long-horizon tasks.
Within a decade or so, a large chunk of the value generated by bounded tasks today will be taken from human labor and moved to data centers. Financially, one could take labor GDP for those tasks, apply a percentage cut, and move it to the AI supply chain. Non-frontier models will dominate volumes, people may still make money (doing sales, design, and some long-horizon planning), but little value will accrue to the company.
I expect most of the value to accrue to unbounded tasks. And in particular, to teams that can convince the world of their ability to allocate capex (i.e., tokens) to go after these long-horizon, unbounded tasks. This is the domain outside of model capabilities: you can always think with a longer horizon, and we will see founders going after companies that would take several lifetimes to build today. Some of it may be the AI labs themselves, some of it will be new companies.
Today, the market rewards recurring, predictable cash flows - and hates R&D and capex spent with no short-term tangible results in sight. In the future, we may see the inverse: the market will heavily discount repeatable cash flow from bounded tasks, while repricing teams that can wisely allocate capex for the long term.
Elon Musk is not an anomaly - he’s the first example of this. Tesla and SpaceX trade at 10X what an old-fashioned financial analyst would price their cash flows at. But the market routinely prices Elon’s ability to allocate R&D spend to what any reasonable person would consider impossible. With superintelligence, there will be several more Elons.
More to say here - but this is a story for another day.
## 相关链接
- [Giovanni Cattani](https://x.com/giovannicatt3)
- [@giovannicatt3](https://x.com/giovannicatt3)
- [417K](https://x.com/giovannicatt3/status/2094815425972539565/analytics)
- [@dwarkesh_sp](https://x.com/@dwarkesh_sp)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [11:51 PM · Sep 1, 2026](https://x.com/giovannicatt3/status/2094815425972539565)
- [417.2K Views](https://x.com/giovannicatt3/status/2094815425972539565/analytics)
- [View quotes](https://x.com/giovannicatt3/status/2094815425972539565/quotes)
---
*导出时间: 2026/9/2 10:50:48*
---
## 中文翻译
# 没有人在认真讨论AI需求
**作者**: Giovanni Cattani
**日期**: 2026-09-01T15:51:31.000Z
**来源**: [https://x.com/giovannicatt3/status/2094815425972539565](https://x.com/giovannicatt3/status/2094815425972539565)
---

2028年的AI资本支出预计将超过法国的国家预算。前沿AI实验室的收入增长速度几乎可以为任何数字提供合理性。AI需求中的反身性是一把双刃剑,现在是开始讨论它的时候了。
在他最新的播客中,[@dwarkesh_sp](https://x.com/@dwarkesh_sp) 疑惑为什么前沿实验室不在算力上投入更多,毕竟前沿智能的预期收入可达每吉瓦1000亿美元。按这个比率,如果Anthropic将其所有预期产能全部变现,到2026年底其ARR可能达到5000亿美元——足以成为全球按收入计第三大的公司。
没有人在认真讨论AI需求。如今,分析师们为AI建模时假定无论供给处于何种水平需求都是无限的,却并没有真正拆解这些需求究竟来自哪里。但需求极其重要,它决定了前沿实验室能投入多少资本、哪些模型会被使用,以及价值将在何处积累。
以下是我思考AI需求、前沿token的案例以及一些相关议题的框架。
我对AI的未来需求极为乐观。但我的框架表明,对前沿token的需求可能部分是反身性的,由AI热潮本身推动。这很好且能加速增长,但它也可能朝相反的方向螺旋下行。
所有数字均为估算。
## Token作为时间单位
METR的长时程图表可能是当今世界上最重要的图表。

"不同LLM能够以80%成功率完成的软件任务时长"(METR)。
基于这张图表,我常说我们可以把token看作时间单位。每个模型的token代表一定的任务时程,而前沿模型拥有最长的时长。在图表上,o3约为30分钟,而Mythos约为3小时。使用o3的软件工程师可以委派最长30分钟的任务,而使用Mythos的工程师则被显著提速——可以委派最长3小时的任务。
这张图表也为构建人类活动的分类提供了框架。让我们定义:
- 长时程 vs. 短时程任务。“长时程”任务是尚无任何模型能成功的任务——即位于从GPT-2到Mythos那条曲线之上的任务。其他一切位于曲线之下的任务都是“短时程”的——实际上,它们已被AI解决。
- 有界 vs. 无界任务。“有界”任务是那些曲线在某一点停止扩展的任务:报税是一项有界任务,其复杂度存在上限。“无界”任务是那些总能做得更多的任务:AI研究、太空探索、长寿研究。
## 劳动分类学
对AI的需求归根结底是对劳动力的需求。要思考AI需求侧的动态,我们需要一种新的劳动分类学。想象一个2x2矩阵,将有界-无界类别与长时程、短时程类别相结合:

有界任务
对于这些任务,AI很快就会在所有基准测试上饱和:你只需相信METR的趋势线即可。今天,你可以用任何AI模型轻松地一次性生成一个简单的前端页面(有界、短时程),而税务规划(有界、长时程)可能还需要一两年,但我们终将达到。
有界任务也是人们通常希望花费尽可能少时间完成的任务(几乎没有上行空间,主要只是不犯错的问题)。在这里,对AI的需求将极高,但会收敛于最便宜的选项:有界任务的ROI主要是成本节省的函数,而非额外收入的函数(对会计的需求也就那么多)。
因此,非前沿模型将占主导:无需为实验室的利润买单,优秀的推理服务提供商随处可得,而较小模型的后训练也很有效。开源模型将继续追赶前沿——其滞后期对这些任务基本无关紧要,因为你只需将它们自动化一次。
无界任务
无界任务则截然不同:根据定义,你总能做得更多。探索太空,你总能探索得更远。缩小芯片上的节点,你总能缩得更小。改进AI,你总能把它做得更好。而你总能构建更多软件,你总需要更新交易策略。
换句话说,无界任务是你希望投入尽可能多时间的任务——这就是为什么前沿token在很大程度上无可替代。这类任务往往一辈子都不够用。由于这些任务极其凸性、呈幂律分布的特性,其ROI方程主要着眼于额外收入而非成本节省。更快就是严格意义上的更好,而竞争动态意味着成为第一是最重要的事。你想要最好的AI模型、该类别中最好的软件、拥有最多alpha的交易策略。
前沿模型将在这里占主导。就像F1一样,赛车只能跑9个月并不重要——你总是需要开最好的那一辆。
## 反身性需求
上述框架如今正在实时上演。
我的观点是,前沿模型前所未有的收入增长由一小部分无界、长时程任务驱动。我最好的猜测是:(1)AI研发,(2)软件工程,(3)交易。
按顺序来说:
1. AI研发:传闻称,如今实验室将其算力预算的60%用于训练,只有40%用于推理,并且可以合理假设全球AI算力产能的50%被用于训练。这已经使AI研发成为明确的头号用例。但我还预计推理那一部分中相当大的比例也是某种形式的AI研发。例如,排名靠前的AI实验室使用前沿模型进行研究和合成数据生成,或者从事后训练的应用AI公司。假设前沿AI实验室约20%的推理收入来自AI研发。
2. 软件工程:软件工程是AI需求最明显的任务类别,但其中的微妙之处在于,这里对前沿token的很大一部分需求来自初创公司和AI公司——而非传统财富500强企业。初创公司不受企业官僚体制的约束,可以更快地交付更多代码。交付得越多,从客户和投资者那里获得的钱就越多。此外,初创公司在市场份额、人才和风投资金方面彼此激烈竞争——而竞争迫使它们使用前沿token。成熟AI公司(NVIDIA、亚马逊等)也是如此。假设这是前沿AI实验室推理收入的另外约15%。
3. 交易:如果“量化交易公司是前沿AItoken的最大支出者之一”的传闻属实,并且如果“客户在前沿AItoken上的支出呈幂律分布”的传闻属实,那么交易占前沿token收入的两位数百分比也不会让我感到惊讶。这对其他投资公司同样适用。假设这也是前沿AI实验室推理收入的15%。
如果这个归因大致正确,那么我们可以说,仅这三类任务就占了前沿AI实验室推理收入的约50%。
尤其有趣的是,这三类任务在token支出与收入之间共享一个紧密的反馈回路,使得收入增长具有反身性:
1. AI研发:AI实验室持续将AI研发支出转化为更强的模型能力,这几乎立即提升收入和融资能力,进而使实验室能投入更多研发资金,如此循环;
2. 软件工程:一家使用AI的初创公司可以快速构建大量软件,以此扩大收入并进行股权融资,然后迅速将这些资源部署到更多的token上,如此循环;
3. 交易:一家交易公司可以在市场上即时测试token支出的影响,利润越高,就越能在AI驱动的策略上再投资,如此循环。
我将这些任务的需求描述为反身性的,因为它们都遵循同一模式:更多的token支出带来更多收入和更强的融资能力,这反过来又给予它们更多资源投入token,如此循环—— seemingly 没有上限。
对于这些任务,唯一的约束是你能为此问题分配多少token。最好的公司是那些能够筹集足够资本并将其分配到正确押注上的公司——就像Anthropic率先将焦点收窄到编程上那样。而这里很酷的一点是,总可寻址市场近乎无限——token支出拓展了我们所能够完成的范围,ROI由更高的收入驱动。
对于这些任务,只有前沿模型才重要。这正是前沿模型如今成为如此好生意的原因。反身性需求只针对前沿模型,即使只领先开源六个月,也足以占据整个市场。
相比之下,有界任务正在被成百上千家初创公司解决。这很好,也是不可避免的。然而,这类收入不存在反身性。你或许能削减成本,但在更低的成本与更高的收入之间并不存在即时反馈回路。而且成本节省的一部分必须与RLaaS提供商分享,成本削减也存在上限。
关于开源与闭源的争论,或者消费级与企业级的争论,其中的含义我留给读者自行思考。
## 反身性是双刃剑
对前沿token的反身性需求是一把双刃剑。反身性在上升时很美好,在下行时则很可怕。
所涉数字如此之大,以至于必须考虑到至少暂时出现前沿token需求收缩的情景。在这种情况下,问题在于关键需求驱动因素是相互关联的,且极度顺周期。
相关性
三大关键任务中任何一项的需求收缩都可能直接冲击前沿token收入的15–20%,而由于相关性,最高可冲击50%。
现在:(i)前沿AI收入的提高推高了实验室的股权价值,(ii)这鼓励了更多风投投资,其中很大一部分花在token上,(iii)这提升了实验室和初创公司的价值,进而(iv)推动公开市场上涨,量化公司从中获利并(v)增加其在前沿token上的支出。这只是一个例子,但传染可以从这个循环中的任何一环开始。
超级顺周期性
这些任务是超级顺周期的,因为其需求随着周期上行而加速,也可能在周期下行时向相反方向加速。
市场状态直接影响所有三个关键驱动因素的需求。市场上涨使量化交易公司能够在token上花更多钱,同时也给予AI实验室和初创公司更多可投资的资本。
在这个框架下,你可能只需要一个简单的触发因素就能引发反身性向下修正。举几个我随口能想到的例子:
1. 监管拖慢AI能力进步;
2. 更高的利率拖慢建设进程;
3. 任何外生冲击。
## 一个AI需求模型
显然,我们需要一个前沿token需求模型。
超级顺周期、高度相关的需求是脆弱的。虽然过程中出现过一些波折,但ChatGPT首次发布几乎与纳斯达克最近的相对底部重合,且私募和公开市场都在持续走高。我们甚至还没有探索AI实验室收入潜在的放缓会如何影响市场。这种情况不太可能很快发生(下一代模型可能成为加速的催化剂),但恰恰因为这个原因,现在是思考这一话题的绝佳时机。
鉴于目前AI年度资本支出和收入水平,一个AI需求模型将补充我们现有的供给模型,并为关键投资决策提供参考——从融资到投资——尤其对于暴露于建设潮中的公司。上述框架或许可以作为一个起点。
## 更远的价值
需求模型还应为建设潮之外的资本配置提供参考。价值将继续积累于物理AI供应链。但尽管讨论较少,价值也将积累于追求无界、长时程任务的团队。
在大约十年之内,当今由有界任务产生的价值中很大一部分将从人类劳动转移到数据中心。从财务角度看,人们可以取这些任务的劳动GDP,按一定比例折减,并将其转移到AI供应链。非前沿模型将主导用量,人们可能仍能赚钱(做销售、设计和一些长时程规划),但公司能积累的价值甚少。
我预计大部分价值将积累于无界任务。尤其是那些能够说服世界相信其有能力将资本支出(即token)配置到这些长时程、无界任务上的团队。这是模型能力之外的领域:你总能以更长的时程思考,我们将看到创始人去追求那些以今天的速度需要好几辈子才能建成的公司。其中一些可能就是AI实验室本身,另一些将是新公司。
如今,市场奖励经常性、可预测的现金流——并厌恶在短期内看不到有形成果的研发和资本支出。在未来,我们可能看到相反的情况:市场将大幅折价有界任务的可重复现金流,同时为能够明智地长期配置资本支出的团队重新定价。
埃隆·马斯克不是异类——他是这一现象的首个例子。特斯拉和SpaceX的估值是传统财务分析师按其现金流定价的10倍。但市场一直在为埃隆将研发支出配置到任何理性之人都会认为不可能的事情上的能力定价。有了超级智能,将会出现更多个埃隆。
这里还有更多可说的——但那是另一天的故事了。
## 相关链接
- [Giovanni Cattani](https://x.com/giovannicatt3)
- [@giovannicatt3](https://x.com/giovannicatt3)
- [417K](https://x.com/giovannicatt3/status/2094815425972539565/analytics)
- [@dwarkesh_sp](https://x.com/@dwarkesh_sp)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [11:51 PM · Sep 1, 2026](https://x.com/giovannicatt3/status/2094815425972539565)
- [417.2K Views](https://x.com/giovannicatt3/status/2094815425972539565/analytics)
- [View quotes](https://x.com/giovannicatt3/status/2094815425972539565/quotes)
---
*导出时间: 2026/9/2 10:50:48*