# How to Make a Coding Agent Smarter Without Touching the Model or the Prompt
**作者**: AlphaSignal AI
**日期**: 2026-04-30T17:14:18.000Z
**来源**: [https://x.com/AlphaSignalAI/status/2049900160080077229](https://x.com/AlphaSignalAI/status/2049900160080077229)
---
A new paper evolves a coding agent's tools, middleware, and memory automatically. It beats every human-tuned harness in 32 hours.
The system prompt alone regresses. Editing it as the only adaptation surface drops pass@1 by 2.3 points on Terminal-Bench 2.
AHE (Agentic Harness Engineering) is the framework that produced this finding. It holds the base model frozen, evolves all seven harness components automatically against rollouts, and lifts a bash-only seed from 69.7% to 77.0% in ten iterations.
The result beats human-designed Codex-CLI (71.9%), the prompt-only self-evolver ACE (68.9%), and the trajectory-feedback baseline TF-GRPO (72.3%) on the same 89-task panel in 32 hours.
The transfer ships the evolved workspace unchanged: 12% fewer tokens on SWE-bench-verified, +5.1 to +10.1pp across four other model families, with the largest gain on the weakest base.
> “If you didn’t quite catch that intro, you should definitely check out our Harness Engineering workshop. If you did follow along, you should still give it a look anyway!” more details at the end.
## Context
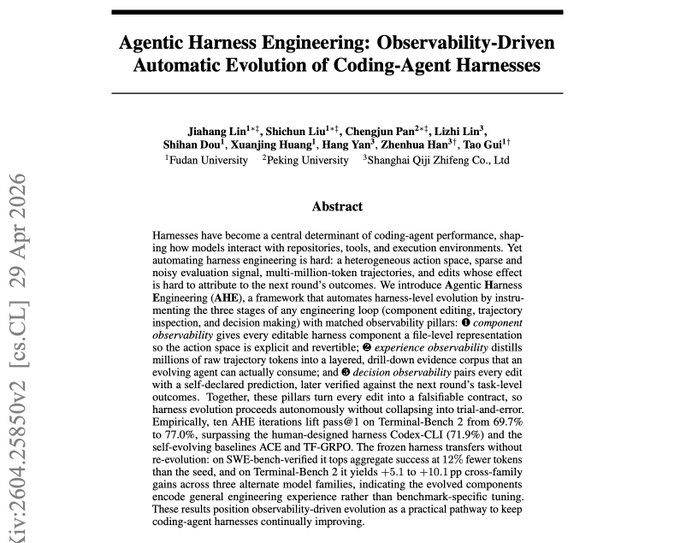
The paper is authored by Jiahang Lin, Shichun Liu, Chengjun Pan, and collaborators at Fudan University, Peking University, and Shanghai Qiji Zhifeng, titled "Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses" (arXiv 2604.25850, April 28, 2026, MIT-licensed code).
A coding agent's harness is everything around the model: system prompt, tool definitions, middleware, skills, sub-agents, memory. Production teams hand-tune these by inspecting trajectories and editing files. The manual loop is slow and the gains scatter across undocumented decisions.
Prior automated work optimizes one component at a time, almost always the prompt or an in-context playbook (ACE, GEPA, DSPy) or the trajectory distribution (TF-GRPO, GRPO variants). Tools, middleware, and memory stay closed.
AHE evolves the full harness as a combinatorial whole and treats every edit as a falsifiable contract verified against the next round's task outcomes.
## How AHE works
The central design move is that every phase of the loop produces structured, file-level artifacts another agent can read.
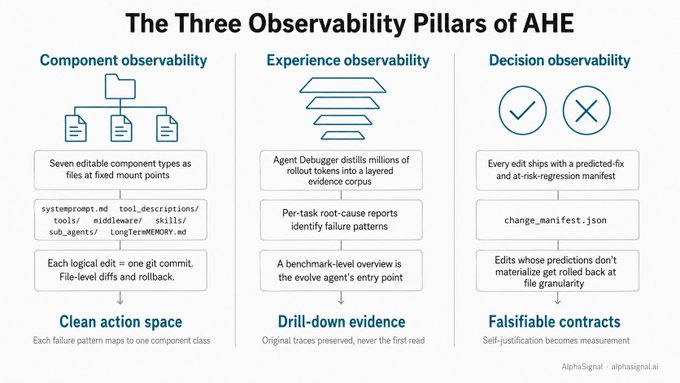
Component observability. The harness is instantiated on the NexAU framework, which exposes seven editable component types as files at fixed mount points: system prompt, tool description, tool implementation, middleware, skill, sub-agent configuration, and long-term memory. Each failure pattern maps cleanly to one component class. Each logical edit becomes one git commit, so file-level diffs and rollback come for free.
The seed harness is deliberately minimal, just a single bash tool with no middleware or skills, so every component the loop adds has to earn its place against measured rollouts.
Experience observability. The Agent Debugger framework distills raw rollout traces (millions of tokens) into a layered evidence corpus. Each trajectory message lives in its own file. Per-task root-cause reports identify failure patterns.
A benchmark-level overview aggregates every report into the evolve agent's entry point. Original traces stay accessible for verification but are never the first read.
Decision observability. Every edit ships with a change_manifest.json entry naming the failure pattern it addresses, the predicted task fixes, the at-risk regressions, and the constraint level (prompt, tool description, tool implementation, middleware, skill).
In the next round, the loop intersects predicted fixes and regressions against observed task-level deltas. Edits whose predictions don't materialize get rolled back automatically at file granularity. Self-justification becomes measurement.
## The outer loop

The plain pseudocode is included in appendix section at the end
The load-bearing choice is that attribution runs before distillation. The verdict for prior edits lands inside the evidence corpus the evolve agent reads, binding each manifest entry as a contract instead of a rationale.
The evolve agent writes only inside workspace/. The runs directory, tracer, verifier, and LLM config are read-only. The seed system prompt is non-deletable.
These restrictions block the shortcuts an unconstrained self-modifier would take, like disabling the verifier or raising the reasoning budget, and keep every recorded gain attributable to harness edits.
## Evidence
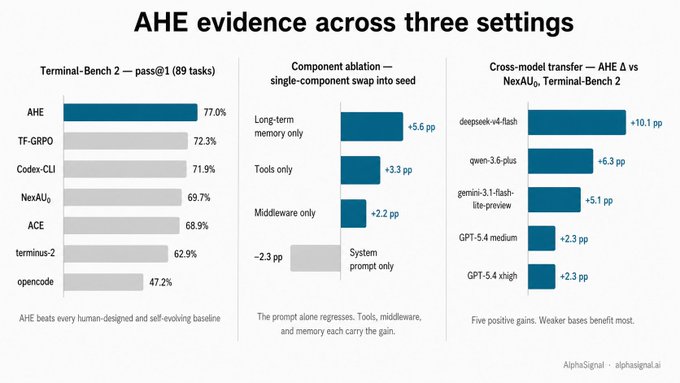
Ten AHE iterations on Terminal-Bench 2 (89 tasks, k=2 rollouts, GPT-5.4 high reasoning, ~32 hours total runtime) lift pass@1 from 69.7% to 77.0%. AHE outperforms three human-designed harnesses (opencode 47.2%, terminus-2 62.9%, Codex-CLI 71.9%) and both self-evolve baselines (ACE 68.9%, TF-GRPO 72.3%).
On Easy and Medium tiers AHE leads cleanly. On Hard it slips to 53.3% behind Codex-CLI's 56.7%, traced to component interference rather than missing capability.
Cross-benchmark transfer holds without re-evolution. On SWE-bench-verified (500 tasks across seven repos), AHE achieves the highest aggregate at 75.6% while spending 12% fewer tokens than the seed, 21% fewer than TF-GRPO, and 32% fewer than ACE.
Gains concentrate on django and sphinx-doc, the two largest, most token-expensive repos. Cost efficiency on SWE-bench (Succ/Mtok): AHE 1.64, NexAU₀ 1.43, TF-GRPO 1.27, ACE 1.10.
Cross-model transfer is the strongest evidence that the harness encodes general engineering experience. The same evolved workspace, evaluated unchanged on five alternate bases, produces five positive gains: +10.1pp on deepseek-v4-flash (51.7→61.8), +6.3pp on qwen-3.6-plus (56.2→62.5), +5.1pp on gemini-3.1-flash-lite-preview (36.5→41.6), and +2.3pp on both GPT-5.4 medium and xhigh.
Weaker bases benefit more because they lean on the coordination patterns AHE has fixed inside tools, middleware, and memory. Stronger bases re-derive the same coordination from the prompt cheaply.
The component ablation is the load-bearing finding. Swapping a single AHE component into the bash-only seed: memory alone +5.6pp, tools alone +3.3pp, middleware alone +2.2pp, system prompt alone −2.3pp. The harness components ACE and TF-GRPO never edit are exactly where the gain lives.
## Four case studies
The paper traces four trajectories from failure to fix across iterations 2, 5, 6, and 8. Each peak in the best-so-far curve lines up with one trajectory.
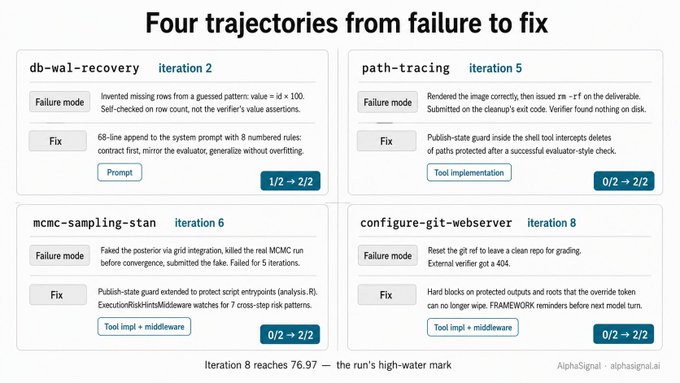
db-wal-recovery (iteration 2). The agent had to reconstruct a SQLite database from a corrupted write-ahead log. The failing rollout invented missing rows from a guessed pattern (value = id × 100) and self-checked on row count instead of the verifier's value assertions.
The fix was a 68-line append to the system prompt with eight numbered rules: contract first, mirror the evaluator, generalize without overfitting visible samples. None of the rules mentions SQLite, WAL, or this task. The rules were proposed for a different cluster of partial-pass tasks and carried over by accident, flipping db-wal-recovery 1/2 → 2/2 and holding 2/2 every iteration after.
path-tracing (iteration 5). The agent rendered a correct image, self-checked it, then issued rm -rf as a final tidy-up step and submitted on the cleanup's exit code. The verifier found nothing on disk and rejected the rollout. The seed prompt already had advice against destroying verified state, but no execution-time mechanism enforced it.
The iteration-5 fix installed a publish-state guard inside the shell tool: when the shell observes a successful evaluator-style check, it parses the acceptance command for protected paths and intercepts later deletes. Task flips 0/2 → 2/2.
mcmc-sampling-stan (iteration 6). The agent computed a fake posterior via grid integration, fired the real MCMC run as a background job, killed it before convergence "to preserve the deliverables," and submitted the fake. This failed for five straight iterations.
Iteration 6 closed it with two components working together: the publish-state guard extended to protect script entrypoints (analysis.R), and a new ExecutionRiskHintsMiddleware watching the live command history for seven cross-step risk patterns (proxy validators, shallow validation, localhost-only checks, repeated retries against the same error, among others). Task flips 0/2 → 2/2 and stays.
configure-git-webserver (iteration 8). The agent reached a working webserver, self-checked via localhost curl, then issued ALLOW_POST_SUCCESS_RESET-prefixed cleanup commands that wiped the live web root and reset the git ref "to leave a clean repo for grading." The external verifier got a 404.
Iteration 8 patched the override token: deletion of protected outputs and reset of protected roots became hard blocks the token can no longer wipe. A before_model hook promoted execution-risk warnings into FRAMEWORK reminders visible on the next model turn. Iteration 8's overall score reached 76.97, the run's high-water mark.
The pattern across all four cases: prompts say what to avoid, but execution-time enforcement is what changes outcomes. Three of the four winning fixes shipped at the tool-implementation or middleware level.
## Limitations
Hard-tier slip. AHE marginally trails Codex-CLI on Hard (53.3% vs 56.7%). Memory, middleware, and the system prompt all push toward the same closure-style verification, which spends turn budget on redundant re-checks. Swapping AHE's long-term memory alone into the seed (no other components) already surpasses Codex on Hard.
Non-additive component interaction. Three positive single-component gains sum to +11.1pp, but full AHE only achieves +7.3pp. Stacking the components costs 3.8pp. The evolve agent optimizes an aggregate dominated by 55 Medium tasks, so it converges to a Medium-heavy trade-off that returns part of the Hard memory effect.
Regression blindness. Across nine evaluation rounds, the evolve agent issued 43 unique regression predictions and only 5 landed (precision 11.6%). 40 unforeseen regressions actually occurred (recall 11.1%). Fix predictions are 5× above random. Regression predictions are barely 2× above.
The agent can justify why an edit should help. It cannot reliably name what the same edit will break.
Benchmark scope. The full evolution run is on Terminal-Bench 2. Cross-benchmark and cross-model transfer evidence is encouraging, but a non-Terminal-Bench-2 evolution run is what would close the benchmaxxing question. The authors flag this and call it out as a generalization hazard.
So the best recommendation is to treat AHE as a controlled research prototype that already produces a frozen harness worth studying, while waiting for evolution runs on a second benchmark before adopting the framework as a deployment-grade self-improvement loop.
## AlphaSignal Take
Worth Watching. The framework does what it claims, the receipts (change manifests + auto-rollback) replace self-justification with measurement, and the cross-model transfer is the strongest signal yet that harness structure encodes coordination patterns weaker bases cannot re-derive cheaply.
The two unfinished pieces are the regression-blindness gap and a second-benchmark evolution run. Closing either pushes it from research-prototype to production-grade.
The forward-looking entity to watch is NexAU, the substrate the loop runs on, since the framework's reach scales with how many production agents adopt the file-level component contract.
## Who benefits, who doesn't
Benefits: teams running long-horizon coding agents on multi-step terminal or repository workflows, anyone hand-tuning prompts beyond a rough first pass, ML engineers evaluating self-evolution loops as an alternative to fine-tuning, and researchers studying test-time adaptation surfaces that don't require gradient updates.
Skips: teams whose agent loop is short-horizon API-call chains, anyone without rollout traces or a verifier with binary pass/fail signal, and teams already invested in prompt-only frameworks (ACE, GEPA, DSPy) that cannot open the harness components where the gain lives.
## Practitioner implication
ML engineers can now evolve a coding agent's tools, middleware, and memory automatically against a benchmark, now that observability primitives turn each component edit into a falsifiable contract.
## The Workshop
We’re hosting a session on Harness Engineering to move beyond simple prompts and context. It’s about building the constraints that let agents work autonomously.
May 7th, 11am PT. Led by AJ Joobandi (Augment Code). 20 seats, $150.
You’ll learn why agents break, how to design robust success metrics, and walk away with a plug-and-play harness file.
→ Grab your seat here
## Links
- Paper on arXiv (paper, ~45 min read)
- GitHub repo (code, MIT license)
- Agent Debugger blog (background, ~10 min read)
- NexAU framework (substrate the loop runs on)
Follow @AlphaSignalAI for more content like this.
Subscribe at AlphaSignal.ai for daily AI signals. Read by 280,000+ developers.
## Appendix
```
Algorithm 1: AHE outer loop
H_best ← H₀ # bash-only NexAU₀ seed
for t = 1 to N do
T_t ← Rollout(M, H_{t-1}, D, k) # phase 1: k≥2 rollouts per task
T̃_t ← Clean(T_t) # phase 2: drop base64, dedup tool output
if t ≥ 2 then # phase 3: attribute prior manifest, then rollback
V_t ← Attribute(C_{t-1}, T_{t-1}, T_t)
H_{t-1} ← Rollback(H_{t-1}, V_t)
R_t ← AgentDebugger(T̃_t) # phase 4: layered distillation
(H_t, C_t) ← Evolve(H_{t-1}, R_t, V_t) # phase 5: workspace edits + new manifest
Commit(H_t, C_t, t) # phase 6: tag iteration in git
if Pass@1(T_t) > Pass@1(H_best) then
H_best ← H_t
return H_best
```
## 相关链接
- [克斯马 reposted](https://x.com/mrbleem_eth)
- [AlphaSignal AI](https://x.com/AlphaSignalAI)
- [@AlphaSignalAI](https://x.com/AlphaSignalAI)
- [4.4K](https://x.com/AlphaSignalAI/status/2049900160080077229/analytics)
- [Harness Engineering workshop](https://luma.com/t24o902x)
- [here](https://lu.ma/t24o902x)
- [Paper on arXiv](https://arxiv.org/abs/2604.25850)
- [GitHub repo](https://github.com/china-qijizhifeng/agentic-harness-engineering)
- [Agent Debugger blog](https://dawning-road.github.io/blog/agent-debugger)
- [NexAU framework](https://github.com/nex-agi/NexAU)
- [@AlphaSignalAI](https://x.com/@AlphaSignalAI)
- [AlphaSignal.ai](https://alphasignal.ai/)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [1:14 AM · May 1, 2026](https://x.com/AlphaSignalAI/status/2049900160080077229)
- [4,475 Views](https://x.com/AlphaSignalAI/status/2049900160080077229/analytics)
---
*导出时间: 2026/5/1 10:09:06*
---
## 中文翻译
# 如何在不改动模型或提示词的情况下让编程代理更智能
**作者**: AlphaSignal AI
**日期**: 2026-04-30T17:14:18.000Z
**来源**: [https://x.com/AlphaSignalAI/status/2049900160080077229](https://x.com/AlphaSignalAI/status/2049900160080077229)
---

一篇新论文实现了对编程代理的工具、中间件和记忆的自动进化。它在32小时内击败了所有人工调优的挂载系统。
仅调整系统提示词甚至会导致性能回退。如果只将编辑提示词作为唯一的适配手段,在 Terminal-Bench 2 上的 pass@1 指标会下降 2.3 分。
AHE(Agentic Harness Engineering,代理挂载系统工程)是得出这一发现的框架。它保持基础模型冻结,自动进化所有七个挂载组件以对抗推演,并在十次迭代中将仅限 Bash 的种子配置从 69.7% 提升至 77.0%。
该结果在 32 小时内,基于相同的 89 个任务面板,击败了人工设计的 Codex-CLI(71.9%)、纯提示词自进化器 ACE(68.9%)以及轨迹反馈基线 TF-GRPO(72.3%)。
迁移过程将进化出的工作空间原封不动地移植:在 SWE-bench-verified 上 token 使用量减少了 12%,在另外四个模型族上提升了 5.1 至 10.1 个百分点,且在最弱的基座模型上收益最大。
> “如果您刚才没完全看懂这篇简介,一定要来看看我们的挂载系统工程研讨会。如果您已经跟上了,无论如何还是应该看一看!” 更多详情见文末。

## 背景
该论文由复旦大学、北京大学的 Jiahang Lin、Shichun Liu、Chengjun Pan 以及上海启致锋的合作者撰写,题为“代理挂载系统工程:可观测性驱动的编程代理挂载自动进化”(Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses,arXiv 2604.25850,2026年4月28日,MIT 许可代码)。
编程代理的挂载是指模型周围的一切:系统提示词、工具定义、中间件、技能、子代理、记忆。生产团队通过检查轨迹和编辑文件来进行手工微调。这种人工循环缓慢,且收益分散在许多未记录的决策中。
之前的自动化工作通常一次只优化一个组件,几乎总是提示词或上下文内的剧本(ACE、GEPA、DSPy),或者是轨迹分布(TF-GRPO、GRPO 变体)。工具、中间件和记忆则保持封闭。
AHE 将完整的挂载作为一个组合整体进行进化,并将每一次编辑视为一份可证伪的合约,根据下一轮的任务结果进行验证。
## AHE 的工作原理
核心设计在于,循环的每个阶段都会产生结构化的、文件级别的人工制品,供另一个代理读取。

**组件可观测性**。挂载在 NexAU 框架上实例化,该框架将七种可编辑的组件类型作为文件暴露在固定的挂载点:系统提示词、工具描述、工具实现、中间件、技能、子代理配置和长期记忆。每种失败模式都清晰地映射到一个组件类别。每个逻辑编辑都会变成一次 git 提交,因此文件级别的差异和回滚是免费附带的。
种子挂载故意做得极简,只有一个 Bash 工具,没有中间件或技能,因此循环添加的每个组件都必须在实测推演中证明自己的价值。
**经验可观测性**。Agent Debugger 框架将原始推演轨迹(数百万个 token)提炼为分层证据语料库。每条轨迹消息都位于各自的文件中。按任务的根因报告会识别失败模式。
基准级别的概览将每份报告聚合成进化代理的入口点。原始轨迹仍然可访问以供验证,但绝不作为首选阅读内容。
**决策可观测性**。每次编辑都附带一条 change_manifest.json 条目,命名其解决的失败模式、预测的任务修复、面临风险的回退以及约束级别(提示词、工具描述、工具实现、中间件、技能)。
在下一轮中,循环将预测的修复和回退与观察到的任务级别差值进行交叉比对。预测未兑现的编辑会自动按文件粒度回滚。自辩解变成了可度量的指标。
## 外层循环

简单的伪代码包含在文末的附录部分
关键的选择在于归因在提炼之前运行。先前编辑的结论被存放入进化代理读取的证据语料库中,将每个清单条目绑定为一份合约,而非理由。
进化代理仅在 workspace/ 内进行写入。runs 目录、tracer、verifier 和 LLM 配置均为只读。种子系统提示词不可删除。
这些限制阻断了不受约束的自我修改器可能采取的捷径,例如禁用验证器或增加推理预算,并确保每一次记录下来的增益都可归因于挂载编辑。
## 证据

在 Terminal-Bench 2 上进行的十次 AHE 迭代(89 个任务,k=2 次推演,GPT-5.4 高推理模式,总运行时间约 32 小时)将 pass@1 从 69.7% 提升至 77.0%。AHE 的表现优于三个人工设计的挂载系统(opencode 47.2%、terminus-2 62.9%、Codex-CLI 71.9%)以及两个自进化基线(ACE 68.9%、TF-GRPO 72.3%)。
在简单和中等难度层级上,AHE 遥遥领先。在困难层级上,它下滑至 53.3%,落后于 Codex-CLI 的 56.7%,追踪表明原因在于组件干扰而非能力缺失。
跨基准迁移无需重新进化即可保持效果。在 SWE-bench-verified(跨越 7 个代码库的 500 个任务)上,AHE 取得了最高的总分 75.6%,同时使用的 token 比种子配置少 12%,比 TF-GRPO 少 21%,比 ACE 少 32%。
收益集中在 django 和 sphinx-doc 这两个规模最大、token 成本最高的代码库上。SWE-bench 上的成本效率:AHE 1.64,NexAU₀ 1.43,TF-GRPO 1.27,ACE 1.10。
跨模型迁移是挂载系统编码通用工程经验的最有力证据。同一个进化出的工作空间,在五个不同的基座模型上未经修改进行评估,产生了五个正向增益:在 deepseek-v4-flash 上提升 10.1pp(51.7→61.8),在 qwen-3.6-plus 上提升 6.3pp(56.2→62.5),在 gemini-3.1-flash-lite-preview 上提升 5.1pp(36.5→41.6),在 GPT-5.4 medium 和 xhigh 上各提升 2.3pp。
较弱的基座模型受益更多,因为它们依赖 AHE 在工具、中间件和记忆中固化的协调模式。较强的基座模型可以廉价地从提示词中重新推导出相同的协调逻辑。
组件消融实验是支撑性的发现。将单个 AHE 组件交换到仅限 Bash 的种子配置中:仅记忆就提升 5.6pp,仅工具提升 3.3pp,仅中间件提升 2.2pp,仅系统提示词反而下降 2.3pp。收益所在之处正是 ACE 和 TF-GRPO 从未编辑过的挂载组件。
## 四个案例研究
论文追踪了四次从失败到修复的轨迹,分别在第 2、5、6 和 8 次迭代中。目前最佳曲线中的每一个峰值都与其中一条轨迹对齐。

**db-wal-recovery(第 2 次迭代)**。代理必须从损坏的预写日志中重建 SQLite 数据库。失败的推演根据猜测的模式(value = id × 100)虚构了缺失的行,并检查行数而非验证器的值断言。
修复方案是在系统提示词中追加了 68 行内容,包含八条编号规则:优先合约、镜像评估器、在不过度拟合可见样本的情况下进行泛化。这些规则都没有提到 SQLite、WAL 或该任务。这些规则是为另一组部分通过的任务提出的,并被意外沿用,将 db-wal-recovery 从 1/2 翻转为 2/2,并在随后的每次迭代中都保持 2/2。
**path-tracing(第 5 次迭代)**。代理渲染了正确的图像,进行了自检,然后发出了 `rm -rf` 作为最后的清理步骤,并基于清理的退出代码提交了结果。验证器在磁盘上什么也没找到,拒绝了该推演。种子提示词已有关于不要销毁已验证状态的建议,但没有执行时的机制来强制执行。
第 5 次迭代的修复方案在 shell 工具内部安装了一个发布状态保护器:当 shell 观察到成功的评估器风格检查时,它会解析接受命令以获取受保护的路径,并拦截后续的删除操作。任务从 0/2 翻转为 2/2。
**mcmc-sampling-stan(第 6 次迭代)**。代理通过网格积分计算了一个虚假的后验概率,将真正的 MCMC 运行作为后台任务启动,在收敛前将其终止“以保护交付物”,并提交了虚假结果。这连续失败了五次迭代。
第 6 次迭代通过两个组件协同工作解决了这个问题:发布状态保护器被扩展以保护脚本入口点(analysis.R),以及一个新的 ExecutionRiskHintsMiddleware 监视实时命令历史中的七种跨步骤风险模式(代理验证器、浅层验证、仅本地主机检查、针对同一错误的重复重试等)。任务从 0/2 翻转为 2/2 并保持稳定。
**configure-git-webserver(第 8 次迭代)**。代理建立了一个可工作的 Web 服务器,通过 localhost curl 进行了自检,然后发出了带有 ALLOW_POST_SUCCESS_RESET 前缀的清理命令,擦除了实时的 Web 根目录并重置了 git 引用“为了给评分留下一个干净的仓库”。外部验证器收到了 404 错误。
第 8 次迭代修补了覆盖令牌:删除受保护的输出和重置受保护的根目录变成了硬性阻止,令牌无法再擦除。一个 before_model 钩子将执行风险提示提升为 FRAMEWORK 提醒,在下一轮模型对话中可见。第 8 次迭代的总体得分达到 76.97,是该运行的高水位线。
所有四个案例的模式表明:提示词只能说明要避免什么,但执行时的强制执行才是改变结果的关键。四个获胜的修复方案中有三个是在工具实现或中间件层面实现的。
## 局限性
**困难层级的下滑**。AHE 在困难层级上略微落后于 Codex-CLI(53.3% vs 56.7%)。记忆、中间件和系统提示词都倾向于同样的闭包式验证,这会在冗余的重新检查上消耗轮次预算。仅将 AHE 的长期记忆交换到种子配置中(无其他组件)就已经在困难层级上超过了 Codex。
**非叠加的组件交互**。三个正向的单组件收益加起来是 +11.1pp,但完整的 AHE 仅实现了 +7.3pp。堆叠组件损失了 3.8pp。进化代理优化的是一个由 55 个中等任务主导的总分,因此它收敛于一个侧重于中等任务的权衡,部分牺牲了困难任务的记忆效果。
**回归预测盲区**。在九轮评估中,进化代理发出了 43 个独特的回归预测,只有 5 个命中(精确率 11.6%)。实际上发生了 40 个未预见到的回归(召回率 11.1%)。修复预测比随机高出 5 倍。回归预测仅比随机高出 2 倍。
代理可以证明为什么编辑应该有帮助。它无法可靠地指出同一个编辑会破坏什么。
**基准范围**。完整的进化运行是在 Terminal-Bench 2 上进行的。跨基准和跨模型的迁移证据令人鼓舞,但非 Terminal-Bench-2 的进化运行才是回答“刷榜”问题的关键。作者标记了这一点,并将其称为泛化风险。
因此,最好的建议是将 AHE 视为一个受控的研究原型,它已经产生了一个值得研究的冻结挂载,同时在将框架作为部署级自我改进循环采用之前,等待在第二个基准上进行进化运行。
## AlphaSignal 观点
**值得关注**。该框架实现了其声称的功能,凭证(变更清单 + 自动回滚)用测量取代了自辩解,跨模型迁移是迄今为止最有力的信号,表明挂载结构编码了较弱的基座模型无法廉价重新推导的协调模式。
两个未完成的方面是回归盲区差距和第二次基准进化运行。解决其中任何一个都会将其从研究原型推向生产级。
值得关注的未来实体是 NexAU,即循环运行的基础设施,因为框架的影响力取决于有多少生产代理采用文件级组件合约。
## 谁受益,谁不受益
**受益者**:在多步骤终端或仓库工作流中运行长周期编程代理的团队,任何进行超越粗略第一版的提示词手工微调的人,将自进化循环评估为微调替代方案的 ML 工程师,以及研究不需要梯度更新的测试时适配表面的研究人员。
**跳过者**:其代理循环是短周期 API 调用链的团队,没有推演轨迹或带有二进制通过/失败信号的验证器的团队,以及已经投资于仅限提示词框架(ACE、GEPA、DSPy)且无法打开收益所在的挂载组件的团队。
## 从业者启示
ML 工程师现在可以针对基准自动进化编程代理的工具、中间件和记忆,因为可观测性原语将每个组件编辑变成了可证伪的合约。
## 研讨会
我们正在举办一场关于挂载系统工程的会议,旨在超越简单的提示词和上下文。这是关于构建让代理能够自主工作的约束。
5月7日,上午11点(PT)。由 AJ Joobandi(Augment Code)主讲。20 个席位,150 美元。
您将了解代理为什么会崩溃,如何设计稳健的成功指标,并带走一个即插即用的挂载文件。
→ 在此抢座

## 链接
- arXiv 论文(论文,约 45 分钟阅读)
- GitHub 仓库(代码,MIT 许可)
- Agent Debugger 博客(背景,约 10 分钟阅读)
- NexAU 框架(循环运行的基础设施)
关注 @AlphaSignalAI 获取更多此类内容。
在 AlphaSignal.ai 订阅每日 AI 信号。已有 280,000+ 开发者阅读。
## 附录
```
算法 1:AHE 外层循环
H_best ← H₀ # 仅限 bash 的 NexAU₀ 种子
for t = 1 to N do
T_t ← Rollout(M, H_{t-1}, D, k) # 阶段 1:每个任务 k≥2 次推演
T̃_t ← Clean(T_t) # 阶段 2:删除 base64,去重工具输出
if t ≥ 2 then # 阶段 3:归因先前列表,然后回滚
V_t ← Attribute(C_{t-1}, T_{t-1}, T_t)
H_{t-1} ← Rollback(H_{t-1}, V_t)
R_t ← AgentDebugger(T̃_t) # 阶段 4:分层提炼
(H_t, C_t) ← Evolve(H_{t-1}, R_t, V_t) # 阶段 5:工作空间编辑 + 新清单
Commit(H_t, C_t, t) # 阶段 6:在 git 中标记迭代
if Pass@1(T_t) > Pass@1(H_best) then
H_best ← H_t
return H_best
```
## 相关链接
- [克斯马 reposted](https://x.com/mrbleem_eth)
- [AlphaSignal AI](https://x.com/AlphaSignalAI)
- [@AlphaSignalAI](https://x.com/AlphaSignalAI)
- [4.4K](https://x.com/AlphaSignalAI/status/2049900160080077229/analytics)
- [Harness Engineering workshop](https://luma.com/t24o902x)
- [here](https://lu.ma/t24o902x)
- [Paper on arXiv](https://arxiv.org/abs/2604.25850)
- [GitHub repo](https://github.com/china-qijizhifeng/agentic-harness-engineering)
- [Agent Debugger blog](https://dawning-road.github.io/blog/agent-debugger)
- [NexAU framework](https://github.com/nex-agi/NexAU)
- [@AlphaSignalAI](https://x.com/@AlphaSignalAI)
- [AlphaSignal.ai](https://alphasignal.ai/)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [1:14 AM · May 1, 2026](https://x.com/AlphaSignalAI/status/2049900160080077229)
- [4,475 Views](https://x.com/AlphaSignalAI/status/2049900160080077229/analytics)
---
*导出时间: 2026/5/1 10:09:06*