# The Hermes Agent Memory Guidebook
**作者**: Kevin Simback
**日期**: 2026-05-23T19:02:34.000Z
**来源**: [https://x.com/KSimback/status/2058262328496554021](https://x.com/KSimback/status/2058262328496554021)
---
> TLDR: this is your definitive guide to all things related to memory systems for Hermes Agent. Why create this? Because every week I see new posts or articles describing some new memory tool for Hermes agents and these make me question if my memory setup is the best. So I dug into all of them and broke it down for you.
Over the past few months my Hermes agent has been mapping the Hermes ecosystem over at hermesatlas.com. One of the key areas it has covered is memory and it even has a dedicated section for it.
hermesatlas.com
And let's be honest, there are a LOT of memory related tools available and there are a LOT of write-ups about them. I see new articles on X every week about some new memory setup. It's hard to keep up, and even harder to know if you're doing it all wrong because they all make claims about how certain memory systems are better than others.
But many of these write-ups skip the architecture (how memory works in Hermes) or conflate different elements of the memory stack. This article is the culmination of everything I've learned about Hermes agent memory and a guide to help you navigate what makes most sense for your setup.
## Memory is arguably the most important element of an agent setup
Without memory, an agent is just a stateless function and no different than a blank ChatGPT window. Every prompt looks like the first prompt. That works for one-shot questions but breaks down the moment you have a use case that needs to know what happened yesterday, remember your preferences, accumulate skills from prior tasks, or coordinate with another agent.
A coding session that doesn't remember the conventions you established last Tuesday will reinvent them this Tuesday. A personal assistant agent that doesn't remember your preferences has to ask you the same repeated questions. Without memory, an agent really isn't an agent at all.
Memory is what turns an chatbot into something that compounds. Which is why every serious agent harness - OpenClaw, Claude Code, Codex, and our beloved Hermes - has memory primitives built in, and why a real product category has emerged around dedicated memory infrastructure or agents (Mem0 raised $24M, Letta $10M, plus Zep, Cipher, Supermemory, Hindsight, etc.).
The Hermes Agent take is interesting because Nous Research treats memory as first-class plug-in infrastructure, not a feature. There's a base layer that always runs, a pluggable provider system that lets you choose from 8 architectures (or write your own), and a healthy community plug-in layer on top.
That 3-layer stack is what I will explore in depth in this article.
## Hermes Agent memory architecture at a glance
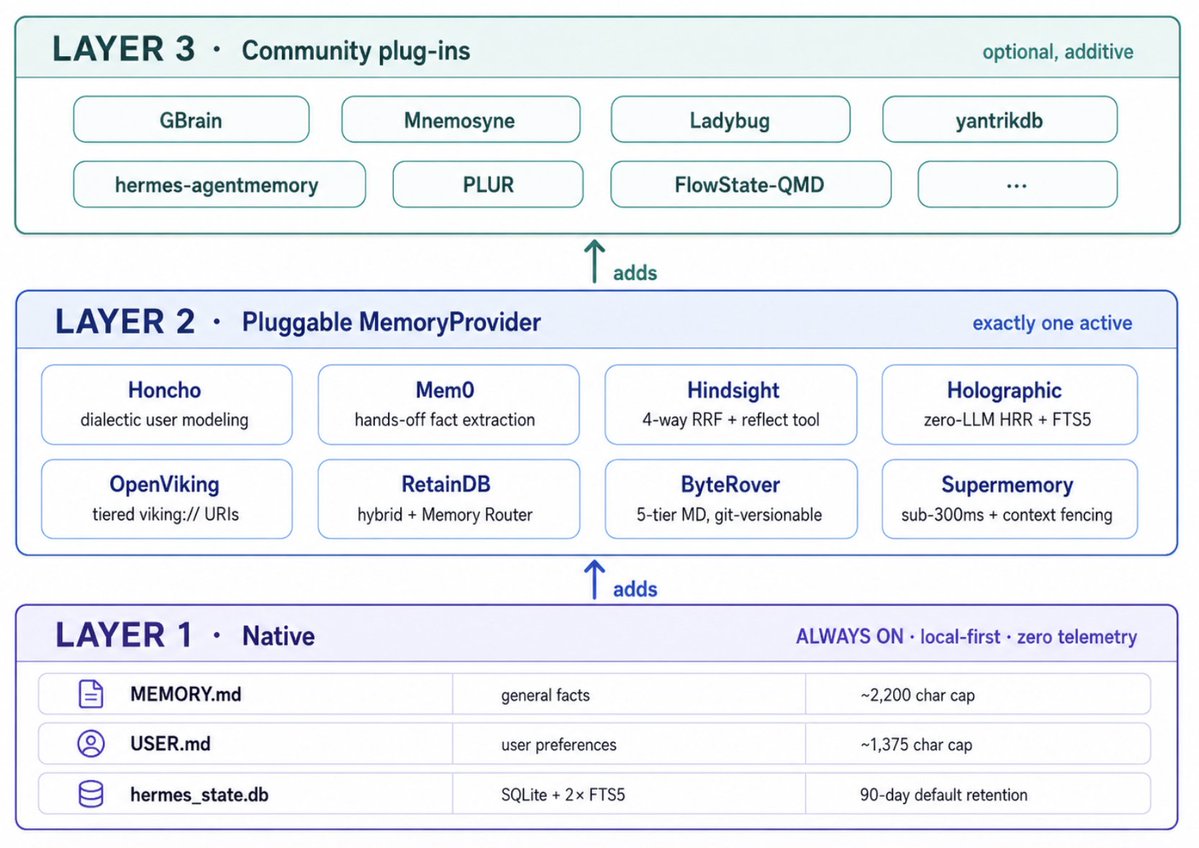
Here's what each layer means for you as a Hermes user.
Layer 1 - what ships in the box. You get this whether you do anything or not. Two small markdown files the agent uses as its always-visible notebook, plus a local database that archives every session you've ever had. No setup, no config. For many use cases, this is often all you need.
Layer 2 - the optional plug-in slot. When you outgrow the native layer (you want semantic recall across sessions, or a system that models your preferences, or token-efficient retrieval at scale) you pick one of 8 official providers. They each take a different architectural bet about what memory should do, and you can run exactly one at a time. Switching providers is a clean start - the new provider doesn't inherit the old one's data, but the Layer 1 native files keep running underneath either way.
Layer 3 - what the community builds beyond the official 8. Two flavors. Some community projects are MemoryProvider plug-ins that compete head-to-head with the Layer 2 picks (Mnemosyne is the standout - fully local, sub-millisecond, with a real tiered cognitive architecture). Others sit alongside the official providers in a different slot entirely (GBrain is the standout here - it stores world facts like people, companies, and projects in a markdown vault, while your Layer 2 provider handles operational memory). Layer 3 usually means more setup and less polish than the official 8, but it's where you go when you need a capability the eight providers don't offer.
The layers stack rather than replace each other. Switching the Layer 2 provider does not wipe Layer 1. Each provider has its own store, but the native session database and the two markdown files keep running underneath. Layer 3 plug-ins are additive on top of both.
## Layer 1: Native - what you get out of the box
The native layer is three things that ship with every Hermes install: two small markdown files and one database. They play different roles, and it's worth understanding each before we get to the plug-in providers.
Note: if you already understand the out of box setup or want to skip to the optional stuff you can install on top, go to Layer 2.
The two markdown files
When you install Hermes, it creates two text files in your home directory at ~/.hermes/:
> MEMORY.md - the agent's general knowledge notebook. Project context, technical decisions, things worth remembering across sessions. Capped at about 2,200 characters, roughly a paragraph and a half.
> USER.md - what the agent knows about you specifically. Your preferences, your working style, your role. Capped at about 1,375 characters, roughly one paragraph.
You can open both files in any text editor. They're plain markdown. You can even edit them by hand if you want, and the agent will read your edits next session.
The reason they're so small is that they aren't the agent's filing cabinet - they're the agent's sticky notes. At the start of every session, Hermes pastes the entire contents of both files into the prompt sent to the model. So everything in these files is always "in front of" the agent. No retrieval needed, it just sees them.
The agent itself decides what goes into these files. When something important comes up in a session - you say "I prefer bullet points instead of paragraphs" or the agent figures out that you use Vercel for deployments - the agent calls a tool called memory with one of three actions: add, replace, or remove. There's no read action because the files are already pasted into the prompt; the agent reads them by virtue of looking at its own context.
What happens when the files fill up?
This is where most third-party write-ups get things wrong. They claim Hermes automatically consolidates the files when they hit 80% of the cap. I went into the code at agent/memory_manager.py to verify, and the actual behavior is more interesting:
There is no automatic consolidation - the 80% rule is a prompt instruction, not code. The system prompt header shows the agent a real-time fill gauge - something like "MEMORY: 1,847/2,200 chars (84 percent)" - along with the instruction "when memory is above 80% capacity, consolidate entries before adding new ones." The agent reads that, and the agent decides whether to act on it. If the file is already at the cap and the agent tries to add anything anyway, the memory tool returns an error listing the current entries and forces the agent to free space via replace or remove first.
This is a deliberate design choice. Nous trusts the model to manage its own notebook. The upside is full agent control, but the downside is also full agent control. A poorly-prompted agent can sit at the cap indefinitely, refusing every new add call and quietly losing information that should have replaced something older, but I'm confident this gets resolved soon as there's some PRs around this.
A related point of confusion worth clearing up before we go on: v0.12 introduced something called the "Autonomous Curator" and many write-ups describe it as automatic memory management. It is not. The Curator operates only on the agent's skill library at ~/.hermes/skills/ - moving skills from active to stale to archived based on usage. It never touches MEMORY.md or USER.md.
The database (and how it relates to the markdown files)
The two markdown files are the agent's always-visible notes. The database is the agent's full archive of everything that has ever happened.
Hermes stores every session in a SQLite database file at ~/.hermes/hermes_state.db. Every user message, every agent response, every tool call, every reasoning step, plus economic data like token counts and dollar cost per session - all of it lands here. Default retention is 90 days; older sessions get pruned automatically every 24 hours unless you change the setting.
This database is not auto-injected into prompts. It would be enormous - imagine pasting your entire chat history into every new conversation. Instead, the agent searches it on demand when it needs to find something specific.
The search uses SQLite's built-in full-text search (FTS5), and Hermes maintains two parallel indexes: one for normal word-level search ("did we discuss the content strategy?") and one for trigram search that handles substrings and code tokens ("find every session where I mentioned github").
So the mental model is:
> The two markdown files = what the agent always has in its head. Small, curated, always present in every prompt.
> The session database = what the agent can look up if it knows what to look for. Huge, raw, searchable on demand.
These are complementary, not redundant. When something matters across all future sessions, the agent should write it to MEMORY.md so it's always present. When something might matter again but doesn't need to be top-of-mind, it lives in the session database and gets pulled up only when the agent searches for it.
A nice side-effect of the database design: because Hermes captures every reasoning step and every tool call with full economic data, the database is also a complete training trajectory if you ever want to export it. This is beyond the scope of this article but something that aligns with my thesis on where the moats are in agents.
## Layer 2: The pluggable "MemoryProvider" system
This is the layer that lets you graduate from "small notebook plus searchable archive" to a real memory system - one that extracts facts from your conversations automatically, builds a profile of you, supports semantic recall across sessions, or handles a large knowledge graph.
Setting this up is quite simple - you run "hermes memory setup", pick a provider from the menu, and from then on the agent has a richer memory layer to draw from on top of the native files. Note: some providers require API keys and paid plans.
The important note is you can only run one provider at a time. Hermes treats this as a single deliberate choice, not a stack of bolt-ons.
That keeps your tool surface clean - each provider exposes its own set of agent tools, and the agent would get confused if there were three competing "search memory" tools sitting in front of it - and it makes the configuration easy to reason about. The Layer 1 native files keep running underneath whether you have a provider active or not.
Picking the right provider matters because they make very different architectural bets. Some are aggressive at extracting facts. Some build a model of how you think rather than what you said. Some are obsessed with token efficiency. Some are graph-first. The full decision tree is later in this article; the technical mechanics below are for readers who want to know what providers actually plug into.
Let's dive in.
## The 8 Official Providers
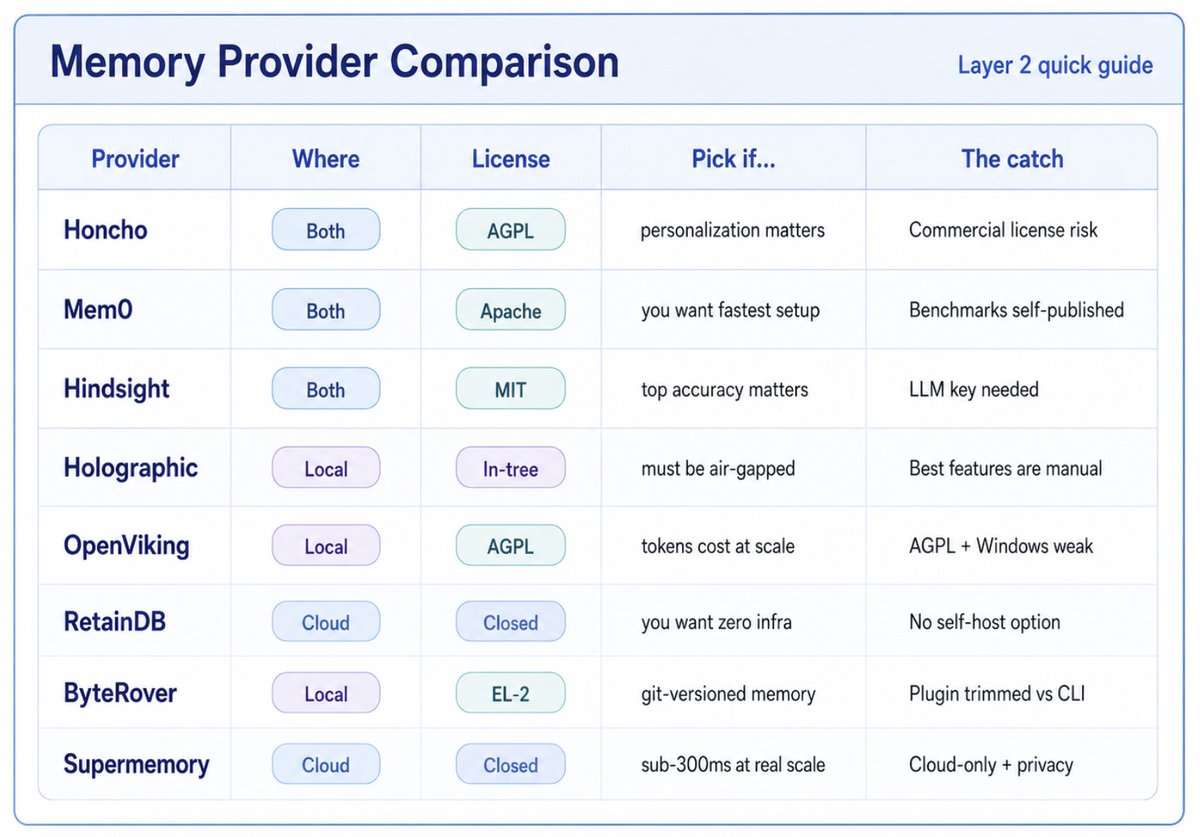
Honcho (Plastic Labs) - AI-native dialectic user modeling
The only provider in the lineup that tries to model how you think, not just what you said. Instead of storing flat facts like "Kevin uses 4-space indents," Honcho runs a multi-step reasoning pass after your conversations to build a profile of your reasoning patterns, preferences, and goals.
That profile evolves over time, so the agent gets better at anticipating what you'd want even on topics you've never discussed. It also lets multiple "AI identities" share the same view of you - useful if you run different specialist agents for coding, writing, and strategy and want all of them to know your style. Most-cited favorite in the Hermes Discord (@offendingcommit: "I've tried them all... I freakin' love Honcho.").
Mem0 - fastest 30-second setup, broadest ecosystem
The "just give me memory and stop asking questions" pick. You sign up for Mem0 cloud, paste an API key, and you're done - the provider extracts facts from conversations, deduplicates them, and serves up semantic search automatically in the background.
It's also the exclusive memory provider for AWS's Strands Agents SDK, which gives it the widest ecosystem reach in the lineup. In April 2026 Mem0 shipped a "v3" algorithm claiming to leapfrog Hindsight on benchmarks (94.8 on LongMemEval, 91.6 on LoCoMo).
Hindsight (Vectorize.io) - the benchmark king
The first memory system of any kind to publicly cross 90 on LongMemEval (91.4, December 2025). Hindsight thinks about memory as four separate networks - things about the world, things that happened, opinions, and raw observations - and pulls only a handful of high-value facts from each conversation (2 to 5, not one per sentence).
When you ask it something, it runs four different retrieval strategies in parallel - keyword search, vector similarity, graph traversal across related entities, and a recency pass - then fuses the results. That's how it gets the best recall accuracy in the published lineup.
It's also the only provider with a reflect tool that lets the agent run a reasoning pass over its own memory. That's uniquely valuable if you're running multiple agents on a shared memory bank and you need an orchestrator to synthesize what all of them know.
Holographic - zero-dependency, fully local, air-gapped
The only provider in the lineup that needs no internet, no API key, and no LLM to function. Everything lives in a local SQLite file. It uses a 1991-era technique called Holographic Reduced Representations to do compositional reasoning over facts - you can bind concepts together algebraically and probe for related ones later. Retrieval is sub-millisecond because it's pure local SQL.
OpenViking - tiered filesystem context DB
Your memory lives as files in a directory tree on your disk. You can cat them, grep them, edit them by hand. Each piece of stored knowledge has three loading tiers: a one-sentence summary, a paragraph-level overview, and the full content.
When the agent recalls something, it starts cheap (summaries only) and only loads the deeper tiers if the summary looks relevant. That structure is important if you're cost-sensitive at scale or you want memory you can read and edit like normal files.
RetainDB - cheapest paid tier, lowest friction
$20/month for 100,000 queries, with a free tier of 10,000 operations to test. The only provider in the lineup that's cloud-only at every price point (no self-host even on enterprise). The hook is convenience: you operate no infrastructure, RetainDB handles everything, and there's a "Memory Router" mode that intercepts your LLM calls and adds memory transparently with one config line.
Pick this option if you want shared memory across team members or agents and you don't want to operate a database.
ByteRover - memory as a git repo
Your memory is plain markdown files in a .brv/context-tree/ directory - grep-able, version-controllable, no database to run. ByteRover layers a 5-tier retrieval system on top, and four of those tiers don't need an LLM call, so most lookups finish in under 100ms with zero token spend.
The key selling point: you can branch, merge, and roll back memory like code with CLI commands. It also uses a special hook to extract high-value insights before Hermes compresses context, which is the cleanest fix in the lineup for the "agent loses memory after restart" failure mode (noted in issue #17251).
Supermemory - latency + scale leader
Sub-300ms recall sustained at over 100 billion tokens per month. Supermemory built a custom vector graph engine for this rather than stapling a vector DB and a graph DB together.
Its standout feature is context fencing: it automatically strips already-recalled memories out of conversations before storing them, which kills the "memory feedback loop" where auto-capture systems start re-ingesting their own outputs into the next round of memory.
Good choice if you want to operate at real scale (consumer app, multi-tenant SaaS, agent platform) and latency matters, but likely overkill for normal consumer use.
Here's a comparative look across all 8
## Layer 3: Community plug-ins worth knowing
If none of the official 8 fits your use case, or if you want even more on top, the community has built another layer of memory tooling for Hermes. About five of these are production-quality enough to consider seriously, plus a longer tail of experiments to keep eyes on.
Two things to know up front about Layer 3:
1. Not every Layer 3 project competes with Layer 2. Some are alternative MemoryProvider plug-ins you'd pick instead of one of the official 8 (Mnemosyne is the clearest example). Others occupy a different role entirely - they store a different type of memory and run alongside your Layer 2 provider, not in place of it (GBrain is the clearest example, storing world facts about people, companies, and projects in a separate brain layer while your Layer 2 provider handles operational memory).
2. You give up polish to get capability. The official 8 ship with Nous's review and tend to "just work." Community plug-ins are typically a bit rougher on the install, have fewer docs, and more chance of hitting a bug. But they unlock things the official set doesn't offer like fully-local sub-millisecond retrieval (Mnemosyne), a markdown-and-Postgres knowledge graph that builds itself with zero LLM calls (GBrain), explainable retrieval rankings (yantrikdb), and cross-agent memory portability (PLUR).
The safe path if you're committing to a memory stack for real work: start with one of the official 8 and only reach for Layer 3 when you've identified a specific capability gap a community project fills. The standouts below are GBrain and Mnemosyne.
GBrain (by garrytan) - this is what I personally use
Open-sourced in April, MIT licensed, ~18k+ stars. TypeScript. Built by Garry Tan to run his own production agents. GBrain is structurally different from the official 8. GBrain does not subclass MemoryProvider, it plugs in as skillpack + MCP server (~30 MCP tools), and occupys a different ontological slot. The explicit doctrine in docs/guides/brain-vs-memory.md:
What makes it special:
- Not just RAG: a full 8-layer knowledge engine for dramatically better memory and recall
- Epistemology layer: tracks “who said what, when, and with what confidence” so no more hallucinated facts or lost context
- Self-wiring knowledge graph: automatically extracts entities and creates real relationships (e.g., “attended,” “works_at,” “invested_in,” “founded”) with zero extra LLM calls
- Dream cycles for autonomous synthesis: runs overnight (or on-demand) so your brain literally gets smarter while you sleep
- Hybrid search done right: combines vector, keyword, RRF fusion, multi-query expansion, cosine reranking, compiled-truth boost, and backlink boost for far more accurate results than plain vector search
- Specialized + versioned chunking: recursive markdown chunker (v4) that intelligently handles code blocks, frontmatter, transcripts, etc. so edits don’t break memory
- Autonomous enrichment + persistent personal memory: tiered enrichment based on how often something is mentioned turning Hermes agent into a “clairvoyant” personal AI that actually knows you
Why pick GBrain over the official 8? If you want a graph cheap, git as system of record, overnight maintenance, you already have a markdown vault (migration covers Obsidian / Logseq / Notion / Roam), or you're building a "company of agents."
Mnemosyne (AxDSan/mnemosyne)
The strongest community alternative when you want a real MemoryProvider plug-in (rather than GBrain, which plays a different role). Runs entirely on your machine - no cloud, no API key, no internet - and recall is fast enough to feel instant (under 2 milliseconds in published tests).
What makes Mnemosyne interesting is its tiered memory architecture, modeled loosely on how humans handle short-term vs long-term memory. There's a "working" tier for what's actively relevant right now, an "episodic" tier for time-stamped events you might want to look up later, and a "scratchpad" for things still being considered for promotion. A consolidation pass runs periodically in the background to move useful items into long-term memory and prune the noise.
The standout feature for serious users: memory has a sense of time. You can ask "what did I believe about X last Tuesday?" and get back the agent's understanding as it was at that point, not as it is today. No other Hermes plug-in does this as cleanly. One soft adoption signal worth noticing: Mnemosyne is the only community memory plug-in that someone has bothered to write a dedicated Hermes skill wrapper for (a small file that teaches the agent how to use it intelligently). Nobody's done that for the others.
Others worth knowing about
- Ladybug Memory - the local-only option with built-in importance ranking. Every memory gets a score from 1 to 10 so the system surfaces the things that matter first instead of treating everything equally. Pick it if you want fully-local memory and the built-in MEMORY.md cap is too small for your knowledge.
- yantrikdb - he one to pick when you need to know why the agent recalled what it did. Every retrieval comes back with a "why retrieved" explanation, which is useful for debugging when the agent surfaces the wrong thing or for high-trust contexts where you need to audit what's shaping the agent's responses. Runs embedded out of the box, no separate database to manage.
- hermes-agentmemory - a community fix for a real Hermes problem: when you tell the agent to forget something, it doesn't actually forget - it keeps an internal summary that quietly influences future recall. This provider does real deletion (gone is gone) and logs every memory operation so you can audit what happened. Pick it if compliance, privacy, or user-controlled forgetting matters.
- PLUR - the cross-agent memory bridge. Hermes memory normally doesn't reach Cursor, and Cursor's doesn't reach Claude Code. PLUR stores everything in a shared .plur/ folder that all of them can read, so a fact you teach one agent automatically shows up in the others. Pick it if you work across multiple agents on the same project and don't want to teach each one separately.
- FlowState-QMD - The "guess what you'll need next" provider. It tries to predict the agent's next likely query and warms up that memory in advance, so by the time the agent actually searches, the result is already cached and responses come back faster. Pick it if your agent does repetitive long-horizon work where the next step is usually guessable from context.
One thing I expected to find that doesn't exist: memory-as-skill is effectively a non-pattern. The agentskills.io standard means a "skill" could in principle implement memory. In practice all credible persistent memory flows through the MemoryProvider ABC. Even skills that "do memory" (the Mnemosyne SKILL.md, for instance) are wrappers around plug-ins, telling the agent how to use them.
## How to actually pick?
Step 1: pick your layer strategy
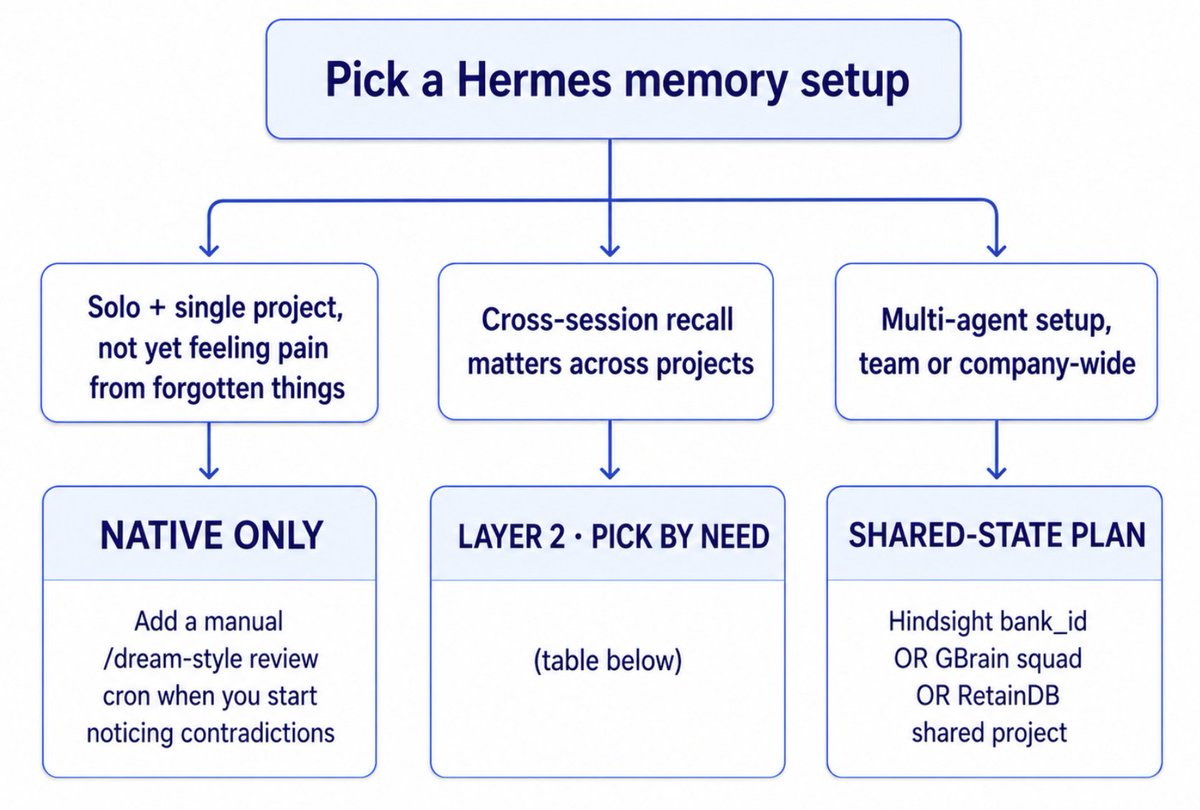
Step 2: pick your layer 2 system
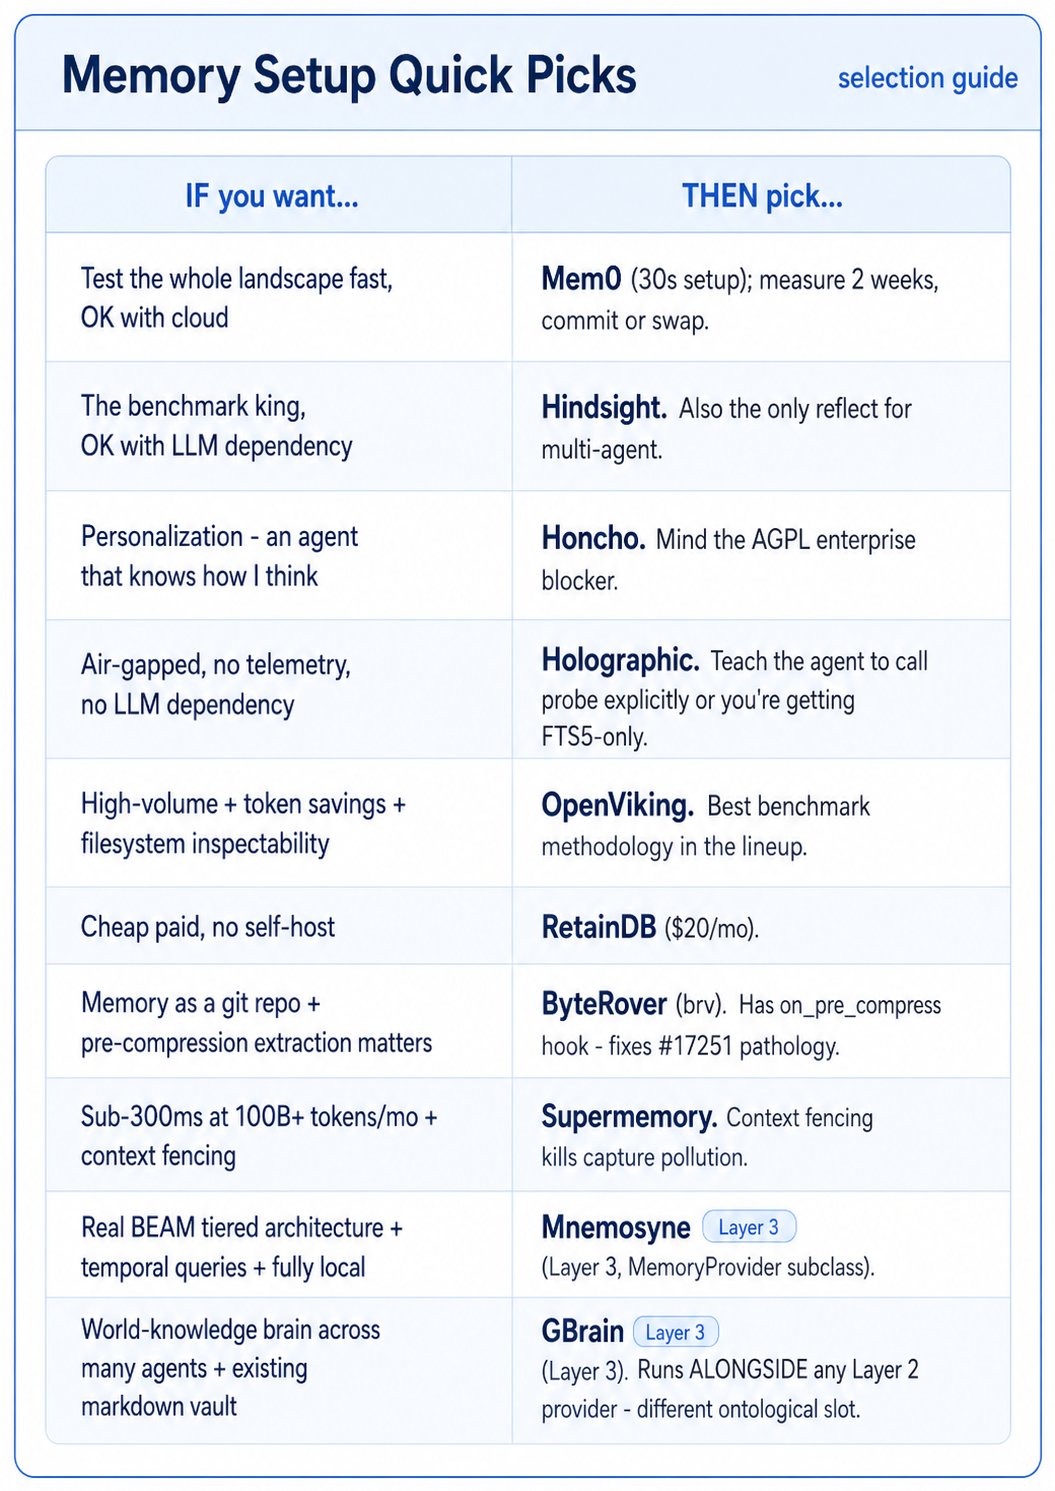
Warning signs you went too heavy:
- The agent feels noticeably slower. Responses that used to come back in about a second now take 3+ seconds. A heavy memory layer adds work on every turn, and once latency creeps past a few seconds the agent stops feeling responsive.
- Your API bill is creeping up for the same usage. Memory operations consume tokens, and some providers fire extra background LLM calls every time you save something. If your usage patterns haven't changed but your spend has, suspect the memory layer.
- The agent starts contradicting itself. It recalls one version of a fact in one session and the opposite in the next, and can't tell you which is right. This usually means memory is accumulating without ever being consolidated - the agent is now drawing from a polluted well.
- The agent runs out of context mid-conversation. A greedy memory layer eats into the same context budget your actual conversation needs. If you start seeing "context too long" errors, or the agent forgets what you told it five minutes ago, the memory layer is overspending its share.
- Your work isn't actually getting better. This is the one that matters most. You added memory expecting more accurate, more personalized output. After a couple of weeks, can you point at a specific way the agent is genuinely better than before? If you can't, the memory layer isn't earning its complexity. Pull it.
I hope you enjoyed this Hermes Agent deep dive on all things memory. If you want to explore more within the Hermes ecosystem, check out hermesatlas.com and sign up for the Hermes Atlas newsletter to stay up to date on everything.
## 相关链接
- [Kevin Simback](https://x.com/KSimback)
- [@KSimback](https://x.com/KSimback)
- [11K](https://x.com/KSimback/status/2058262328496554021/analytics)
- [hermesatlas.com](https://hermesatlas.com/)
- [hermesatlas.com](https://hermesatlas.com/)
- [Nous Research](https://x.com/NousResearch)
- [where the moats are in agents](https://x.com/compose/articles/edit/2044821377530597376)
- [Honcho (Plastic Labs)](https://hermesatlas.com/projects/plastic-labs/honcho)
- [@offendingcommit](https://x.com/@offendingcommit)
- [Mem0](https://hermesatlas.com/projects/mem0ai/mem0)
- [Hindsight](https://hermesatlas.com/projects/vectorize-io/hindsight)
- [Vectorize.io](https://vectorize.io/)
- [Holographic](https://github.com/NousResearch/hermes-agent/tree/main/plugins/memory/holographic)
- [OpenViking](https://openviking.ai/)
- [RetainDB](https://www.retaindb.com/)
- [ByteRover](https://docs.byterover.dev/autonomous-agents/hermes)
- [Supermemory](https://supermemory.ai/)
- [GBrain](https://hermesatlas.com/projects/garrytan/gbrain)
- [garrytan](https://x.com/garrytan)
- [Mnemosyne](https://hermesatlas.com/projects/AxDSan/mnemosyne)
- [Ladybug Memory](https://github.com/Ladybug-Memory/hermes-memory-plugin)
- [yantrikdb](https://github.com/yantrikos/yantrikdb-hermes-plugin)
- [hermes-agentmemory](https://github.com/MukundaKatta/hermes-agentmemory)
- [PLUR](https://hermesatlas.com/projects/plur-ai/plur)
- [FlowState-QMD](https://github.com/amanning3390/flowstate-qmd)
- [agentskills.io](https://agentskills.io/)
- [hermesatlas.com](https://hermesatlas.com/)
- [newsletter](https://hermesatlas.com/#newsletter)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [3:02 AM · May 24, 2026](https://x.com/KSimback/status/2058262328496554021)
- [11.7K Views](https://x.com/KSimback/status/2058262328496554021/analytics)
---
*导出时间: 2026/5/24 09:01:34*
---
## 中文翻译
# Hermes Agent 记忆系统完全指南
**作者**: Kevin Simback
**日期**: 2026-05-23T19:02:34.000Z
**来源**: [https://x.com/KSimback/status/2058262328496554021](https://x.com/KSimback/status/2058262328496554021)
---

> TLDR:这是你了解 Hermes Agent 记忆系统相关一切的终极指南。为什么要写这个?因为每周我都会看到新的帖子或文章介绍某种新的 Hermes agent 记忆工具,这些让我开始怀疑自己的记忆配置是不是最优的。所以我深入研究了所有这些工具,并为你做了拆解分析。
过去几个月里,我的 Hermes agent 一直在 hermesatlas.com 上绘制 Hermes 生态图谱。它覆盖的关键领域之一就是记忆,甚至还有一个专门的版块。

hermesatlas.com
说实话,现有的记忆相关工具非常多,关于它们的介绍文章也非常多。我每周都能在 X 上看到关于某种新记忆配置的新文章。要跟上这些进展很难,而要判断自己是不是做得完全不对就更难了,因为它们都在宣称某些记忆系统比其他的更好。
但其中很多文章都跳过了架构层面(记忆在 Hermes 中如何工作),或者混淆了记忆技术栈中不同的元素。这篇文章是我所学到的关于 Hermes agent 记忆的一切的集大成之作,也是一份帮你厘清哪种方案最适合你的配置的指南。
## 记忆可以说是 agent 配置中最重要的元素
没有记忆,agent 只是一个无状态函数,和空白的 ChatGPT 窗口没什么区别。每个提示词看起来都像是第一个提示词。这对一次性问题来说没问题,但一旦你的用例需要知道昨天发生了什么、记住你的偏好、从先前的任务中积累技能,或者与其他 agent 协调,它就崩溃了。
一个不记得你上周二确立的代码规范的编码会话,这个周二会重新发明它们。一个不记得你偏好的个人助理 agent,不得不反复问你同样的问题。没有记忆,agent 真的算不上是 agent。
记忆是把聊天机器人变成能够不断累积增值的东西的关键。这也是为什么每个严肃的 agent 框架——OpenClaw、Claude Code、Codex,以及我们心爱的 Hermes——都内置了记忆原语,也是为什么围绕专门的记忆基础设施或 agent 已经形成了一个真正的产品类别(Mem0 融资了 2400 万美元,Letta 融资 1000 万美元,还有 Zep、Cipher、Supermemory、Hindsight 等等)。
Hermes Agent 的做法很有意思,因为 Nous Research 把记忆视为一等公民的插件基础设施,而不是一个功能。有一个始终运行的基础层,一个可插拔的提供商系统让你可以从 8 种架构中选择(或者自己编写),以及在其之上的活跃的社区插件层。
这个三层技术栈就是我在本文中要深入探讨的内容。
## Hermes Agent 记忆架构一览

以下是对你作为 Hermes 用户而言,每一层的含义。
第 1 层——开箱即用的部分。无论你做不做任何配置,你都会得到这一层。两个小的 markdown 文件,agent 将其作为始终可见的笔记本,外加一个本地数据库,存档你的所有历史会话。无需安装,无需配置。对于许多用例来说,这通常就是你所需要的全部。
第 2 层——可选的插件槽位。当你的需求超出原生层的能力时(你想要跨会话的语义召回,或者一个能建模你偏好的系统,或者大规模下节省 token 的检索),你可以从 8 个官方提供商中选择一个。它们各自对“记忆应该做什么”做出了不同的架构押注,而且你一次只能运行一个。切换提供商是一个干净的重新开始——新提供商不会继承旧提供商的数据,但无论哪种情况,第 1 层的原生文件都继续在底层运行。
第 3 层——社区在官方 8 个之外构建的内容。有两种形式。一些社区项目是与第 2 层选项正面竞争的 MemoryProvider 插件(Mnemosyne 是其中的佼佼者——完全本地化、亚毫秒级响应,具备真正的分层认知架构)。另一些则处于与官方提供商完全不同的槽位中(这里的佼佼者是 GBrain——它将人物、公司和项目等世界事实存储在一个 markdown 知识库中,而你的第 2 层提供商负责处理操作性记忆)。第 3 层通常比官方 8 个需要更多的配置,打磨程度也更低,但当你需要这八个提供商都不具备的能力时,这就是你要来的地方。
这些层是叠加而非相互替换的。切换第 2 层提供商不会清除第 1 层。每个提供商都有自己的存储,但原生会话数据库和两个 markdown 文件在底层持续运行。第 3 层插件是在两者之上附加的。
## 第 1 层:原生层——开箱即用的内容
原生层是随每个 Hermes 安装包一起提供的三个东西:两个小的 markdown 文件和一个数据库。它们扮演着不同的角色,在我们进入插件提供商之前,值得逐一了解。
注意:如果你已经了解开箱即用的配置,或者想直接跳到可以在其之上安装的可选内容,请前往第 2 层。
### 两个 markdown 文件
当你安装 Hermes 时,它会在你的主目录 ~/.hermes/ 下创建两个文本文件:
> MEMORY.md——agent 的通用知识笔记本。项目背景、技术决策、值得跨会话记住的事项。上限约为 2,200 个字符,大约相当于一段半的文字。
> USER.md——agent 对你本人的了解。你的偏好、你的工作方式、你的角色。上限约为 1,375 个字符,大约相当于一段文字。
你可以在任何文本编辑器中打开这两个文件。它们是纯 markdown 格式。你甚至可以手动编辑它们,agent 会在下一个会话中读取你的修改。
它们之所以这么小,是因为它们并不是智能体的文件柜——而是智能体的便利贴。每次会话开始时,Hermes 会将这两个文件的全部内容粘贴到发送给模型的提示词中。因此,这些文件里的一切始终“摆在”智能体面前。无需检索,它直接就能看到。
写入这些文件的内容由智能体自己决定。当会话中出现重要事项——比如你说“我喜欢用要点而不是段落”,或者智能体发现你使用 Vercel 进行部署——智能体会调用一个名为 memory 的工具,执行三种操作之一:添加(add)、替换(replace)或移除(remove)。没有读取(read)操作,因为这些文件已经粘贴到了提示词中;智能体通过查看自己的上下文来读取它们。
当文件被填满时会发生什么?
大多数第三方文章在这一点上都搞错了。它们声称 Hermes 会在文件达到容量上限的 80% 时自动进行整合。我查看了 agent/memory_manager.py 中的代码进行验证,实际的行为更有意思:
并没有自动整合——80% 规则是一条提示词指令,而不是代码。系统提示词头部会向智能体显示一个实时填充仪表——类似“MEMORY: 1,847/2,200 chars (84 percent)”——并附带一条指令:“当记忆超过 80% 容量时,在添加新条目之前先整合条目。”智能体读到这条指令,然后由智能体自己决定是否执行。如果文件已经达到上限,而智能体仍试图添加内容,memory 工具会返回一个错误,列出当前条目,并强制智能体先通过替换或移除来释放空间。
这是一个刻意的设计选择。Nous 信任模型来管理自己的笔记本。好处是智能体拥有完全的控制权,但坏处同样是智能体拥有完全的控制权。一个提示词写得不好的智能体可能会无限期地停留在容量上限,拒绝每一次新的添加调用,并悄无声息地丢失本应替换旧内容的新信息,不过我相信这个问题很快会得到解决,因为已经有一些相关的 PR 了。
在继续之前,有一个相关的困惑点值得澄清:v0.12 引入了一个名为“Autonomous Curator(自主策展人)”的功能,许多文章将其描述为自动记忆管理。事实并非如此。Curator 仅作用于智能体位于 ~/.hermes/skills/ 的技能库——根据使用情况将技能从活跃(active)移至过时(stale)再到归档(archived)。它从不触碰 MEMORY.md 或 USER.md。
数据库(以及它与 markdown 文件的关系)
这两个 markdown 文件是智能体始终可见的笔记。数据库则是智能体对曾经发生过的一切的完整存档。
Hermes 将每个会话存储在 ~/.hermes/hermes_state.db 的 SQLite 数据库文件中。每条用户消息、每个智能体响应、每次工具调用、每个推理步骤,以及经济数据(如 token 数量和每会话的美元成本)——所有这些都存放在这里。默认保留期为 90 天;除非你更改设置,否则较旧的会话会每 24 小时自动清理。
这个数据库不会自动注入到提示词中。那将非常庞大——想象一下把你的整个聊天历史粘贴到每个新对话中。相反,当智能体需要查找特定内容时,它会按需搜索该数据库。
搜索使用 SQLite 内置的全文搜索(FTS5),Hermes 维护着两个并行索引:一个用于普通的词级搜索(“我们讨论过内容策略吗?”),另一个用于三元组(trigram)搜索,可处理子字符串和代码标记(“找到我提到 github 的每个会话”)。
因此心智模型是:
> 两个 markdown 文件 = 智能体头脑中始终拥有的东西。小而精炼,在每个提示词中都始终存在。
> 会话数据库 = 智能体在知道要找什么时可以查阅的东西。庞大、原始、可按需搜索。
这两者是互补的,而不是冗余的。当某件事对所有未来的会话都很重要时,智能体应将其写入 MEMORY.md,使其始终存在。当某件事可能再次相关但无需时刻记在心头时,它就存放在会话数据库中,仅在智能体搜索时才被调取。
数据库设计的一个不错的附带效果:由于 Hermes 记录了每个推理步骤和每次工具调用,并附带完整的经济数据,如果你将来想导出,该数据库也是一个完整的训练轨迹。这超出了本文的范围,但与我关于智能体护城河所在的论点相契合。
## 第 2 层:可插拔的“MemoryProvider”系统
这一层让你从“小笔记本加可搜索存档”升级为真正的记忆系统——一个能够自动从你的对话中提取事实、构建你的画像、支持跨会话语义召回或处理大型知识图谱的系统。
设置非常简单——你运行“hermes memory setup”,从菜单中选择一个提供商,从那时起,智能体就可以在原生文件之上获得一个更丰富的记忆层可供调用。注意:某些提供商需要 API 密钥和付费计划。
重要提示:一次只能运行一个提供商。Hermes 将此视为一个经过深思熟虑的单一选择,而不是一堆拼凑的插件。
这样可以保持你的工具界面整洁——每个提供商都会暴露自己的一套智能体工具,如果智能体面前同时出现三个相互竞争的“搜索记忆”工具,它会感到困惑——这也使配置更容易理解。无论你是否启用了提供商,第 1 层的原生文件都会继续在底层运行。
选择合适的提供商很重要,因为它们做出了截然不同的架构押注。有些在提取事实方面很激进。有些构建的是你如何思考的模型,而不是你说了什么。有些则执着于 token 效率。有些是图优先的。完整的决策树在本文后面;下面的技术细节面向那些想了解这些提供商究竟接入了什么机制的读者。
让我们深入了解。
## 8 个官方提供商
Honcho(Plastic Labs)- AI 原生辩证用户建模
阵容中唯一一家尝试建模你如何思考,而不仅仅是你说过什么的供应商。Honcho 不是存储“Kevin 使用 4 空格缩进”这类扁平事实,而是在每次对话后运行一个多步骤推理流程,构建一份关于你推理模式、偏好和目标的画像。
这份画像会随时间演进,因此即使是你从未讨论过的话题,智能体也能越来越擅长预测你的需求。它还允许多个“AI 身份”共享对你的同一视图——如果你为编程、写作和策略分别运行不同的专业智能体,又希望它们都了解你的风格,这就很有用。这是 Hermes Discord 中被引用最多的最爱(@offendingcommit:“我全都试过了……我太爱 Honcho 了。”)。
Mem0 - 最快的 30 秒设置,最广泛的生态系统
“只给我记忆,别问问题”的选择。注册 Mem0 云服务,粘贴一个 API 密钥,就完成了——该供应商会在后台自动从对话中提取事实、去重,并提供语义搜索。
它还是 AWS 的 Strands Agents SDK 的独家记忆供应商,这使它在这个阵容中拥有最广泛的生态系统覆盖。2026 年 4 月,Mem0 发布了号称在基准测试上超越 Hindsight 的“v3”算法(LongMemEval 上 94.8,LoCoMo 上 91.6)。
Hindsight (Vectorize.io) - 基准测试之王
首个公开在 LongMemEval 上突破 90 分的记忆系统(91.4,2025 年 12 月)。Hindsight 将记忆视为四个独立的网络——关于世界的事实、发生的事件、观点和原始观察——并从每次对话中只提取少量高价值事实(2 到 5 条,而不是每句话一条)。
当你向它提问时,它会并行运行四种不同的检索策略——关键词搜索、向量相似度、跨相关实体的图遍历,以及一个时效性检查——然后融合结果。这就是它在已公布的阵容中获得最佳召回准确率的方法。
它也是唯一一家提供 reflect 工具的供应商,该工具允许智能体对自己的记忆进行推理。如果你在共享记忆库上运行多个智能体,并需要一个协调器来综合所有智能体所知道的内容,这将具有独特价值。
Holographic - 零依赖、完全本地、物理隔离
阵容中唯一一个无需互联网、无需 API 密钥、也无需 LLM 就能运行的供应商。一切都存储在本地 SQLite 文件中。它使用一种 1991 年的称为全息简化表示的技术来对事实进行组合推理——你可以用代数方式将概念绑定在一起,之后再探测相关概念。检索是亚毫秒级的,因为它是纯本地 SQL。
OpenViking - 分层文件系统上下文数据库
你的记忆以文件形式存在于磁盘上的目录树中。你可以 cat、grep 或手动编辑它们。每条存储的知识都有三个加载层级:一句话摘要、段落级概览和完整内容。
当智能体回忆某件事时,它从低成本开始(仅摘要),只有在摘要看起来相关时才加载更深层级。如果你对大规模成本敏感,或者希望记忆可以像普通文件一样阅读和编辑,这种结构就很重要。
RetainDB - 最便宜的付费档位,最低的使用门槛
每月 20 美元可获得 10 万次查询,另有 1 万次操作的免费档供测试。阵容中唯一一家在所有价格档位都仅限云端的供应商(即使在企业版也不提供自托管)。它的卖点是便利:你无需运营任何基础设施,RetainDB 处理一切,还有一种“记忆路由器”模式,可以拦截你的 LLM 调用,并通过一行配置透明地添加记忆。
如果你想要团队成员或智能体之间共享记忆,又不想运营数据库,就选这个选项。
ByteRover - 记忆即 git 仓库
你的记忆是 .brv/context-tree/ 目录下的纯 markdown 文件——可 grep、可版本控制、无需运行数据库。ByteRover 在其上叠加了一个 5 层检索系统,其中四层不需要 LLM 调用,因此大多数查询在 100 毫秒内完成且零 token 消耗。
关键卖点:你可以用 CLI 命令像代码一样对记忆进行分支、合并和回滚。它还使用一个特殊的钩子在 Hermes 压缩上下文之前提取高价值洞见,这是阵容中对“智能体重启后丢失记忆”这一故障模式(见 issue #17251)最干净的修复方案。
Supermemory - 延迟与规模领先者
每月处理超过 1000 亿 token 时仍能保持低于 300 毫秒的召回延迟。Supermemory 为此构建了一个定制的向量图引擎,而不是简单地把向量数据库和图数据库拼在一起。
它的突出特性是上下文隔离:在存储之前自动从对话中剥离已被召回的记忆,从而消除“记忆反馈循环”——即自动捕获系统开始将自身输出重新摄入下一轮记忆的问题。
如果你想在真正的规模下运营(消费级应用、多租户 SaaS、智能体平台)且延迟很重要,这是不错的选择;但对于普通消费级使用可能有些大材小用。
以下是全部 8 家的对比概览

## 第 3 层:值得了解的社区插件
如果官方的 8 家都不符合你的用例,或者你想在此基础上获得更多,社区已经为 Hermes 构建了另一层记忆工具。其中大约有五个的生产质量足以认真考虑,此外还有一长串值得关注的实验项目。
关于第 3 层,有两件事需要提前了解:
1. 并非所有第三层项目都与第二层竞争。有些是替代性的 MemoryProvider 插件,可以用来替代官方 8 个之一(Mnemosyne 是最明显的例子)。另一些则占据完全不同的角色——它们存储不同类型的记忆,与你的第二层提供者并行运行,而非取而代之(GBrain 是最明显的例子,它将关于人物、公司和项目的世界事实存储在单独的大脑层中,而你的第二层提供者负责处理操作性记忆)。
2. 你用精致度换取能力。官方 8 个经过 Nous 的审查,往往“开箱即用”。社区插件通常在安装上略显粗糙,文档较少,遇到 bug 的几率也更高。但它们能实现官方集合所不具备的功能,如完全本地化的亚毫秒级检索(Mnemosyne)、无需任何 LLM 调用即可自动构建的 Markdown 与 Postgres 知识图谱(GBrain)、可解释的检索排序(yantrikdb),以及跨智能体的记忆可移植性(PLUR)。
如果你要为真正的工作搭建记忆技术栈,稳妥的路径是:先从官方 8 个之一开始,只有当你确定了某个具体的、由社区项目填补的能力缺口时,才考虑第三层。以下亮点是 GBrain 和 Mnemosyne。
GBrain(作者 garrytan)——这是我个人在用的
2025 年 4 月开源,MIT 许可证,约 1.8 万+ stars。TypeScript。由 Garry Tan 为运行自己的生产级智能体而构建。GBrain 在结构上不同于官方 8 个。GBrain 并不继承 MemoryProvider,而是以 skillpack + MCP 服务器(约 30 个 MCP 工具)的形式接入,占据一个不同的本体论位置。docs/guides/brain-vs-memory.md 中明确了这一理念:
它的特别之处:
- 不只是 RAG:一个完整的 8 层知识引擎,带来显著更好的记忆与召回
- 认识论层:追踪“谁在何时说了什么、置信度如何”,不再有幻觉事实或丢失的上下文
- 自联接知识图谱:自动提取实体并创建真实关系(如“参加过”、“就职于”、“投资了”、“创立了”),零额外 LLM 调用
- 用于自主综合的梦境周期:在夜间(或按需)运行,让你大脑在你睡觉时真的变得更聪明
- 做对了的混合搜索:结合向量、关键词、RRF 融合、多查询扩展、余弦重排序、编译事实加成和反向链接加成,结果远比普通向量搜索准确
- 专用且带版本控制的分块:递归 Markdown 分块器(v4),智能处理代码块、frontmatter、转录文本等,编辑不会破坏记忆
- 自主增强 + 持久化个人记忆:基于提及频率的分层增强,将 Hermes 智能体变成一个真正了解你的“千里眼”个人 AI
为什么选 GBrain 而不是官方 8 个?如果你想要廉价获得图谱、以 git 作为记录系统、夜间维护、已有 Markdown 仓库(迁移支持 Obsidian / Logseq / Notion / Roam),或者你正在构建一个“智能体公司”。
Mnemosyne(AxDSan/mnemosyne)
当你想要一个真正的 MemoryProvider 插件时(而非扮演不同角色的 GBrain),这是最强的社区替代方案。完全在你的机器上运行——无云端、无 API 密钥、无需联网——召回速度快到感觉是即时的(已公布的测试中低于 2 毫秒)。
Mnemosyne 的有趣之处在于其分层记忆架构,粗略地模仿人类处理短期与长期记忆的方式。有一个“工作”层存放当前活跃相关的内容,一个“情景”层存放带时间戳、以后可能想查询的事件,还有一个“草稿板”存放仍在考虑是否提升的项目。一个整合过程在后台定期运行,将有用的条目移入长期记忆并清理噪音。
对认真用户而言的突出特性:记忆具有时间感。你可以问“上周二我对 X 的看法是什么?”并得到智能体在那一刻的理解,而非今天的理解。没有其他 Hermes 插件能做到如此干净。一个值得注意的软性采用信号:Mnemosyne 是唯一一个有人特意为其编写了专用 Hermes 技能封装(一个教会智能体如何智能使用它的小文件)的社区记忆插件。其他人都没有这么做。
其他值得了解的项目
- Ladybug Memory - 纯本地方案,内置重要性排序。每条记忆都会得到一个 1 到 10 的分数,让系统优先呈现重要的内容,而不是一视同仁。如果你想要完全本地的记忆,且内置的 MEMORY.md 上限对你的知识量来说太小,就选它。
- yantrikdb - 当你需要知道智能体为什么召回某条记忆时,选这个。每次检索都会附带一条“为什么被检索”的解释,这在智能体呈现了错误内容需要调试时很有用,也适用于需要审计是什么影响了智能体响应的高信任场景。开箱即用内嵌运行,无需管理单独的数据库。
- hermes-agentmemory - 针对 Hermes 一个真实问题的社区修复:当你让智能体忘记某件事时,它其实并没有真正忘记——它会保留一份内部摘要,悄悄影响未来的召回。这个提供者执行真正的删除(删了就是删了),并记录每一次记忆操作,方便你审计发生了什么。如果合规、隐私或用户可控的遗忘对你很重要,就选它。
- PLUR - 跨智能体记忆桥。Hermes 的记忆通常无法到达 Cursor,Cursor 的记忆也无法到达 Claude Code。PLUR 把所有内容存储在一个共享的 .plur/ 文件夹中,所有智能体都能读取,因此你教给一个智能体的事实会自动出现在其他智能体中。如果你在同一个项目上使用多个智能体,不想分别重复教导每一个,就选它。
- FlowState-QMD - “猜猜你接下来需要什么”的提供者。它会尝试预测智能体的下一个可能的查询,并提前预热该记忆,这样当智能体真正搜索时,结果已经缓存好了,响应速度更快。如果你的智能体做重复性的长周期工作,且下一步通常可以从上下文中猜到,就选它。
有一件我本以为会存在但实际不存在的事:memory-as-skill(记忆即技能)实际上并不是一种模式。agentskills.io 标准意味着“技能”原则上可以实现记忆功能。但实际上,所有可信的持久化记忆都通过 MemoryProvider ABC 流转。即使是“做记忆”的技能(例如 Mnemosyne 的 SKILL.md),也只是插件的外壳,告诉智能体如何使用它们。
## 实际上该如何选择?
第一步:选择你的分层策略

第二步:选择你的第二层系统

以下是做得过重的警告信号:
- 智能体明显变慢了。以前大约一秒就能返回的响应,现在需要 3 秒以上。繁重的记忆层每一轮都会增加工作量,一旦延迟超过几秒,智能体就不再给人响应灵敏的感觉。
- 在相同的使用量下,你的 API 账单在悄然上升。记忆操作会消耗 token,一些提供者每次保存内容时还会触发额外的后台 LLM 调用。如果你的使用模式没变但开销增加了,就要怀疑是记忆层的问题。
- 智能体开始自相矛盾。它在一次会话中回忆起某个事实的一个版本,在下一次会话中却回忆起相反的版本,而且无法告诉你哪个是对的。这通常意味着记忆在不断累积却从未被整合——智能体现在正在从一个被污染的水井中取水。
- 智能体在对话中途耗尽了上下文。贪心的记忆层会侵蚀你的实际对话所需的上下文预算。如果你开始看到“上下文过长”的错误,或者智能体忘记了你五分钟前告诉它的事情,说明记忆层超支了。
- 你的工作实际上没有变好。这是最重要的一条。你添加记忆是期望获得更准确、更个性化的输出。几周之后,你能指出智能体在哪个具体方面确实比以前更好了吗?如果不能,说明记忆层没有配得上它的复杂性。把它撤掉吧。
希望你喜欢这篇关于 Hermes Agent 记忆全方位的深度解析。如果你想进一步探索 Hermes 生态,请访问 hermesatlas.com 并订阅 Hermes Atlas 新闻通讯,随时了解最新动态。
## 相关链接
- [Kevin Simback](https://x.com/KSimback)
- [@KSimback](https://x.com/KSimback)
- [11K](https://x.com/KSimback/status/2058262328496554021/analytics)
- [hermesatlas.com](https://hermesatlas.com/)
- [hermesatlas.com](https://hermesatlas.com/)
- [Nous Research](https://x.com/NousResearch)
- [智能体的护城河在哪里](https://x.com/compose/articles/edit/2044821377530597376)
- [Honcho (Plastic Labs)](https://hermesatlas.com/projects/plastic-labs/honcho)
- [@offendingcommit](https://x.com/@offendingcommit)
- [Mem0](https://hermesatlas.com/projects/mem0ai/mem0)
- [Hindsight](https://hermesatlas.com/projects/vectorize-io/hindsight)
- [Vectorize.io](https://vectorize.io/)
- [Holographic](https://github.com/NousResearch/hermes-agent/tree/main/plugins/memory/holographic)
- [OpenViking](https://openviking.ai/)
- [RetainDB](https://www.retaindb.com/)
- [ByteRover](https://docs.byterover.dev/autonomous-agents/hermes)
- [Supermemory](https://supermemory.ai/)
- [GBrain](https://hermesatlas.com/projects/garrytan/gbrain)
- [garrytan](https://x.com/garrytan)
- [Mnemosyne](https://hermesatlas.com/projects/AxDSan/mnemosyne)
- [Ladybug Memory](https://github.com/Ladybug-Memory/hermes-memory-plugin)
- [yantrikdb](https://github.com/yantrikos/yantrikdb-hermes-plugin)
- [hermes-agentmemory](https://github.com/MukundaKatta/hermes-agentmemory)
- [PLUR](https://hermesatlas.com/projects/plur-ai/plur)
- [FlowState-QMD](https://github.com/amanning3390/flowstate-qmd)
- [agentskills.io](https://agentskills.io/)
- [hermesatlas.com](https://hermesatlas.com/)
- [新闻通讯](https://hermesatlas.com/#newsletter)
- [升级到 Premium](https://x.com/i/premium_sign_up)
- [2026年5月24日 凌晨3:02](https://x.com/KSimback/status/2058262328496554021)
- [11.7K 次浏览](https://x.com/KSimback/status/2058262328496554021/analytics)
---
*导出时间: 2026/5/24 09:01:34*