构建永不遗忘的智能体:从基础到向量与图谱混合记忆方案 Akshay 2026-04-14 27.9 KB ☆ 收藏 𝕏 文章列表 文章深入探讨了LLM智能体的“记忆”难题,指出单纯增加上下文窗口无法解决“迷失在中间”效应及会话遗忘问题。作者基于认知科学框架,分析了从Python列表、Markdown文件到向量检索各阶段的局限性,强调构建兼具持久化、语义理解和关系推理能力的记忆层至关重要,最终引入了一个能够整合向量、图谱和关系存储的开源解决方案。 AgentMemoryLLMVector SearchGraph RAGLong-term MemoryContext WindowCognitive ScienceOpen Source 83 强烈推荐 ▶ 文章基于第一性原理深度剖析了Agent记忆系统的演进与痛点,包含丰富的技术细节与洞察,结构清晰且极具近期时效性。 # Build Agents that never forget **作者**: Akshay **日期**: 2026-04-13T17:36:17.000Z **来源**: [https://x.com/akshay_pachaar/status/2043745099792953508](https://x.com/akshay_pachaar/status/2043745099792953508) ---  A first-principles walk through agent memory: from Python lists to markdown files to vector search to graph-vector hybrids, and finally, a clean, open-source solution for all of this. 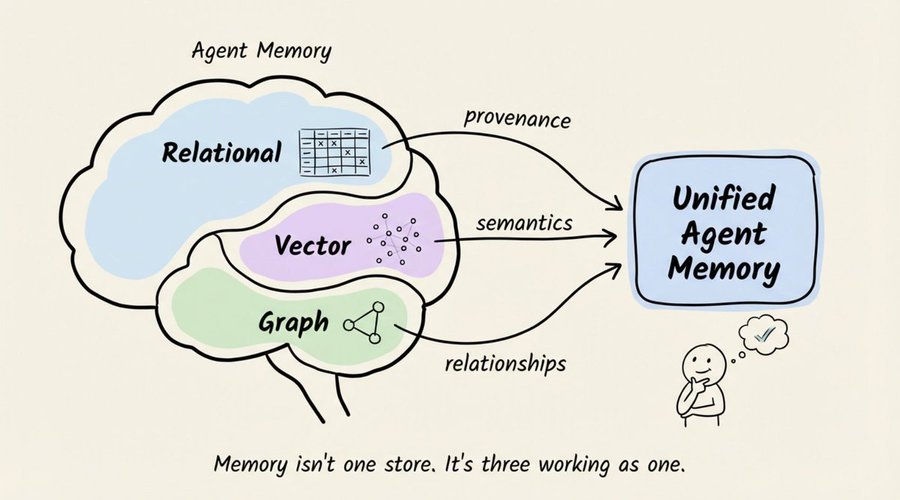 An LLM is stateless by design. Every API call starts fresh. The "memory" you feel when chatting with ChatGPT is an illusion created by re-sending the entire conversation history with every request. That trick works for casual chat. It falls apart the moment you try to build a real agent. Here are 7 failure modes show up the instant you skip memory: Context amnesia: the agent asks for information you already gave it Zero personalization: every interaction feels generic Multi-step task failure: intermediate state silently drops mid-task Repeated mistakes: no episodic recall means the same errors, forever No knowledge accumulation: every session starts from scratch Hallucination from gaps: when context overflows, the model invents Identity collapse: no continuity, no trust The obvious response is "throw more context at it." That's why 128K and 200K token windows feel like they should solve everything. They don't. Accuracy drops over 30% when relevant information sits in the middle of a long context. This is the well-documented "lost in the middle" effect. Context is a shared budget: system prompts, retrieved docs, conversation history, and output all fight for the same tokens. Even at 100K tokens, the absence of persistence, prioritization, and salience makes raw context length insufficient. 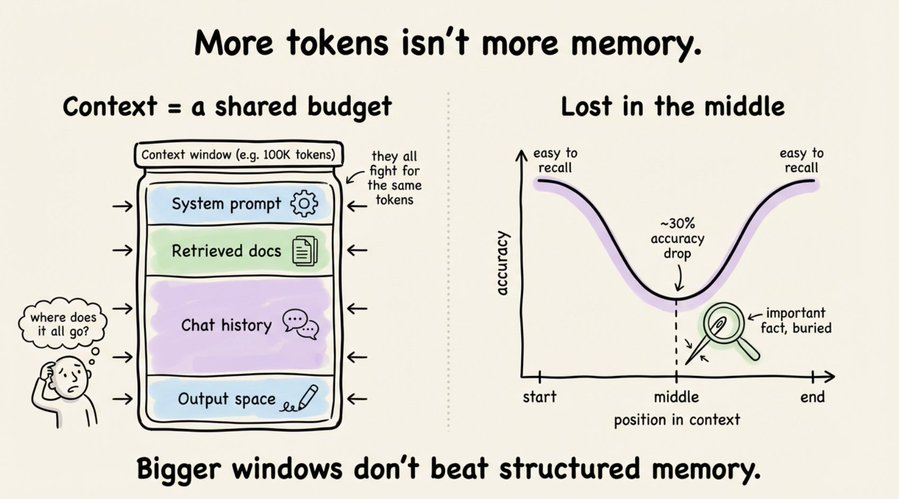 Memory isn't about cramming more text into the prompt. It's about structuring what the agent remembers so it can find what matters. ## The cognitive science frame that actually helps Lilian Weng's 2023 formulation has become the default framework: Agent = LLM + Memory + Planning + Tool Use. The four co-equal pillars. Her taxonomy borrows from cognitive science, where human memory splits into three systems: - Sensory memory captures raw perceptual input and holds it for a fraction of a second. Only the portions you pay attention to get passed forward. - Working memory is where active thinking happens. It holds roughly 7±2 items at a time (Miller's 1956 finding). Lose focus, and the contents disappear. - Long-term memory is durable storage with no practical capacity limit. Retrieval is the bottleneck: you can store millions of things and still fail to recall the one you need. Each maps directly to a component in modern agent architectures: 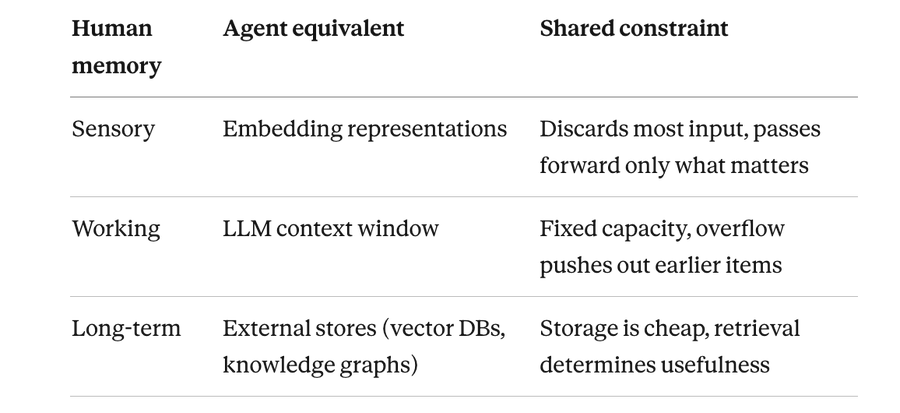 Long-term memory itself splits further: - Episodic: specific past events ("on Tuesday, the PostgreSQL cluster went down") - Semantic: facts and concepts ("PostgreSQL is a relational database") - Procedural: skills and workflows ("when a user asks for a refund, first check the purchase date") The bridge between episodic and semantic is memory consolidation: repeated specific events distilling into general knowledge. An agent that notices "users consistently prefer executive summaries" across dozens of interactions should turn that into a reusable rule. Without consolidation, your agent replays individual events rather than learning from them. 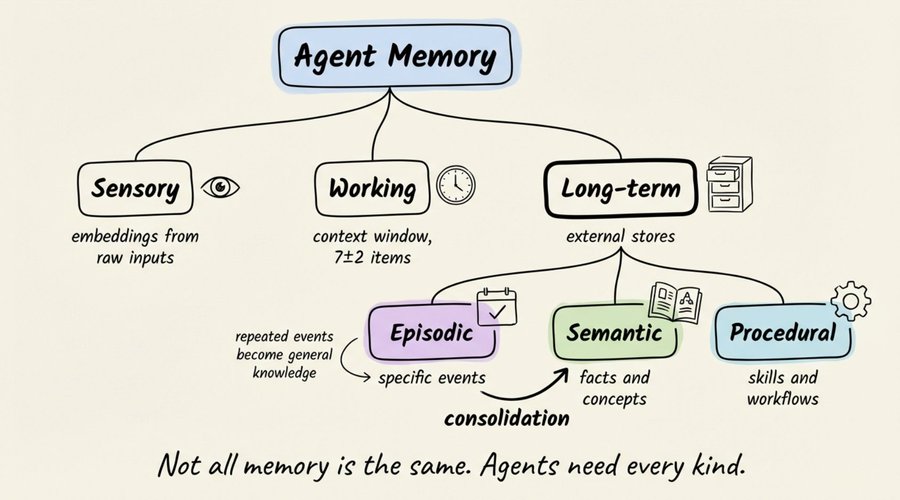 ## The minimal agent, and what breaks first Strip away the frameworks and an agent is a loop: perceive, think, act. Tell it "I have 4 apples," then ask "I ate one, how many left?" and it has no idea what apples you're talking about. Each call exists in isolation. ## Layer 1: The Python list The first fix everyone reaches for: Multi-turn works now. The apples question gets answered correctly because the full conversation re-ships with every call. Two problems show up fast: - The list grows unbounded. Around turn 200, you hit the context ceiling and the oldest messages silently drop. The user's name from turn 1 disappears long before yesterday's throwaway joke. No prioritization, just strict chronological order. - Everything lives in RAM. The moment the Python process ends, your agent has no idea who you are. ## Layer 2: Markdown files for persistence The next move is writing memory to disk. Markdown is a natural fit: human-readable, Git-friendly, and the agent can read it back as plain text. Claude Code uses exactly this pattern with CLAUDE.md and MEMORY.md files. Persistence is solved. Restart the script, and the conversation is still on disk. You could also maintain a separate facts file that the agent extracts over time: You can open the file in any editor, see exactly what the agent knows, and fix it by hand. Genuinely useful for prototyping. With 4 facts, this works perfectly. Load the entire file into context and the LLM handles any question about Sarah, her company, or her industry. Now fast-forward three months. Your agent has 2,000 extracted facts and 200 conversation logs. That's 500K+ tokens of markdown on disk, and your context window is 128K. You can no longer load everything. You need to selectively retrieve only the facts relevant to the current query. With flat files, your only option is keyword search: At small scale, markdown files work. At real scale, they force keyword retrieval, and keywords can't handle synonyms, paraphrases, or connections across facts. The information is on disk. But you can't load all of it, and keyword search is too brittle to find the right pieces. If you've used OpenClaw, you've seen this play out. It stores memory as markdown checkpoint files, and over weeks of daily use, earlier facts quietly slip away as context accumulates and gets compacted. The storage is there. The retrieval isn't. Storage without intelligent retrieval is a library with no catalog. ## Layer 3: Vector search and the wall it hits Bolt on embeddings. Chunk your markdown, embed the chunks, search by cosine similarity. Now "database" matches "PostgreSQL" because their vectors live close together in embedding space. The synonym problem dissolves. Then you hit a new wall. Consider these three facts in your vector DB: User asks: "Was Alice's project affected by Tuesday's outage?" The query mentions Alice and Tuesday's outage, so vector search ranks the first and third facts high. But the critical bridge, "Project Atlas uses PostgreSQL," mentions neither Alice nor Tuesday. It's the connecting piece, and it's the one that won't surface. Each fact is an isolated point in embedding space. The connective tissue linking them is invisible to vectors.  This isn't an edge case. It's the normal shape of real-world questions. Business knowledge is inherently relational: people belong to teams, teams own projects, projects depend on systems, systems have incidents. Any question that crosses two or more hops exceeds what flat vector retrieval can answer. ## The capability matrix Each layer fixes the previous pain but reveals a deeper one: 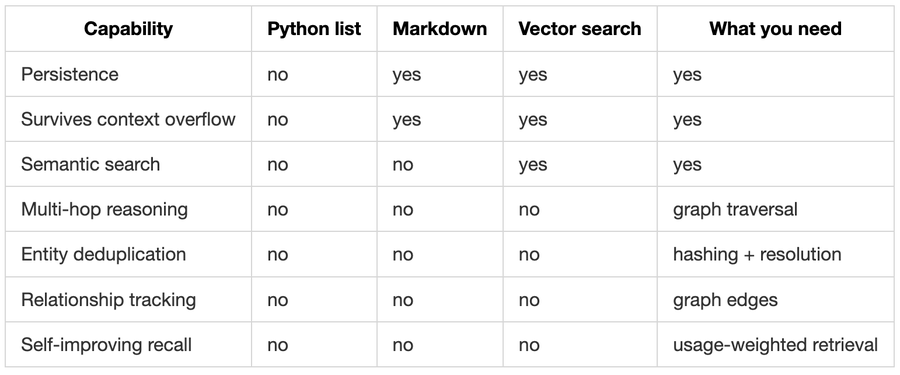 You need persistence, semantic understanding, and relational reasoning in a single memory layer. Building this yourself means gluing together a vector database, a graph database, a relational store, an entity extractor, a deduplication pipeline, and an edge-weighting system. That's weeks of infrastructure work before you write a single line of agent logic. I've been using a solution that fills this gap cleanly. It's fully open-source, handles all three storage paradigms under one roof, and you can get it running in minutes. Let's talk about Cognee. Cognee: three stores, one engine, four calls Cognee is an open-source knowledge engine built for agent memory. It combines vector search with knowledge graphs and a relational provenance layer into a single system. The entire API surface is four async calls: Behind those four calls sits a three-store architecture.  Why three stores and not one ? Each store captures a dimension of knowledge the others can't: - Relational store → provenance: where data came from, when it was ingested, who has access - Vector store → semantics: what content means, what it's similar to - Graph store → relationships: how entities connect, what causes what, who reports to whom Flatten any of these and you lose information that matters for retrieval accuracy. The default stack is SQLite + LanceDB + Kuzu, entirely embedded and file-based. pip install cognee plus an LLM API key and you're running. No Docker, no external services. For production, swap SQLite for Postgres, LanceDB for Qdrant/Pinecone/pgvector, and Kuzu for Neo4j/FalkorDB/Neptune. Same four-call API either way. ## What cognify actually does? cognee.cognify() runs a multi-stage pipeline that converts raw text into structured, interconnected knowledge: Document classification by type and domain Permission checking for multi-tenant access control Chunk extraction that respects paragraph structure (not fixed-size cuts) Entity and relationship extraction via LLM, with automatic deduplication through content hashing Summary generation for efficient retrieval Dual indexing into the vector store (embeddings) and graph store (edges) The deduplication step matters more than it sounds. If the same entity shows up across 50 documents, Cognee merges it into a single graph node with 50 inbound edges. Your agent no longer sees "Alice" as 50 different strangers. And the pipeline is incremental by default: only new or updated files get reprocessed. 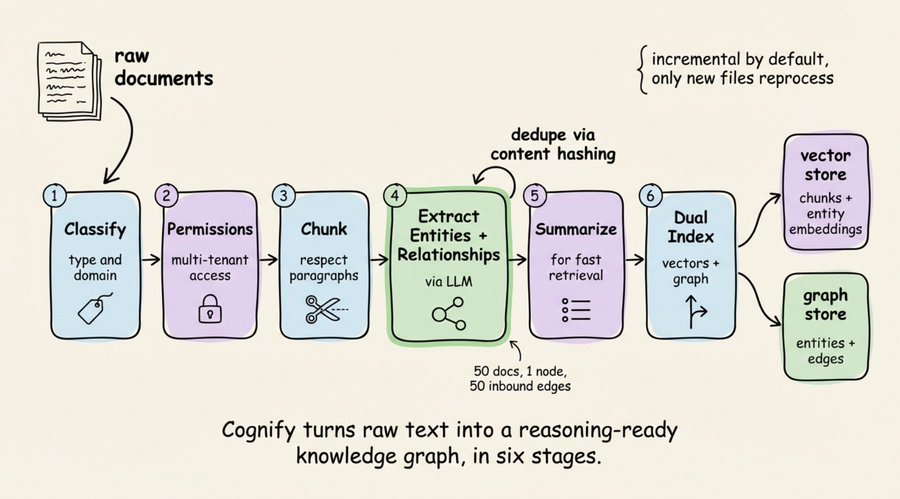 Every graph node has a corresponding embedding. This dual representation is the core trick: enter through vectors (find semantically similar content) and exit through the graph (follow relationships to connected entities), or the reverse. That's what makes multi-hop queries work without sacrificing semantic search. ## Memify: memory that learns memify() is what separates Cognee from every "ingest and search" tool. It runs an RL-inspired optimization pass over the graph: - Strengthening useful paths that led to good retrieval - Pruning stale nodes that haven't been touched - Auto-tuning edge weights based on real usage - Adding derived facts by identifying implicit relationships A customer support agent's graph naturally strengthens paths through product docs and refund policies while letting rarely-queried HR edges decay. The graph develops its own sense of relevance over time. 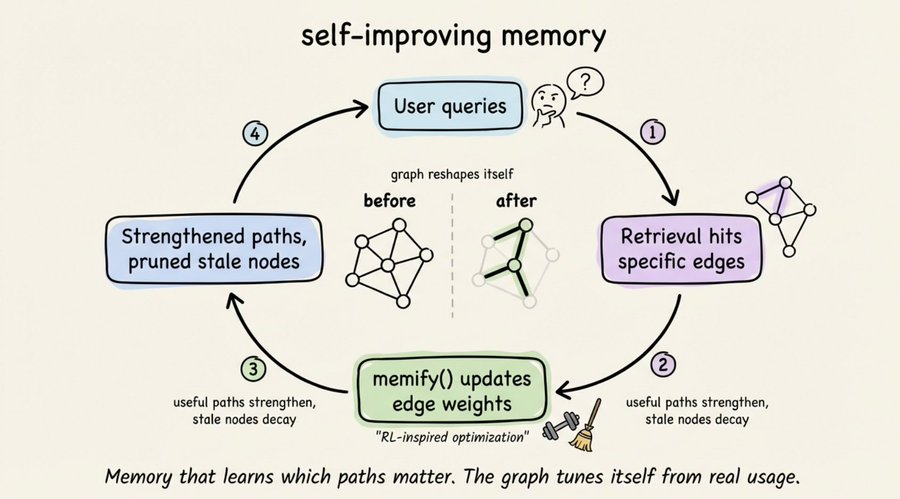 ## Fourteen retrieval modes Cognee ships 14 search modes. The ones you'll actually reach for: 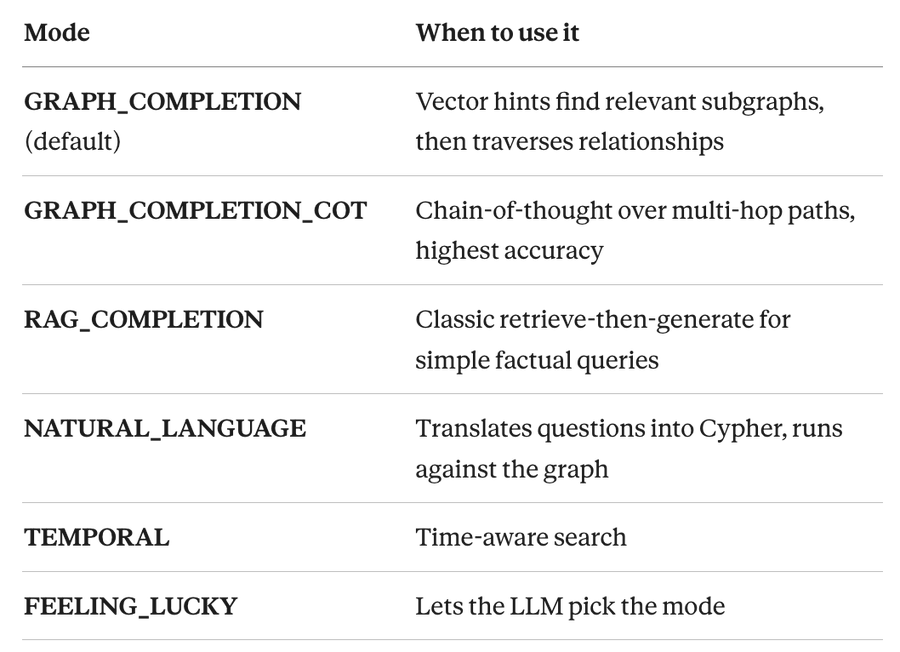 Building a real agent with Cognee memory Here's the complete pattern wiring Cognee into the perceive-think-act loop: The memory cycle: ingest, extract, store, retrieve, respond, store again. Each turn enriches the knowledge graph, and incremental processing means you only pay to index new content. Session memory handles pronoun resolution automatically: Multi-tenancy is built in at the graph level with per-dataset permissions (read, write, delete, share). Not namespace separation, actual graph-level isolation. ## The practical path forward If you're building an agent today, the real starting question is: "what does my agent need to remember, and what kind of questions will it answer?" If your queries only need similarity search ("find conversations like this one"), vector-only memory works. The moment queries cross entity boundaries ("Was Alice's project affected by Tuesday's outage?"), you need graph traversal. You can wire together separate vector, graph, and relational stores yourself. Teams that go this route typically burn weeks on infrastructure for a memory layer that still doesn't learn from its own usage. Cognee collapses that into four API calls. Embedded defaults get you running in minutes. Swappable backends (Postgres, Qdrant, Neo4j) take you to production without changing your agent code. Intelligence requires structure, not just storage. The three storage paradigms (relational, vector, graph) aren't competing options. They're complementary layers of the same memory system. Treating them that way is what turns a stateless LLM wrapper into something that actually learns. What's the next thing you'd want your agent to remember tomorrow that it forgot today? Start there. 👉 Check out Cognee on GitHub →, give it a star, and try wiring it into your next agent. Four async calls, a pip install, and you're running. That's a wrap! If you enjoyed reading this: Find me →@akshay_pachaar ✔️ Every day, I share tutorials and insights on AI, Machine Learning, and vibe coding best practices. ## 相关链接 - [Akshay](https://x.com/akshay_pachaar) - [@akshay_pachaar](https://x.com/akshay_pachaar) - [53K](https://x.com/akshay_pachaar/status/2043745099792953508/analytics) - [Miller's 1956 finding](https://pmc.ncbi.nlm.nih.gov/articles/PMC4486516/) - [Cognee: three stores, one engine, four calls](https://github.com/topoteretes/cognee) - [Cognee](https://github.com/topoteretes/cognee) - [Cognee collapses that into four API calls](https://github.com/topoteretes/cognee) - [Check out Cognee on GitHub →](https://github.com/topoteretes/cognee) - [@akshay_pachaar](https://x.com/@akshay_pachaar) - [Upgrade to Premium](https://x.com/i/premium_sign_up) - [1:36 AM · Apr 14, 2026](https://x.com/akshay_pachaar/status/2043745099792953508) - [53K Views](https://x.com/akshay_pachaar/status/2043745099792953508/analytics) - [View quotes](https://x.com/akshay_pachaar/status/2043745099792953508/quotes) --- *导出时间: 2026/4/14 13:12:16* --- ## 中文翻译 # 构建永不遗忘的智能体 **作者**: Akshay **日期**: 2026-04-13T17:36:17.000Z **来源**: [https://x.com/akshay_pachaar/status/2043745099792953508](https://x.com/akshay_pachaar/status/2043745099792953508) ---  从第一性原理出发讲解智能体记忆:从 Python 列表到 Markdown 文件,再到向量搜索和图-向量混合方案,最后给出一个干净的开源解决方案,涵盖这一切。  LLM 在设计上是无状态的。每次 API 调用都从零开始。你与 ChatGPT 聊天时感受到的“记忆”,只是一种幻觉——它是通过在每次请求时重新发送完整对话历史制造的。 这种技巧对日常闲聊有效。但一旦你试图构建真正的智能体,它就会失效。 一旦跳过记忆,以下 7 种失败模式立刻会出现: 上下文失忆:智能体向你询问你已经提供过的信息 零个性化:每次交互都显得千篇一律 多步任务失败:中间状态在任务执行途中悄然丢失 重复犯错:没有情景记忆意味着同样的错误永远重演 无法积累知识:每次会话都从零开始 因信息缺口而产生幻觉:当上下文溢出时,模型开始编造 身份崩溃:没有连续性,就没有信任 显而易见的应对是“给它更多上下文”。这正是为什么 128K 和 200K token 的窗口看起来应该能解决一切问题。 实际上解决不了。 当相关信息位于长上下文的中间位置时,准确率下降超过 30%。这就是被广泛记录的“迷失在中间”效应。 上下文是一个共享预算:系统提示词、检索到的文档、对话历史和输出都在争夺同样的 token。 即使有 100K token,由于缺乏持久化、优先级排序和显著性机制,单纯的上下文长度仍然不够。  记忆不是往提示词里塞更多文本。而是对智能体记住的内容进行结构化,使它能够找到重要的东西。 ## 真正有用的认知科学框架 Lilian Weng 在 2023 年提出的公式已成为默认框架: 智能体 = LLM + 记忆 + 规划 + 工具使用。 四大平等的支柱。 她的分类借鉴了认知科学,其中人类记忆分为三个系统: - 感觉记忆捕捉原始感知输入,并只保留几分之一秒。只有你注意到的那部分才会被传递下去。 - 工作记忆是主动思考发生的地方。它一次大约容纳 7±2 个项目(Miller 在 1956 年的发现)。一旦分心,内容就会消失。 - 长期记忆是持久存储,几乎没有实际容量限制。瓶颈在于检索:你可以存储数百万条信息,却仍然无法回忆起需要的那一条。 每一项都直接对应现代智能体架构中的一个组件:  长期记忆本身还可进一步细分: - 情景记忆:具体的过往事件(“周二,PostgreSQL 集群宕机了”) - 语义记忆:事实和概念(“PostgreSQL 是一个关系型数据库”) - 程序记忆:技能和工作流(“当用户要求退款时,先检查购买日期”) 情景记忆与语义记忆之间的桥梁是记忆巩固:重复的具体事件蒸馏为一般性知识。一个在数十次交互中注意到“用户始终偏好执行摘要”的智能体,应该把它转化为一条可复用的规则。没有巩固机制,你的智能体只会重播单个事件,而不是从中学习。  ## 最简智能体,以及最先崩溃的部分 剥离所有框架之后,智能体就是一个循环:感知、思考、行动。 告诉它“我有 4 个苹果”,然后问“我吃了一个,还剩几个?”——它完全不知道你说的是哪些苹果。每次调用都是孤立存在的。 ## 第一层:Python 列表 每个人都会想到的第一个修复方案: 多轮对话现在可以工作了。苹果问题得到了正确回答,因为完整的对话随每次调用一起重新发送。 但两个问题很快显现: - 列表会无限增长。大约到第 200 轮时,你会触及上下文上限,最旧的消息被悄然丢弃。第 1 轮中用户的名字早在昨天的随口玩笑之前就消失了。没有优先级,只有严格的按时间顺序排列。 - 一切都存在于 RAM 中。Python 进程一结束,你的智能体就完全不认识你了。 ## 第二层:用 Markdown 文件实现持久化 下一步是把记忆写入磁盘。Markdown 是一个天然的选择:人类可读、对 Git 友好,而且智能体可以把它当作纯文本读回来。Claude Code 使用的正是这种模式,通过 CLAUDE.md 和 MEMORY.md 文件。 持久化解决了。重启脚本,对话仍然保留在磁盘上。你还可以维护一个单独的事实文件,由智能体随时间从中提取信息: 你可以在任何编辑器中打开这个文件,清楚地看到智能体知道什么,并手动修正它。这对原型开发确实非常有用。 只有 4 条事实时,这完美运作。把整个文件加载进上下文,LLM 就能回答任何关于 Sarah、她的公司或她的行业的问题。 现在快进三个月。你的智能体积累了 2,000 条提取的事实和 200 份对话日志。磁盘上有超过 50 万 token 的 Markdown,而你的上下文窗口只有 128K。 你已经无法加载全部内容了。你需要有选择地只检索与当前查询相关的事实。对于扁平文件,你唯一的选择是关键词搜索: 在小规模下,Markdown 文件可行。在真实规模下,它们迫使你使用关键词检索,而关键词无法处理同义词、改述或跨事实的关联。 信息就在磁盘上。但你无法全部加载,而关键词搜索又太脆弱,找不到正确的部分。 如果你用过 OpenClaw,你就见过这种情况上演。它将记忆存储为 Markdown 检查点文件,而在数周的日常使用中,随着上下文不断积累并被压缩,较早的事实悄然溜走。存储有了。检索却没有。 没有智能检索的存储,就是一座没有目录的图书馆。 ## 第三层:向量搜索及其撞上的墙 再加上嵌入(embeddings)。把你的 Markdown 分块,对块进行嵌入,然后通过余弦相似度搜索。现在“数据库”能匹配到“PostgreSQL”,因为它们的向量在嵌入空间中彼此接近。同义词问题迎刃而解。 然后你会撞上新的墙。看看向量数据库中的这三条事实: 用户问:“Alice 的项目受到周二故障的影响了吗?” 查询提到了 Alice 和周二的故障,因此向量搜索会把第一条和第三条事实排在前面。但关键的桥梁——“Project Atlas 使用 PostgreSQL”——既没提到 Alice 也没提到周二。它是连接性的那一环,却恰恰是不会浮现出来的那一个。 每条事实都是嵌入空间中的一个孤立点。将它们连接起来的组织结构对向量来说是不可见的。  这并非边缘案例。这就是现实世界问题的常态形态。业务知识本质上是关系型的:人属于团队,团队拥有项目,项目依赖系统,系统会发生事故。任何跨越两跳或更多跳的查询都超出了扁平向量检索所能回答的范围。 ## 能力矩阵 每一层都修复了之前的痛点,但也暴露出更深一层的问题:  你需要在单一的记忆层中同时具备持久化、语义理解和关系推理。 自己搭建这一切意味着把向量数据库、图数据库、关系型存储、实体提取器、去重流水线和边权重系统粘合在一起。在你写下第一行智能体逻辑之前,这已经是数周的基础设施工作。 我一直在使用一个能干净利落填补这一空白的解决方案。它完全开源,在同一屋檐下处理所有三种存储范式,而且几分钟内就能跑起来。让我们来聊聊 Cognee。 Cognee:三个存储,一个引擎,四次调用 Cognee 是一个为智能体记忆构建的开源知识引擎。它将向量搜索、知识图谱和关系型溯源层结合到一个系统中。 整个 API 面只有四个异步调用: 在这四次调用背后是一个三存储架构。  为什么要三个存储而不是一个? 每个存储捕捉的都是其他存储无法捕捉的知识维度: - 关系型存储 → 溯源:数据从哪来、何时被摄取、谁有访问权限 - 向量存储 → 语义:内容是什么意思、与什么相似 - 图存储 → 关系:实体如何连接、什么导致什么、谁向谁汇报 抹平其中任何一个,你都会丢失对检索准确性至关重要的信息。 默认技术栈是 SQLite + LanceDB + Kuzu,完全嵌入式且基于文件。pip install cognee 加上一个 LLM API 密钥,你就能运行。 不需要 Docker,不需要外部服务。 生产环境中,可以把 SQLite 换成 Postgres,LanceDB 换成 Qdrant/Pinecone/pgvector,Kuzu 换成 Neo4j/FalkorDB/Neptune。 无论哪种方式,都是同样的四次调用 API。 ## cognify 到底做了什么? cognee.cognify() 运行一个多阶段流水线,将原始文本转换为结构化、相互关联的知识: - 按类型和领域对文档分类 - 针对多租户访问控制的权限检查 - 尊重段落结构的分块提取(而非固定大小切割) - 通过 LLM 进行实体和关系提取,并借助内容哈希实现自动去重 - 为高效检索生成摘要 - 双重索引:向量存储(嵌入)和图存储(边) 去重这一步比听起来更重要。如果同一实体出现在 50 个文档中,Cognee 会将其合并为一个图节点,并带有 50 条入边。你的智能体不再把“Alice”看作 50 个不同的陌生人。而且流水线默认是增量的:只有新增或更新的文件才会被重新处理。  每个图节点都有对应的嵌入。这种双重表示是核心技巧:通过向量进入(找到语义相似的内容),再通过图离开(沿关系追踪到相连的实体),或者反过来。这正是让多跳查询得以工作、同时不牺牲语义搜索的原因。 ## Memify:会学习的记忆 memify() 是 Cognee 区别于所有“摄取加搜索”工具的地方。它在图上运行一个受强化学习启发的优化过程: - 强化那些带来良好检索结果的有用路径 - 剪除长期未被触及的陈旧节点 - 根据实际使用情况自动调整边权重 - 通过识别隐式关系来添加派生事实 一个客服智能体的图会自然强化经过产品文档和退款政策的路径,同时让很少被查询的 HR 边逐渐衰减。图会随着时间发展出自己的相关性判断。  ## 十四种检索模式 Cognee 提供了 14 种搜索模式。你真正会用到的有:  用 Cognee 记忆构建真实的智能体 下面是将 Cognee 接入“感知—思考—行动”循环的完整模式: 记忆循环:摄取、提取、存储、检索、响应、再次存储。每一轮都会丰富知识图谱,而增量处理意味着你只需为新内容付费索引。 会话记忆自动处理代词消解: 多租户在图级别内置,具备按数据集的权限(读、写、删除、共享)。不是命名空间隔离,而是真正的图级隔离。 ## 切实可行的前进道路 如果你今天正在构建智能体,真正的起点问题是:“我的智能体需要记住什么,它要回答什么样的问题?” 如果你的查询只需要相似度搜索(“找到与这段对话类似的对话”),仅用向量的记忆就够了。一旦查询跨越实体边界(“Alice 的项目受到周二故障的影响了吗?”),你就需要图遍历。 你可以自己将独立的向量、图和关系存储拼接起来。走这条路线的团队通常会在基础设施上耗费数周时间,构建出一个依然无法从自身使用中学习的记忆层。 Cognee 将这一切浓缩为四个 API 调用。内置的默认配置让你几分钟内就能跑起来。可替换的后端(Postgres、Qdrant、Neo4j)让你无需更改智能体代码即可投入生产。 智能需要结构,而不仅仅是存储。这三种存储范式(关系型、向量、图)并非相互竞争的选项,而是同一个记忆系统的互补层次。以这种方式对待它们,才能把一个无状态的 LLM 包装器变成真正会学习的东西。 你希望你的智能体明天记住、而今天却忘记了的东西是什么?从这里开始。 👉 前往 GitHub 查看 Cognee →,给它点个星,并试着把它接入你的下一个智能体。 四个异步调用、一次 pip install,你就跑起来了。 本次分享到此结束! 如果你喜欢这篇文章: 关注我 →@akshay_pachaar ✔️ 每天,我都会分享关于 AI、机器学习和 vibe coding 最佳实践的教程与见解。 ## 相关链接 - [Akshay](https://x.com/akshay_pachaar) - [@akshay_pachaar](https://x.com/akshay_pachaar) - [53K](https://x.com/akshay_pachaar/status/2043745099792953508/analytics) - [Miller 1956 年的发现](https://pmc.ncbi.nlm.nih.gov/articles/PMC4486516/) - [Cognee:三个存储,一个引擎,四次调用](https://github.com/topoteretes/cognee) - [Cognee](https://github.com/topoteretes/cognee) - [Cognee 将这一切浓缩为四个 API 调用](https://github.com/topoteretes/cognee) - [前往 GitHub 查看 Cognee →](https://github.com/topoteretes/cognee) - [@akshay_pachaar](https://x.com/@akshay_pachaar) - [升级到 Premium](https://x.com/i/premium_sign_up) - [2026年4月14日 凌晨1:36](https://x.com/akshay_pachaar/status/2043745099792953508) - [5.3万次浏览](https://x.com/akshay_pachaar/status/2043745099792953508/analytics) - [查看引用](https://x.com/akshay_pachaar/status/2043745099792953508/quotes) --- *导出时间: 2026/4/14 13:12:16*
A Agent 的数据面概念扫盲-建立技术侧认知体系 本文深入解析了 Agent 数据面的核心概念,将其比作操作系统的内存管理单元。文章详细阐述了 Context Engineering 的演变、Session/Thread/Profile 的架构差异,以及 Session Memory 与 Long-term Memory 的区别。作者还重点介绍了 Hermes 中的 Memory 设计方案、SQLite FTS5 与 BM25 算法原理,以及向量检索与关键词检索在 RAG 中的混合应用,旨在为开发者建立一套完整的 Agent 数据面技术认知体系。 技术 › Agent MateMatt 2026-07-12 AgentContext EngineeringRAGMemoryBM25SQLite FTS5向量检索HermesLong-term MemoryLLM
A Agent Memory Is Not a Search Problem 文章指出 Agent 记忆系统的核心问题不是检索而是上下文组织。跨 15 个模型、20 万模拟对话的研究显示,任务拆分为多轮会使准确率平均下降 39%,而合并为单轮可恢复大部分损失。文章回顾了 Agent 记忆的四个发展阶段(全量历史、滚动摘要、向量检索、知识图谱),批评语义/情景/程序性记忆分类无法指导检索决策,并主张按六种问题类型构建六种上下文形态。作者基于开源 Graphiti 引擎,以客户历史为例实操演示如何让记忆系统在模型运行前正确组织上下文,避免基于过时信息的自信回答。 技术 › Agent Akshay 2026-09-29 AgentLLMMemory知识图谱Graphiti上下文工程向量检索RAG
O Open Memory, Own the Intelligence 本文探讨了AI Agent开发中开放Harness与记忆所有权的重要性。作者引用Harrison Chase的观点——'不拥有Harness就不拥有记忆',并区分了Memory(从上下文窗口记录的事实,如用户偏好、仓库知识)和Intelligence(利用这些事实让会话更智能的机制)。文章详细介绍了Mem0的方案:通过custom_instructions和infer=False控制记忆提取,用语义+BM25+实体搜索进行检索,并借助Dream实现记忆合并、替代与综合。作者主张将记忆层置于Harness之外,存储于SQL、向量数据库和实体存储中,从而实现跨Harness的记忆与智能的可移植性,即使前沿实验室的循环保持封闭。 技术 › Agent mem0 2026-09-15 Mem0AgentMemoryHarnessLLM开源可移植性LangChainClaude Code
未 未来 Skill 的终极形式 → Agent 大脑 文章探讨为什么同一个 Skill 在不同人手中运行效果差异巨大:Skill 如同课本,本身不等于能力,离开适配的环境便难以发挥作用。作者引用 OpenAI 产品负责人 Tibo 的观点和 Karpathy 的 LLM Knowledge Bases 实践,提出未来 Skill 的终极形式是 Agent 大脑——一个持续吸收 Skill、理解本地环境、积累真实运行反馈并自主更新演化的个人知识库。真正拉开 Agent 能力差距的,不是安装了多少 Skill,而是外部知识能否被熔炼进属于自己的系统。 技术 › Skill vink 2026-08-29 AgentSkill知识库KarpathyLLMMemory个人知识管理环境适配自主进化
M Memory Engineering: retrieval is the job 文章探讨了 AI Agent 记忆工程的核心问题:存储已解决,检索才是关键。指出存储过多信息会导致检索性能大幅下降,并引用 LongMemEval 等研究数据证明“更多记忆,更差召回”。文章介绍了记忆的三种类型(情景、语义、程序)和四种操作(写入、检索、衰减、巩固),强调了“少写、精检”的重要性。 技术 › Agent Roxx 2026-08-06 AgentMemoryRetrievalLLMCoALAEngineering
A Agent 系统中的上下文与记忆工程 本文探讨了在 Agentic AI 系统中,上下文工程与记忆工程如何解决不同问题。上下文工程专注于单次推理调用的设计,涵盖选择性包含、结构放置、压缩和历史管理;记忆工程则关注跨会话的持久化,涉及写入策略、存储层选择和检索策略。两者在检索边界交汇,共同决定了 Agent 在实际工作负载中的可靠性。 技术 › Agent beamnxw 2026-08-05 AgentMemoryContextRAGSystem DesignLLMEngineeringAI
本 本周顶级 AI 论文精选 文章精选了本周 6 篇顶级 AI 论文,涵盖 Harness Handbook、MSCE 记忆技能框架、PRO-LONG 长程记忆机制、Anthropic 全局工作空间解释性研究、Meta 的 GAMUT 完整性基准测试以及渐进式披露模式。 技术 › LLM DAIR.AI 2026-07-27 AI论文AgentMemoryInterpretabilityAnthropicMetaLLMResearch
T The Graph Engineering Setup Guide 本文介绍了图工程如何为Agent提供复合记忆。通过双时态模型和MCP配置,Claude可获得持久的图记忆,相比向量搜索,多跳任务准确率提升36-46%,幻觉减少40%以上。 技术 › Agent darkzodchi 2026-07-24 Graph EngineeringGraph RAGMemoryMCPClaude CodeNeo4jKnowledge GraphAgent
A AI 视频剪辑 Skill 分享:video-use 文章介绍了开源项目 video-use,这是一套面向 AI Coding Agents 的视频剪辑 Skill。其核心理念是让 LLM 通过“阅读转写文本”而非直接观看视频来理解内容,结合 ffmpeg 等工具实现自动化剪辑。文章详细阐述了从转写、打包、决策到渲染的完整技术流水线,并分享了包括分段拼接、淡入淡出、时移对齐等关键的工程实现细节与“铁律”规则,旨在实现生产级的视频自动化处理。 技术 › Skill meng shao 2026-07-03 AI视频剪辑AutomationLLMffmpegAgentEngineeringOpen SourceVideo
T The Hermes Agent Memory Guidebook 这是一份关于 Hermes Agent 记忆系统的终极指南。文章深入解析了 Hermes 的三层记忆架构:开箱即用的原生层、可选的插件层以及社区扩展层。作者详细说明了本地数据库与 Markdown 文件的协同工作机制,澄清了关于记忆合并的常见误区,并强调了记忆在 Agent 从无状态聊天机器人转变为具备技能累积和个性化能力的智能体过程中的关键作用。 技术 › Agent Kevin Simback 2026-05-28 HermesAgentMemoryArchitectureNous ResearchTutorialMemory ManagementLLM
A Agent Memory Framework: Remember, Cite, Forget 本文提出了一个智能体记忆系统的可靠框架,该框架需同时完成三个核心任务:记住该记的、引用可信的、遗忘过期的。文章详细介绍了记忆的六个层级(如会话状态、项目记忆、索引检索等),阐述了如何通过权威排序解决冲突,并强调了通过硬过期、双时序或软衰减等机制让旧记忆失效的重要性。 技术 › Agent Vox 2026-05-23 AgentMemoryRAGLangGraphMem0ZepGBrainLLM系统架构工程实践
A Agentic Memory: 详解 Agent 记忆系统的架构与实现 文章通过生动的类比,指出缺乏记忆是当前 LLM Agent 的主要短板。作者详细拆解了 Agent 记忆系统的三个核心功能:连续性、上下文和学习。文章重点介绍了四种记忆类型:上下文记忆、外部记忆、情景记忆和参数记忆,并深入探讨了如何通过检索增强(RAG)和反思循环来构建持久的智能。 技术 › Agent Ramakrishna (techwith_ram) 2026-05-17 AgentLLMMemoryArchitectureRAGVectorStoreContextEpisodic向量数据库系统设计