# CUDA from zero to hero #1
**作者**: Pramod Goyal
**日期**: 2026-09-25T19:21:46.000Z
**来源**: [https://x.com/goyal__pramod/status/2103565642800431533](https://x.com/goyal__pramod/status/2103565642800431533)
---
These are my notes as I learn CUDA; here I will try to break down things and represent them in a way that makes the most sense to me. I like to truly understand things internally, so I will try to explain them in enough detail.
I believe the best way to go about this is to actually write CUDA kernels ourselves and improve over time.
I will like this series to be exhaustive enough to bring any newbie up to SOTA level. I will mention blogs/books/videos as I keep learning and growing.
> Note: This is an adaptive article, and I will keep adding (and sometimes removing) as I gain a better understanding of things.
Now let us begin with... understanding the hardware. Now hear me out when it comes to CUDA. Understanding what GPU you have and how it works is equally important as understanding the code. Because these are tightly coupled.
## Understanding the GPU
Now one obvious question that arises is: why do we even have GPUs? Aren't CPUs enough? Can we not combine them*? Why have a separate module at all?
*Interestingly, this is exactly what Apple did; you can understand more about it [here](https://discussions.apple.com/thread/255191914?sortBy=rank) (I remember watching a beautiful video explaining this in greater depth, I forgot about it. If you know what I am talking about, please reach out!).
This is what a CPU looks like
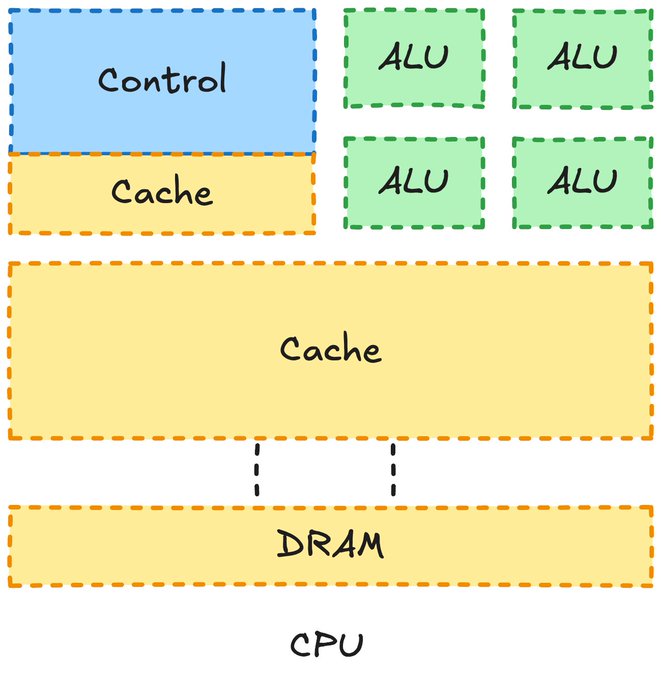
Inspired from PMPP
the different parts are
DRAM -> Dynamic Random Access Memory, this is where data gets stored before computation
CACHE -> Temporary memory space to store on the fly computational values
CONTROL -> Determines where to send the computation, where to store data. It's the control center!
ALU -> Arithmetic Logic Unit, this is the part that takes care of computation.
> Note: This is a gross over simplification of how CPUs look like (even GPUs when we get to it), this is meant to help you understand the core components and how they work. As we go through the article we will gradually break down these high level components to their individual sub parts and understand how they work!
Now this is great if you want to do things in sequence,i.e one after the other. In CPUs we even have multiple cores so you can run multiple computation in parallel (multi-threading, parallelism ,and async are all different ideas consider [reading](https://stackoverflow.com/questions/27435284/multiprocessing-vs-multithreading-vs-asyncio) this to understand the difference.)
Now imagine a matrix multiplication, the core of most of AI. It is an operation which if you think about can be run in parallel, each output value can be calculated independently of the other output values all you need is the row and column vector for that i and j values.
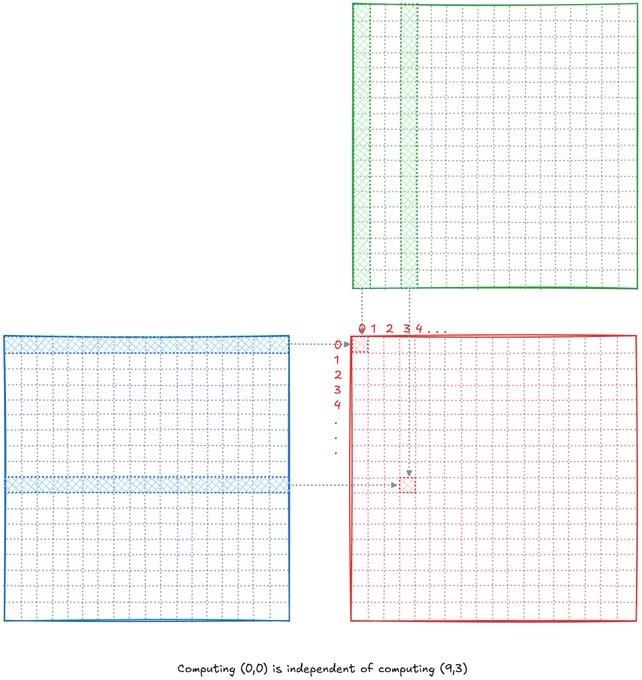
And to enable this, what would we need differently from the CPU... well it isn't hard to answer: more ALUS!!! because we want to compute these values ASAP, and that is why a GPU in general looks like this
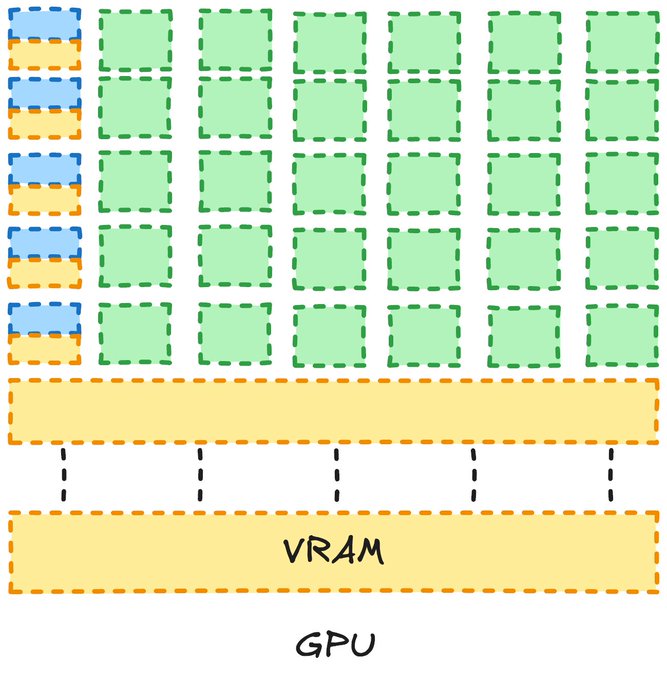
> NOTE: Again, this GPU architecture is an oversimplification. But it is necessary info to get the point across. As we get more advanced, we will add on to our existing knowledge and make the diagrams more complex!
As you can see above, we have way more ALUs. Let's understand them better by looking at what the individual parts are called. We will explore them a bit more in detail unlike the CPU section above as this article is all about understanding GPUs and CUDA.
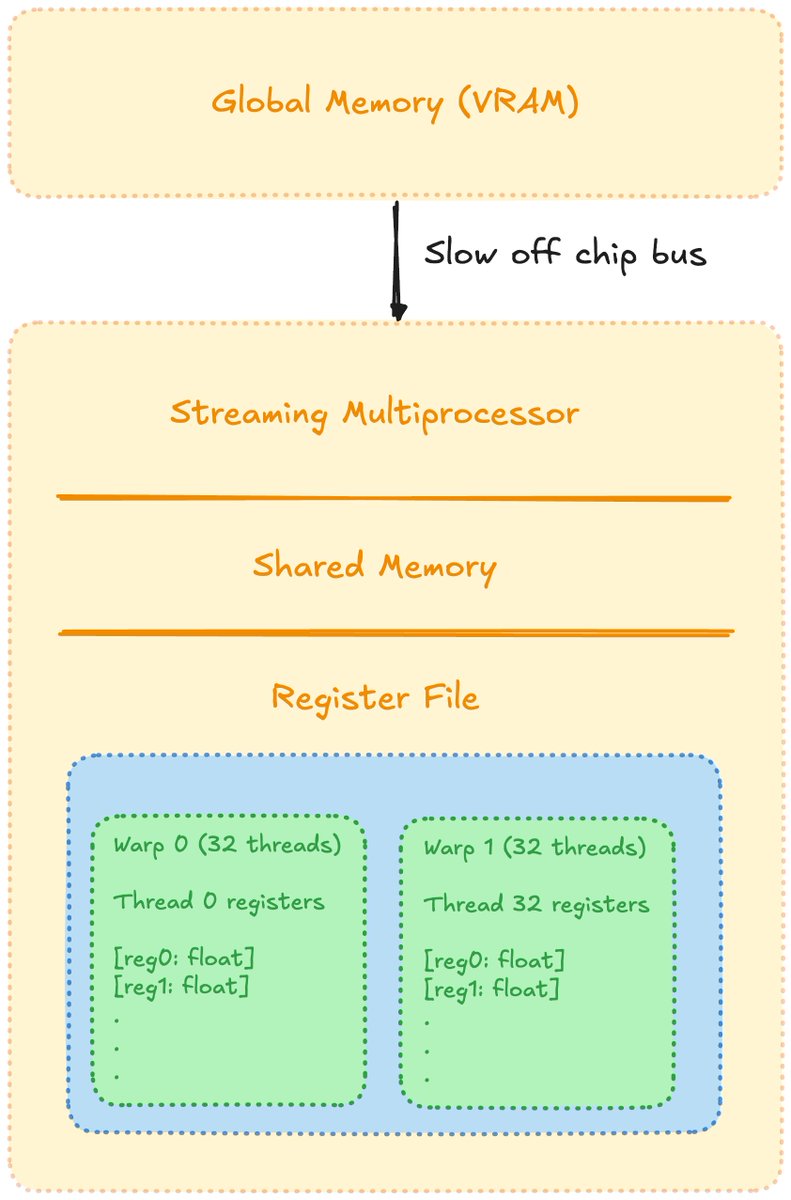
Image inspired from this [blog](https://damek.github.io/random/basic-facts-about-gpus/#fn:12)
The most basic fact that we need to understand is that, the higher the memory storage, slower the speed. And vice versa. (I do not completely understand the reason behind it right now, but when I do. I will write it!).
Global Memory or VRAM, is the advertised GPU storage. An SM (or streaming multiprocessor) has multiple parts to it like tensor cores, threads, warp scheduler and much more stuff.
For this current article, we need not dive that much into it! So we will look at the core ideas for now. The most important thing to understand is that SMs have blocks inside of them; these blocks have threads in them; the threads of a block have access to the shared memory of that block ONLY.
All threads are arranged in a 32-thread warp! Essentially, a warp runs all the threads simultaneously.
(If this does not make a lot of sense right now, do not worry. As we move forward, it will start making more sense!)
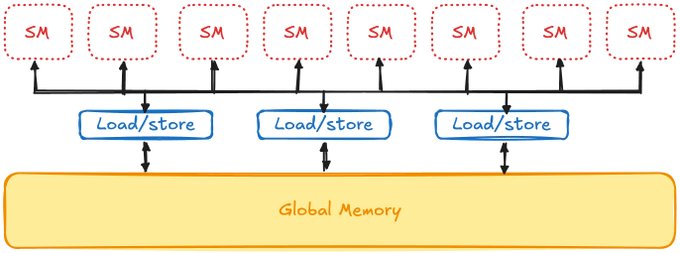
The transfer of data from global memory to an SM is an extremely inefficient operation, [horace he](https://horace.io/) has an amazing blog "[Making GPUs go Brrr](https://horace.io/brrr_intro.html)" that explains it quite well. Check it out. So ideally we would like to take our data, give it to the SM do all the necessary computation there. And only send it back once we are done computing.
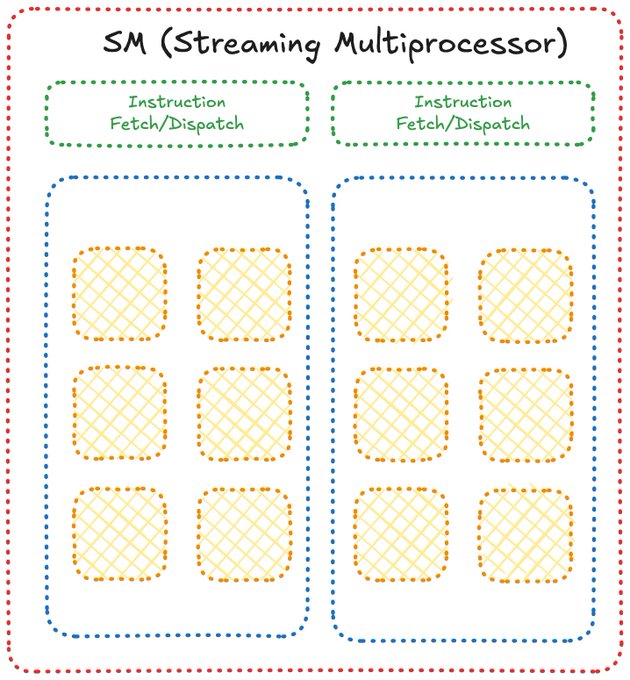
The above image is a simplification of how an SM looks like. Now we have a good general understanding of why GPUs exist and how they look like! This knowledge will prove to be useful when we start getting really knee deep into this.
## Understanding CUDA
Now we can start understanding the internals of CUDA itself.
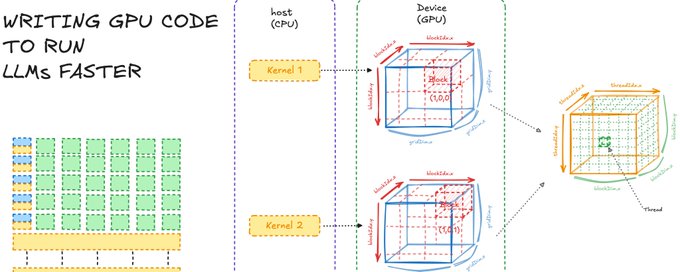
In CUDA we have grids, which have blocks inside of them, and the blocks have threads. They can be laid out in a 3d manner as presented below, but generally everyone just works with a 2d layout so we will use that majority of the time.
As I find the 1d model easier to understand as a beginner, I will use that in this part. And we will start with the multi-dimensional part starting next article.
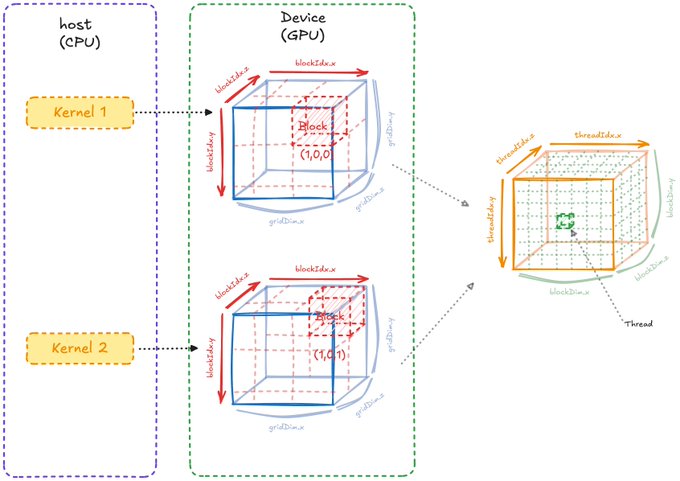
Now the above diagram can be a lot to take in while starting out, but let's break it down component by component.
We have a host where we write the CUDA kernel which is run in the device. The host is the CPU, a kernel is essentially a function and the GPU is the device.
In a kernel we define the number of blocks in a grid, and then the number of threads in each block.
To traverse the blocks and grids, we have the dimensions and indexes. (Look carefully, you will see both are very different thing. One helps move in a direction the other defines the length of that direction)
## Simple MatMul
Now let us write simple matrix multiplication in Python or CPU code, then we will write a CUDA kernel using what we have learned so far!
```
import numpy as np
a = 5
b = 10
c = 5
GEMM_1 = np.random.rand(a, b)
GEMM_2 = np.random.rand(b, c)
ANS_triple = np.zeros((a, c))
for i in range(a):
for j in range(c):
for k in range(b):
ANS_triple[i, j] += GEMM_1[i, k] * GEMM_2[k, j]
# Both should match numpy's built-in matmul
assert np.allclose(ANS_triple, GEMM_1 @ GEMM_2)
```
The simplest idea that we have to keep in mind while working with cuda is that we have multiple threads, running at once, and we want to get them running simultaneously.
The worst matmul that you can write is
```
// A -> M X K
// B -> K X N
// output -> M X N
__global__ void super_bad_matmul_kernel(const float* A, const float* B, float* output, int M, int N, int K){
float temp_val = 0;
for(int i = 0; i<M; i++){
for(int j = 0; j<N; j++){
for(int k = 0; k<K; k++){
temp_val += A[i*K + k]*B[K*k + j];
}
output[i*N + j] = temp_val;
}
}
}
extern "C" void solve(const float* A, const float* B, float* output, int M, int N, int K) {
super_bad_matmul_kernel<<<1, 1>>>(A, B, output, M, N, K);
}
```
The above code is terrible, the main reason being we are not utilising the fact that the code can be parallelized and multiple threads can each calculate one output value. Notice that `solve` only launches a single thread (`<<<1, 1>>>`), so even though it's running on the GPU, that one thread still does the entire triple loop by itself, exactly like the CPU version, we haven't used any of the GPU's parallelism yet.
Let's write the naive CUDA solution, and then I will explain what each part does and why it looks the way it does!
```
// A -> M X K
// B -> K X N
// output -> M X N
__global__ void naive_matmul(const float* A, const float* B, float* output, int M, int N, int K){
int gid = threadIdx.x + blockDim.x*blockIdx.x;
if(gid>= M*N) return;
int row = gid/N;
int col = gid%N;
float temp_val = 0;
for(int i = 0;i<K;i++){
temp_val += A[row*K + i]*B[i*N + col];
}
output[gid] = temp_val;
}
extern "C" void solve(const float* A, const float* B, float* output, int M, int N, int K) {
int threadsPerBlock = 256;
int blocksPerGrid = (M*N + threadsPerBlock - 1)/threadsPerBlock;
naive_matmul<<<blocksPerGrid, threadsPerBlock>>>(A, B, output, M, N, K);
}
```
The above one although not a great implementation shows the value. There is one idea that we have not talked about so far which sits at the center of CUDA. And that is the actual memory layout of the data is one dimensional and it is stored in a row major form.
We know that our output will be of the shape, MxN. But in memory we cannot have 2d layouts, we only have 1d. So instead of a MxN layout we have M rows of N values stacked after each other, which looks something like the below image.
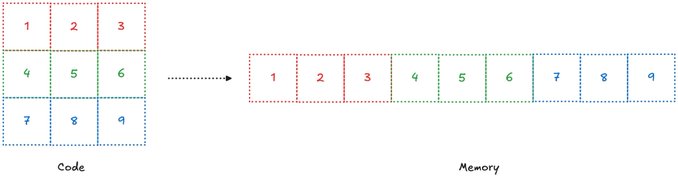
(You can imagine the similar for 3d)
Hence, if we breakdown gid (I like to call it global id; tid, or thread id, is the number of the thread within a block, and since we have defined the block size as 256, tid will never exceed that). It consists of threadIdx, blockDim, and blockIdx. Idx means index and dim means dimension.
It is important you visualize and understand how this is working; threadIdx gives you the current thread you are on in a block. Multiplying the block index (blockIdx) by the block dimension (blockDim) tells you how many threads came before this block.
A good way to understand is by thinking backwards. We want each thread to calculate one value. So we need MxN threads. Which is not possible.
So we set 256 threads and then we define the number of blocks based on this, that is where the ceiling equation comes from
blocksPerGrid = (M*N + threadsPerBlock - 1)/threadsPerBlock;
this will give us enough blocks with enough threads to take care of this computation, now as this is a ceiling function we can have a number of threads which exceed MxN. And hence the reason we have added a check
if(gid>= M*N) return;
read this part a few more times, try to think it in your terms and it should make sense!
## Where do we go from here?
If you would like to put the knowledge you have acquired to the test, I will recommend checking out
- [GPU Puzzles](https://github.com/srush/gpu-puzzles)
- [LeetGPU](https://leetgpu.com/)
This was a real simplification of a lot of ideas, in the next part we will understand what are bottlenecks in a CUDA code, how do we identify it and how we can optimize it. Along with understanding the relevant parts of the GPU for it.
Also if you have read this far, I will just assume you liked it. So you and I are essentially friends at this point, and as a friend. Consider helping me and your other friends by sharing it with them!
## 相关链接
- [Pramod Goyal](https://x.com/goyal__pramod)
- [@goyal__pramod](https://x.com/goyal__pramod)
- [12K](https://x.com/goyal__pramod/status/2103565642800431533/analytics)
- [here](https://discussions.apple.com/thread/255191914?sortBy=rank)
- [reading](https://stackoverflow.com/questions/27435284/multiprocessing-vs-multithreading-vs-asyncio)
- [blog](https://damek.github.io/random/basic-facts-about-gpus/#fn:12)
- [horace he](https://horace.io/)
- [Making GPUs go Brrr](https://horace.io/brrr_intro.html)
- [GPU Puzzles](https://github.com/srush/gpu-puzzles)
- [LeetGPU](https://leetgpu.com/)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [3:21 AM · Sep 26, 2026](https://x.com/goyal__pramod/status/2103565642800431533)
- [12.5K Views](https://x.com/goyal__pramod/status/2103565642800431533/analytics)
---
*导出时间: 2026/9/26 18:38:51*
---
## 中文翻译
# 从零到精通 CUDA #1
**作者**: Pramod Goyal
**日期**: 2026-09-25T19:21:46.000Z
**来源**: [https://x.com/goyal__pramod/status/2103565642800431533](https://x.com/goyal__pramod/status/2103565642800431533)
---

这些是我学习 CUDA 时的笔记;在这里我会尝试把各种概念拆解开来,并以对我来说最容易理解的方式呈现。我喜欢真正从内部透彻地理解事物,所以我会尽量详细地解释。
我认为最好的方式是我们亲自编写 CUDA 核函数,并随着时间的推移不断改进。
我希望这个系列足够详尽,能够把任何新手带到 SOTA 水平。在持续学习和成长的过程中,我会推荐相关的博客/书籍/视频。
> 注意:这是一篇会持续演进的文章,随着我理解的深入,我会不断增删内容。
现在让我们从……理解硬件开始。谈到 CUDA,请听我说:理解你所拥有的 GPU 以及它是如何工作的,和理解代码同样重要。因为两者是紧密耦合的。
## 理解 GPU
现在一个显而易见的问题是:我们为什么需要 GPU?难道 CPU 不够用吗?我们难道不能把它们合并吗*?为什么非要一个独立的模块?
*有趣的是,这正是苹果所做的;你可以在[这里](https://discussions.apple.com/thread/255191914?sortBy=rank)了解更多(我记得看过一个很精彩的视频深入解释了这一点,但我忘了。如果你知道我说的是哪个视频,请联系我!)。
CPU 长这样

灵感来自 PMPP
各个部分分别是:
DRAM -> 动态随机存取存储器,数据在计算之前存储在这里
CACHE -> 临时存储空间,用于存放即时计算出的数值
CONTROL -> 决定计算发送到哪里、数据存储到哪里。它是控制中心!
ALU -> 算术逻辑单元,负责计算的部分。
> 注意:这是对 CPU 结构的极度简化(当我们讲到 GPU 时也是如此),目的是帮助你理解核心组件及其工作原理。随着文章的深入,我们会逐步把这些高层组件拆解成各自的子部件,并理解它们是如何工作的!
如果你想按顺序做事,即一个接一个地执行,这很好。CPU 甚至有多个核心,因此你可以并行运行多个计算(多线程、并行和异步是不同的概念,可以[阅读](https://stackoverflow.com/questions/27435284/multiprocessing-vs-multithreading-vs-asyncio)这篇文章来理解它们的区别)。
现在想象一下矩阵乘法——大多数 AI 的核心。想一想就会发现,这是一个可以并行执行的操作,每个输出值都可以独立于其他输出值进行计算,你只需要对应 i 和 j 值的行向量和列向量。

为了实现这一点,我们需要什么与 CPU 不同的东西……答案不难:更多的 ALU!!!因为我们想尽快算出这些值,这就是为什么 GPU 通常长这样

> 注意:同样,这个 GPU 架构也是过度简化的。但这是传达要点所必需的信息。随着我们不断深入,我们会在已有知识的基础上叠加,让图示变得更复杂!
如上所示,我们的 ALU 多了很多。让我们通过了解各个部分的名称来更好地认识它们。与上面 CPU 部分不同,我们会更详细地探索它们,因为这篇文章的重点就是理解 GPU 和 CUDA。

图片灵感来自这篇[博客](https://damek.github.io/random/basic-facts-about-gpus/#fn:12)
我们需要理解的最基本事实是:内存容量越大,速度越慢,反之亦然。(我现在还不能完全理解其背后的原因,等我搞明白后,我会写下来!)
全局内存或 VRAM,就是宣传中所说的 GPU 存储容量。一个 SM(流式多处理器)包含多个部件,如张量核心、线程、warp 调度器等等。
就本文而言,我们不需要深入那么细!所以我们先看核心概念。最重要的理解点是:SM 里面有块,块里面有线程;一个块的线程只能访问该块的共享内存。
所有线程以 32 个线程为一个 warp 来组织!本质上,一个 warp 同时运行其中的所有线程。
(如果现在还不太理解,别担心。随着我们继续深入,它会逐渐变得清晰!)

数据从全局内存传输到 SM 是一个极其低效的操作,[horace he](https://horace.io/) 有一篇很棒的博客"[Making GPUs go Brrr](https://horace.io/brrr_intro.html)"很好地解释了这一点。去看看吧。所以理想情况下,我们希望把数据取出来,交给 SM,在那里完成所有必要的计算,只有在计算完成后才把结果送回去。

上图是 SM 结构的简化版。现在我们对 GPU 为什么存在以及它的样子有了大致的了解!当我们真正深入钻研时,这些知识会被证明非常有用。
## 理解 CUDA
现在我们可以开始理解 CUDA 本身的内部结构了。
在 CUDA 中,我们有网格,网格里面有块,块里面有线程。它们可以像下面展示的那样以三维方式布局,但通常大家都使用二维布局,所以我们大部分时间会使用二维。
由于我觉得一维模型对初学者来说更容易理解,所以这部分我会使用一维模型。从下一篇文章开始,我们将进入多维的部分。

上面的图在初学时可能信息量很大,但让我们逐个组件来拆解。
我们有一个主机,我们在其上编写在设备上运行的 CUDA 核函数。主机是 CPU,核本质上是一个函数,GPU 是设备。
在一个核中,我们定义网格中块的数量,以及每个块中线程的数量。
为了遍历块和网格,我们有了维度和索引。(仔细看,你会发现这是两个完全不同的东西:一个帮助你在某个方向上移动,另一个定义该方向的长度。)
## 简单的矩阵乘法
现在让我们用 Python 或 CPU 代码写一个简单的矩阵乘法,然后用我们目前学到的知识写一个 CUDA 核函数!
```
import numpy as np
a = 5
b = 10
c = 5
GEMM_1 = np.random.rand(a, b)
GEMM_2 = np.random.rand(b, c)
ANS_triple = np.zeros((a, c))
for i in range(a):
for j in range(c):
for k in range(b):
ANS_triple[i, j] += GEMM_1[i, k] * GEMM_2[k, j]
# Both should match numpy's built-in matmul
assert np.allclose(ANS_triple, GEMM_1 @ GEMM_2)
```
在使用 CUDA 时需要记住的最简单的想法是:我们有多个线程同时运行,我们希望让它们并行执行。
你能写出的最糟糕的矩阵乘法是:
```
// A -> M X K
// B -> K X N
// output -> M X N
__global__ void super_bad_matmul_kernel(const float* A, const float* B, float* output, int M, int N, int K){
float temp_val = 0;
for(int i = 0; i<M; i++){
for(int j = 0; j<N; j++){
for(int k = 0; k<K; k++){
temp_val += A[i*K + k]*B[K*k + j];
}
output[i*N + j] = temp_val;
}
}
}
extern "C" void solve(const float* A, const float* B, float* output, int M, int N, int K) {
super_bad_matmul_kernel<<<1, 1>>>(A, B, output, M, N, K);
}
```
上面的代码非常糟糕,主要原因是它没有利用代码可以并行化这一事实,即多个线程可以各自计算一个输出值。注意 `solve` 只启动了一个线程(`<<<1, 1>>>`),所以即使它在 GPU 上运行,那一个线程仍然要独自完成整个三重循环,和 CPU 版本完全一样,我们还没有利用 GPU 的任何并行能力。
让我们写出朴素的 CUDA 解决方案,然后我会解释每个部分的作用以及它为什么是这样的!
```
// A -> M X K
// B -> K X N
// output -> M X N
__global__ void naive_matmul(const float* A, const float* B, float* output, int M, int N, int K){
int gid = threadIdx.x + blockDim.x*blockIdx.x;
if(gid>= M*N) return;
int row = gid/N;
int col = gid%N;
float temp_val = 0;
for(int i = 0;i<K;i++){
temp_val += A[row*K + i]*B[i*N + col];
}
output[gid] = temp_val;
}
extern "C" void solve(const float* A, const float* B, float* output, int M, int N, int K) {
int threadsPerBlock = 256;
int blocksPerGrid = (M*N + threadsPerBlock - 1)/threadsPerBlock;
naive_matmul<<<blocksPerGrid, threadsPerBlock>>>(A, B, output, M, N, K);
}
```
上面这个虽然不是很好的实现,但展示了价值所在。有一个我们至今没有谈到、却处于 CUDA 核心的概念:数据的实际内存布局是一维的,并且以行主序存储。
我们知道输出的形状是 MxN。但在内存中我们不能有二维布局,只有一维。所以与其说是 MxN 的布局,不如说是 M 行、每行 N 个值依次堆叠,看起来像下面这张图。

(你可以想象三维时的类似情况)
因此,如果我们拆解 gid(我喜欢称之为全局 id;tid,即线程 id,是块内线程的编号,因为我们把块大小定义为 256,所以 tid 永远不会超过这个数)。它由 threadIdx、blockDim 和 blockIdx 组成。Idx 表示索引,dim 表示维度。
很重要的一点是,你要把这一切的工作方式可视化并理解它:threadIdx 告诉你当前在块中处于哪个线程。块索引乘以块维度会告诉你在这个块之前有多少线程。
一个很好的理解方式是倒过来想。我们希望每个线程计算一个值。所以我们需要 MxN 个线程。这是不可能的。
所以我们设置 256 个线程,然后基于此定义块的数量,这就是那个向上取整公式的来源:
blocksPerGrid = (M*N + threadsPerBlock - 1)/threadsPerBlock;
这会给我们足够多的块和线程来完成这个计算,但由于这是一个向上取整函数,线程数可能会超过 MxN。因此我们需要加一个检查:
if(gid>= M*N) return;
把这部分多读几遍,试着用自己的思路去思考,它就应该能说得通了!
## 接下来去哪里?
如果你想检验一下所学的知识,我推荐去看看:
- [GPU Puzzles](https://github.com/srush/gpu-puzzles)
- [LeetGPU](https://leetgpu.com/)
这篇文章对很多概念进行了大幅简化,在下一部分中,我们将理解 CUDA 代码中的瓶颈是什么、如何识别它以及如何优化它,同时还会了解与之相关的 GPU 部件。
另外,如果你读到了这里,我就默认你喜欢这篇文章了。所以在这一点上,你我基本上已经是朋友了,作为朋友,考虑通过分享给它来帮助我和你的其他朋友吧!
## 相关链接
- [Pramod Goyal](https://x.com/goyal__pramod)
- [@goyal__pramod](https://x.com/goyal__pramod)
- [12K](https://x.com/goyal__pramod/status/2103565642800431533/analytics)
- [here](https://discussions.apple.com/thread/255191914?sortBy=rank)
- [reading](https://stackoverflow.com/questions/27435284/multiprocessing-vs-multithreading-vs-asyncio)
- [blog](https://damek.github.io/random/basic-facts-about-gpus/#fn:12)
- [horace he](https://horace.io/)
- [Making GPUs go Brrr](https://horace.io/brrr_intro.html)
- [GPU Puzzles](https://github.com/srush/gpu-puzzles)
- [LeetGPU](https://leetgpu.com/)
- [Upgrade to Premium](https://x.com/i/premium_sign_up)
- [3:21 AM · Sep 26, 2026](https://x.com/goyal__pramod/status/2103565642800431533)
- [12.5K Views](https://x.com/goyal__pramod/status/2103565642800431533/analytics)
---
*导出时间: 2026/9/26 18:38:51*